Small updates, improvements, and housekeeping to docs (#10405)
* Fix Berkeley mentions * Add new collectors to list * Tweak Prometheus/OpenMetrics phrasing * Fix heading depth in performance guide * Clarify that exporting starts with Agent start * Clarify usage of edit-config with new files * Update images * service -> systemctl * Reverse systemctl order
Joel Hans committed
Jan 7, 2021 at 09:53 UTC
0bb7a429b619bc68104983691e4f957482630787
11 files changed
+57
-54
collectors/COLLECTORS.md
+10
-5
@@ -44,7 +44,7 @@ collector—we may be looking for contributions from users such as yourself! If
44
- [System collectors](#system-collectors)
45
- [Applications](#applications)
46
- [Disks and filesystems](#disks-and-filesystems)
47
- - [eBPF (extended Berkely Backet Filter)](#ebpf)
47
+ - [eBPF (extended Berkeley Packet Filter)](#ebpf)
48
- [Hardware](#hardware)
49
- [Memory](#memory)
50
- [Networks](#networks)
@@ -64,8 +64,7 @@ configure any of these collectors according to your setup and infrastructure.
64
### Generic
65
66
- [Prometheus endpoints](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/prometheus): Gathers
67
- metrics from one or more Prometheus endpoints that use the OpenMetrics exposition format. Autodetects more than 600
68
- endpoints.
67
+ metrics from any number of Prometheus endpoints, with support to autodetect more than 600 services and applications.
68
69
### APM (application performance monitoring)
70
@@ -111,6 +110,8 @@ configure any of these collectors according to your setup and infrastructure.
110
database components using `_status/vars` endpoint.
111
- [Consul](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/consul/): Capture service and unbound
112
checks status (passing, warning, critical, maintenance).
113
+- [Couchbase](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/couchbase/): Gather per-bucket
114
+ metrics from any number of instances of the distributed JSON document database.
115
- [CouchDB](/collectors/python.d.plugin/couchdb/README.md): Monitor database health and performance metrics
116
(reads/writes, HTTP traffic, replication status, etc).
117
- [MongoDB](/collectors/python.d.plugin/mongodb/README.md): Collect memory-caching system performance metrics and
@@ -118,11 +119,15 @@ configure any of these collectors according to your setup and infrastructure.
119
- [MySQL](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/mysql/): Collect database global,
120
replication and per user statistics.
121
- [OracleDB](/collectors/python.d.plugin/oracledb/README.md): Monitor database performance and health metrics.
122
+- [Pika](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/pika/): Gather metric, such as clients,
123
+ memory usage, queries, and more from the Redis interface-compatible database.
124
- [Postgres](/collectors/python.d.plugin/postgres/README.md): Collect database health and performance metrics.
125
- [ProxySQL](/collectors/python.d.plugin/proxysql/README.md): Monitor database backend and frontend performance
126
metrics.
124
-- [Redis](/collectors/python.d.plugin/redis/): Monitor database status by reading the server's response to the `INFO`
125
- command.
127
+- [Redis (Go)](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/redis/): Monitor status from any
128
+ number of database instances by reading the server's response to the `INFO ALL` command.
129
+- [Redis (Python)](/collectors/python.d.plugin/redis/): Monitor database status by reading the server's response to
130
+ the `INFO` command.
131
- [RethinkDB](/collectors/python.d.plugin/rethinkdbs/README.md): Collect database server and cluster statistics.
132
- [Riak KV](/collectors/python.d.plugin/riakkv/README.md): Collect database stats from the `/stats` endpoint.
133
- [Zookeeper](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/zookeeper/): Monitor application
collectors/python.d.plugin/boinc/README.md
+1
-1
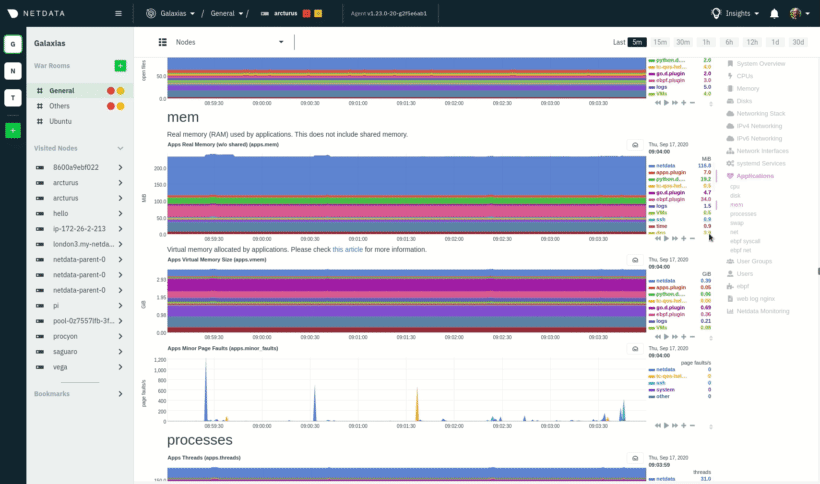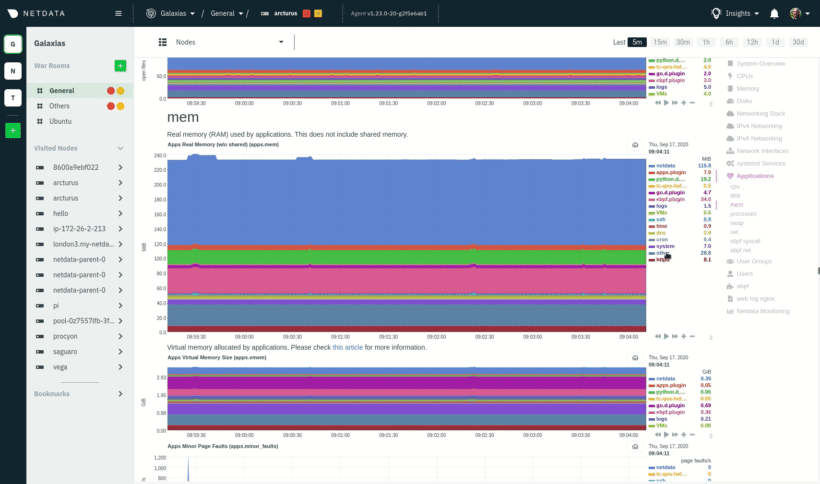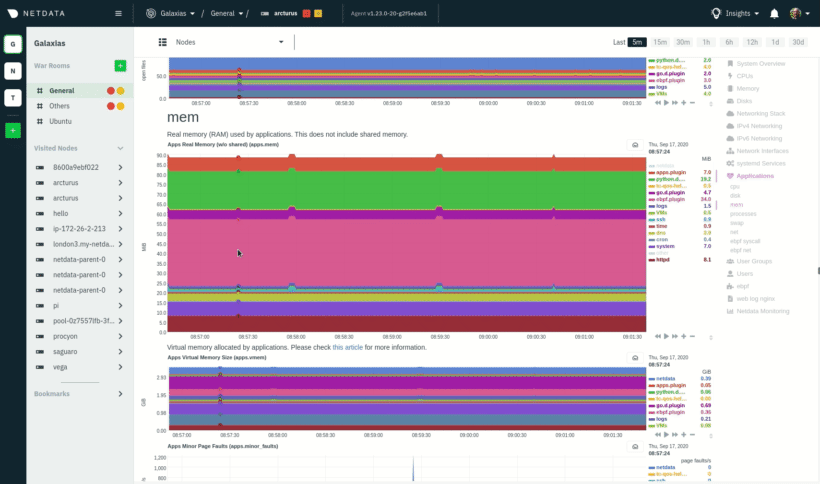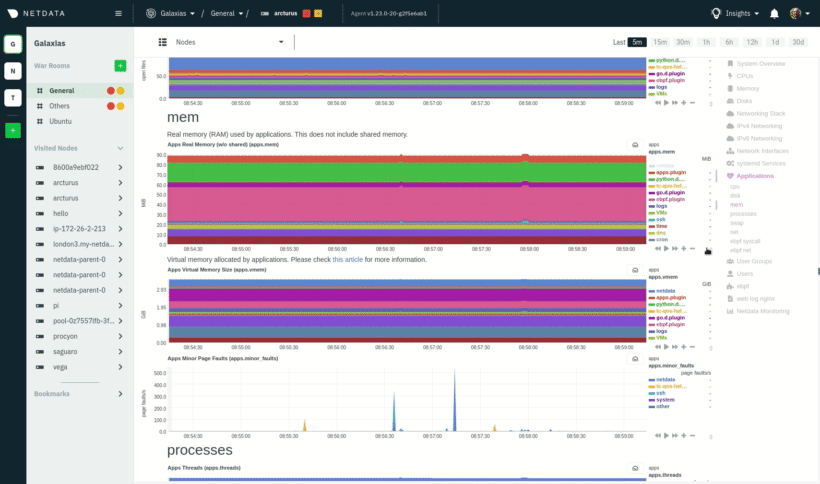
@@ -6,7 +6,7 @@ sidebar_label: "BOINC"
6
7
# BOINC monitoring with Netdata
8
9
-Monitors task counts for the Berkely Open Infrastructure Networking Computing (BOINC) distributed computing client using the same RPC interface that the BOINC monitoring GUI does.
9
+Monitors task counts for the Berkeley Open Infrastructure Networking Computing (BOINC) distributed computing client using the same RPC interface that the BOINC monitoring GUI does.
10
11
It provides charts tracking the total number of tasks and active tasks, as well as ones tracking each of the possible states for tasks.
12
docs/export/enable-connector.md
+8
-5
@@ -11,6 +11,9 @@ database](/docs/export/external-databases.md#supported-databases), you can now e
11
connector itself. We'll walk through the process of enabling the exporting engine itself, followed by two examples using
12
the OpenTSDB and Graphite connectors.
13
14
+> When you enable the exporting engine and a connector, the Netdata Agent exports metrics _beginning from the time you
15
+> restart its process_, not the entire [database of long-term metrics](/docs/store/change-metrics-storage.md).
16
+
17
Once you understand the process of enabling a connector, you can translate that knowledge to any other connector.
18
19
## Enable the exporting engine
@@ -44,9 +47,9 @@ Use the following configuration as a starting point. Copy and paste it into `exp
47
Replace `my_opentsdb_http_instance` with an instance name of your choice, and change the `destination` setting to the IP
48
address or hostname of your OpenTSDB database.
49
47
-Restart your Agent with `service netdata restart` to begin exporting to your OpenTSDB database. Because the
48
-Agent exports metrics as they're collected, you should start seeing data in your external database after only a few
49
-seconds.
50
+Restart your Agent with `sudo systemctl restart netdata` to begin exporting to your OpenTSDB database. The Netdata Agent
51
+exports metrics _beginning from the time the process starts_, and because it exports as metrics are collected, you
52
+should start seeing data in your external database after only a few seconds.
53
54
Any further configuration is optional, based on your needs and the configuration of your OpenTSDB database. See the
55
[OpenTSDB connector doc](/exporting/opentsdb/README.md) and [exporting engine
@@ -65,8 +68,8 @@ Use the following configuration as a starting point. Copy and paste it into `exp
68
Replace `my_graphite_instance` with an instance name of your choice, and change the `destination` setting to the IP
69
address or hostname of your Graphite-supported database.
70
68
-Restart your Agent with `service netdata restart` to begin exporting to your Graphite-supported database. Because the
69
-Agent exports metrics as they're collected, you should start seeing data in your external database after only a few
71
+Restart your Agent with `sudo systemctl restart netdata` to begin exporting to your Graphite-supported database. Because
72
+the Agent exports metrics as they're collected, you should start seeing data in your external database after only a few
73
seconds.
74
75
Any further configuration is optional, based on your needs and the configuration of your Graphite-supported database.
docs/getting-started.md
+8
-18
@@ -193,30 +193,20 @@ Find the `SEND_EMAIL="YES"` line and change it to `SEND_EMAIL="NO"`.
193
## Monitor multiple systems with Netdata Cloud
194
195
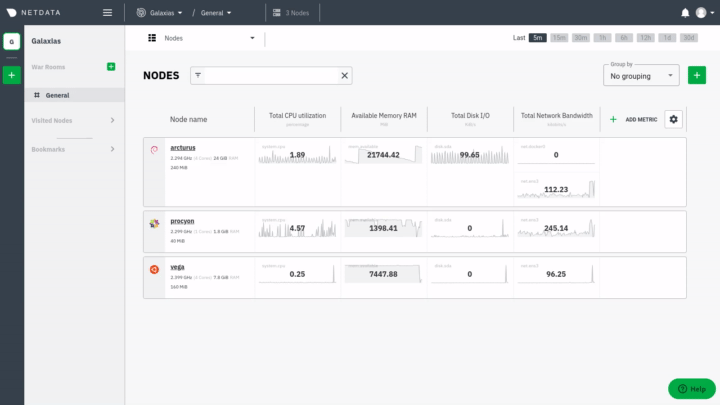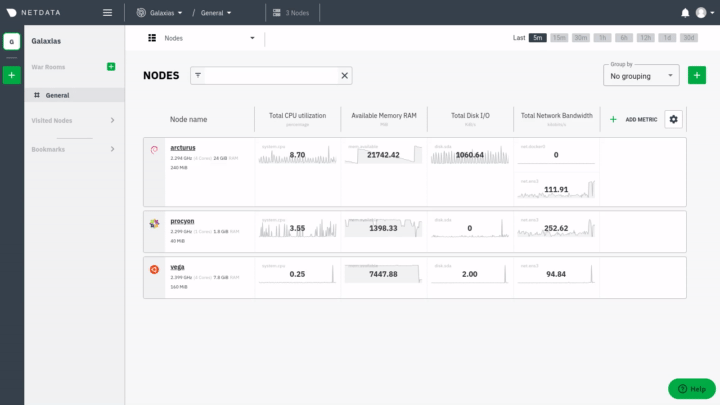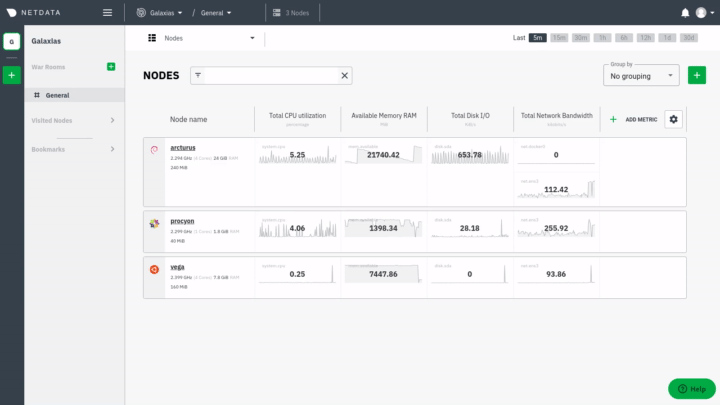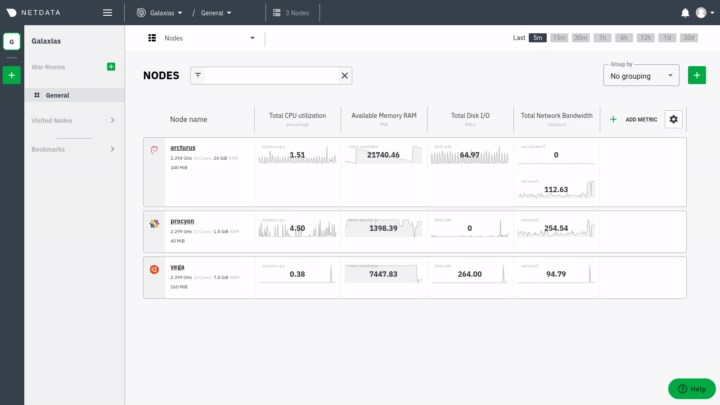
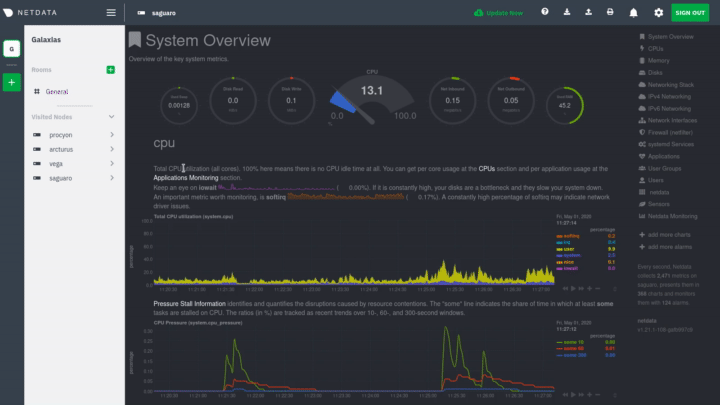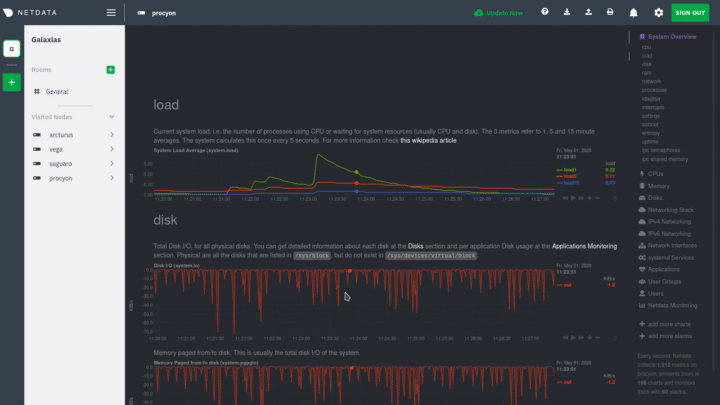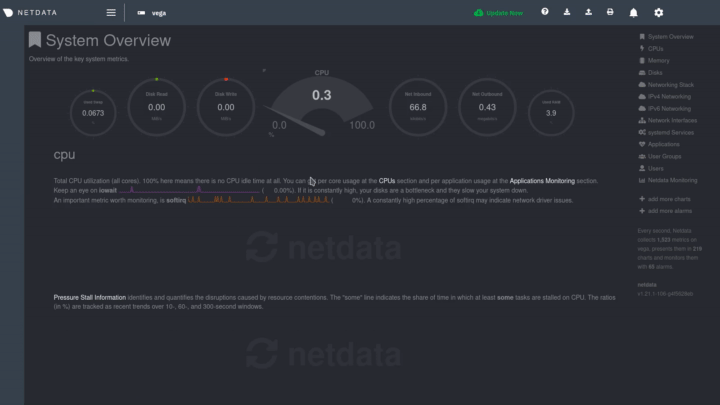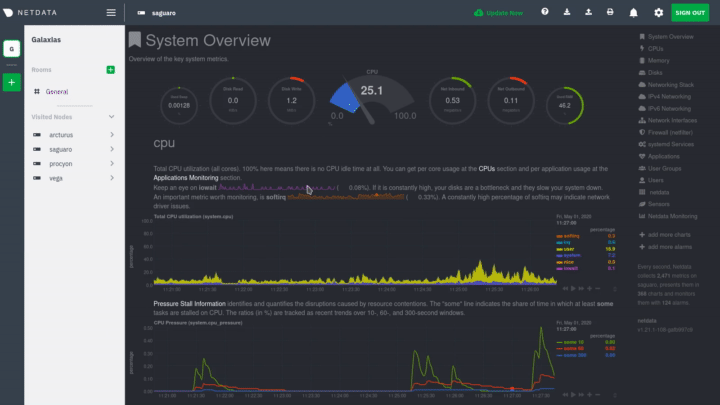
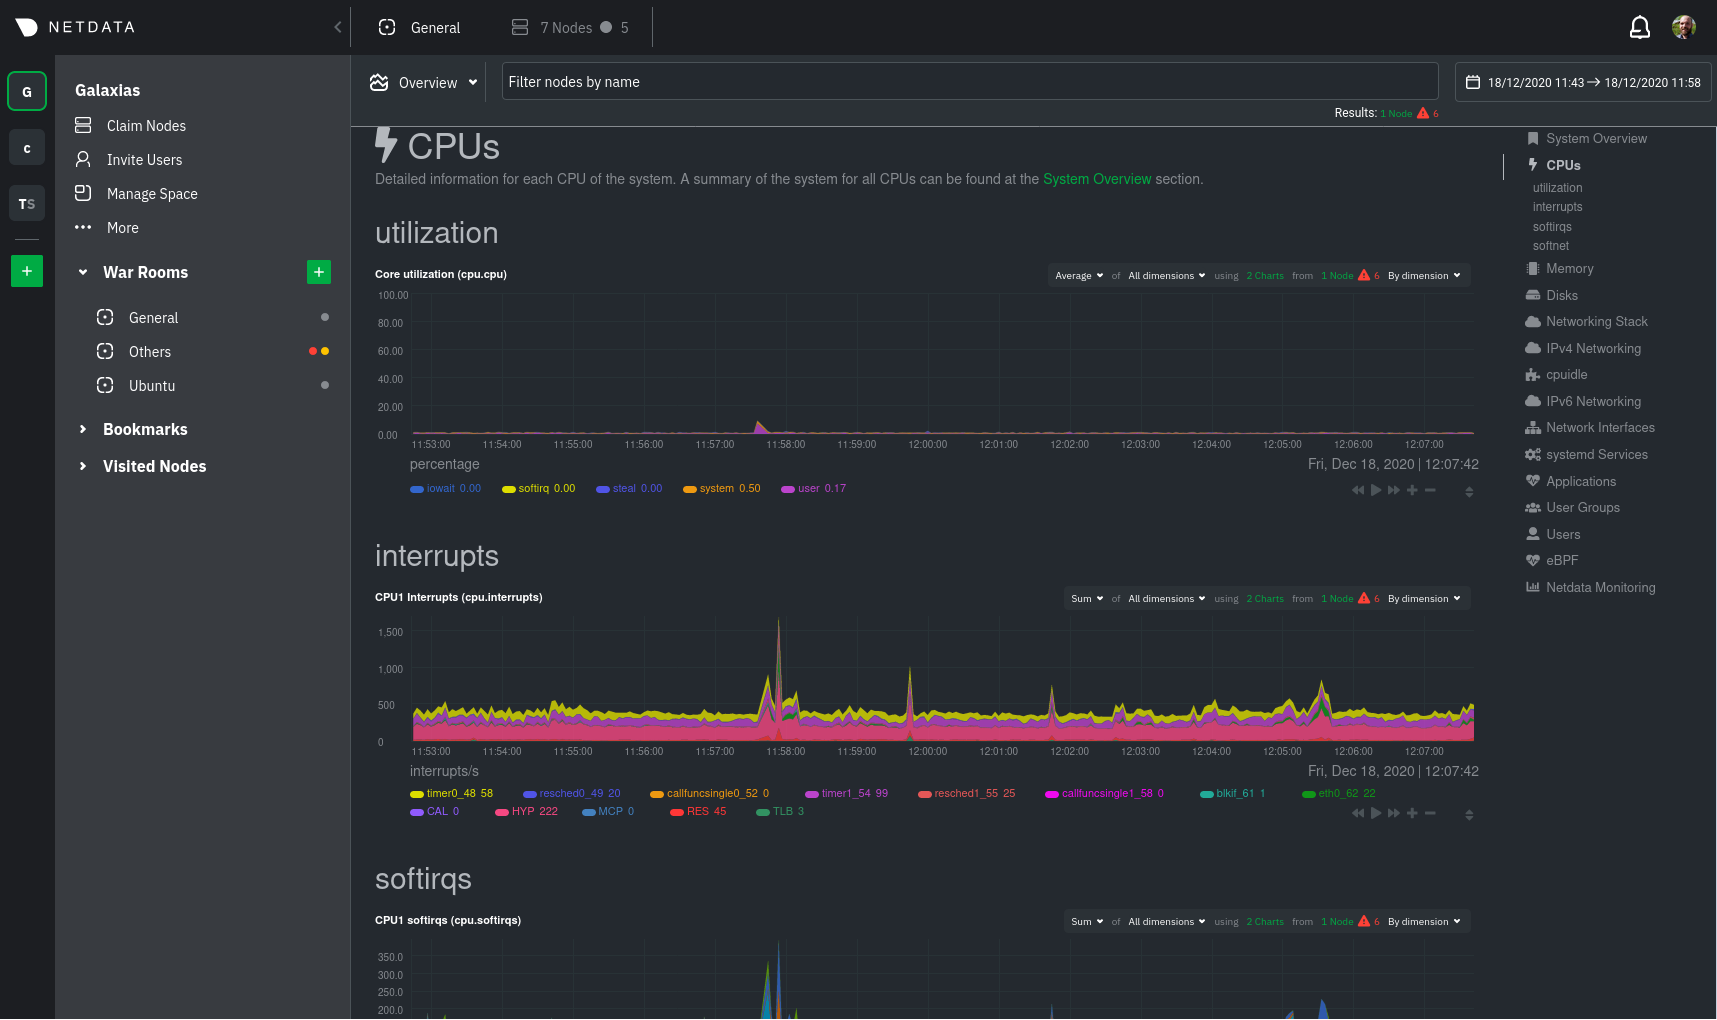
If you have the Agent installed on multiple nodes, you can use Netdata Cloud in two ways: Monitor the health and
196
-performance of an entire infrastructure via the Cloud web interface, or use the Visited Nodes menu that's built into
197
-every dashboard.
196
+performance of an entire infrastructure via the Netdata Cloud web application, or use the Visited Nodes menu that's
197
+built into every dashboard.
198
199
-For example, a small infrastructure monitored via Netdata Cloud:
200
-
201
-
203
-
204
-And the process of using the Visited nodes menu to move between Agent dashboards running on various systems, both local
205
-and remote:
206
-
207
-
199
+
201
202
You can use these features together or separately—the decision is up to you and the needs of your infrastructure.
203
204
**What's next?**:
205
214
-- Read about the [Agent-Cloud integration]().
215
-- Get an overview of Cloud's features by reading [Cloud documentation](https://learn.netdata.cloud/docs/cloud/).
216
-- Follow the 5-minute [get started with Cloud](https://learn.netdata.cloud/docs/cloud/get-started/) guide to finish
217
- onboarding and claim your first nodes.
218
-- Better understand how agents connect securely to the Cloud with [claiming](/claim/README.md) and [Agent-Cloud
219
- link](/aclk/README.md) documentation.
206
+- Sign up for [Netdata Cloud](https://app.netdata.cloud).
207
+- Read the [infrastructure monitoring quickstart](/docs/quickstart/infrastructure.md).
208
+- Better understand how the Netdata Agent connects securely to Netdata Cloud with [claiming](/claim/README.md) and
209
+ [Agent-Cloud link](/aclk/README.md) documentation.
210
211
## Start, stop, and restart Netdata
212
docs/guides/configure/performance.md
+3
-8
@@ -52,7 +52,7 @@ Let's walk through the best ways to improve the Netdata Agent's performance.
52
53
The fastest way to improve the Agent's resource utilization is to reduce how often it collects metrics.
54
55
-## Global
55
+### Global
56
57
If you don't need per-second metrics, or if the Netdata Agent uses a lot of CPU even when no one is viewing that node's
58
dashboard, configure the Agent to collect metrics less often.
@@ -69,18 +69,13 @@ seconds, respectively.
69
update every: 5
70
```
71
72
+### Specific plugin or collector
73
+
74
Every collector and plugin has its own `update every` setting, which you can also change in the `go.d.conf`,
75
`python.d.conf`, `node.d.conf`, or `charts.d.conf` files, or in individual collector configuration files. If the `update
76
every` for an individual collector is less than the global, the Netdata Agent uses the global setting. See the [enable
77
or configure a collector](/docs/collect/enable-configure.md) doc for details.
78
77
-## Specific plugin or collector
78
-
79
-If you did not [reduce the global collection frequency](#global) but find that a specific plugin/collector uses too many
80
-resources, you can reduce its frequency. You configure [internal
81
-collectors](/docs/collect/how-collectors-work.md#collector-architecture-and-terminolog) in `netdata.conf` and external
82
-collectors in their individual `.conf` files.
83
-
79
To reduce the frequency of an [internal
80
plugin/collector](/docs/collect/how-collectors-work.md#collector-architecture-and-terminology), open `netdata.conf` and
81
find the appropriate section. For example, to reduce the frequency of the `apps` plugin, which collects and visualizes
docs/monitor/configure-alarms.md
+10
-4
@@ -22,7 +22,8 @@ files.
22
## Edit health configuration files
23
24
All of Netdata's [health configuration files](/health/REFERENCE.md#health-configuration-files) are in Netdata's config
25
-directory, inside the `health.d/` directory. Use Netdata's `edit-config` script to make changes to any of these files.
25
+directory, inside the `health.d/` directory. Navigate to your [Netdata config directory](/docs/configure/nodes.md) and
26
+use `edit-config` to make changes to any of these files.
27
28
For example, to edit the `cpu.conf` health configuration file, run:
29
@@ -75,13 +76,18 @@ your systems, containers, and applications work.
76
Read Netdata's [health reference](/health/REFERENCE.md#health-entity-reference) for a full listing of the format,
77
syntax, and functionality of health entities.
78
78
-To write a new health entity, use `edit-config` to create a new file inside of the `health.d/` directory.
79
+To write a new health entity into a new file, navigate to your [Netdata config directory](/docs/configure/nodes.md),
80
+then use `touch` to create a new file in the `health.d/` directory. Use `edit-config` to start editing the file.
81
+
82
+As an example, let's create a `ram-usage.conf` file.
83
84
```bash
81
-sudo ./edit-config health.d/example.conf
85
+sudo touch health.d/ram-usage.conf
86
+sudo ./edit-config health.d/ram-usage.conf
87
```
88
84
-For example, here is a health entity that triggers an alarm when a node's RAM usage rises above 80%:
89
+For example, here is a health entity that triggers a warning alarm when a node's RAM usage rises above 80%, and a
90
+critical alarm above 90%:
91
92
```yaml
93
alarm: ram_usage
docs/quickstart/infrastructure.md
+1
-1
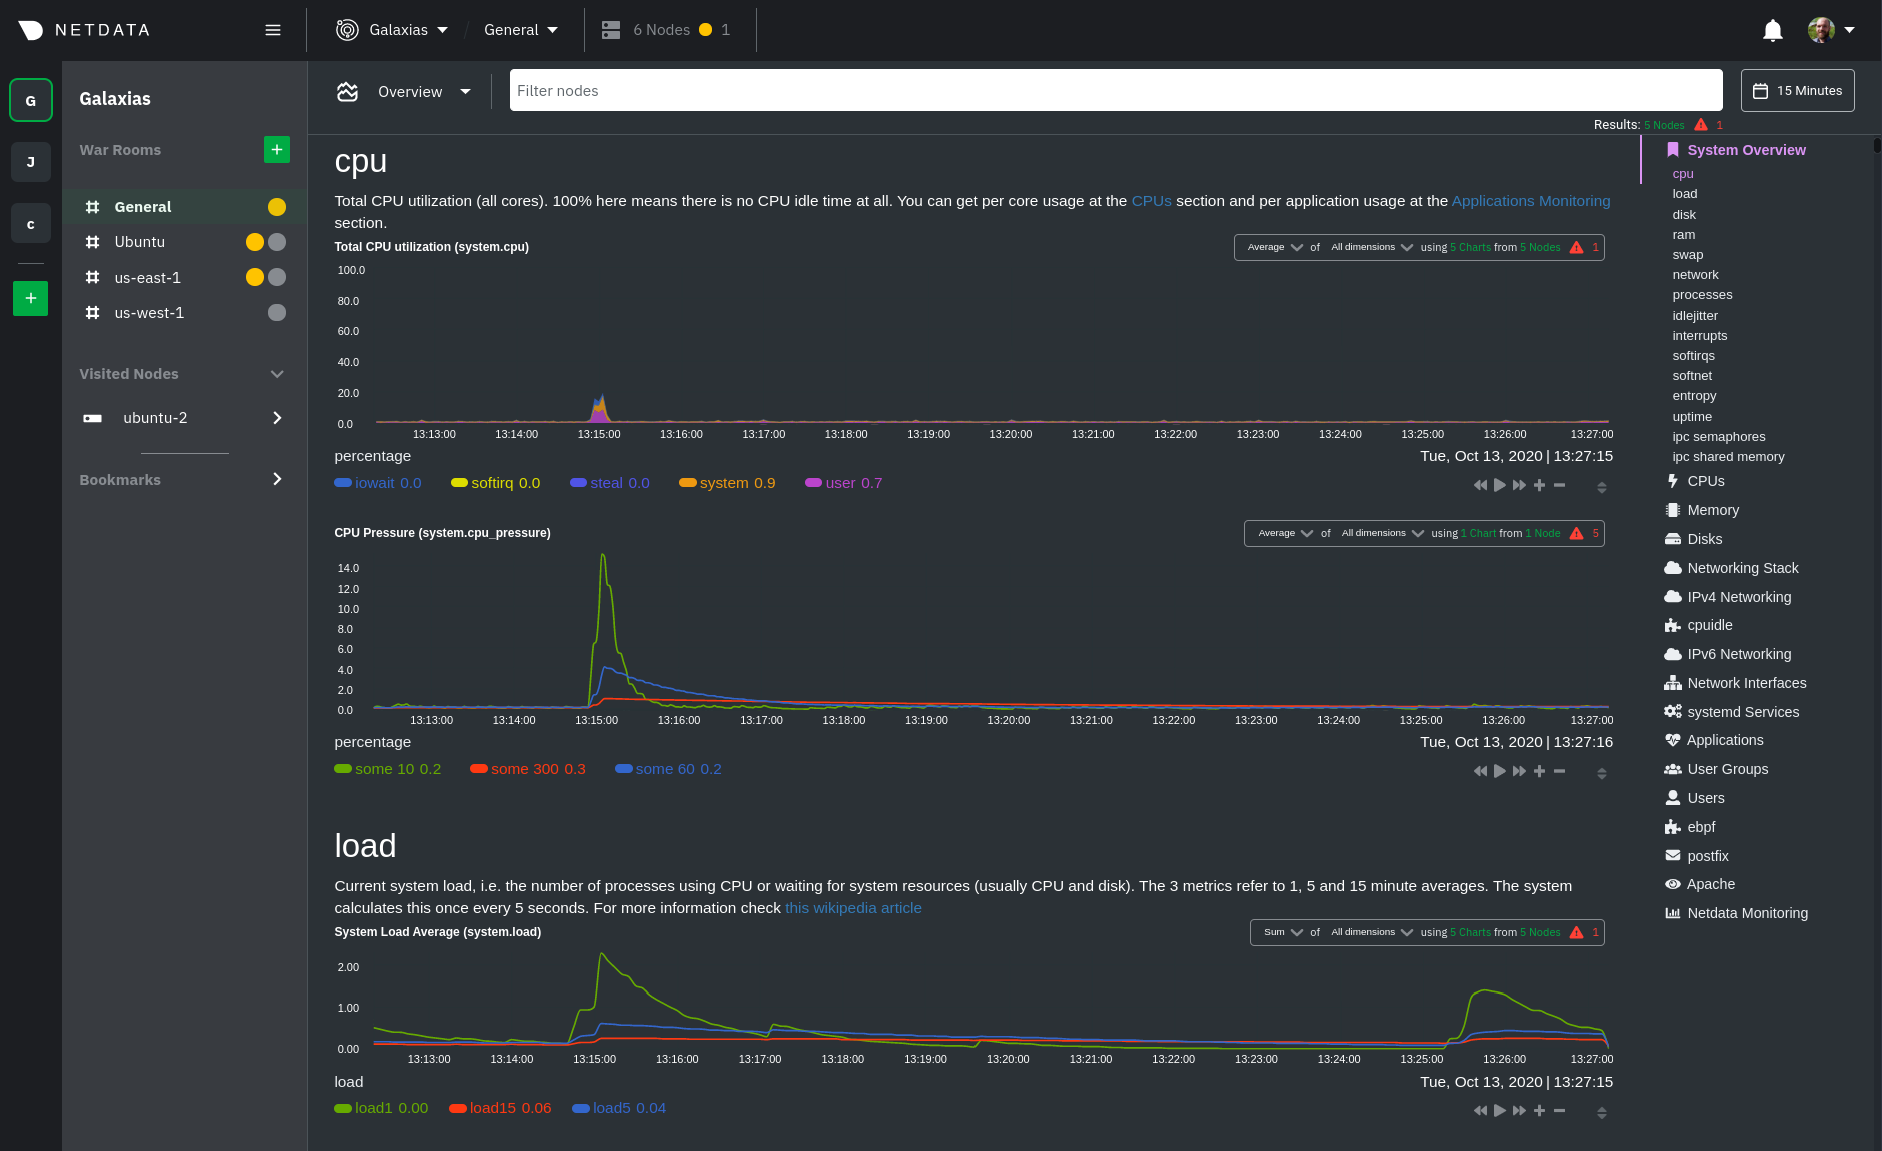
@@ -76,7 +76,7 @@ Overview features composite charts, which display aggregated metrics from every
76
are streamed on-demand from individual nodes and composited onto a single, familiar dashboard.
77
78
79
+Overview](https://user-images.githubusercontent.com/1153921/102651377-b1f4b100-4129-11eb-8e60-d2995d258c16.png)
80
81
Read more about the Overview in the [infrastructure overview](/docs/visualize/overview-infrastructure.md) doc.
82
docs/visualize/create-dashboards.md
+9
-8
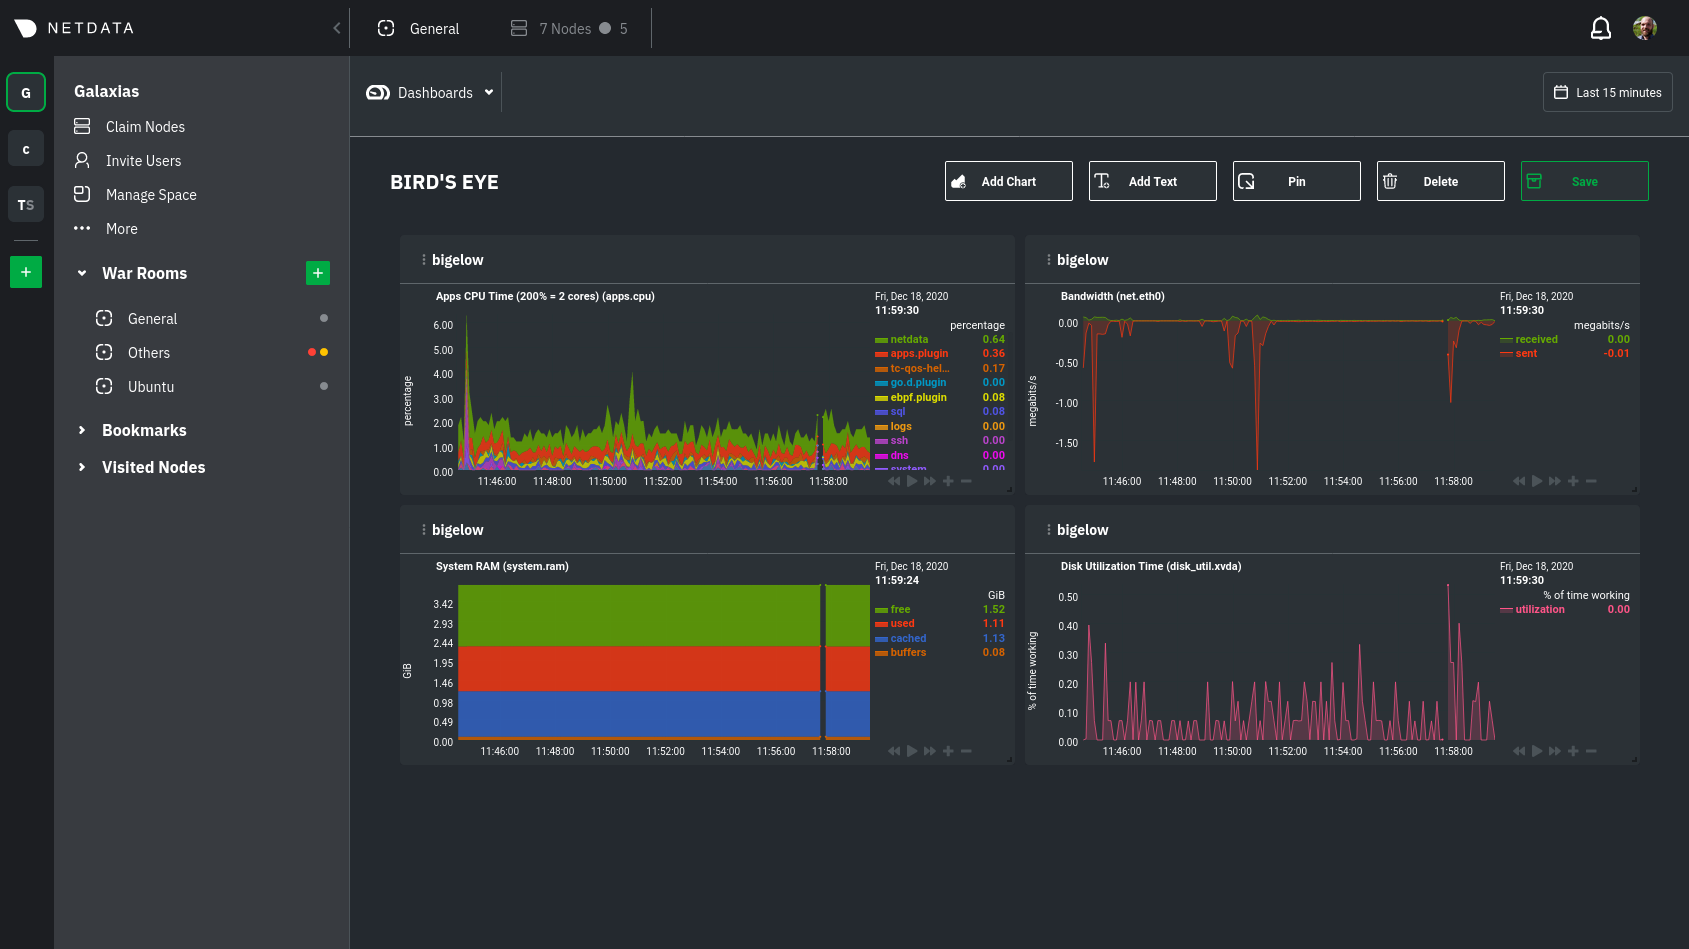
@@ -14,12 +14,14 @@ In the War Room you want to monitor with this dashboard, click on your War Room'
14
Add** button next to **Dashboards**. In the panel, give your new dashboard a name, and click **+ Add**.
15
16
Click the **Add Chart** button to add your first chart card. From the dropdown, select the node you want to add the
17
-chart from, then the context. Netdata Cloud shows you a preview of the chart before you finish adding it. The **Add
18
-Text** button creates a new card with user-defined text, which you can use to describe or document a particular
19
-dashboard's meaning and purpose.
17
+chart from, then the context. Netdata Cloud shows you a preview of the chart before you finish adding it.
18
21
-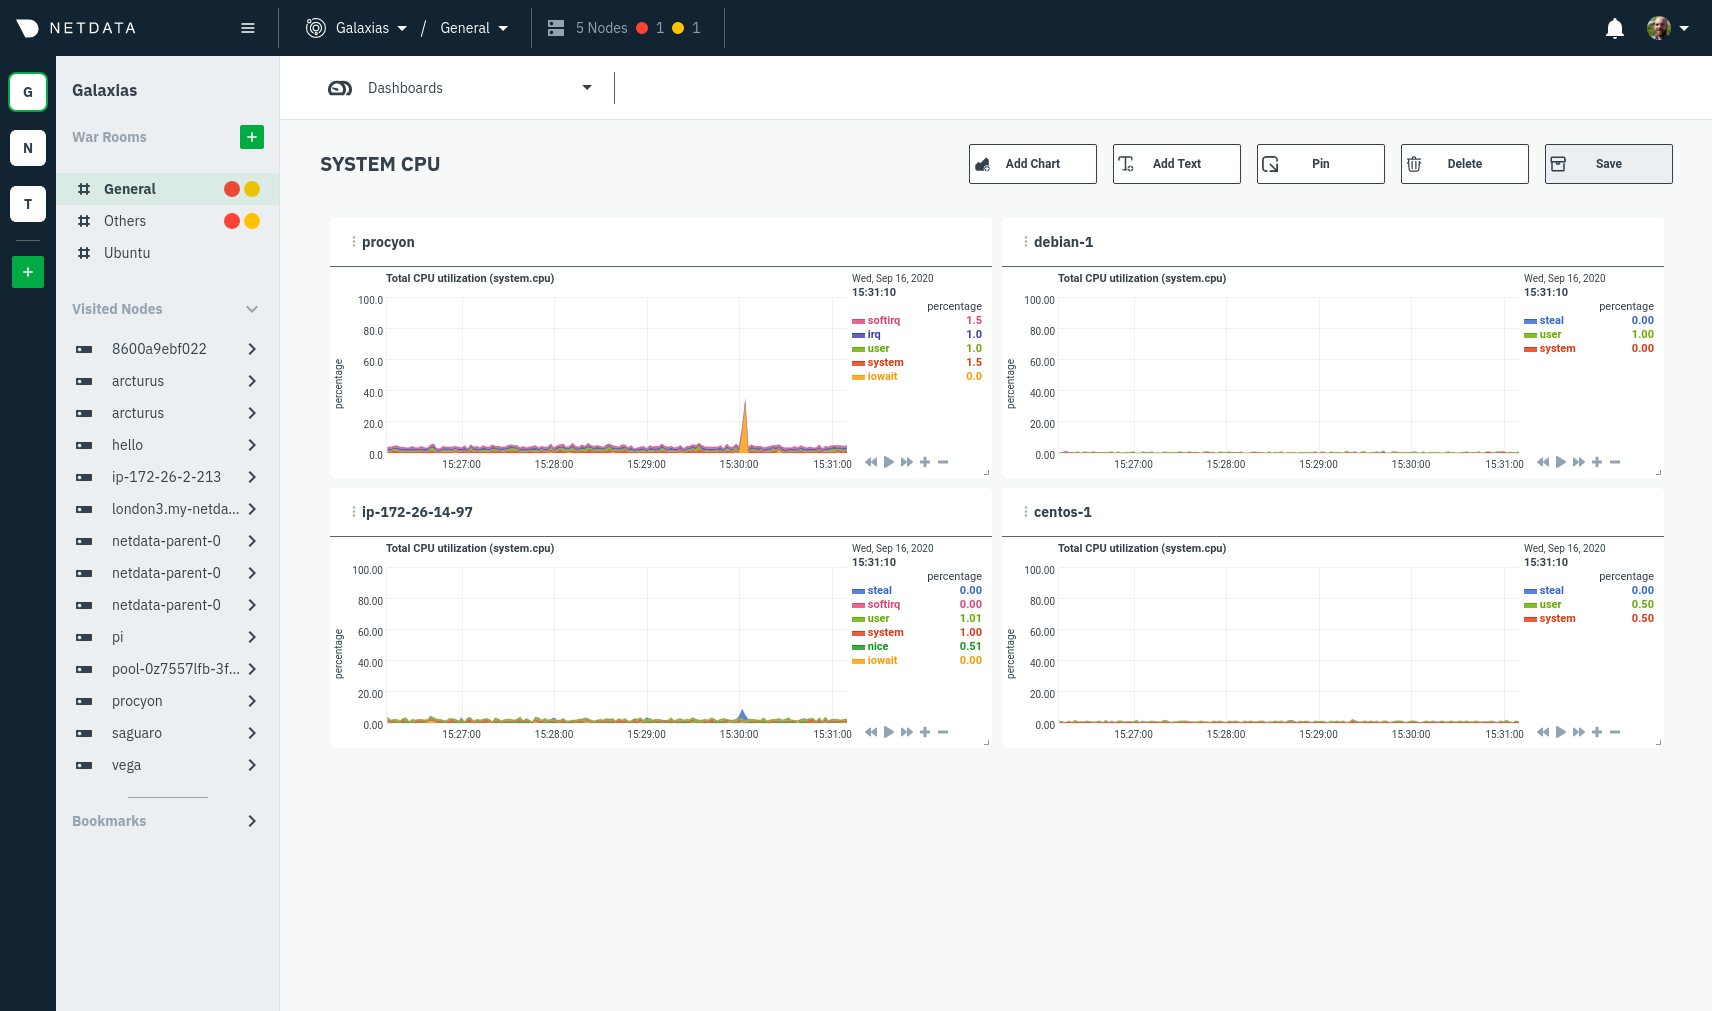
19
+The **Add Text** button creates a new card with user-defined text, which you can use to describe or document a
20
+particular dashboard's meaning and purpose. Enrich the dashboards you create with documentation or procedures on how to
21
+respond
22
+
23
+
25
26
Charts in dashboards are [fully interactive](/docs/visualize/interact-dashboards-charts.md) and synchronized. You can
27
pan through time, zoom, highlight specific timeframes, and more.
@@ -41,7 +43,8 @@ complex performance problems.
43
44
When viewing a single-node Cloud dashboard, you can also click on the add to dashboard icon <img
45
src="https://user-images.githubusercontent.com/1153921/87587846-827fdb00-c697-11ea-9f31-aed0b8c6afba.png" alt="Dashboard
44
-icon" class="image-inline" /> to quickly add that chart to a new or existing dashboard. You might find this useful when investigating an anomaly and want to quickly populate a dashboard with potentially correlated metrics.
46
+icon" class="image-inline" /> to quickly add that chart to a new or existing dashboard. You might find this useful when
47
+investigating an anomaly and want to quickly populate a dashboard with potentially correlated metrics.
48
49
## Pin dashboards and navigate through Netdata Cloud
50
@@ -49,8 +52,6 @@ Click on the **Pin** button in any dashboard to put those charts into a separate
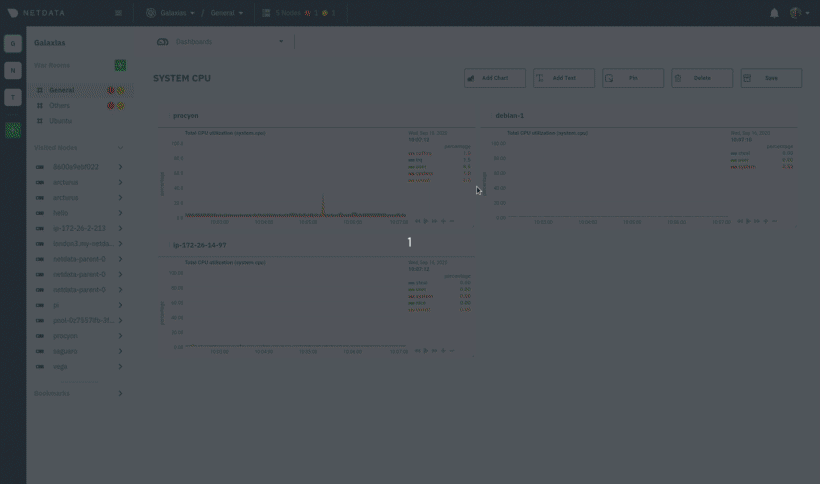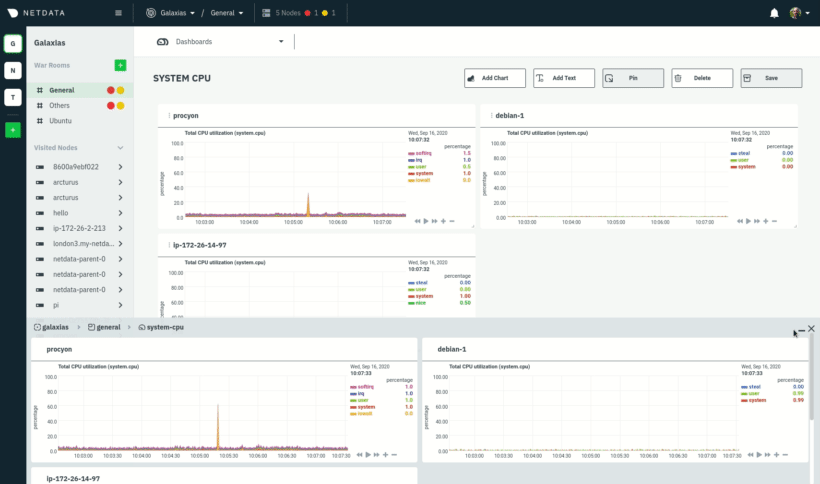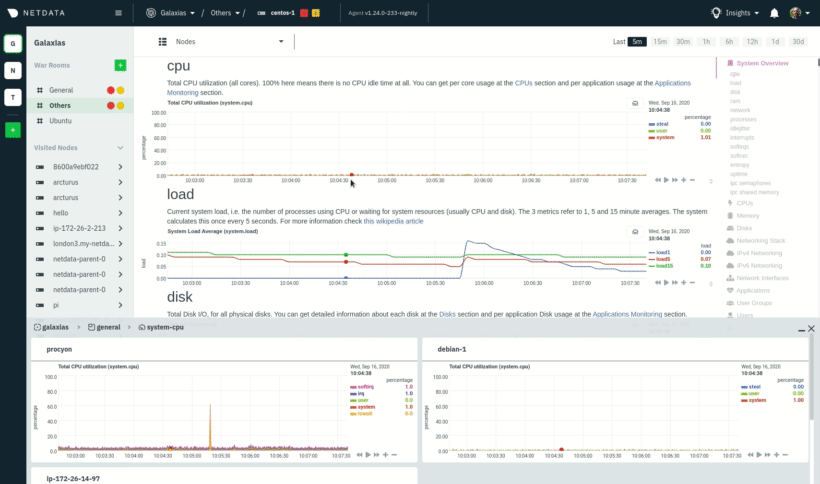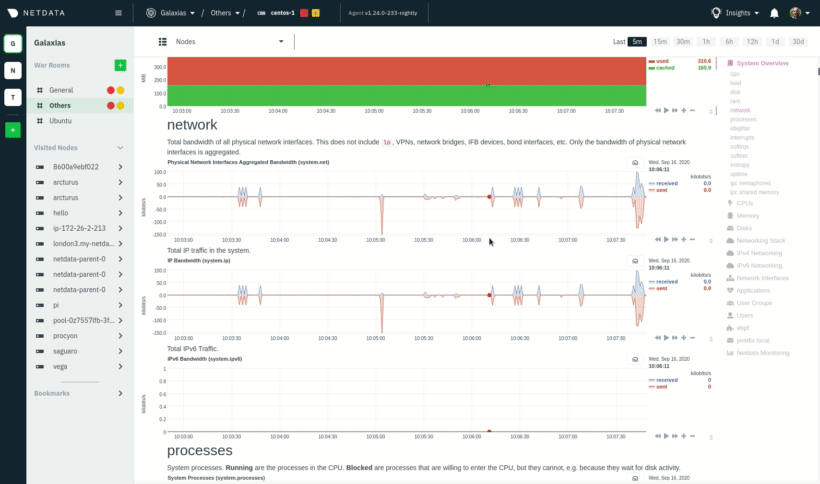
52
can now navigate through Netdata Cloud freely, individual Cloud dashboards, the Nodes view, different War Rooms, or even
53
different Spaces, and have those valuable metrics follow you.
54
52
-
53
-
55
Pinning dashboards helps you correlate potentially related charts across your infrastructure and discover root causes
56
faster.
57
docs/visualize/interact-dashboards-charts.md
+3
-3
@@ -83,8 +83,8 @@ Whenever you use a chart in this way, Netdata synchronizes all the other charts
83
| **Zoom** to a specific timeframe | `SHIFT` + `mouse selection` | | |
84
| **Zoom** in/out | `SHIFT`/`ALT` + `mouse scrollwheel` | `SHIFT`/`ALT` + `two-finger pinch` (touchpad/touchscreen) | `SHIFT`/`ALT` + `two-finger scroll` (touchpad/touchscreen) |
85
86
-
86
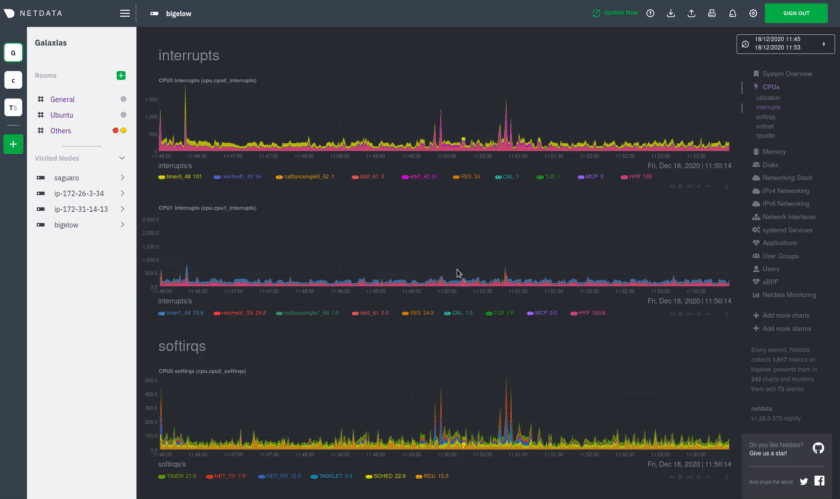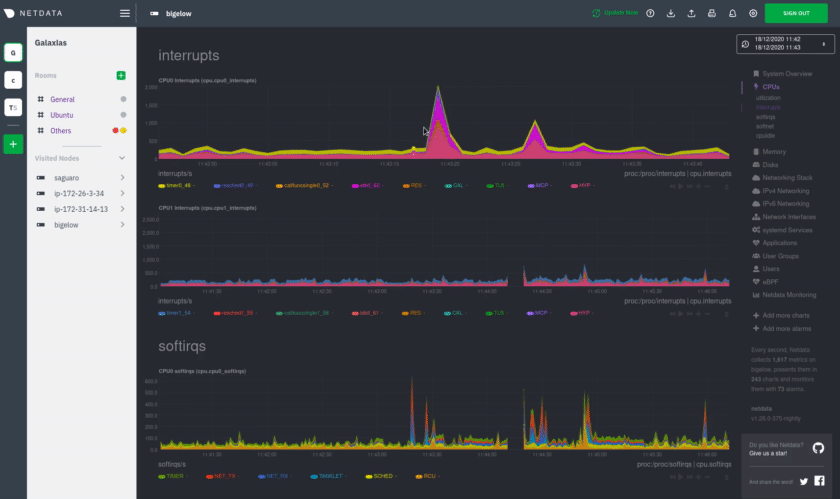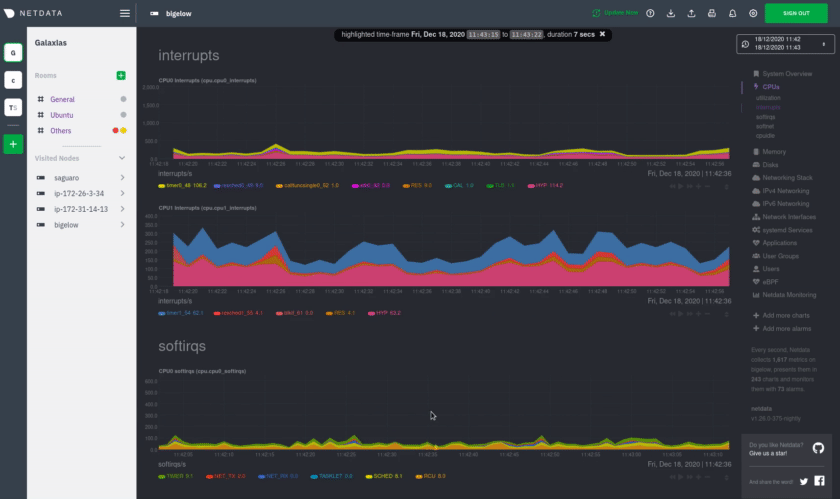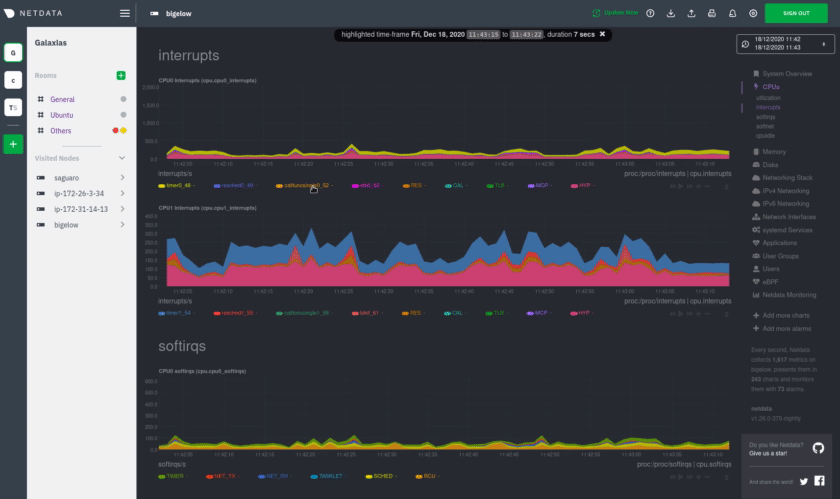
+
88
89
These interactions can also be triggered using the icons on the bottom-right corner of every chart. They are,
90
respectively, `Pan Left`, `Reset`, `Pan Right`, `Zoom In`, and `Zoom Out`.
@@ -97,7 +97,7 @@ You can resize any chart by clicking-and-dragging the icon on the bottom-right c
97
to its original height, double-click the same icon.
98
99
100
+height](https://user-images.githubusercontent.com/1153921/102652691-24b25c00-412b-11eb-9e2c-95325fcedc67.gif)
101
102
### Composite charts in Netdata Cloud
103
docs/visualize/overview-infrastructure.md
+1
-1
@@ -15,7 +15,7 @@ anomalies, then drill down with filtering or single-node dashboards to see more.
15
each chart visualizes average or sum metrics values from across 5 distributed nodes.
16
17

18
+Overview](https://user-images.githubusercontent.com/1153921/102651377-b1f4b100-4129-11eb-8e60-d2995d258c16.png)
19
20
## Using the Overview
21
exporting/README.md
+3
@@ -17,6 +17,9 @@ databases](/docs/export/external-databases.md), or jump in to [enabling a connec
17
The exporting engine has a modular structure and supports metric exporting via multiple exporting connector instances at
18
the same time. You can have different update intervals and filters configured for every exporting connector instance.
19
20
+When you enable the exporting engine and a connector, the Netdata Agent exports metrics _beginning from the time you
21
+restart its process_, not the entire [database of long-term metrics](/docs/store/change-metrics-storage.md).
22
+
23
The exporting engine has its own configuration file `exporting.conf`. The configuration is almost similar to the
24
deprecated [backends](/backends/README.md#configuration) system. The most important difference is that type of a
25
connector should be specified in a section name before a colon and an instance name after the colon. Also, you can't use