remove "foreach" from health REFERENCE.md (#17106)
Ilya Mashchenko committed
Mar 5, 2024 at 17:02 UTC
149719ca8c3f98de74b7de466f709e4b8ddc191a
1 file changed
+12
-239
src/health/REFERENCE.md
+12
-239
@@ -253,7 +253,7 @@ Netdata parses the following lines. Beneath the table is an in-depth explanation
253
| [`repeat`](#alert-line-repeat) | no | The interval for sending notifications when an alert is in WARNING or CRITICAL mode. |
254
| [`options`](#alert-line-options) | no | Add an option to not clear alerts. |
255
| [`host labels`](#alert-line-host-labels) | no | Restrict an alert or template to a list of matching labels present on a host. |
256
-| [`chart labels`](#alert-line-chart-labels) | no | Restrict an alert or template to a list of matching labels present on a chart. |
256
+| [`chart labels`](#alert-line-chart-labels) | no | Restrict an alert or template to a list of matching labels present on a chart. |
257
| [`summary`](#alert-line-summary) | no | A brief description of the alert. |
258
| [`info`](#alert-line-info) | no | A longer text field that provides more information of this alert |
259
@@ -439,7 +439,7 @@ This line makes a database lookup to find a value. This result of this lookup is
439
The format is:
440
441
```yaml
442
-lookup: METHOD AFTER [at BEFORE] [every DURATION] [OPTIONS] [of DIMENSIONS] [foreach DIMENSIONS]
442
+lookup: METHOD AFTER [at BEFORE] [every DURATION] [OPTIONS] [of DIMENSIONS]
443
```
444
445
The full [database query API](https://github.com/netdata/netdata/blob/master/src/web/api/queries/README.md) is supported. In short:
@@ -467,12 +467,6 @@ The full [database query API](https://github.com/netdata/netdata/blob/master/src
467
`,` or `|` instead of spaces)_ and the `match-ids` and `match-names` options affect the searches
468
for dimensions.
469
470
-- `foreach DIMENSIONS` is optional and works only with [templates](#alert-line-alarm-or-template), will always be the last parameter, and uses the same `,`/`|`
471
- rules as the `of` parameter. Each dimension you specify in `foreach` will use the same rule
472
- to trigger an alert. If you set both `of` and `foreach`, Netdata will ignore the `of` parameter
473
- and replace it with one of the dimensions you gave to `foreach`. This option allows you to
474
- [use dimension templates to create dynamic alerts](#use-dimension-templates-to-create-dynamic-alerts).
475
-
470
The result of the lookup will be available as `$this` and `$NAME` in expressions.
471
The timestamps of the timeframe evaluated by the database lookup is available as variables
472
`$after` and `$before` (both are unix timestamps).
@@ -877,17 +871,17 @@ context are essentially identical, with the only difference being the family tha
871
- `$update_every` is the update frequency of the chart
872
- `$green` and `$red` the threshold defined in alerts (these are per chart - the charts inherits them from the first alert that defined them)
873
880
- Chart dimensions define their last calculated (i.e. interpolated) value, exactly as
881
- shown on the charts, but also a variable with their name and suffix `_raw` that resolves
882
- to the last collected value - as collected and another with suffix `_last_collected_t`
883
- that resolves to unix timestamp the dimension was last collected (there may be dimensions
884
- that fail to be collected while others continue normally).
874
+ > Chart dimensions define their last calculated (i.e. interpolated) value, exactly as
875
+ shown on the charts, but also a variable with their name and suffix `_raw` that resolves
876
+ to the last collected value - as collected and another with suffix `_last_collected_t`
877
+ that resolves to unix timestamp the dimension was last collected (there may be dimensions
878
+ that fail to be collected while others continue normally).
879
880
- **host variables**. All the dimensions of all charts, including all alerts, in fullname.
881
Fullname is `CHART.VARIABLE`, where `CHART` is either the chart id or the chart name (both
882
are supported).
883
890
-- **special variables\*** are:
884
+- **special variables** are:
885
886
- `$this`, which is resolved to the value of the current alert.
887
@@ -1069,44 +1063,7 @@ Note that the drops chart does not exist if a network interface has never droppe
1063
When Netdata detects a dropped packet, it will add the chart, and it will automatically attach this
1064
alert to it.
1065
1072
-### Example 5 - CPU usage
1073
-
1074
-Check if user or system dimension is using more than 50% of cpu:
1075
-
1076
-```yaml
1077
-template: cpu_template
1078
- on: system.cpu
1079
- os: linux
1080
- lookup: average -1m foreach system,user
1081
- units: %
1082
- every: 10s
1083
- warn: $this > 50
1084
- crit: $this > 80
1085
-```
1086
-
1087
-The `lookup` line will calculate the average CPU usage from system and user over the last minute. Because we have
1088
-the foreach in the `lookup` line, Netdata will create two independent alerts called `cpu_template_system`
1089
-and `dim_template_user` that will have all the other parameters shared among them.
1090
-
1091
-### Example 6 - CPU usage
1092
-
1093
-Check if all dimensions are using more than 50% of cpu:
1094
-
1095
-```yaml
1096
-template: cpu_template
1097
- on: system.cpu
1098
- os: linux
1099
- lookup: average -1m foreach *
1100
- units: %
1101
- every: 10s
1102
- warn: $this > 50
1103
- crit: $this > 80
1104
-```
1105
-
1106
-The `lookup` line will calculate the average of CPU usage from system and user over the last minute. In this case
1107
-Netdata will create alerts for all dimensions of the chart.
1108
-
1109
-### Example 7 - Z-Score based alert
1066
+### Example 5 - Z-Score based alert
1067
1068
Derive a "[Z Score](https://en.wikipedia.org/wiki/Standard_score)" based alert on `user` dimension of the `system.cpu` chart:
1069
@@ -1132,28 +1089,7 @@ lookup: mean -10s of user
1089
1090
Since [`z = (x - mean) / stddev`](https://en.wikipedia.org/wiki/Standard_score) we create two input alerts, one for `mean` and one for `stddev` and then use them both as inputs in our final `cpu_user_zscore` alert.
1091
1135
-### Example 8 - [Anomaly rate](https://github.com/netdata/netdata/blob/master/src/ml/README.md#anomaly-rate) based CPU dimensions alert
1136
-
1137
-Warning if 5 minute rolling [anomaly rate](https://github.com/netdata/netdata/blob/master/src/ml/README.md#anomaly-rate) for any CPU dimension is above 5%, critical if it goes above 20%:
1138
-
1139
-```yaml
1140
-template: ml_5min_cpu_dims
1141
- on: system.cpu
1142
- os: linux
1143
- hosts: *
1144
- lookup: average -5m anomaly-bit foreach *
1145
- calc: $this
1146
- units: %
1147
- every: 30s
1148
- warn: $this > (($status >= $WARNING) ? (5) : (20))
1149
- crit: $this > (($status == $CRITICAL) ? (20) : (100))
1150
- info: rolling 5min anomaly rate for each system.cpu dimension
1151
-```
1152
-
1153
-The `lookup` line will calculate the average anomaly rate of each `system.cpu` dimension over the last 5 minues. In this case
1154
-Netdata will create alerts for all dimensions of the chart.
1155
-
1156
-### Example 9 - [Anomaly rate](https://github.com/netdata/netdata/blob/master/src/ml/README.md#anomaly-rate) based CPU chart alert
1092
+### Example 6 - [Anomaly rate](https://github.com/netdata/netdata/blob/master/src/ml/README.md#anomaly-rate) based CPU chart alert
1093
1094
Warning if 5 minute rolling [anomaly rate](https://github.com/netdata/netdata/blob/master/src/ml/README.md#anomaly-rate) averaged across all CPU dimensions is above 5%, critical if it goes above 20%:
1095
@@ -1174,7 +1110,7 @@ template: ml_5min_cpu_chart
1110
The `lookup` line will calculate the average anomaly rate across all `system.cpu` dimensions over the last 5 minues. In this case
1111
Netdata will create one alert for the chart.
1112
1177
-### Example 10 - [Anomaly rate](https://github.com/netdata/netdata/blob/master/src/ml/README.md#anomaly-rate) based node level alert
1113
+### Example 7 - [Anomaly rate](https://github.com/netdata/netdata/blob/master/src/ml/README.md#anomaly-rate) based node level alert
1114
1115
Warning if 5 minute rolling [anomaly rate](https://github.com/netdata/netdata/blob/master/src/ml/README.md#anomaly-rate) averaged across all ML enabled dimensions is above 5%, critical if it goes above 20%:
1116
@@ -1192,170 +1128,7 @@ template: ml_5min_node
1128
info: rolling 5min anomaly rate for all ML enabled dims
1129
```
1130
1195
-The `lookup` line will use the `anomaly_rate` dimension of the `anomaly_detection.anomaly_rate` ML chart to calculate the average [node level anomaly rate](https://github.com/netdata/netdata/blob/master/src/ml/README.md#node-anomaly-rate) over the last 5 minues.
1196
-
1197
-## Use dimension templates to create dynamic alerts
1198
-
1199
-In v1.18 of Netdata, we introduced **dimension templates** for alerts, which simplifies the process of
1200
-writing [alert entities](#health-entity-reference) for
1201
-charts with many dimensions.
1202
-
1203
-Dimension templates can condense many individual entities into one—no more copy-pasting one entity and changing the
1204
-`alarm`/`template` and `lookup` lines for each dimension you'd like to monitor.
1205
-
1206
-### The fundamentals of `foreach`
1207
-
1208
-> **Note**: works only with [templates](#alert-line-alarm-or-template).
1209
-
1210
-Our dimension templates update creates a new `foreach` parameter to the
1211
-existing [`lookup` line](#alert-line-lookup). This
1212
-is where the magic happens.
1213
-
1214
-You use the `foreach` parameter to specify which dimensions you want to monitor with this single alert. You can separate
1215
-them with a comma (`,`) or a pipe (`|`). You can also use
1216
-a [Netdata simple pattern](https://github.com/netdata/netdata/blob/master/src/libnetdata/simple_pattern/README.md) to create
1217
-many alerts with a regex-like syntax.
1218
-
1219
-The `foreach` parameter _has_ to be the last parameter in your `lookup` line, and if you have both `of` and `foreach` in
1220
-the same `lookup` line, Netdata will ignore the `of` parameter and use `foreach` instead.
1221
-
1222
-Let's get into some examples, so you can see how the new parameter works.
1223
-
1224
-> ⚠️ The following entities are examples to showcase the functionality and syntax of dimension templates. They are not
1225
-> meant to be run as-is on production systems.
1226
-
1227
-### Condensing entities with `foreach`
1228
-
1229
-Let's say you want to monitor the `system`, `user`, and `nice` dimensions in your system's overall CPU utilization.
1230
-Before dimension templates, you would need the following three entities:
1231
-
1232
-```yaml
1233
- alarm: cpu_system
1234
- on: system.cpu
1235
-lookup: average -10m of system
1236
- every: 1m
1237
- warn: $this > 50
1238
- crit: $this > 80
1239
-
1240
- alarm: cpu_user
1241
- on: system.cpu
1242
-lookup: average -10m of user
1243
- every: 1m
1244
- warn: $this > 50
1245
- crit: $this > 80
1246
-
1247
- alarm: cpu_nice
1248
- on: system.cpu
1249
-lookup: average -10m of nice
1250
- every: 1m
1251
- warn: $this > 50
1252
- crit: $this > 80
1253
-```
1254
-
1255
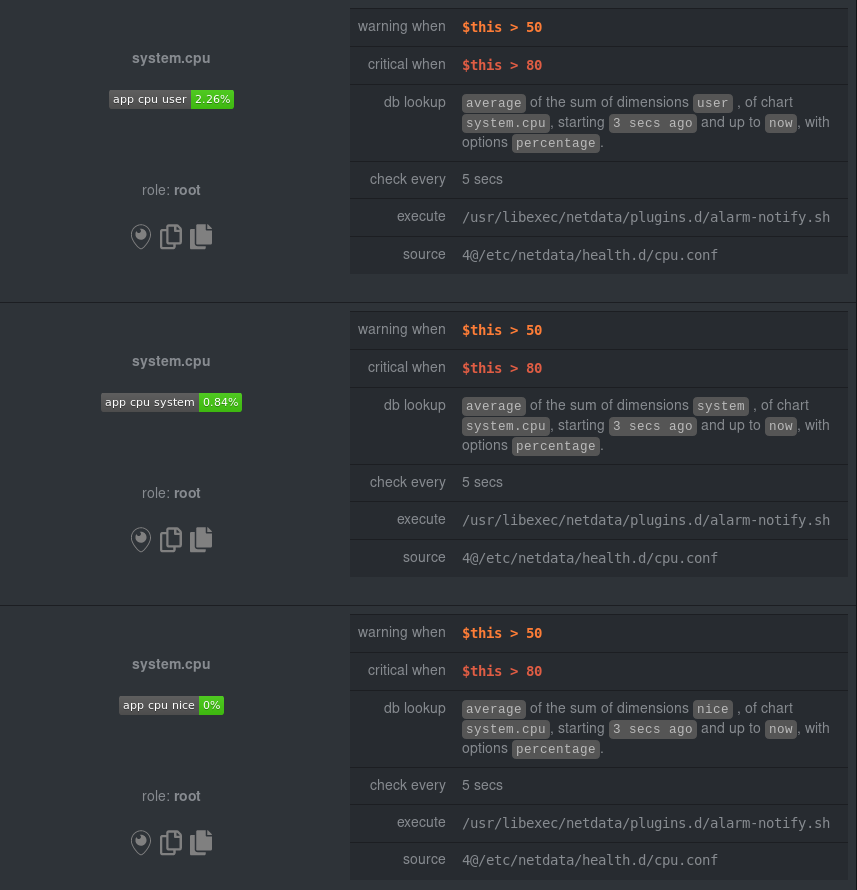
-With dimension templates, you can condense these into a single template. Take note of the `lookup` line.
1256
-
1257
-```yaml
1258
-template: cpu_template
1259
- on: system.cpu
1260
- lookup: average -10m foreach system,user,nice
1261
- every: 1m
1262
- warn: $this > 50
1263
- crit: $this > 80
1264
-```
1265
-
1266
-The `template` line specifies the naming scheme Netdata will use. You can use whatever naming scheme you'd like, with `.`
1267
-and `_` being the only allowed symbols.
1268
-
1269
-The `lookup` line has changed from `of` to `foreach`, and we're now passing three dimensions.
1270
-
1271
-In this example, Netdata will create three alerts with the names `cpu_template_system`, `cpu_template_user`, and
1272
-`cpu_template_nice`. Every minute, each alert will use the same database query to calculate the average CPU usage for
1273
-the `system`, `user`, and `nice` dimensions over the last 10 minutes and send out alerts if necessary.
1274
-
1275
-You can find these three alerts active by clicking on the **Alerts** button in the top navigation, and then clicking on
1276
-the **All** tab and scrolling to the **system - cpu** collapsible section.
1277
-
1278
-
1279
-
1280
-Let's look at some other examples of how `foreach` works, so you can best apply it in your configurations.
1281
-
1282
-### Using a Netdata simple pattern in `foreach`
1283
-
1284
-In the last example, we used `foreach system,user,nice` to create three distinct alerts using dimension templates. But
1285
-what if you want to quickly create alerts for _all_ the dimensions of a given chart?
1286
-
1287
-Use a [simple pattern](https://github.com/netdata/netdata/blob/master/src/libnetdata/simple_pattern/README.md)! One example of a simple pattern is a single wildcard
1288
-(`*`).
1289
-
1290
-Instead of monitoring system CPU usage, let's monitor per-application CPU usage using the `apps.cpu` chart. Passing a
1291
-wildcard as the simple pattern tells Netdata to create a separate alert for _every_ process on your system:
1292
-
1293
-```yaml
1294
- alarm: app_cpu
1295
- on: apps.cpu
1296
-lookup: average -10m percentage foreach *
1297
- every: 1m
1298
- warn: $this > 50
1299
- crit: $this > 80
1300
-```
1301
-
1302
-This entity will now create alerts for every dimension in the `apps.cpu` chart. Given that most `apps.cpu` charts have
1303
-10 or more dimensions, using the wildcard ensures you catch every CPU-hogging process.
1304
-
1305
-To learn more about how to use simple patterns with dimension templates, see
1306
-our [simple patterns documentation](https://github.com/netdata/netdata/blob/master/src/libnetdata/simple_pattern/README.md).
1307
-
1308
-### Using `foreach` with alert templates
1309
-
1310
-Dimension templates also work
1311
-with [alert templates](#alert-line-alarm-or-template).
1312
-Alert templates help you create alerts for all the charts with a given context—for example, all the cores of your
1313
-system's CPU.
1314
-
1315
-By combining the two, you can create dozens of individual alerts with a single template entity. Here's how you would
1316
-create alerts for the `system`, `user`, and `nice` dimensions for every chart in the `cpu.cpu` context—or, in other
1317
-words, every CPU core.
1318
-
1319
-```yaml
1320
-template: cpu_template
1321
- on: cpu.cpu
1322
- lookup: average -10m percentage foreach system,user,nice
1323
- every: 1m
1324
- warn: $this > 50
1325
- crit: $this > 80
1326
-```
1327
-
1328
-On a system with a 6-core, 12-thread Ryzen 5 1600 CPU, this one entity creates alerts on the following charts and
1329
-dimensions:
1330
-
1331
-- `cpu.cpu0`
1332
- - `cpu_template_user`
1333
- - `cpu_template_system`
1334
- - `cpu_template_nice`
1335
-
1336
-- `cpu.cpu1`
1337
- - `cpu_template_user`
1338
- - `cpu_template_system`
1339
- - `cpu_template_nice`
1340
-
1341
-- `cpu.cpu2`
1342
- - `cpu_template_user`
1343
- - `cpu_template_system`
1344
- - `cpu_template_nice`
1345
-
1346
-- ...
1347
-
1348
-- `cpu.cpu11`
1349
- - `cpu_template_user`
1350
- - `cpu_template_system`
1351
- - `cpu_template_nice`
1352
-
1353
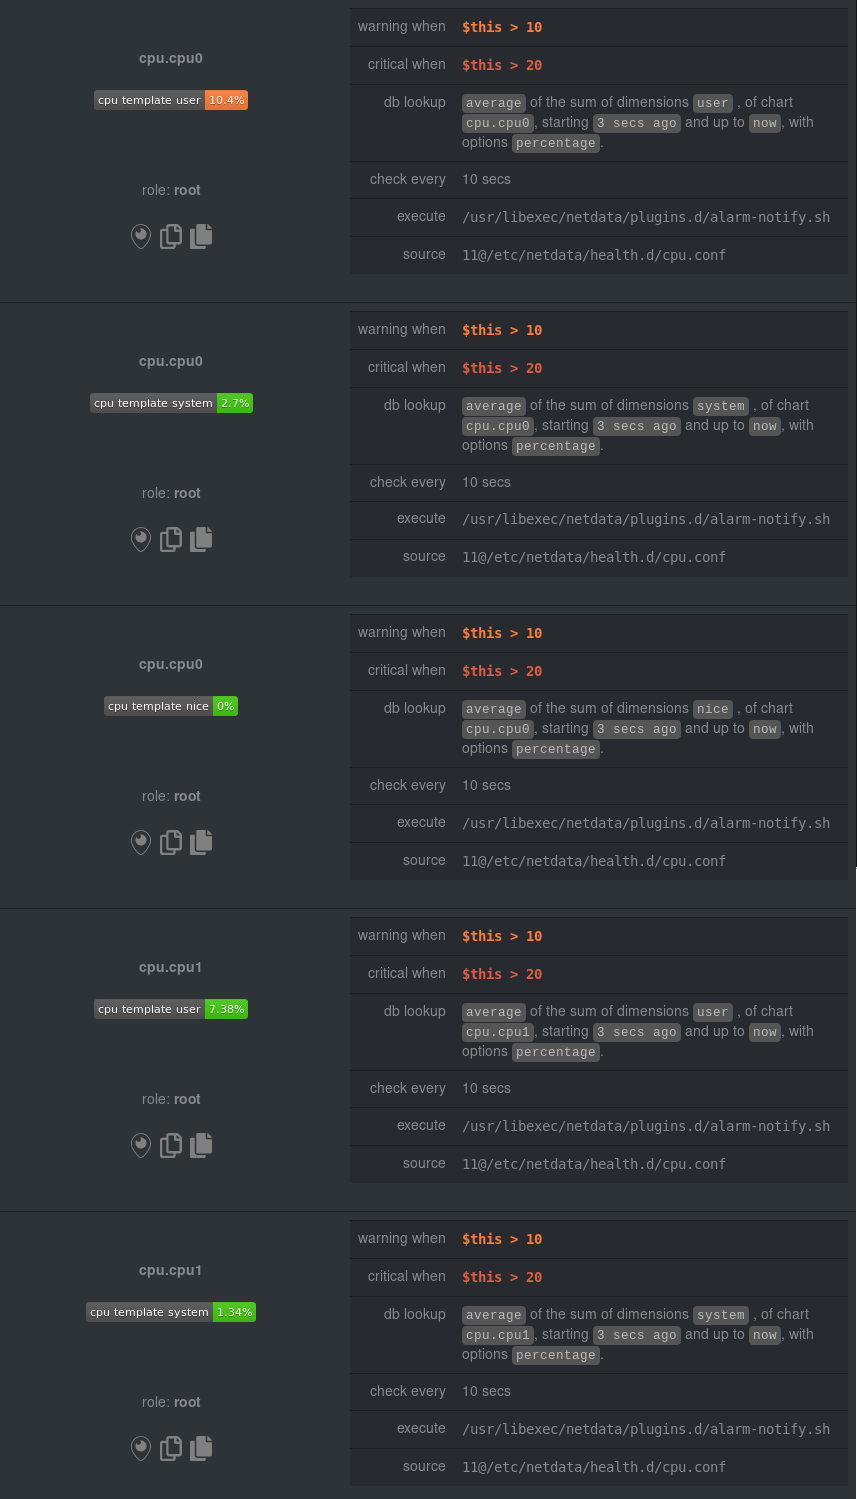
-And how just a few of those dimension template-generated alerts look like in the Netdata dashboard.
1354
-
1355
-
1356
-
1357
-All in all, this single entity creates 36 individual alerts. Much easier than writing 36 separate entities in your
1358
-health configuration files!
1131
+The `lookup` line will use the `anomaly_rate` dimension of the `anomaly_detection.anomaly_rate` ML chart to calculate the average [node level anomaly rate](https://github.com/netdata/netdata/blob/master/src/ml/README.md#node-anomaly-rate) over the last 5 minutes.
1132
1133
## Troubleshooting
1134