Add guide: Monitor any process in real-time with Netdata (#10338)
* Init process guide * Continue work on process guide * Finish initial draft * Tweak eBPF guide * Fixes for Amy
Joel Hans committed
Dec 8, 2020 at 13:56 UTC
2cb06e5a3ef88f6915bb414b362627a93cd5f746
5 files changed
+352
-55
collectors/apps.plugin/README.md
+24
-25
@@ -1,8 +1,7 @@
1
<!--
2
----
2
title: "apps.plugin"
3
+sidebar_label: "Application monitoring (apps.plugin)"
4
custom_edit_url: https://github.com/netdata/netdata/edit/master/collectors/apps.plugin/README.md
5
----
5
-->
6
7
# apps.plugin
@@ -39,35 +38,35 @@ that fork/spawn other short lived processes hundreds of times per second.
38
39
Each of these sections provides the same number of charts:
40
42
-- CPU Utilization
41
+- CPU utilization (`apps.cpu`)
42
- Total CPU usage
44
- - User / System CPU usage
43
+ - User/system CPU usage (`apps.cpu_user`/`apps.cpu_system`)
44
- Disk I/O
46
- - Physical Reads / Writes
47
- - Logical Reads / Writes
48
- - Open Unique Files (if a file is found open multiple times, it is counted just once)
45
+ - Physical reads/writes (`apps.preads`/`apps.pwrites`)
46
+ - Logical reads/writes (`apps.lreads`/`apps.lwrites`)
47
+ - Open unique files (if a file is found open multiple times, it is counted just once, `apps.files`)
48
- Memory
50
- - Real Memory Used (non shared)
51
- - Virtual Memory Allocated
52
- - Minor Page Faults (i.e. memory activity)
49
+ - Real Memory Used (non-shared, `apps.mem`)
50
+ - Virtual Memory Allocated (`apps.vmem`)
51
+ - Minor page faults (i.e. memory activity, `apps.minor_faults`)
52
- Processes
54
- - Threads Running
55
- - Processes Running
56
- - Pipes Open
57
- - Carried Over Uptime (since the Netdata restart)
58
- - Minimum Uptime
59
- - Average Uptime
60
- - Maximum Uptime
61
-
62
-- Swap Memory
63
- - Swap Memory Used
64
- - Major Page Faults (i.e. swap activity)
53
+ - Threads running (`apps.threads`)
54
+ - Processes running (`apps.processes`)
55
+ - Carried over uptime (since the last Netdata Agent restart, `apps.uptime`)
56
+ - Minimum uptime (`apps.uptime_min`)
57
+ - Average uptime (`apps.uptime_average`)
58
+ - Maximum uptime (`apps.uptime_max`)
59
+ - Pipes open (`apps.pipes`)
60
+- Swap memory
61
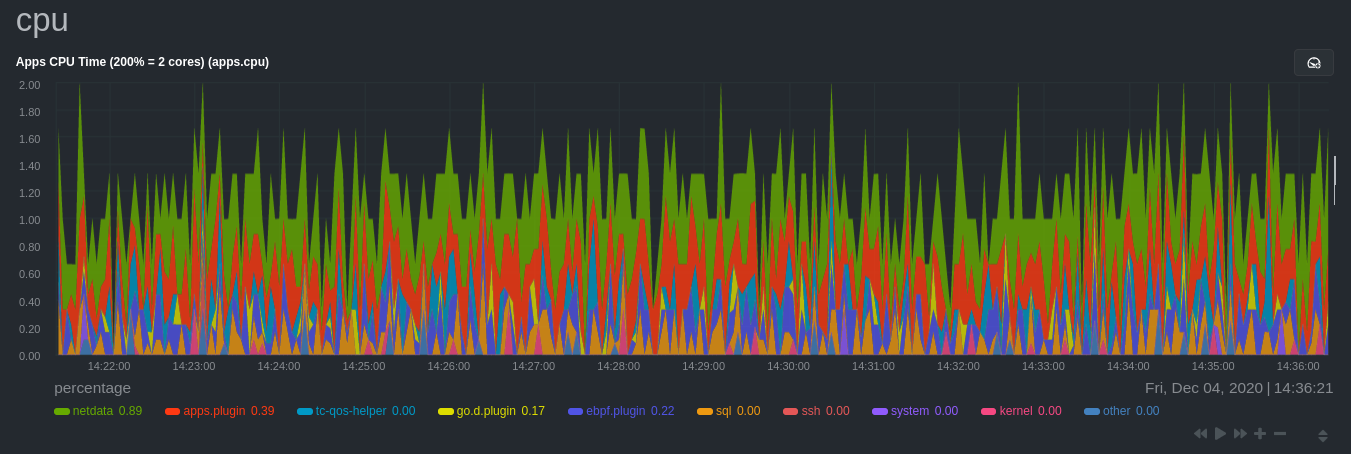
+ - Swap memory used (`apps.swap`)
62
+ - Major page faults (i.e. swap activiy, `apps.major_faults`)
63
- Network
66
- - Sockets Open
67
-
68
-In addition, if the [eBPF collector](/collectors/ebpf.plugin/README.md) is running, your dashboard will also show
69
-an additional [list](/collectors/ebpf.plugin/README.md#integration-with-appsplugin) of charts using low-level Linux metrics.
64
+ - Sockets open (`apps.sockets`)
65
66
+In addition, if the [eBPF collector](/collectors/ebpf.plugin/README.md) is running, your dashboard will also show an
67
+additional [list of charts](/collectors/ebpf.plugin/README.md#integration-with-appsplugin) using low-level Linux
68
+metrics.
69
+
70
The above are reported:
71
72
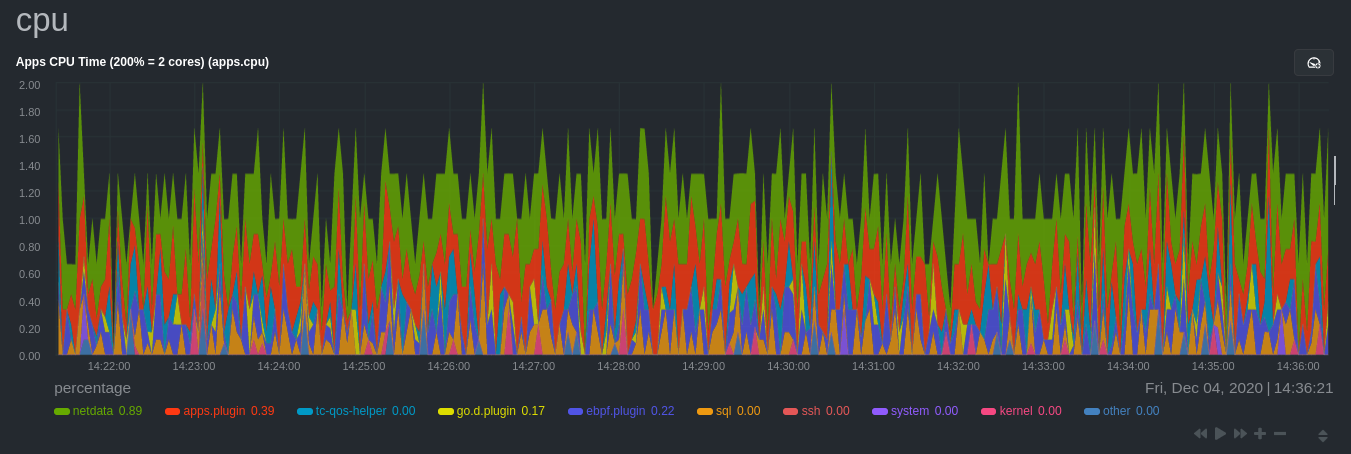
- For **Applications** per target configured.
collectors/ebpf.plugin/README.md
+17
-14
@@ -156,24 +156,27 @@ The eBPF collector also creates charts for each running application through an i
156
interact with the Linux kernel.
157
158
When the integration is enabled, your dashboard will also show the following charts using low-level Linux metrics:
159
-
160
-- eBPF syscall
161
- - Number of calls to open files.
162
- - Number of files closed.
163
- - Number of calls to delete files.
164
- - Number of calls to `vfs_write`.
165
- - Number of calls to `vfs_read`.
166
- - Number of bytes written trough `vfs_write`
167
- - Number of bytes read trough `vfs_read`
168
- - Number of process created trough `do_fork`
169
- - Number of threads created trough `do_fork` or `__x86_64_sys_clone`, depending on your system's kernel version.
170
- - Number of times that a process called `do_exit`.
159
+
160
+- eBPF file
161
+ - Number of calls to open files. (`apps.file_open`)
162
+ - Number of files closed. (`apps.file_closed`)
163
- Number of calls to open files that returned errors.
164
- Number of calls to close files that returned errors.
165
+- eBPF syscall
166
+ - Number of calls to delete files. (`apps.file_deleted`)
167
+ - Number of calls to `vfs_write`. (`apps.vfs_write_call`)
168
+ - Number of calls to `vfs_read`. (`apps.vfs_read_call`)
169
+ - Number of bytes written with `vfs_write`. (`apps.vfs_write_bytes`)
170
+ - Number of bytes read with `vfs_read`. (`apps.vfs_read_bytes`)
171
+ - Number of calls to write a file that returned errors.
172
- Number of calls to read a file that returned errors.
174
- - Number of calls to read a file that returned errors.
173
+- eBPF process
174
+ - Number of process created with `do_fork`. (`apps.process_create`)
175
+ - Number of threads created with `do_fork` or `__x86_64_sys_clone`, depending on your system's kernel version. (`apps.thread_create`)
176
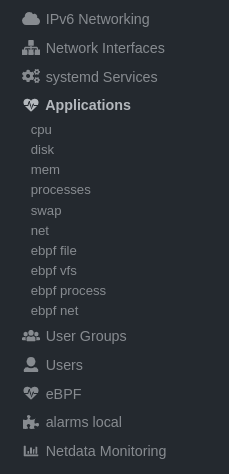
+ - Number of times that a process called `do_exit`. (`apps.task_close`)
177
- eBPF net
176
- - Number of bytes transmited per seconds.
178
+ - Number of bytes sent. (`apps.bandwidth_sent`)
179
+ - Number of bytes received. (`apps.bandwidth_recv`)
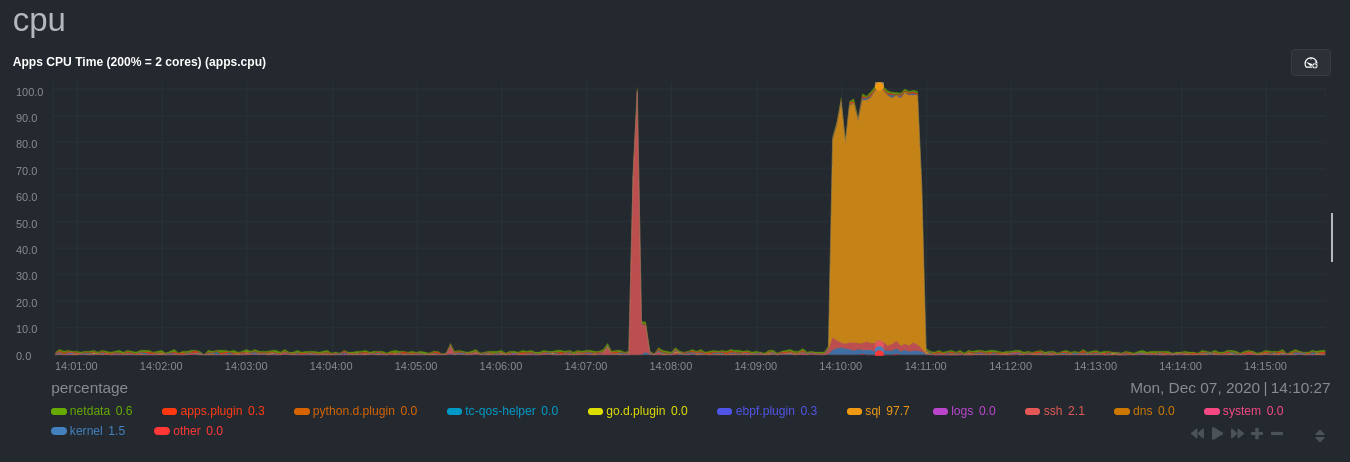
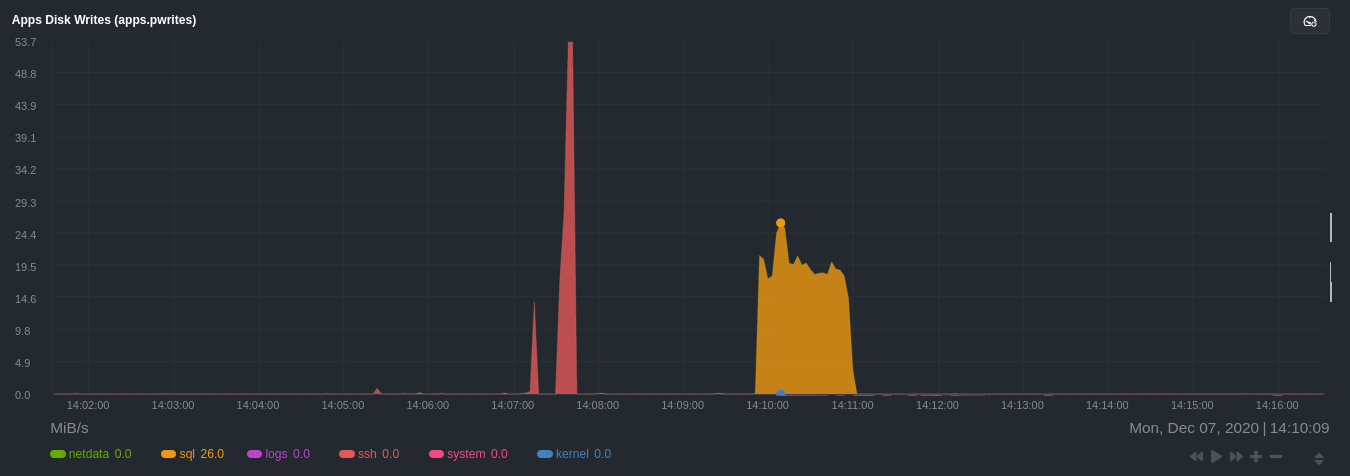
180
181
If you want to _disable_ the integration with `apps.plugin` along with the above charts, change the setting `apps` to
182
`no`.
docs/guides/monitor/process.md
new
+299
@@ -0,0 +1,299 @@
1
+<!--
2
+title: Monitor any process in real-time with Netdata
3
+description: "Tap into Netdata's powerful collectors, with per-second utilization metrics for every process, to troubleshoot faster and make data-informed decisions."
4
+image: /img/seo/guides/monitor/process.png
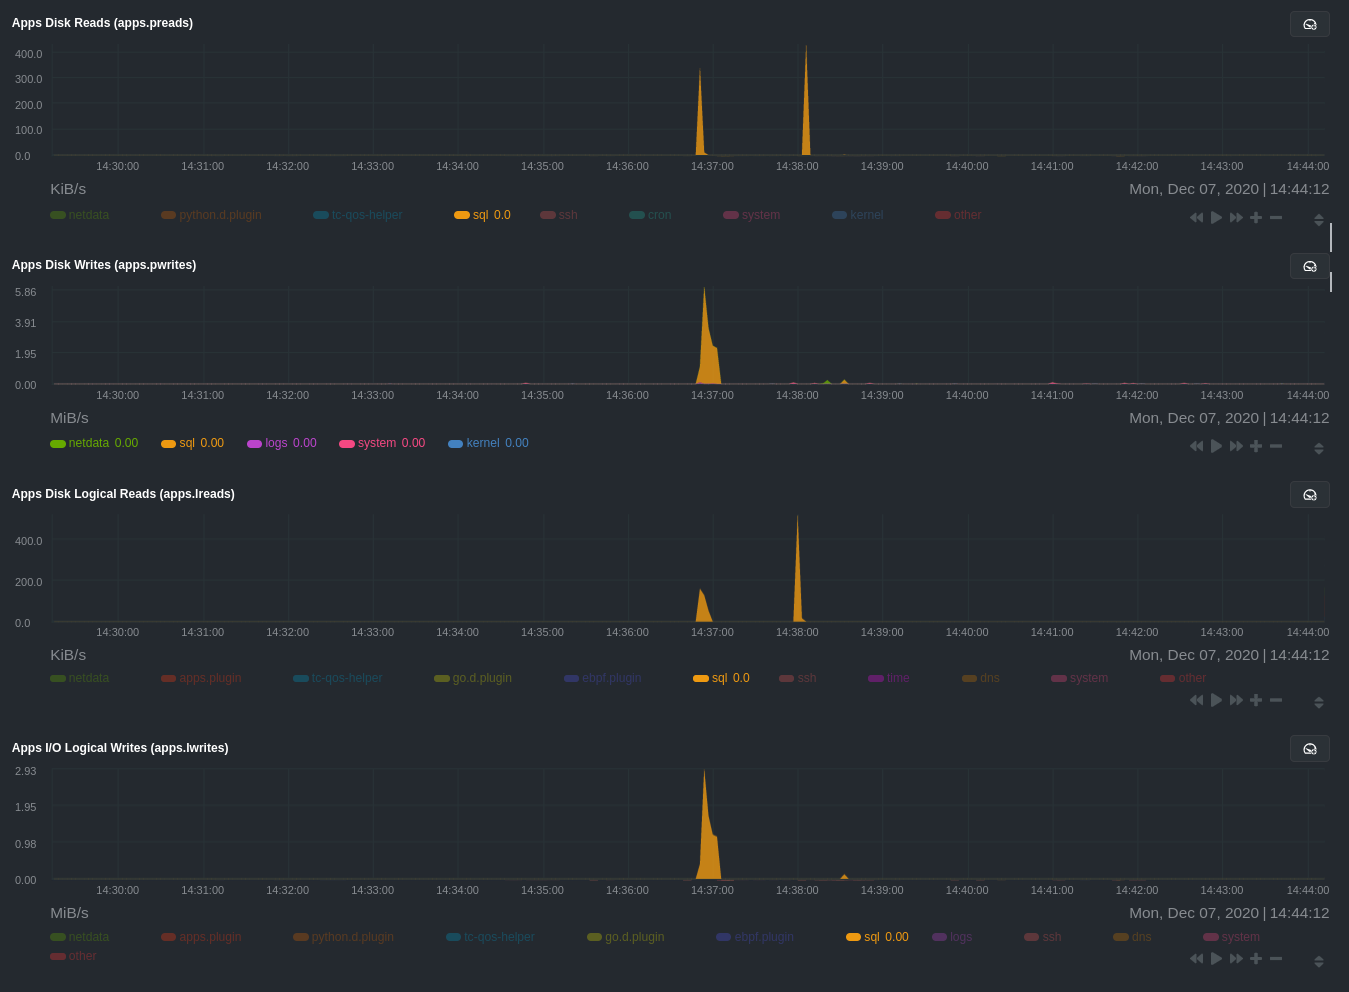
5
+custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/guides/monitor/process.md
6
+-->
7
+
8
+# Monitor any process in real-time with Netdata
9
+
10
+Netdata is more than a multitude of generic system-level metrics and visualizations. Instead of providing only a bird's
11
+eye view of your system, leaving you to wonder exactly _what_ is taking up 99% CPU, Netdata also gives you visibility
12
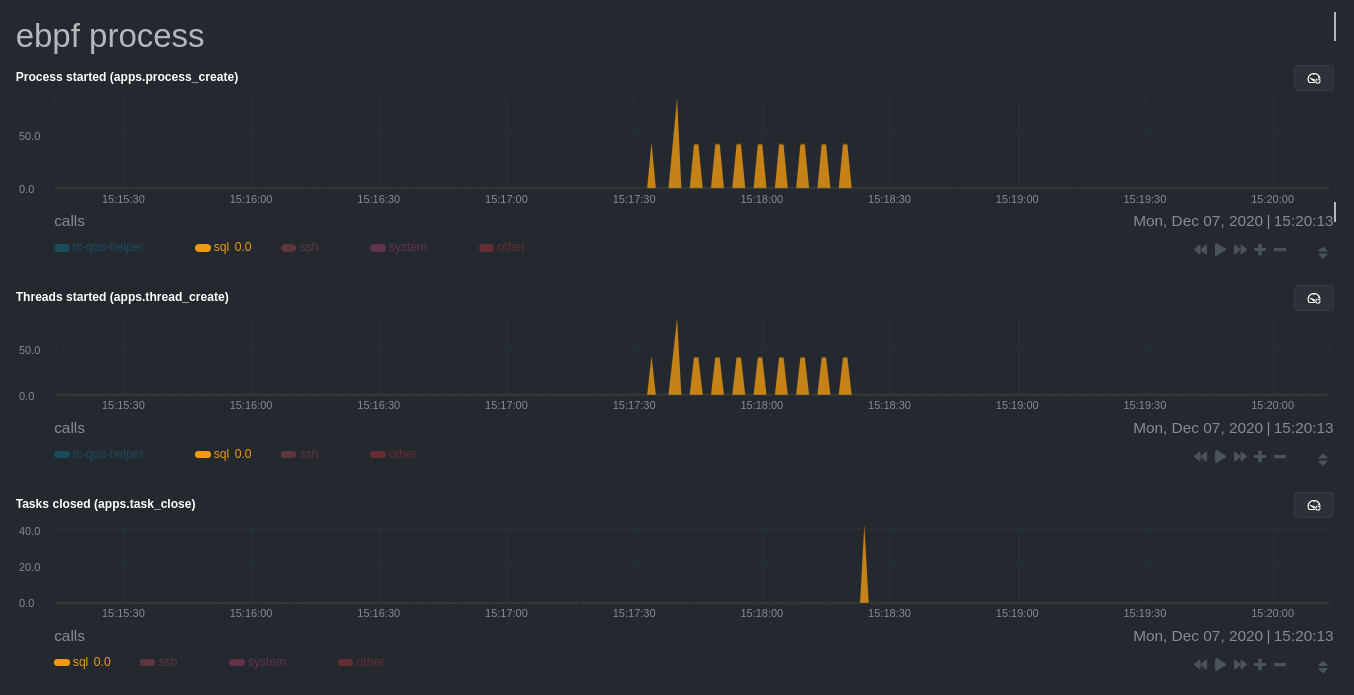
+into _every layer_ of your node. These additional layers give you context, and meaningful insights, into the true health
13
+and performance of your infrastructure.
14
+
15
+One of these layers is the _process_. Every time a Linux system runs a program, it creates an independent process that
16
+executes the program's instructions in parallel with anything else happening on the system. Linux systems track the
17
+state and resource utilization of processes using the [`/proc` filesystem](https://en.wikipedia.org/wiki/Procfs), and
18
+Netdata is designed to hook into those metrics to create meaningul visualizations out of the box.
19
+
20
+While there are a lot of existing command-line tools for tracking processes on Linux systems, such as `ps` or `top`,
21
+only Netdata provides dozens of real-time charts, at both per-second and event frequency, without you having to write
22
+SQL queries or know a bunch of arbitrary command-line flags.
23
+
24
+With Netdata's process monitoring, you can:
25
+
26
+- Benchmark/optimize performance of standard applications, like web servers or databases
27
+- Benchmark/optimize performance of custom applications
28
+- Troubleshoot CPU/memory/disk utilization issues (why is my system's CPU spiking right now?)
29
+- Perform granular capacity planning based on the specific needs of your infrastructure
30
+- Search for leaking file descriptors
31
+- Investigate zombie processes
32
+
33
+... and much more. Let's get started.
34
+
35
+## Prerequisites
36
+
37
+- One or more Linux nodes running the [Netdata Agent](/docs/get/README.md). If you need more time to understand
38
+ Netdata before following this guide, see the [infrastructure](/docs/quickstart/infrastructure.md) or
39
+ [single-node](/docs/quickstart/single-node.md) monitoring quickstarts.
40
+- A general understanding of how to [configure the Netdata Agent](/docs/configure/nodes.md) using `edit-config`.
41
+- A Netdata Cloud account. [Sign up](https://app.netdata.cloud) if you don't have one already.
42
+
43
+## How does Netdata do process monitoring?
44
+
45
+The Netdata Agent already knows to look for hundreds of [standard applications that we support via
46
+collectors](/collectors/COLLECTORS.md), and groups them based on their purpose. Let's say you want to monitor a MySQL
47
+database using its process. The Netdata Agent already knows to look for processes with the string `mysqld` in their
48
+name, along with a few others, and puts them into the `sql` group. This `sql` group then becomes a dimension in all
49
+process-specific charts.
50
+
51
+The process and groups settings are used by two unique and powerful collectors.
52
+
53
+[**`apps.plugin`**](/collectors/apps.plugin/README.md) looks at the Linux process tree every second, much like `top` or
54
+`ps fax`, and collects resource utilization information on every running process. It then automatically adds a layer of
55
+meaningful visualization on top of these metrics, and creates per-process/application charts.
56
+
57
+[**`ebpf.plugin`**](/collectors/ebpf.plugin/README.md): Netdata's extended Berkeley Packet Filter (eBPF) collector
58
+monitors Linux kernel-level metrics for file descriptors, virtual filesystem IO, and process management, and then hands
59
+process-specific metrics over to `apps.plugin` for visualization. The eBPF collector also collects and visualizes
60
+metrics on an _event frequency_, which means it captures every kernel interaction, and not just the volume of
61
+interaction at every second in time. That's even more precise than Netdata's standard per-second granularity.
62
+
63
+### Per-process metrics and charts in Netdata
64
+
65
+With these collectors working in parallel, Netdata visualizes the following per-second metrics for _any_ process on your
66
+Linux systems:
67
+
68
+- CPU utilization (`apps.cpu`)
69
+ - Total CPU usage
70
+ - User/system CPU usage (`apps.cpu_user`/`apps.cpu_system`)
71
+- Disk I/O
72
+ - Physical reads/writes (`apps.preads`/`apps.pwrites`)
73
+ - Logical reads/writes (`apps.lreads`/`apps.lwrites`)
74
+ - Open unique files (if a file is found open multiple times, it is counted just once, `apps.files`)
75
+- Memory
76
+ - Real Memory Used (non-shared, `apps.mem`)
77
+ - Virtual Memory Allocated (`apps.vmem`)
78
+ - Minor page faults (i.e. memory activity, `apps.minor_faults`)
79
+- Processes
80
+ - Threads running (`apps.threads`)
81
+ - Processes running (`apps.processes`)
82
+ - Carried over uptime (since the last Netdata Agent restart, `apps.uptime`)
83
+ - Minimum uptime (`apps.uptime_min`)
84
+ - Average uptime (`apps.uptime_average`)
85
+ - Maximum uptime (`apps.uptime_max`)
86
+ - Pipes open (`apps.pipes`)
87
+- Swap memory
88
+ - Swap memory used (`apps.swap`)
89
+ - Major page faults (i.e. swap activiy, `apps.major_faults`)
90
+- Network
91
+ - Sockets open (`apps.sockets`)
92
+- eBPF file
93
+ - Number of calls to open files. (`apps.file_open`)
94
+ - Number of files closed. (`apps.file_closed`)
95
+ - Number of calls to open files that returned errors.
96
+ - Number of calls to close files that returned errors.
97
+- eBPF syscall
98
+ - Number of calls to delete files. (`apps.file_deleted`)
99
+ - Number of calls to `vfs_write`. (`apps.vfs_write_call`)
100
+ - Number of calls to `vfs_read`. (`apps.vfs_read_call`)
101
+ - Number of bytes written with `vfs_write`. (`apps.vfs_write_bytes`)
102
+ - Number of bytes read with `vfs_read`. (`apps.vfs_read_bytes`)
103
+ - Number of calls to write a file that returned errors.
104
+ - Number of calls to read a file that returned errors.
105
+- eBPF process
106
+ - Number of process created with `do_fork`. (`apps.process_create`)
107
+ - Number of threads created with `do_fork` or `__x86_64_sys_clone`, depending on your system's kernel version. (`apps.thread_create`)
108
+ - Number of times that a process called `do_exit`. (`apps.task_close`)
109
+- eBPF net
110
+ - Number of bytes sent. (`apps.bandwidth_sent`)
111
+ - Number of bytes received. (`apps.bandwidth_recv`)
112
+
113
+As an example, here's the per-process CPU utilization chart, including a `sql` group/dimension.
114
+
115
+
117
+
118
+## Configure the Netdata Agent to recognize a specific process
119
+
120
+To monitor any process, you need to make sure the Netdata Agent is aware of it. As mentioned above, the Agent is already
121
+aware of hundreds of processes, and collects metrics from them automatically.
122
+
123
+But, if you want to change the grouping behavior, add an application that isn't yet supported in the Netdata Agent, or
124
+monitor a custom application, you need to edit the `apps_groups.conf` configuration file.
125
+
126
+Navigate to your [Netdata config directory](/docs/configure/nodes.md) and use `edit-config` to edit the file.
127
+
128
+```bash
129
+cd /etc/netdata # Replace this with your Netdata config directory if not at /etc/netdata.
130
+sudo ./edit-config apps_groups.conf
131
+```
132
+
133
+Inside the file are lists of process names, oftentimes using wildcards (`*`), that the Netdata Agent looks for and
134
+groups together. For example, the Netdata Agent looks for processes starting with `mysqld`, `mariad`, `postgres`, and
135
+others, and groups them into `sql`. That makes sense, since all these procesess are for SQL databases.
136
+
137
+```conf
138
+sql: mysqld* mariad* postgres* postmaster* oracle_* ora_* sqlservr
139
+```
140
+
141
+These groups are then reflected as [dimensions](/web/README.md#dimensions) within Netdata's charts.
142
+
143
+
145
+
146
+See the following two sections for details based on your needs. If you don't need to configure `apps_groups.conf`, jump
147
+down to [visualizing process metrics](#visualize-process-metrics).
148
+
149
+### Standard applications (web servers, databases, containers, and more)
150
+
151
+As explained above, the Netdata Agent is already aware of most standard applications you run on Linux nodes, and you
152
+shouldn't need to configure it to discover them.
153
+
154
+However, if you're using multiple applications that the Netdata Agent groups together you may want to separate them for
155
+more precise monitoring. If you're not running any other types of SQL databases on that node, you don't need to change
156
+the grouping, since you know that any MySQL is the only process contributing to the `sql` group.
157
+
158
+Let's say you're using both MySQL and PostgreSQL databases on a single node, and want to monitor their processes
159
+independently. Open the `apps_groups.conf` file as explained in the [section
160
+above](#configure-the-netdata-agent-to-recognize-a-specific-process) and scroll down until you find the `database
161
+servers` section. Create new groups for MySQL and PostgreSQL, and move their process queries into the unique groups.
162
+
163
+```conf
164
+# -----------------------------------------------------------------------------
165
+# database servers
166
+
167
+mysql: mysqld*
168
+postgres: postgres*
169
+sql: mariad* postmaster* oracle_* ora_* sqlservr
170
+```
171
+
172
+Restart Netdata with `service netdata restart`, or the appropriate method for your system, to start collecting
173
+utilization metrics from your application. Time to [visualize your process metrics](#visualize-process-metrics).
174
+
175
+### Custom applications
176
+
177
+Let's assume you have an application that runs on the process `custom-app`. To monitor eBPF metrics for that application
178
+separate from any others, you need to create a new group in `apps_groups.conf` and associate that process name with it.
179
+
180
+Open the `apps_groups.conf` file as explained in the [section
181
+above](#configure-the-netdata-agent-to-recognize-a-specific-process). Scroll down to `# NETDATA processes accounting`.
182
+Above that, paste in the following text, which creates a new `custom-app` group with the `custom-app` process. Replace
183
+`custom-app` with the name of your application's Linux process. `apps_groups.conf` should now look like this:
184
+
185
+```conf
186
+...
187
+# -----------------------------------------------------------------------------
188
+# Custom applications to monitor with apps.plugin and ebpf.plugin
189
+
190
+custom-app: custom-app
191
+
192
+# -----------------------------------------------------------------------------
193
+# NETDATA processes accounting
194
+...
195
+```
196
+
197
+Restart Netdata with `service netdata restart`, or the appropriate method for your system, to start collecting
198
+utilization metrics from your application.
199
+
200
+## Visualize process metrics
201
+
202
+Now that you're collecting metrics for your process, you'll want to visualize them using Netdata's real-time,
203
+interactive charts. Find these visualizations in the same section regardless of whether you use [Netdata
204
+Cloud](https://app.netdata.cloud) for infrastructure monitoring, or single-node monitoring with the local Agent's
205
+dashboard at `http://localhost:19999`.
206
+
207
+If you need a refresher on all the available per-process charts, see the [above
208
+list](#per-process-metrics-and-charts-in-netdata).
209
+
210
+### Using Netdata's application collector (`apps.plugin`)
211
+
212
+`apps.plugin` puts all of its charts under the **Applications** section of any Netdata dashboard.
213
+
214
+
216
+
217
+Let's continue with the MySQL example. We can create a [test
218
+database](https://www.digitalocean.com/community/tutorials/how-to-measure-mysql-query-performance-with-mysqlslap) in
219
+MySQL to generate load on the `mysql` process.
220
+
221
+`apps.plugin` immediately collects and visualizes this activity `apps.cpu` chart, which shows an increase in CPU
222
+utilization from the `sql` group. There is a parallel increase in `apps.pwrites`, which visualizes writes to disk.
223
+
224
+
226
+
227
+
229
+
230
+Next, the `mysqlslap` utility queries the database to provide some benchmarking load on the MySQL database. It won't
231
+look exactly like a production database executing lots of user queries, but it gives you an idea into the possibility of
232
+these visualizations.
233
+
234
+```bash
235
+sudo mysqlslap --user=sysadmin --password --host=localhost --concurrency=50 --iterations=10 --create-schema=employees --query="SELECT * FROM dept_emp;" --verbose
236
+```
237
+
238
+The following per-process disk utilization charts show spikes under the `sql` group at the same time `mysqlslap` was run
239
+numerous times, with slightly different concurrency and query options.
240
+
241
+
243
+
244
+> 💡 Click on any dimension below a chart in Netdata Cloud (or to the right of a chart on a local Agent dashboard), to
245
+> visualize only that dimension. This can be particularly useful in process monitoring to separate one process'
246
+> utilization from the rest of the system.
247
+
248
+### Using Netdata's eBPF collector (`ebpf.plugin`)
249
+
250
+Netdata's eBPF collector puts its charts in two places. Of most imporance to process monitoring are the **ebpf file**,
251
+**ebpf syscall**, **ebpf process**, and **ebpf net** sub-sections under **Applications**, shown in the above screenshot.
252
+
253
+For example, running the above workload shows the entire "story" how MySQL interacts with the Linux kernel to open
254
+processes/threads to handle a large number of SQL queries, then subsequently close the tasks as each query returns the
255
+relevant data.
256
+
257
+
259
+
260
+`ebpf.plugin` visualizes additional eBPF metrics, which are system-wide and not per-process, under the **eBPF** section.
261
+
262
+## What's next?
263
+
264
+Now that you have `apps_groups.conf` configured correctly, and know where to find per-process visualizations throughout
265
+Netdata's ecosystem, you can precisely monitor the health and performance of any process on your node using per-second
266
+metrics.
267
+
268
+For even more in-depth troubleshooting, see our guide on [monitoring and debugging applications with
269
+eBPF](/docs/guides/troubleshoot/monitor-debug-applications-ebpf.md).
270
+
271
+If the process you're monitoring also has a [supported collector](/collectors/COLLECTORS.md), now is a great time to set
272
+that up if it wasn't autodetected. With both process utilization and application-specific metrics, you should have every
273
+piece of data needed to discover the root cause of an incident. See our [collector
274
+setup](/docs/collect/enable-configure.md) doc for details.
275
+
276
+[Create new dashboards](/docs/visualize/create-dashboards.md) in Netdata Cloud using charts from `apps.plugin`,
277
+`ebpf.plugin`, and application-specific collectors to build targeted dashboards for monitoring key procesess across your
278
+infrastructure.
279
+
280
+Try running [Metric Correlations](https://learn.netdata.cloud/docs/cloud/insights/metric-correlations) on a node that's
281
+running the process(es) you're monitoring. Even if nothing is going wrong at the moment, Netdata Cloud's embedded
282
+intelligence helps you better understand how a MySQL database, for example, might influence a system's volume of memory
283
+page faults. And when an incident is afoot, use Metric Correlations to reduce mean time to resolution (MTTR) and
284
+cognitive load.
285
+
286
+If you want more specific metrics from your custom application, check out Netdata's [statsd
287
+support](/collectors/statsd.plugin/README.md). With statd, you can send detailed metrics from your application to
288
+Netdata and visualize them with per-second granularity. Netdata's statsd collector works with dozens of [statsd server
289
+implementations](https://github.com/etsy/statsd/wiki#client-implementations), which work with most application
290
+frameworks.
291
+
292
+### Related reference documentation
293
+
294
+- [Netdata Agent · `apps.plugin`](/collectors/apps.plugin/README.md)
295
+- [Netdata Agent · `ebpf.plugin`](/collectors/ebpf.plugin/README.md)
296
+- [Netdata Agent · Dashboards](/web/README.md#dimensions)
297
+- [Netdata Agent · MySQL collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/mysql)
298
+
299
+[](<>)
docs/guides/troubleshoot/monitor-debug-applications-ebpf.md
+9
-11
@@ -113,9 +113,9 @@ Visit the Netdata dashboard at `http://NODE:19999`, replacing `NODE` with the ho
113
to monitor this application. Scroll down to the **Applications** section. These charts now feature a `firefox` dimension
114
with metrics specific to that process.
115
116
-Pay particular attention to the charts in the **ebpf syscall** and **ebpf net** sections. These charts are populated by
117
-low-level Linux kernel metrics thanks to eBPF, and showcase the volume of calls to open/close files, call functions like
118
-`do_fork`, IO activity on the VFS, and much more.
116
+Pay particular attention to the charts in the **ebpf file**, **ebpf syscall**, **ebpf process**, and **ebpf net**
117
+sub-sections. These charts are populated by low-level Linux kernel metrics thanks to eBPF, and showcase the volume of
118
+calls to open/close files, call functions like `do_fork`, IO activity on the VFS, and much more.
119
120
See the [eBPF collector documentation](/collectors/ebpf.plugin/README.md#integration-with-appsplugin) for the full list
121
of per-application charts.
@@ -237,15 +237,13 @@ If you don't already have a Netdata Cloud account, go [sign in](https://app.netd
237
Read the [get started with Cloud guide](https://learn.netdata.cloud/docs/cloud/get-started) for a walkthrough of node
238
claiming and other fundamentals.
239
240
-Add more charts to a War Room's Overview, or the Nodes view, by clicking on the gear icon at the far end of the table.
241
-Click on the **Context** input and scroll until you find the eBPF chart you're interested in, or type in the name of the
242
-context directly. Maybe something like `apps.vfs_write_call`? Next, click on the **Dimensions** input and find the `dev`
243
-dimension, or maybe `apache`/`redis` if you set your `apps_groups.conf` up like the examples above.
240
+Once you've added one or more nodes to a Space in Netdata Cloud, you can see aggregated eBPF metrics in the [Overview
241
+dashboard](/docs/visualize/overview-infrastructure.md) under the same **Applications** or **eBPF** sections that you
242
+find on the local Agent dashboard. Or, [create new dashboards](/docs/visualize/create-dashboards.md) using eBPF metrics
243
+from any number of distributed nodes to see how your application interacts with multiple Linux kernels on multiple Linux
244
+systems.
245
245
-Click **Save** to add the chart for all your claimed nodes. Now you can see how your application interacts with multiple
246
-Linux kernels on multiple Linux systems.
247
-
248
-Now that you can see these metrics in Netdata Cloud, you can [invite your
246
+Now that you can see eBPF metrics in Netdata Cloud, you can [invite your
247
team](https://learn.netdata.cloud/docs/cloud/manage/invite-your-team) and share your findings with others.
248
249
## What's next?
web/README.md
+3
-5
@@ -1,12 +1,10 @@
1
<!--
2
----
3
-title: "Web dashboards overview"
4
-date: 2020-03-11
2
+title: "Dashboards"
3
+description: "Netdata comes bundled with hundreds of real-time, context-aware charts that help your monitor health and performance without configuration."
4
custom_edit_url: https://github.com/netdata/netdata/edit/master/web/README.md
6
----
5
-->
6
9
-# Web dashboards overview
7
+# Dashboards
8
9
Because Netdata is a health monitoring and _performance troubleshooting_ system,
10
we put a lot of emphasis on real-time, meaningful, and context-aware charts.