refresh the ML documentation and consolidate the two docs (#17543)
* refresh the ML documentation and consolidate the two docs * ml conf doc * ml category overview page debloat * link to AA * update metrics correlation doc * Apply suggestions from code review Co-authored-by: Ilya Mashchenko <ilya@netdata.cloud> --------- Co-authored-by: Ilya Mashchenko <ilya@netdata.cloud>
Fotis Voutsas committed
Apr 30, 2024 at 10:04 UTC
310253994cffc689cd32bcd7666afd54f520be03
4 files changed
+192
-357
docs/category-overview-pages/machine-learning-and-assisted-troubleshooting.md
+4
-94
@@ -1,97 +1,7 @@
1
# Machine Learning and Anomaly Detection
2
3
-Machine learning (ML) is a subfield of Artificial Intelligence (AI) that enables computers to learn and improve from experience without being explicitly programmed.
3
+Netdata provides a variety of Machine Learning features to help you troubleshoot certain scenarios that might come up.
4
5
-In observability, machine learning can be used to detect patterns and anomalies in large datasets, enabling users to identify potential issues before they become critical.
6
-
7
-Machine Learning for observability is usually misunderstood, and frequently leads to unrealistic expectations. Check for example the [presentation Google gave at SreCON19](https://www.usenix.org/conference/srecon19emea/presentation/underwood) explaining that all ideas that Google SREs and DevOps came up with, about the use of Machine Learning in observability were bad, and as Todd notes they should feel bad about it.
8
-
9
-At Netdata we are approaching machine learning in a completely different way. Instead of trying to make machine learning do something it cannot achieve, we tried to understand if and what useful insights it can provide and eventually we turned it to an assistant that can improve troubleshooting, reduce mean time to resolution and in many case prevent issues from escalating.
10
-
11
-## Design Principles
12
-
13
-The following are the high level design principles of Machine Learning in Netdata:
14
-
15
-1. **Unsupervised**
16
-
17
- In other words: whatever machine learning can do, it should do it by itself, without any help or assistance from users.
18
-
19
-2. **Real-time**
20
-
21
- We understand that Machine Learning will have some impact on resource utilization, especially in CPU utilization, but it shouldn't prevent Netdata from being real-time and high-fidelity.
22
-
23
-3. **Integrated**
24
-
25
- Everything achieved with machine learning should be tightly integrated to the infrastructure exploration and troubleshooting practices we are used to.
26
-
27
-4. **Assist, Advice, Consult**
28
-
29
- If we can't be sure that a decision made by Machine Learning is 100% accurate, we should use this to assist and consult users in their journey.
30
-
31
- In other words, we don't want to wake up someone at 3 AM, just because a machine learning model detected something.
32
-
33
-## Machine Learning per Time-Series
34
-
35
-Given the samples recently collected for a time-series, Machine Learning is used to detect if a sample just collected is an outlier or not.
36
-
37
-Since the query combinations are infinite, Netdata detects anomalies at the time-series level, and then combines the anomaly rates of all time-series involved in each query, to provide the anomaly rate for the query.
38
-
39
-When a collected sample is an outlier, we set the Anomaly Bit of the collected sample and we store it together with the sample value in the time-series database.
40
-
41
-## Multiple Machine Learning Models per Time-Series to Eliminate Noise
42
-
43
-Unsupervised machine learning has some noise, random false positives.
44
-
45
-To remove this noise, Netdata trains multiple machine learning models for each time-series, covering more than the last 2 days, in total.
46
-
47
-Netdata uses all of the available ML models to detect anomalies. So, all machine learning models of a time-series need to agree that a collected sample is an outlier, for it to be marked as an anomaly.
48
-
49
-This process removes 99% of the false positives, offering reliable unsupervised anomaly detection.
50
-
51
-## Node Level Anomaly
52
-
53
-When a metric becomes anomalous, in many cases a lot other metrics get anomalous too.
54
-
55
-For example, an anomaly on a web server may also introduce unusual network bandwidth, cpu usage, memory consumption, disk I/O, context switches, interrupts, etc. If the web server is serving an API that has an application server and a database server we may see anomalies being propagated to them too.
56
-
57
-To represent the spread of an anomaly in a node, Netdata computes a **Node Level Anomaly**. This is the percentage of the metrics of a node being concurrently anomalous, vs the total number of metrics of that node.
58
-
59
-## Node Anomaly Events
60
-
61
-Netdata produces a "node anomaly event" when a the percentage of concurrently anomalous time-series is high enough and persists over time.
62
-
63
-This anomaly event signals that there was sufficient evidence among all the time-series that some strange behavior might have been detected in a more global sense across the node.
64
-
65
-## What is the Anomaly Bit?
66
-
67
-Each sample collected, carries an Anomaly Bit. This bit (true/false) is set when the collected sample found to be an outlier, based on the machine learning models available for it so far.
68
-
69
-This bit is embedded into the custom floating point number the Netdata database uses, so it does not introduce any overheads in memory or disk footprint.
70
-
71
-The query engine of Netdata uses this bit to compute anomaly rates while it executes normal time-series queries. This eliminates to need for additional queries for anomaly rates, as all `/api/v2` time-series query include anomaly rate information.
72
-
73
-## What is the Anomaly Rate (AR)?
74
-
75
-The Anomaly Rate of a query, is a percentage, representing the number of samples in the query found anomalous, vs the total number of samples participating in the query.
76
-
77
-## How it works - a more technical presentation
78
-
79
-For each time-series Netdata trains every 3 hours, a `k-means clustering` model, using the last 6 hours of samples collected for it.
80
-
81
-Rather than using raw samples of each time-series, the model works on a preprocessed "feature vector" of recent smoothed and differenced values.
82
-
83
-This enables the model to detect a wider range of potentially anomalous patterns as opposed to just point anomalies like big spikes or drops.
84
-
85
-Some of the types of anomalies Netdata detects are:
86
-
87
-1. **Point Anomalies** or **Strange Points**: Single points that represent very big or very small values, not seen before (in some statistical sense).
88
-2. **Contextual Anomalies** or **Strange Patterns**: Not strange points in their own, but unexpected sequences of points, given the history of the time-series.
89
-3. **Collective Anomalies** or **Strange Multivariate Patterns**: Neither strange points nor strange patterns, but in global sense something looks off.
90
-4. **Concept Drifts** or **Strange Trends**: A slow and steady drift to a new state.
91
-5. **Change Point Detection** or **Strange Step**: A shift occurred and gradually a new normal is established.
92
-
93
-For a visual representation, check this infographic:
94
-
95
-
96
-
97
-A more detailed explanation can be found on [this (informal) presentation](https://docs.google.com/presentation/d/18zkCvU3nKP-Bw_nQZuXTEa4PIVM6wppH3VUnAauq-RU/edit#slide=id.p).
5
+- K-means clustering [Machine Learning models](https://github.com/netdata/netdata/blob/master/src/ml/README.md) are trained to power the [Anomaly Advisor](https://github.com/netdata/netdata/blob/master/docs/dashboard/anomaly-advisor-tab.md) on the dashboard, which allows you to identify anomalies in your infrastructure
6
+- [Metric Correlations](https://github.com/netdata/netdata/blob/master/docs/cloud/insights/metric-correlations.md) are possible through the dashboard using the [Two-sample Kolmogorov Smirnov](https://en.wikipedia.org/wiki/Kolmogorov%E2%80%93Smirnov_test#Two-sample_Kolmogorov%E2%80%93Smirnov_test) statistical test and Volume heuristic measures
7
+- The [Netdata Assistant](https://github.com/netdata/netdata/blob/master/docs/cloud/netdata-assistant.md) is able to answer your prompts when it comes to troubleshooting alerts and anomalies.
docs/cloud/insights/metric-correlations.md
+11
-33
@@ -1,36 +1,22 @@
1
-<!--
2
-title: "Metric Correlations"
3
-description: "Quickly find metrics and charts closely related to a particular timeframe of interest anywhere in your infrastructure to discover the root cause faster."
4
-custom_edit_url: "https://github.com/netdata/netdata/blob/master/docs/cloud/insights/metric-correlations.md"
5
-sidebar_label: "Metric Correlations"
6
-learn_status: "Published"
7
-learn_topic_type: "Tasks"
8
-learn_rel_path: "Operations"
9
--->
10
-
1
# Metric Correlations
2
13
-The Metric Correlations (MC) feature lets you quickly find metrics and charts related to a particular window of interest that you want to explore further. By displaying the standard Netdata dashboard, filtered to show only charts that are relevant to the window of interest, you can get to the root cause sooner.
3
+The Metric Correlations feature lets you quickly find metrics and charts related to a particular window of interest that you want to explore further.
4
+
5
+By displaying the standard Netdata dashboard, filtered to show only charts that are relevant to the window of interest, you can get to the root cause sooner.
6
7
Because Metric Correlations uses every available metric from your infrastructure, with as high as 1-second granularity, you get the most accurate insights using every possible metric.
8
9
## Using Metric Correlations
10
19
-When viewing the overview or a single-node dashboard, the **Metric Correlations** button appears in the top right corner of the page.
20
-
21
-
11
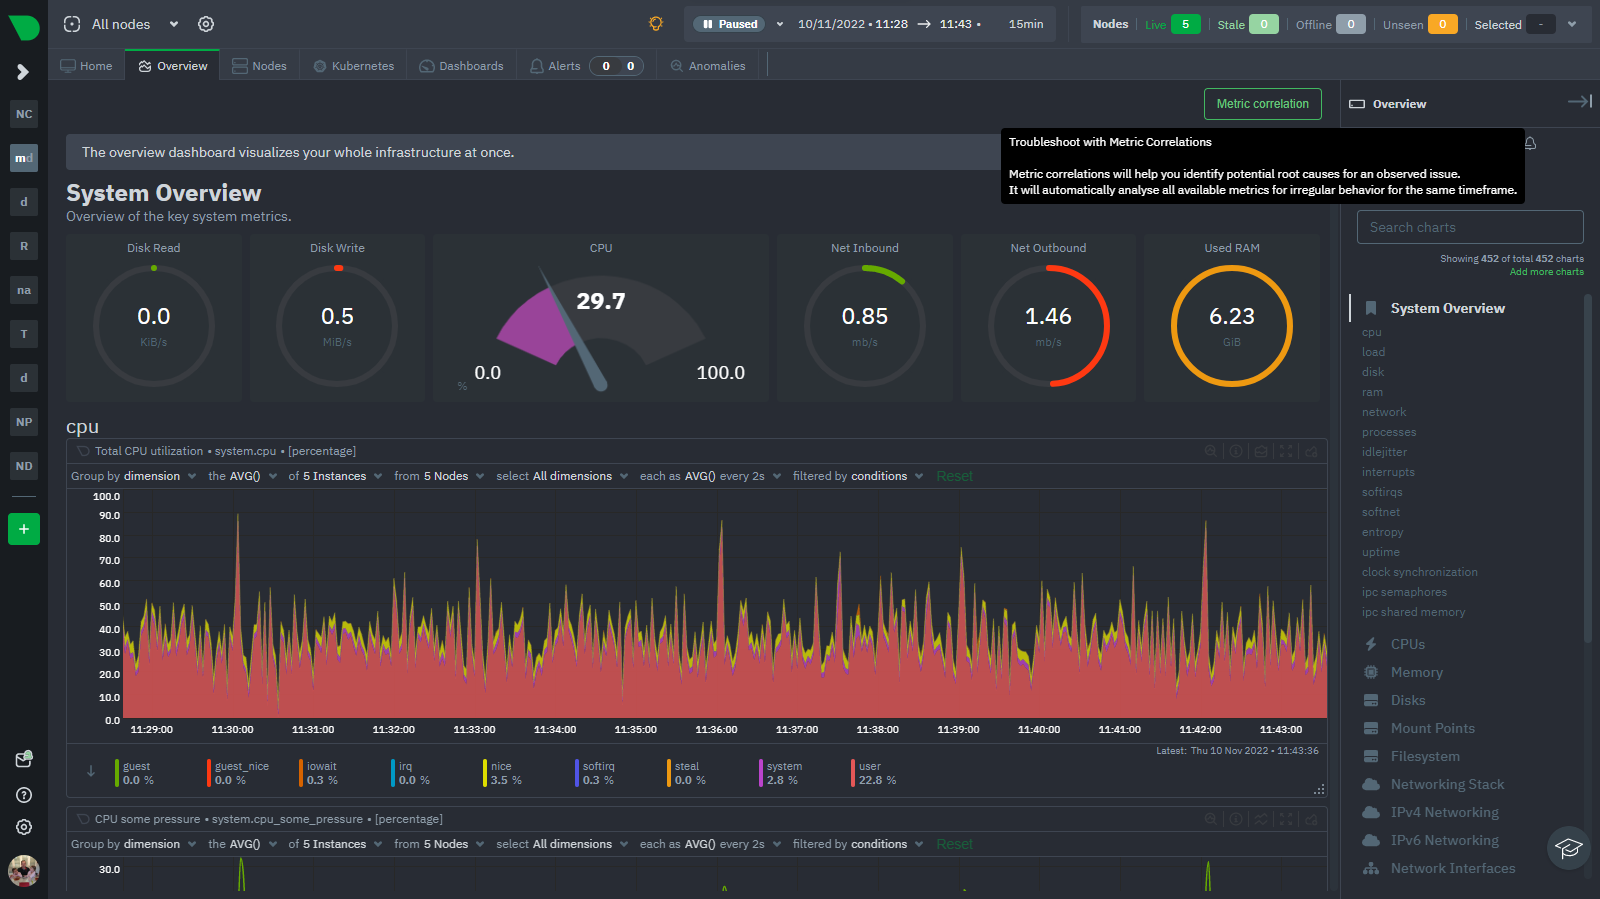
+When viewing the [Metrics tab or a single-node dashboard](https://github.com/netdata/netdata/blob/master/docs/dashboard/metrics-tab-and-single-node-tabs.md), the **Metric Correlations** button appears in the top right corner of the page.
12
23
-To start correlating metrics, click the **Metric Correlations** button, then hold the `Alt` key (or `⌘` on macOS) and click-and-drag a selection of metrics on a single chart. The selected timeframe needs to be at least 15 seconds for Metric Correlation to work.
13
+To start correlating metrics, click the **Metric Correlations** button, hold the `Alt` key (or `⌘` on macOS), and drag a selection of metrics on a single chart. The selected timeframe needs at least 15 seconds for Metric Correlation to work.
14
15
The menu then displays information about the selected area and reference baseline. Metric Correlations uses the reference baseline to discover which additional metrics are most closely connected to the selected metrics. The reference baseline is based upon the period immediately preceding the highlighted window and is the length of 4 times the highlighted window. This is to ensure that the reference baseline is always immediately before the highlighted window of interest and a bit longer so as to ensure it's a more representative short term baseline.
16
27
-Press the **Find Correlations** button to start up the correlations process, the button is only enabled when a valid timeframe is selected (at least 15 seconds). Once pressed, the process will score all available metrics on your nodes and return a filtered version of the Netdata dashboard. Now, you'll see only those metrics that have changed the most between a baseline window and the highlighted window you have selected.
28
-
29
-
30
-
31
-These charts are fully interactive, and whenever possible, will only show the _dimensions_ related to the timeline you selected.
17
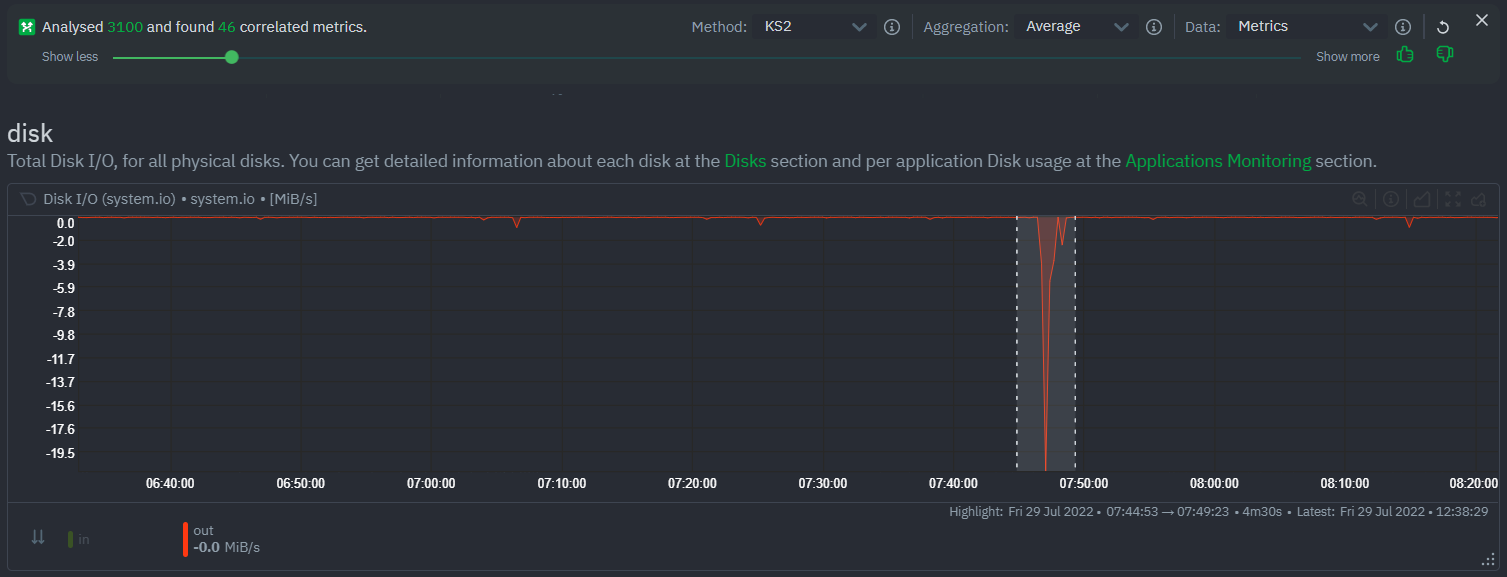
+Click the **Find Correlations** button to begin the correlation process. This button is only active if a valid timeframe is selected. Once clicked, the process will evaluate all available metrics on your nodes and return a filtered version of the Netdata dashboard. You will now only see the metrics that changed the most between the base window and the highlighted window you selected..
18
33
-You can interact with all the scored metrics via the slider. Slide toward **show less** for more nuanced and significant results, or toward **show more** to "loosen" the threshold to explore other charts that may have changed too, but in a less significant manner.
19
+These charts are fully interactive, and whenever possible, will only show the **dimensions** related to the timeline you selected.
20
21
If you find something else interesting in the results, you can select another window and press **Find Correlations** again to kick the process off again.
22
@@ -53,29 +39,21 @@ Behind the scenes, Netdata will aggregate the raw data as needed such that arbit
39
40
### Data
41
56
-Netdata is different from typical observability agents since, in addition to just collecting raw metric values, it will by default also assign an "[Anomaly Bit](https://github.com/netdata/netdata/tree/master/src/ml#anomaly-bit---100--anomalous-0--normal)" related to each collected metric each second. This bit will be 0 for "normal" and 1 for "anomalous". This means that each metric also natively has an "[Anomaly Rate](https://github.com/netdata/netdata/tree/master/src/ml#anomaly-rate---averageanomaly-bit)" associated with it and, as such, MC can be run against the raw metric values or their corresponding anomaly rates.
42
+Unlike other observability agents that only collect raw metrics, Netdata also assigns an [Anomaly Bit](https://github.com/netdata/netdata/tree/master/src/ml#anomaly-bit) in real-time. This bit flags whether a metric is within normal ranges (0) or deviates significantly (1). This built-in anomaly detection allows for the analysis of both the raw data and the anomaly rates.
43
44
**Note**: Read more [here](https://github.com/netdata/netdata/blob/master/src/ml/README.md) to learn more about the native anomaly detection features within netdata.
45
46
- `Metrics` - Run MC on the raw metric values.
47
- `Anomaly Rate` - Run MC on the corresponding anomaly rate for each metric.
48
63
-## Metric Correlations on the agent
64
-
65
-As of `v1.35.0` Netdata is able to run the Metric Correlations algorithm ([Two Sample Kolmogorov-Smirnov test](https://en.wikipedia.org/wiki/Kolmogorov%E2%80%93Smirnov_test#Two-sample_Kolmogorov%E2%80%93Smirnov_test)) on the agent itself. This avoids sending the underlying raw data to the original Netdata Cloud based microservice and so typically will be much much faster as no data moves around and the computation happens instead on the agent.
49
+## Metric Correlations on the Agent
50
51
When a Metric Correlations request is made to Netdata Cloud, if any node instances have MC enabled then the request will be routed to the node instance with the highest hops (e.g. a parent node if one is found or the node itself if not). If no node instances have MC enabled then the request will be routed to the original Netdata Cloud based service which will request input data from the nodes and run the computation within the Netdata Cloud backend.
52
69
-#### Enabling/Disabling Metric Correlations on the agent
70
-
71
-As of `v1.35.0-22-nightly` Metric Correlation has been enabled by default on all agents. After further optimizations to the implementation, the impact of running the metric correlations algorithm on the agent was less than the impact of preparing all the data to send to cloud for MC to run in the cloud, as such running MC on the agent is less impactful on local resources than running via cloud.
72
-
73
-Should you still want to, disabling nodes for Metric Correlation on the agent is a simple one line config change. Just set `enable metric correlations = no` in the `[global]` section of `netdata.conf`
74
-
75
-## Usage tips!
53
+## Usage tips
54
55
- When running Metric Correlations from the [Metrics tab](docs/dashboard/metrics-tab-and-single-node-tabs.md) across multiple nodes, you might find better results if you iterate on the initial results by grouping by node to then filter to nodes of interest and rerun the Metric Correlations. So a typical workflow in this case would be to:
78
- - If unsure which nodes you are interested in then run MC on all nodes.
56
+ - If unsure which nodes you are interested in then run MC on all nodes.
57
- Within the initial results returned group the most interesting chart by node to see if the changes are across all nodes or a subset of nodes.
58
- If you see a subset of nodes clearly jump out when you group by node, then filter for just those nodes of interest and run the MC again. This will result in less aggregation needing to be done by Netdata and so should help give clearer results as you interact with the slider.
59
- Use the `Volume` algorithm for metrics with a lot of gaps (e.g. request latency when there are few requests), otherwise stick with `KS2`
src/ml/README.md
+72
-230
@@ -1,279 +1,121 @@
1
-<!--
2
-title: "Configure machine learning (ML) powered anomaly detection"
3
-custom_edit_url: "https://github.com/netdata/netdata/edit/master/src/ml/README.md"
4
-description: "This is an in-depth look at how Netdata uses ML to detect anomalies."
5
-sidebar_label: "Configure machine learning (ML) powered anomaly detection"
6
-learn_status: "Published"
7
-learn_topic_type: "Tasks"
8
-learn_rel_path: "Configuration"
9
--->
1
+# ML models and anomaly detection
2
11
-# Machine learning (ML) powered anomaly detection
3
+In observability, machine learning can be used to detect patterns and anomalies in large datasets, enabling users to identify potential issues before they become critical.
4
13
-## Overview
5
+At Netdata through understanding what useful insights ML can provide, we created a tool that can improve troubleshooting, reduce mean time to resolution and in many cases prevent issues from escalating. That tool is called the [Anomaly Advisor](https://github.com/netdata/netdata/blob/master/docs/dashboard/anomaly-advisor-tab.md), available at our [Netdata dashboard](https://github.com/netdata/netdata/blob/master/docs/category-overview-pages/accessing-netdata-dashboards.md).
6
15
-Machine learning is a subfield of artificial intelligence that enables computers to learn and improve from experience without being explicitly programmed. In monitoring, machine learning can be used to detect patterns and anomalies in large datasets, enabling users to identify potential issues before they become critical. The importance of machine learning in monitoring lies in its ability to analyze vast amounts of data in real-time and provide actionable insights that can help optimize system performance and prevent downtime. Machine learning can also improve the efficiency and scalability of monitoring systems, enabling organizations to monitor complex infrastructures and applications with ease.
7
+> **Note**
8
+>
9
+> If you want to learn how to configure ML on your nodes, check the [ML configuration documentation](https://github.com/netdata/netdata/blob/master/src/ml/ml-configuration.md).
10
17
-The primary goal of implementing machine learning features in Netdata is to enable users to detect and alert on anomalies in their systems with advanced anomaly detection capabilities. Netdata's machine learning features are designed to be highly customizable and scalable, so users can tailor the ML models and training process to their specific requirements and monitor systems of any size or complexity.
11
+## Design principles
12
19
-As of [`v1.32.0`](https://github.com/netdata/netdata/releases/tag/v1.32.0), Netdata comes with ML powered [anomaly detection](https://en.wikipedia.org/wiki/Anomaly_detection) capabilities built into it and available to use out of the box, with zero configuration required (ML was enabled by default in `v1.35.0-29-nightly` in [this PR](https://github.com/netdata/netdata/pull/13158), previously it required a one line config change).
13
+The following are the high level design principles of Machine Learning in Netdata:
14
21
-🚧 **Note**: If you would like to get involved and help us with some feedback, email us at analytics-ml-team@netdata.cloud, comment on the [beta launch post](https://community.netdata.cloud/t/anomaly-advisor-beta-launch/2717) in the Netdata community, or come join us in the [🤖-ml-powered-monitoring](https://discord.gg/4eRSEUpJnc) channel of the Netdata discord.
15
+1. **Unsupervised**
16
23
-Once ML is enabled, Netdata will begin training a model for each dimension. By default this model is a [k-means clustering](https://en.wikipedia.org/wiki/K-means_clustering) model trained on the most recent 4 hours of data. Rather than just using the most recent value of each raw metric, the model works on a preprocessed ["feature vector"](#feature-vector) of recent smoothed and differenced values. This enables the model to detect a wider range of potentially anomalous patterns in recent observations as opposed to just point anomalies like big spikes or drops. ([This infographic](https://user-images.githubusercontent.com/2178292/144414415-275a3477-5b47-43d6-8959-509eb48ebb20.png) shows some different types of anomalies).
17
+ Whatever the ML models can do, they should do it by themselves, without any help or assistance from users.
18
25
-The sections below will introduce some of the main concepts:
26
-- anomaly bit
27
-- anomaly score
28
-- anomaly rate
29
-- anomaly detector
19
+2. **Real-time**
20
31
-Additional explanations and details can be found in the [Glossary](#glossary) and [Notes](#notes) at the bottom of the page.
21
+ We understand that Machine Learning will have some impact on resource utilization, especially in CPU utilization, but it shouldn't prevent Netdata from being real-time and high-fidelity.
22
33
-### Anomaly Bit - (100 = Anomalous, 0 = Normal)
23
+3. **Integrated**
24
35
-Once each model is trained, Netdata will begin producing an ["anomaly score"](#anomaly-score) at each time step for each dimension. This ["anomaly score"](#anomaly-score) is essentially a distance measure to the trained cluster centers of the model (by default each model has k=2, so two cluster centers are learned). More anomalous looking data should be more distant to those cluster centers. If this ["anomaly score"](#anomaly-score) is sufficiently large, this is a sign that the recent raw values of the dimension could potentially be anomalous. By default, "sufficiently large" means that the distance is in the 99th percentile or above of all distances observed during training or, put another way, it has to be further away than the furthest 1% of the data used during training. Once this threshold is passed, the ["anomaly bit"](#anomaly-bit) corresponding to that dimension is set to 100 to flag it as anomalous, otherwise it would be left at 0 to signal normal data.
25
+ Everything achieved with Machine Learning should be tightly integrated to the infrastructure exploration and troubleshooting practices we are used to.
26
37
-What this means is that in addition to the raw value of each metric, Netdata now also stores an ["anomaly bit"](#anomaly-bit) that is either 100 (anomalous) or 0 (normal). Importantly, this is achieved without additional storage overhead due to how the anomaly bit has been implemented within the existing internal Netdata storage representation.
27
+4. **Assist, Advice, Consult**
28
39
-This ["anomaly bit"](#anomaly-bit) is exposed via the `anomaly-bit` key that can be passed to the `options` param of the `/api/v1/data` REST API.
29
+ If we can't be sure that a decision made by Machine Learning is 100% accurate, we should use this to assist and consult users in their journey.
30
41
-For example, here are some recent raw dimension values for `system.ip` on our [london](http://london.my-netdata.io/) demo server:
31
+ In other words, we don't want to wake up someone at 3 AM, just because a model detected something.
32
43
-[`https://london.my-netdata.io/api/v1/data?chart=system.ip`](https://london.my-netdata.io/api/v1/data?chart=system.ip)
33
+Some of the types of anomalies Netdata detects are:
34
45
-```
46
-{
47
- "labels": ["time", "received", "sent"],
48
- "data":
49
- [
50
- [ 1638365672, 54.84098, -76.70201],
51
- [ 1638365671, 124.4328, -309.7543],
52
- [ 1638365670, 123.73152, -167.9056],
53
- ...
54
- ]
55
-}
56
-```
35
+1. **Point Anomalies** or **Strange Points**: Single points that represent very big or very small values, not seen before (in some statistical sense).
36
+2. **Contextual Anomalies** or **Strange Patterns**: Not strange points in their own, but unexpected sequences of points, given the history of the time-series.
37
+3. **Collective Anomalies** or **Strange Multivariate Patterns**: Neither strange points nor strange patterns, but in global sense something looks off.
38
+4. **Concept Drifts** or **Strange Trends**: A slow and steady drift to a new state.
39
+5. **Change Point Detection** or **Strange Step**: A shift occurred and gradually a new normal is established.
40
58
-And if we add the `&options=anomaly-bit` params, we can see the "anomaly bit" value corresponding to each raw dimension value:
41
+### Models
42
60
-[`https://london.my-netdata.io/api/v1/data?chart=system.ip&options=anomaly-bit`](https://london.my-netdata.io/api/v1/data?chart=system.ip&options=anomaly-bit)
43
+Once ML is enabled, Netdata will begin training a model for each dimension. By default this model is a [k-means clustering](https://en.wikipedia.org/wiki/K-means_clustering) model trained on the most recent 4 hours of data.
44
62
-```
63
-{
64
- "labels": ["time", "received", "sent"],
65
- "data":
66
- [
67
- [ 1638365672, 0, 0],
68
- [ 1638365671, 0, 0],
69
- [ 1638365670, 0, 0],
70
- ...
71
- ]
72
-}
73
-```
74
-In this example, the dimensions "received" and "sent" didn't show any abnormal behavior, so the anomaly bit is zero.
75
-Under normal circumstances, the anomaly bit will mostly be 0. However, there can be random fluctuations setting the anomaly to 100, although this very much depends on the nature of the dimension in question.
45
+Rather than just using the most recent value of each raw metric, the model works on a preprocessed [feature vector](https://en.wikipedia.org/wiki/Feature_(machine_learning)#:~:text=edges%20and%20objects.-,Feature%20vectors,-%5Bedit%5D) of recent smoothed values.
46
77
-### Anomaly Rate - average(anomaly bit)
47
+This enables the model to detect a wider range of potentially anomalous patterns in recent observations as opposed to just point-anomalies like big spikes or drops.
48
79
-Once all models have been trained, we can think of the Netdata dashboard as essentially a big matrix or table of 0's and 100's. If we consider this "anomaly bit"-based representation of the state of the node, we can now think about how we might detect overall node level anomalies. The figure below illustrates the main ideas.
49
+Unsupervised models have some noise, random false positives. To remove this noise, Netdata trains multiple machine learning models for each time-series, covering more than the last 2 days in total.
50
81
-```
82
- dimensions
83
-time d1 d2 d3 d4 d5 NAR
84
- 1 0 0 0 0 0 0%
85
- 2 0 0 0 0 100 20%
86
- 3 0 0 0 0 0 0%
87
- 4 0 100 0 0 0 20%
88
- 5 100 0 0 0 0 20%
89
- 6 0 100 100 0 100 60%
90
- 7 0 100 0 100 0 40%
91
- 8 0 0 0 0 100 20%
92
- 9 0 0 100 100 0 40%
93
- 10 0 0 0 0 0 0%
94
-
95
-DAR 10% 30% 20% 20% 30% 22% NAR_t1-t10
51
+Netdata uses all of its available ML models to detect anomalies. So, all machine learning models of a time-series need to agree that a collected sample is an outlier, for it to be marked as an anomaly.
52
97
-DAR = Dimension Anomaly Rate
98
-NAR = Node Anomaly Rate
99
-NAR_t1-t10 = Node Anomaly Rate over t1 to t10
100
-```
53
+This process removes 99% of the false positives, offering reliable unsupervised anomaly detection.
54
102
-To work out an ["anomaly rate"](#anomaly-rate), we can just average a row or a column in any direction. For example, if we were to just average along a row then this would be the ["node anomaly rate"](#node-anomaly-rate) (all dimensions) at time t. Likewise if we averaged a column then we would have the ["dimension anomaly rate"](#dimension-anomaly-rate) for each dimension over the time window t=1-10. Extending this idea, we can work out an overall ["anomaly rate"](#anomaly-rate) for the whole matrix or any subset of it we might be interested in.
55
+The sections below will introduce you to the main concepts.
56
104
-### Anomaly Detector - Node level anomaly events
57
+### Anomaly Bit
58
106
-An ["anomaly detector"](#anomaly-detector) looks at all anomaly bits of a node. Netdata's anomaly detector produces an ["anomaly event"](#anomaly-event) when a the percentage of anomaly bits is high enough for a persistent amount of time. This anomaly event signals that there was sufficient evidence among all the anomaly bits that some strange behavior might have been detected in a more global sense across the node.
59
+Once each model is trained, Netdata will begin producing an **anomaly score** at each time step for each dimension. It **represents a distance measure** to the centers of the model's trained clusters (by default each model has k=2, so two clusters exist for every model).
60
108
-Essentially if the ["Node Anomaly Rate"](#node-anomaly-rate) (NAR) passes a defined threshold and stays above that threshold for a persistent amount of time, a "Node [Anomaly Event](#anomaly-event)" will be triggered.
61
+Anomalous data should have bigger distance from the cluster centers than points of data that are considered normal. If the anomaly score is sufficiently large, it is a sign that the recent raw values of the dimension could potentially be anomalous.
62
110
-These anomaly events are currently exposed via the `new_anomaly_event` dimension on the `anomaly_detection.anomaly_detection` chart.
111
-
112
-## Configuration
113
-
114
-If you are running a netdata version after `v1.35.0-29-nightly` then ML will be enabled by default.
115
-
116
-To enable or disable anomaly detection:
117
-1. Find and open the Netdata configuration file `netdata.conf`.
118
-2. In the `[ml]` section, set `enabled = yes` to enable or `enabled = no` to disable.
119
-3. Restart netdata (typically `sudo systemctl restart netdata`).
120
-
121
-> 📑 Note
122
->
123
-> If you would like to learn more about configuring Netdata please see the [Configuration section](https://github.com/netdata/netdata/blob/master/docs/configure/nodes.md) of our documentation.
124
-
125
-Below is a list of all the available configuration params and their default values.
126
-
127
-```
128
-[ml]
129
- # enabled = yes
130
- # maximum num samples to train = 21600
131
- # minimum num samples to train = 900
132
- # train every = 10800
133
- # number of models per dimension = 18
134
- # dbengine anomaly rate every = 30
135
- # num samples to diff = 1
136
- # num samples to smooth = 3
137
- # num samples to lag = 5
138
- # random sampling ratio = 0.2
139
- # maximum number of k-means iterations = 1000
140
- # dimension anomaly score threshold = 0.99
141
- # host anomaly rate threshold = 1.0
142
- # anomaly detection grouping method = average
143
- # anomaly detection grouping duration = 300
144
- # hosts to skip from training = !*
145
- # charts to skip from training = netdata.*
146
- # dimension anomaly rate suppression window = 900
147
- # dimension anomaly rate suppression threshold = 450
148
- # delete models older than = 604800
149
-```
150
-
151
-### Configuration Examples
152
-
153
-If you would like to run ML on a parent instead of at the edge, some configuration options are illustrated below.
154
-
155
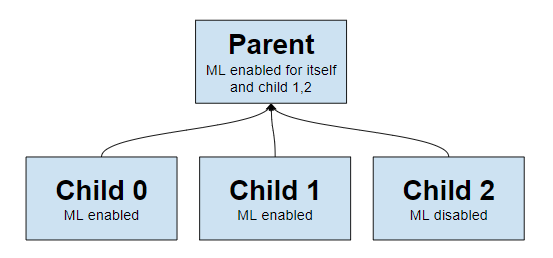
-This example assumes 3 child nodes [streaming](https://github.com/netdata/netdata/blob/master/src/streaming/README.md) to 1 parent node and illustrates the main ways you might want to configure running ML for the children on the parent, running ML on the children themselves, or even a mix of approaches.
156
-
157
-
158
-
159
-```
160
-# parent will run ML for itself and child 1,2, it will skip running ML for child 0.
161
-# child 0 will run its own ML at the edge.
162
-# child 1 will run its own ML at the edge, even though parent will also run ML for it, a bit wasteful potentially to run ML in both places but is possible (Netdata Cloud will essentially average any overlapping models).
163
-# child 2 will not run ML at the edge, it will be run in the parent only.
164
-
165
-# parent-ml-enabled
166
-# run ML on all hosts apart from child-ml-enabled
167
-[ml]
168
- enabled = yes
169
- hosts to skip from training = child-0-ml-enabled
170
-
171
-# child-0-ml-enabled
172
-# run ML on child-0-ml-enabled
173
-[ml]
174
- enabled = yes
175
-
176
-# child-1-ml-enabled
177
-# run ML on child-1-ml-enabled
178
-[ml]
179
- enabled = yes
180
-
181
-# child-2-ml-disabled
182
-# do not run ML on child-2-ml-disabled
183
-[ml]
184
- enabled = no
185
-```
186
-
187
-### Descriptions (min/max)
188
-
189
-- `enabled`: `yes` to enable, `no` to disable.
190
-- `maximum num samples to train`: (`3600`/`86400`) This is the maximum amount of time you would like to train each model on. For example, the default of `21600` trains on the preceding 6 hours of data, assuming an `update every` of 1 second.
191
-- `minimum num samples to train`: (`900`/`21600`) This is the minimum amount of data required to be able to train a model. For example, the default of `900` implies that once at least 15 minutes of data is available for training, a model is trained, otherwise it is skipped and checked again at the next training run.
192
-- `train every`: (`1800`/`21600`) This is how often each model will be retrained. For example, the default of `10800` means that each model is retrained every 3 hours. Note: The training of all models is spread out across the `train every` period for efficiency, so in reality, it means that each model will be trained in a staggered manner within each `train every` period.
193
-- `number of models per dimension`: (`1`/`168`) This is the number of trained models that will be used for scoring. For example the default `number of models per dimension = 18` means that the most recently trained 18 models for the dimension will be used to determine the corresponding anomaly bit. This means that under default settings of `maximum num samples to train = 21600`, `train every = 10800` and `number of models per dimension = 18`, netdata will store and use the last 18 trained models for each dimension when determining the anomaly bit. This means that for the latest feature vector in this configuration to be considered anomalous it would need to look anomalous across _all_ the models trained for that dimension in the last 18*(10800/3600) ~= 54 hours. As such, increasing `number of models per dimension` may reduce some false positives since it will result in more models (covering a wider time frame of training) being used during scoring.
194
-- `dbengine anomaly rate every`: (`30`/`900`) This is how often netdata will aggregate all the anomaly bits into a single chart (`anomaly_detection.anomaly_rates`). The aggregation into a single chart allows enabling anomaly rate ranking over _all_ metrics with one API call as opposed to a call per chart.
195
-- `num samples to diff`: (`0`/`1`) This is a `0` or `1` to determine if you want the model to operate on differences of the raw data or just the raw data. For example, the default of `1` means that we take differences of the raw values. Using differences is more general and works on dimensions that might naturally tend to have some trends or cycles in them that is normal behavior to which we don't want to be too sensitive.
196
-- `num samples to smooth`: (`0`/`5`) This is a small integer that controls the amount of smoothing applied as part of the feature processing used by the model. For example, the default of `3` means that the rolling average of the last 3 values is used. Smoothing like this helps the model be a little more robust to spiky types of dimensions that naturally "jump" up or down as part of their normal behavior.
197
-- `num samples to lag`: (`0`/`5`) This is a small integer that determines how many lagged values of the dimension to include in the feature vector. For example, the default of `5` means that in addition to the most recent (by default, differenced and smoothed) value of the dimension, the feature vector will also include the 5 previous values too. Using lagged values in our feature representation allows the model to work over strange patterns over recent values of a dimension as opposed to just focusing on if the most recent value itself is big or small enough to be anomalous.
198
-- `random sampling ratio`: (`0.2`/`1.0`) This parameter determines how much of the available training data is randomly sampled when training a model. The default of `0.2` means that Netdata will train on a random 20% of training data. This parameter influences cost efficiency. At `0.2` the model is still reasonably trained while minimizing system overhead costs caused by the training.
199
-- `maximum number of k-means iterations`: This is a parameter that can be passed to the model to limit the number of iterations in training the k-means model. Vast majority of cases can ignore and leave as default.
200
-- `dimension anomaly score threshold`: (`0.01`/`5.00`) This is the threshold at which an individual dimension at a specific timestep is considered anomalous or not. For example, the default of `0.99` means that a dimension with an anomaly score of 99% or higher is flagged as anomalous. This is a normalized probability based on the training data, so the default of 99% means that anything that is as strange (based on distance measure) or more strange as the most strange 1% of data observed during training will be flagged as anomalous. If you wanted to make the anomaly detection on individual dimensions more sensitive you could try a value like `0.90` (90%) or to make it less sensitive you could try `1.5` (150%).
201
-- `host anomaly rate threshold`: (`0.1`/`10.0`) This is the percentage of dimensions (based on all those enabled for anomaly detection) that need to be considered anomalous at specific timestep for the host itself to be considered anomalous. For example, the default value of `1.0` means that if more than 1% of dimensions are anomalous at the same time then the host itself is considered in an anomalous state.
202
-- `anomaly detection grouping method`: The grouping method used when calculating node level anomaly rate.
203
-- `anomaly detection grouping duration`: (`60`/`900`) The duration across which to calculate the node level anomaly rate, the default of `900` means that the node level anomaly rate is calculated across a rolling 5 minute window.
204
-- `hosts to skip from training`: This parameter allows you to turn off anomaly detection for any child hosts on a parent host by defining those you would like to skip from training here. For example, a value like `dev-*` skips all hosts on a parent that begin with the "dev-" prefix. The default value of `!*` means "don't skip any".
205
-- `charts to skip from training`: This parameter allows you to exclude certain charts from anomaly detection. By default, only netdata related charts are excluded. This is to avoid the scenario where accessing the netdata dashboard could itself trigger some anomalies if you don't access them regularly. If you want to include charts that are excluded by default, add them in small groups and then measure any impact on performance before adding additional ones. Example: If you want to include system, apps, and user charts:`!system.* !apps.* !user.* *`.
206
-- `delete models older than`: (`86400`/`604800`) Delete old models from the database that are unused, by default models will be deleted after 7 days.
207
-
208
-## Charts
209
-
210
-Once enabled, the "Anomaly Detection" menu and charts will be available on the dashboard.
211
-
212
-
213
-
214
-In terms of anomaly detection, the most interesting charts would be the `anomaly_detection.dimensions` and `anomaly_detection.anomaly_rate` ones, which hold the `anomalous` and `anomaly_rate` dimensions that show the overall number of dimensions considered anomalous at any time and the corresponding anomaly rate.
215
-
216
-- `anomaly_detection.dimensions`: Total count of dimensions considered anomalous or normal.
217
-- `anomaly_detection.anomaly_rate`: Percentage of anomalous dimensions.
218
-- `anomaly_detection.anomaly_detection`: Flags (0 or 1) to show when an anomaly event has been triggered by the detector.
63
+By default, the threshold is that the anomalous data's distance from the center of the cluster should be greater than the 99th percentile distance of the data used in training.
64
220
-Below is an example of how these charts may look in the presence of an anomaly event.
65
+Once this threshold is passed, the anomaly bit corresponding to that dimension is set to `true` to flag it as anomalous, otherwise it would be left as `false` to signal normal data.
66
222
-Initially we see a jump in `anomalous` dimensions:
67
+#### How the anomaly bit is used
68
224
-
69
+In addition to the raw value of each metric, Netdata also stores the anomaly bit **that is either 100 (anomalous) or 0 (normal)**.
70
226
-And a corresponding jump in the `anomaly_rate`:
71
+More importantly, this is achieved without additional storage overhead as this bit is embedded into the custom floating point number the Netdata database uses, so it does not introduce any overheads in memory or disk footprint.
72
228
-
73
+The query engine of Netdata uses this bit to compute anomaly rates while it executes normal time-series queries. This eliminates to need for additional queries for anomaly rates, as all `/api/v2` time-series query include anomaly rate information.
74
230
-After a short while the rolling node anomaly rate goes `above_threshold`, and once it stays above threshold for long enough a `new_anomaly_event` is created:
75
+### Anomaly Rate
76
232
-
77
+Once all models have been trained, we can think of the Netdata dashboard as a big matrix/table of 0 and 100 values. If we consider this anomaly bit based representation of the state of the node, we can now detect overall node level anomalies.
78
234
-## Glossary
79
+This figure illustrates the main idea (the x axis represents dimensions and the y axis time):
80
236
-#### _feature vector_
81
+| | d1 | d2 | d3 | d4 | d5 | **NAR** |
82
+|---------|---------|---------|---------|---------|---------|-----------------------|
83
+| t1 | 0 | 0 | 0 | 0 | 0 | **0%** |
84
+| t2 | 0 | 0 | 0 | 0 | 100 | **20%** |
85
+| t3 | 0 | 0 | 0 | 0 | 0 | **0%** |
86
+| t4 | 0 | 100 | 0 | 0 | 0 | **20%** |
87
+| t5 | 100 | 0 | 0 | 0 | 0 | **20%** |
88
+| t6 | 0 | 100 | 100 | 0 | 100 | **60%** |
89
+| t7 | 0 | 100 | 0 | 100 | 0 | **40%** |
90
+| t8 | 0 | 0 | 0 | 0 | 100 | **20%** |
91
+| t9 | 0 | 0 | 100 | 100 | 0 | **40%** |
92
+| t10 | 0 | 0 | 0 | 0 | 0 | **0%** |
93
+| **DAR** | **10%** | **30%** | **20%** | **20%** | **30%** | **_NAR_t1-10 = 22%_** |
94
238
-A [feature vector](https://en.wikipedia.org/wiki/Feature_(machine_learning)) is what the ML model is trained on and uses for prediction. The most simple feature vector would be just the latest raw dimension value itself [x]. By default Netdata will use a feature vector consisting of the 6 latest differences and smoothed values of the dimension so conceptually something like `[avg3(diff1(x-5)), avg3(diff1(x-4)), avg3(diff1(x-3)), avg3(diff1(x-2)), avg3(diff1(x-1)), avg3(diff1(x))]` which ends up being just 6 floating point numbers that try and represent the "shape" of recent data.
95
+- DAR = Dimension Anomaly Rate
96
+- NAR = Node Anomaly Rate
97
+- NAR_t1-t10 = Node Anomaly Rate over t1 to t10
98
240
-#### _anomaly score_
99
+To calculate an anomaly rate, we can take the average of a row or a column in any direction.
100
242
-At prediction time the anomaly score is just the distance of the most recent feature vector to the trained cluster centers of the model, which are themselves just feature vectors, albeit supposedly the best most representative feature vectors that could be "learned" from the training data. So if the most recent feature vector is very far away in terms of [euclidean distance](https://en.wikipedia.org/wiki/Euclidean_distance#:~:text=In%20mathematics%2C%20the%20Euclidean%20distance,being%20called%20the%20Pythagorean%20distance.) it's more likely that the recent data it represents consists of some strange pattern not commonly found in the training data.
101
+For example, if we were to average along one row then this would be the Node Anomaly Rate, NAR (for all dimensions) at time `t`.
102
244
-#### _anomaly bit_
103
+Likewise if we averaged a column then we would have the dimension anomaly rate for each dimension over the time window `t = 1-10`. Extending this idea, we can work out an overall anomaly rate for the whole matrix or any subset of it we might be interested in.
104
246
-If the anomaly score is greater than a specified threshold then the most recent feature vector, and hence most recent raw data, is considered anomalous. Since storing the raw anomaly score would essentially double amount of storage space Netdata would need, we instead efficiently store just the anomaly bit in the existing internal Netdata data representation without any additional storage overhead.
105
+### Anomaly detector, node level anomaly events
106
248
-#### _anomaly rate_
107
+An anomaly detector looks at all the anomaly bits of a node. Netdata's anomaly detector produces an anomaly event when the percentage of anomaly bits is high enough for a persistent amount of time.
108
250
-An anomaly rate is really just an average over one or more anomaly bits. An anomaly rate can be calculated over time for one or more dimensions or at a point in time across multiple dimensions, or some combination of the two. Its just an average of some collection of anomaly bits.
109
+This anomaly event signals that there was sufficient evidence among all the anomaly bits that some strange behavior might have been detected in a more global sense across the node.
110
252
-#### _anomaly detector_
111
+Essentially if the Node Anomaly Rate (NAR) passes a defined threshold and stays above that threshold for a persistent amount of time, a node anomaly event will be triggered.
112
254
-The is essentially business logic that just tries to process a collection of anomaly bits to determine if there is enough active anomaly bits to merit investigation or declaration of a node level anomaly event.
255
-
256
-#### _anomaly event_
257
-
258
-Anomaly events are triggered by the anomaly detector and represent a window of time on the node with sufficiently elevated anomaly rates across all dimensions.
259
-
260
-#### _dimension anomaly rate_
261
-
262
-The anomaly rate of a specific dimension over some window of time.
263
-
264
-#### _node anomaly rate_
113
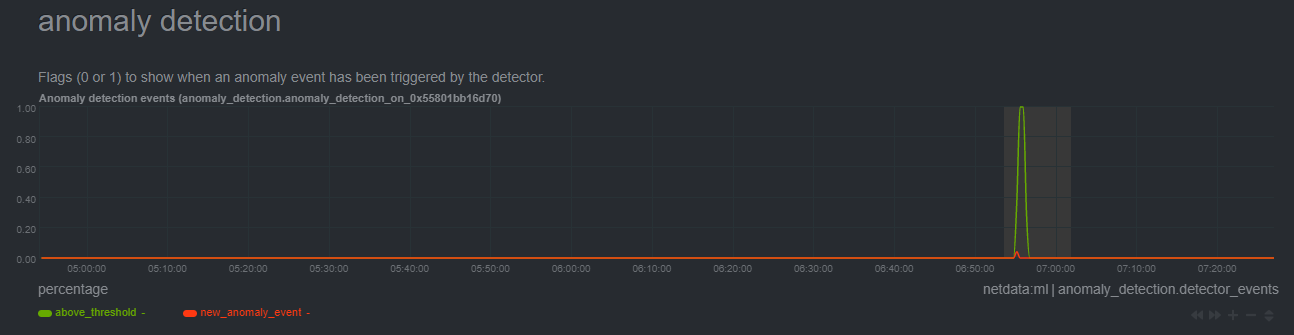
+These anomaly events are currently exposed via the `new_anomaly_event` dimension on the `anomaly_detection.anomaly_detection` chart.
114
266
-The anomaly rate across all dimensions of a node.
115
+## Charts
116
268
-## Notes
117
+Once enabled, the "Anomaly Detection" menu and charts will be available on the dashboard.
118
270
-- We would love to hear any feedback relating to this functionality, please email us at analytics-ml-team@netdata.cloud or come join us in the [🤖-ml-powered-monitoring](https://discord.gg/4eRSEUpJnc) channel of the Netdata discord.
271
-- We are working on additional UI/UX based features that build on these core components to make them as useful as possible out of the box.
272
-- Although not yet a core focus of this work, users could leverage the `anomaly_detection` chart dimensions and/or `anomaly-bit` options in defining alerts based on ML driven anomaly detection models.
273
-- [This presentation](https://docs.google.com/presentation/d/18zkCvU3nKP-Bw_nQZuXTEa4PIVM6wppH3VUnAauq-RU/edit?usp=sharing) walks through some of the main concepts covered above in a more informal way.
274
-- After restart Netdata will wait until `minimum num samples to train` observations of data are available before starting training and prediction.
275
-- Netdata uses [dlib](https://github.com/davisking/dlib) under the hood for its core ML features.
276
-- You should benchmark Netdata resource usage before and after enabling ML. Typical overhead ranges from 1-2% additional CPU at most.
277
-- The "anomaly bit" has been implemented to be a building block to underpin many more ML based use cases that we plan to deliver soon.
278
-- At its core Netdata uses an approach and problem formulation very similar to the Netdata python [anomalies collector](https://github.com/netdata/netdata/blob/master/src/collectors/python.d.plugin/anomalies/README.md), just implemented in a much much more efficient and scalable way in the agent in c++. So if you would like to learn more about the approach and are familiar with Python that is a useful resource to explore, as is the corresponding [deep dive tutorial](https://nbviewer.org/github/netdata/community/blob/main/netdata-agent-api/netdata-pandas/anomalies_collector_deepdive.ipynb) where the default model used is PCA instead of K-Means but the overall approach and formulation is similar.
279
-- Check out our ML related blog posts over at [https://blog.netdata.cloud](https://blog.netdata.cloud/tags/machine-learning)
119
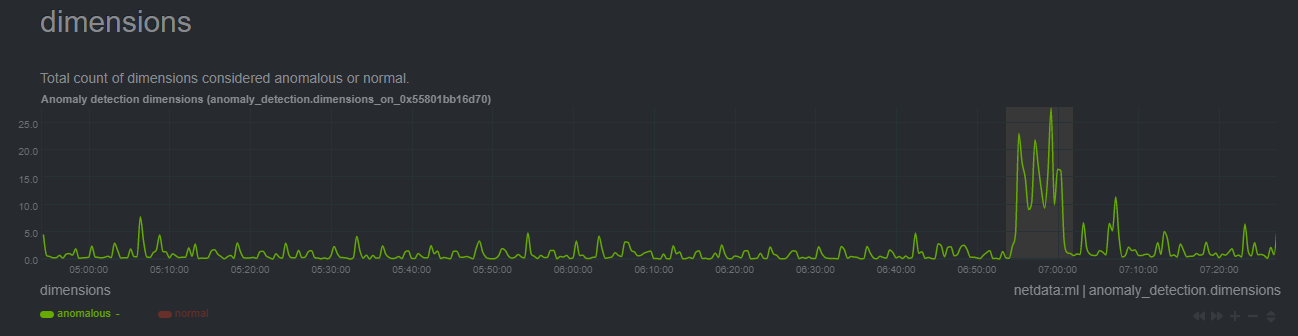
+- `anomaly_detection.dimensions`: Total count of dimensions considered anomalous or normal.
120
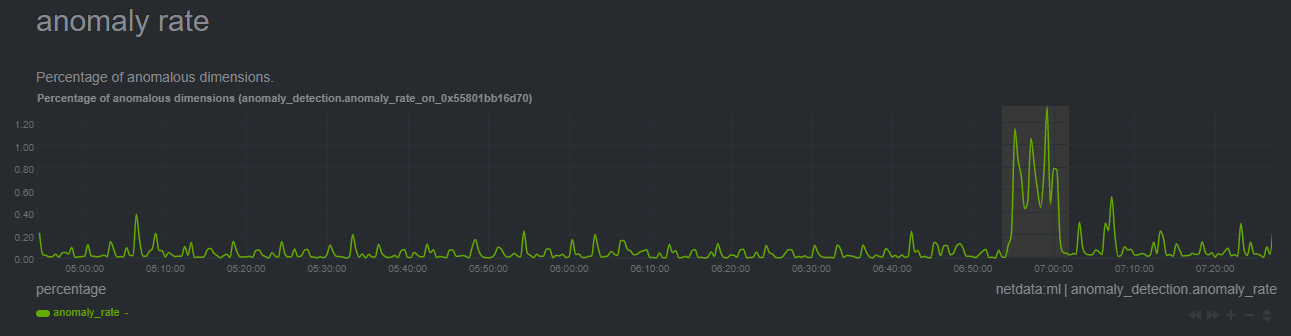
+- `anomaly_detection.anomaly_rate`: Percentage of anomalous dimensions.
121
+- `anomaly_detection.anomaly_detection`: Flags (0 or 1) to show when an anomaly event has been triggered by the detector.
src/ml/ml-configuration.md
new
+105
@@ -0,0 +1,105 @@
1
+# ML Configuration
2
+
3
+Netdata's [Machine Learning](https://github.com/netdata/netdata/blob/master/src/ml/README.md) capabilities are enabled by default.
4
+
5
+To enable or disable Machine Learning capabilities on a node:
6
+
7
+1. [Edit `netdata.conf`](https://github.com/netdata/netdata/blob/master/docs/netdata-agent/configuration.md#edit-netdataconf)
8
+2. In the `[ml]` section, set `enabled = yes` to enable or `enabled = no` to disable
9
+3. [Restart Netdata](https://github.com/netdata/netdata/blob/master/docs/maintenance/start-stop-restart.md)
10
+
11
+Below is a list of all the available configuration params and their default values.
12
+
13
+```bash
14
+[ml]
15
+ # enabled = yes
16
+ # maximum num samples to train = 21600
17
+ # minimum num samples to train = 900
18
+ # train every = 10800
19
+ # number of models per dimension = 18
20
+ # dbengine anomaly rate every = 30
21
+ # num samples to diff = 1
22
+ # num samples to smooth = 3
23
+ # num samples to lag = 5
24
+ # random sampling ratio = 0.2
25
+ # maximum number of k-means iterations = 1000
26
+ # dimension anomaly score threshold = 0.99
27
+ # host anomaly rate threshold = 1.0
28
+ # anomaly detection grouping method = average
29
+ # anomaly detection grouping duration = 300
30
+ # hosts to skip from training = !*
31
+ # charts to skip from training = netdata.*
32
+ # dimension anomaly rate suppression window = 900
33
+ # dimension anomaly rate suppression threshold = 450
34
+ # delete models older than = 604800
35
+```
36
+
37
+## Configuration Examples
38
+
39
+If you would like to run ML on a parent instead of at the edge, some configuration options are illustrated below.
40
+
41
+This example assumes 3 child nodes [streaming](https://github.com/netdata/netdata/blob/master/docs/observability-centralization-points/metrics-centralization-points/README.md) to 1 parent node and illustrates the main ways you might want to configure running ML for the children on the parent, running ML on the children themselves, or even a mix of approaches.
42
+
43
+```mermaid
44
+flowchart BT
45
+ C1["Netdata Child 0
46
+ ML enabled"]
47
+ C2["Netdata Child 1
48
+ ML enabled"]
49
+ C3["Netdata Child 2
50
+ ML disabled"]
51
+ P1["Netdata Parent
52
+ (ML enabled for itself and Child 1 & 2)"]
53
+ C1 --> P1
54
+ C2 --> P1
55
+ C3 --> P1
56
+```
57
+
58
+```text
59
+# parent will run ML for itself and child 1,2, it will skip running ML for child 0.
60
+# child 0 will run its own ML at the edge.
61
+# child 1 will run its own ML at the edge, even though parent will also run ML for it, a bit wasteful potentially to run ML in both places but is possible (Netdata Cloud will essentially average any overlapping models).
62
+# child 2 will not run ML at the edge, it will be run in the parent only.
63
+
64
+# parent-ml-enabled
65
+# run ML on all hosts apart from child-ml-enabled
66
+[ml]
67
+ enabled = yes
68
+ hosts to skip from training = child-0-ml-enabled
69
+
70
+# child-0-ml-enabled
71
+# run ML on child-0-ml-enabled
72
+[ml]
73
+ enabled = yes
74
+
75
+# child-1-ml-enabled
76
+# run ML on child-1-ml-enabled
77
+[ml]
78
+ enabled = yes
79
+
80
+# child-2-ml-disabled
81
+# do not run ML on child-2-ml-disabled
82
+[ml]
83
+ enabled = no
84
+```
85
+
86
+## Descriptions (min/max)
87
+
88
+- `enabled`: `yes` to enable, `no` to disable.
89
+- `maximum num samples to train`: (`3600`/`86400`) This is the maximum amount of time you would like to train each model on. For example, the default of `21600` trains on the preceding 6 hours of data, assuming an `update every` of 1 second.
90
+- `minimum num samples to train`: (`900`/`21600`) This is the minimum amount of data required to be able to train a model. For example, the default of `900` implies that once at least 15 minutes of data is available for training, a model is trained, otherwise it is skipped and checked again at the next training run.
91
+- `train every`: (`1800`/`21600`) This is how often each model will be retrained. For example, the default of `10800` means that each model is retrained every 3 hours. Note: The training of all models is spread out across the `train every` period for efficiency, so in reality, it means that each model will be trained in a staggered manner within each `train every` period.
92
+- `number of models per dimension`: (`1`/`168`) This is the number of trained models that will be used for scoring. For example the default `number of models per dimension = 18` means that the most recently trained 18 models for the dimension will be used to determine the corresponding anomaly bit. This means that under default settings of `maximum num samples to train = 21600`, `train every = 10800` and `number of models per dimension = 18`, netdata will store and use the last 18 trained models for each dimension when determining the anomaly bit. This means that for the latest feature vector in this configuration to be considered anomalous it would need to look anomalous across _all_ the models trained for that dimension in the last 18*(10800/3600) ~= 54 hours. As such, increasing `number of models per dimension` may reduce some false positives since it will result in more models (covering a wider time frame of training) being used during scoring.
93
+- `dbengine anomaly rate every`: (`30`/`900`) This is how often netdata will aggregate all the anomaly bits into a single chart (`anomaly_detection.anomaly_rates`). The aggregation into a single chart allows enabling anomaly rate ranking over _all_ metrics with one API call as opposed to a call per chart.
94
+- `num samples to diff`: (`0`/`1`) This is a `0` or `1` to determine if you want the model to operate on differences of the raw data or just the raw data. For example, the default of `1` means that we take differences of the raw values. Using differences is more general and works on dimensions that might naturally tend to have some trends or cycles in them that is normal behavior to which we don't want to be too sensitive.
95
+- `num samples to smooth`: (`0`/`5`) This is a small integer that controls the amount of smoothing applied as part of the feature processing used by the model. For example, the default of `3` means that the rolling average of the last 3 values is used. Smoothing like this helps the model be a little more robust to spiky types of dimensions that naturally "jump" up or down as part of their normal behavior.
96
+- `num samples to lag`: (`0`/`5`) This is a small integer that determines how many lagged values of the dimension to include in the feature vector. For example, the default of `5` means that in addition to the most recent (by default, differenced and smoothed) value of the dimension, the feature vector will also include the 5 previous values too. Using lagged values in our feature representation allows the model to work over strange patterns over recent values of a dimension as opposed to just focusing on if the most recent value itself is big or small enough to be anomalous.
97
+- `random sampling ratio`: (`0.2`/`1.0`) This parameter determines how much of the available training data is randomly sampled when training a model. The default of `0.2` means that Netdata will train on a random 20% of training data. This parameter influences cost efficiency. At `0.2` the model is still reasonably trained while minimizing system overhead costs caused by the training.
98
+- `maximum number of k-means iterations`: This is a parameter that can be passed to the model to limit the number of iterations in training the k-means model. Vast majority of cases can ignore and leave as default.
99
+- `dimension anomaly score threshold`: (`0.01`/`5.00`) This is the threshold at which an individual dimension at a specific timestep is considered anomalous or not. For example, the default of `0.99` means that a dimension with an anomaly score of 99% or higher is flagged as anomalous. This is a normalized probability based on the training data, so the default of 99% means that anything that is as strange (based on distance measure) or more strange as the most strange 1% of data observed during training will be flagged as anomalous. If you wanted to make the anomaly detection on individual dimensions more sensitive you could try a value like `0.90` (90%) or to make it less sensitive you could try `1.5` (150%).
100
+- `host anomaly rate threshold`: (`0.1`/`10.0`) This is the percentage of dimensions (based on all those enabled for anomaly detection) that need to be considered anomalous at specific timestep for the host itself to be considered anomalous. For example, the default value of `1.0` means that if more than 1% of dimensions are anomalous at the same time then the host itself is considered in an anomalous state.
101
+- `anomaly detection grouping method`: The grouping method used when calculating node level anomaly rate.
102
+- `anomaly detection grouping duration`: (`60`/`900`) The duration across which to calculate the node level anomaly rate, the default of `900` means that the node level anomaly rate is calculated across a rolling 5 minute window.
103
+- `hosts to skip from training`: This parameter allows you to turn off anomaly detection for any child hosts on a parent host by defining those you would like to skip from training here. For example, a value like `dev-*` skips all hosts on a parent that begin with the "dev-" prefix. The default value of `!*` means "don't skip any".
104
+- `charts to skip from training`: This parameter allows you to exclude certain charts from anomaly detection. By default, only netdata related charts are excluded. This is to avoid the scenario where accessing the netdata dashboard could itself trigger some anomalies if you don't access them regularly. If you want to include charts that are excluded by default, add them in small groups and then measure any impact on performance before adding additional ones. Example: If you want to include system, apps, and user charts:`!system.* !apps.* !user.* *`.
105
+- `delete models older than`: (`86400`/`604800`) Delete old models from the database that are unused, by default models will be deleted after 7 days.