Update guide: Kubernetes monitoring with Netdata: Overview and visualizations (#10691)
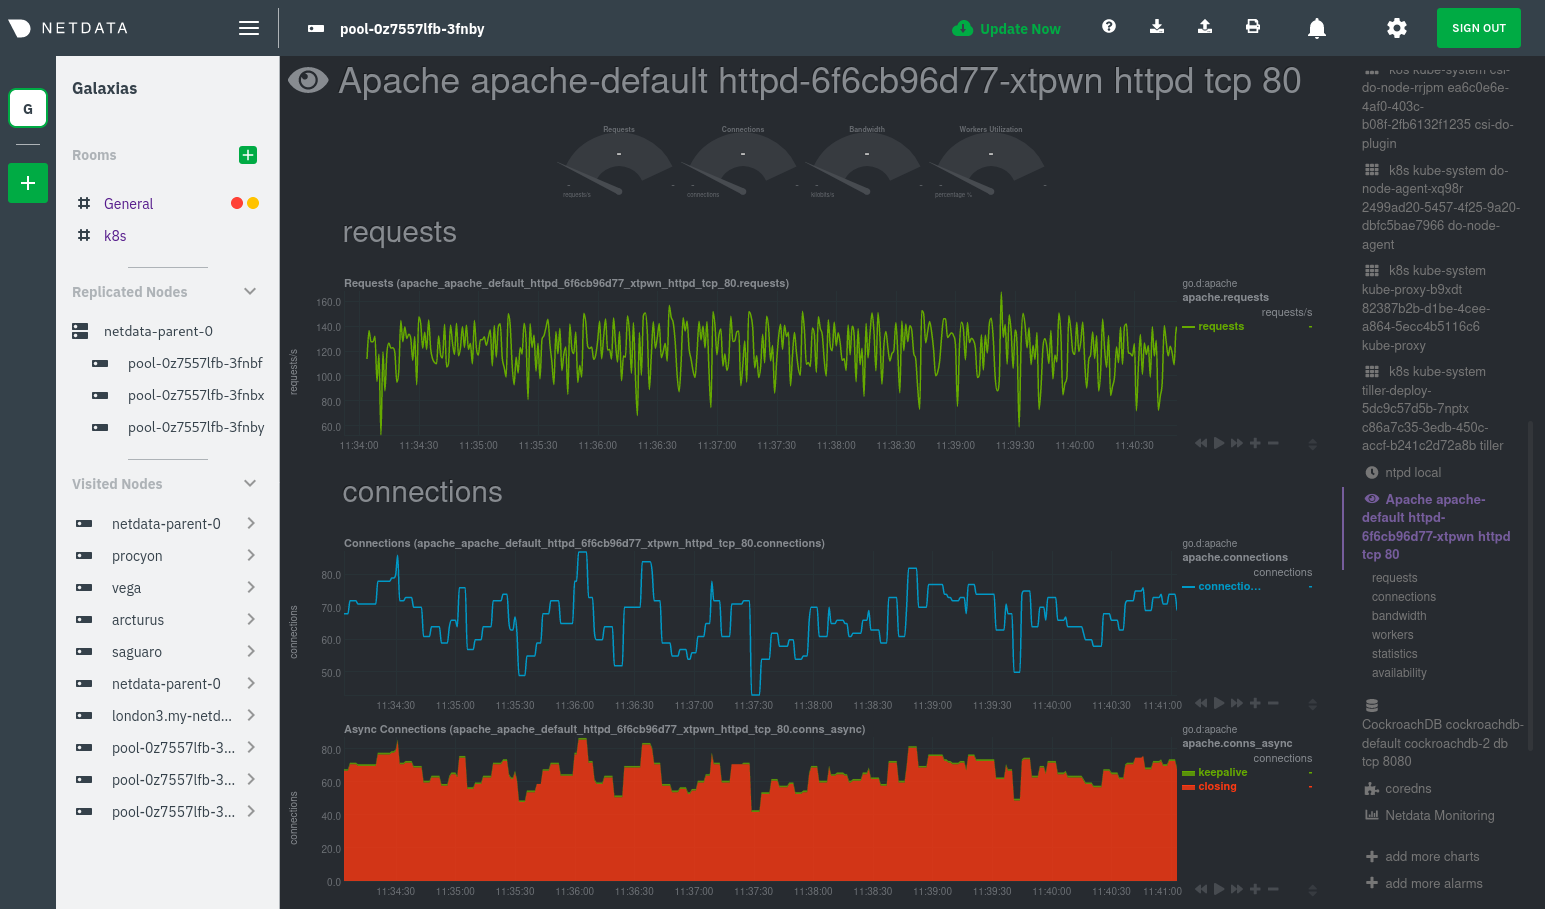
* Start work on update * Finish initial re-draft * Sneak in tweaks to anomaly guides * Tweaks to both guide and deploy instructions * Add meta description * Fixes for Odysseas
Joel Hans committed
Mar 4, 2021 at 06:44 UTC
39dc6ccc383826a8641d69a4800194fdaf45ff63
5 files changed
+207
-225
docs/guides/monitor/anomaly-detection.md
+9
-10
@@ -107,7 +107,7 @@ involve tweaking the behavior of the ML training itself.
107
doesn't have historical metrics going back that far, consider [changing the metrics retention
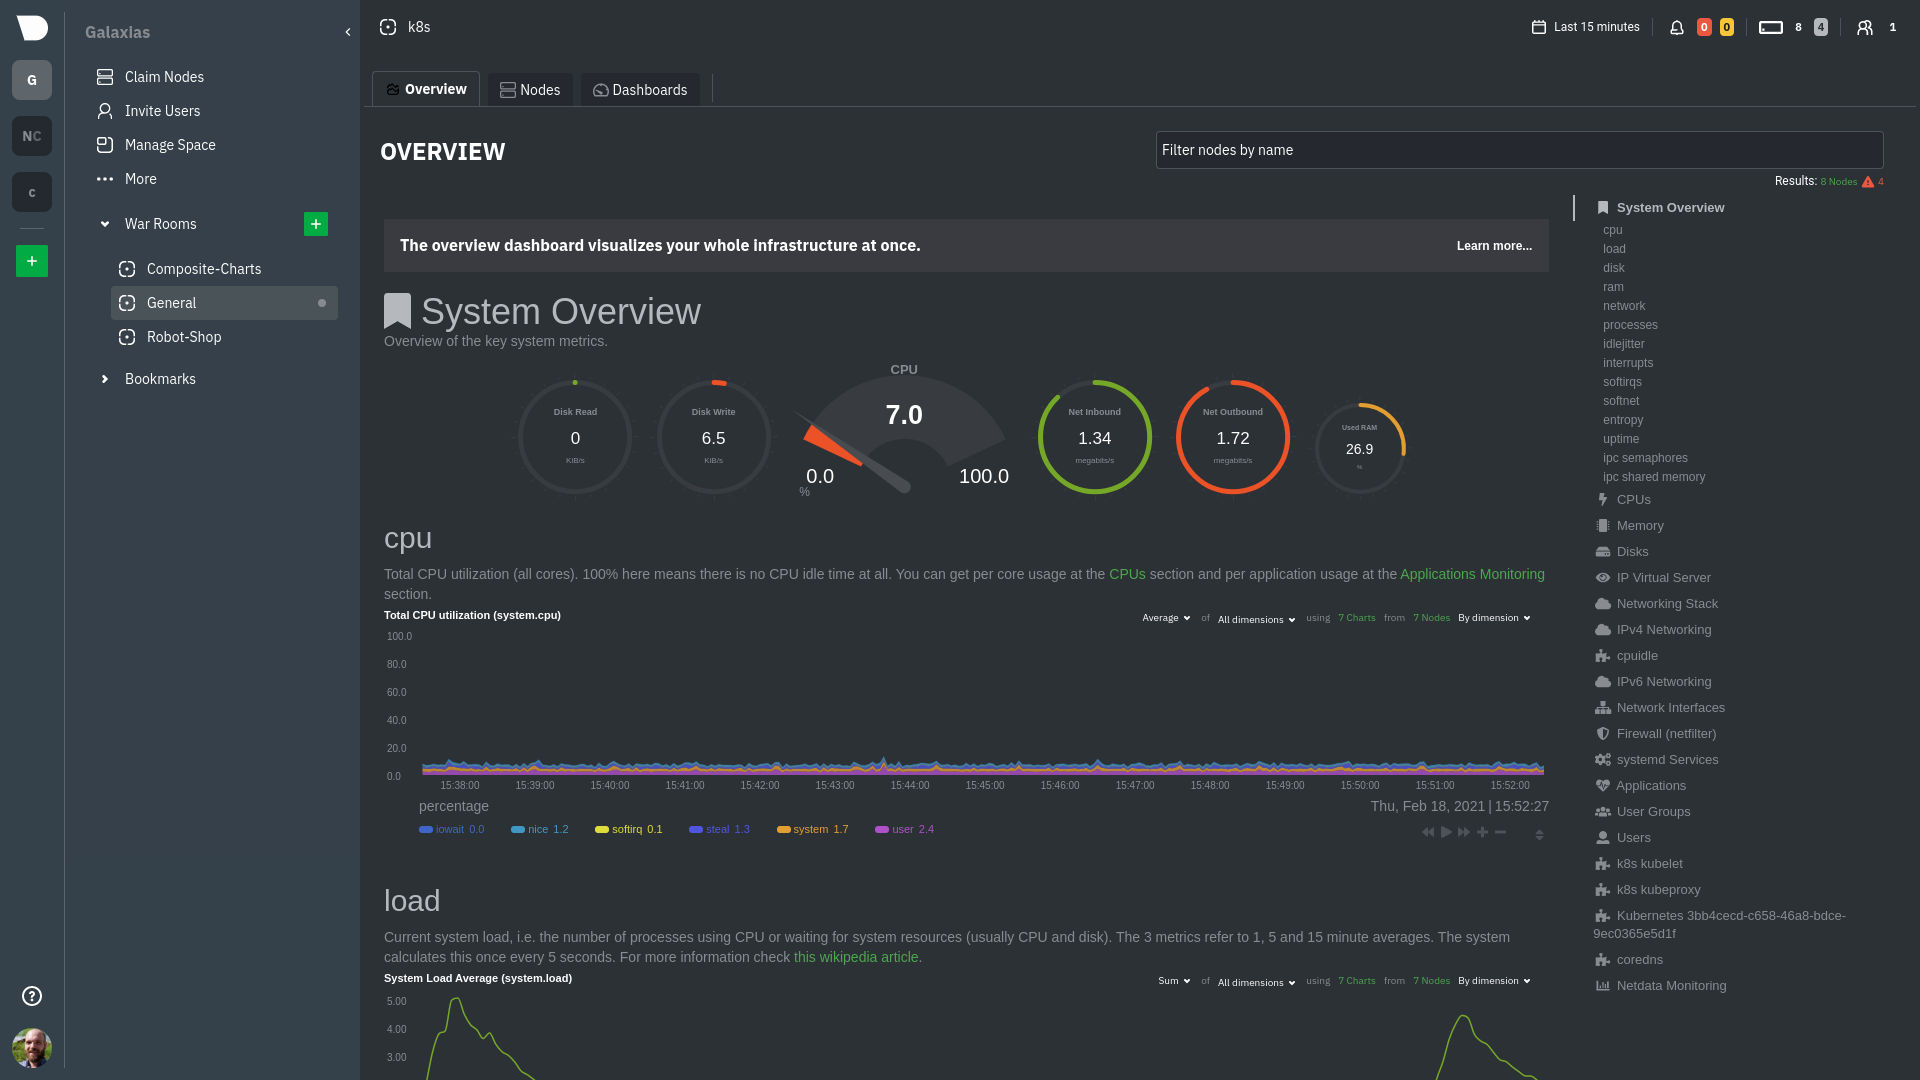
108
policy](/docs/store/change-metrics-storage.md) or reducing this window.
109
- `custom_models`: A way to define custom models that you want anomaly probabilities for, including multi-node or
110
- streaming setups. More on custom models in part 3 of this guide series.
110
+ streaming setups.
111
112
> ⚠️ Setting `charts_regex` with many charts or `train_n_secs` to a very large number will have an impact on the
113
> resources and time required to train a model for every chart. The actual performance implications depend on the
@@ -173,20 +173,19 @@ example, it's time to apply that knowledge to other mission-critical parts of yo
173
what to monitor next, check out our list of [collectors](/collectors/COLLECTORS.md) to see what kind of metrics Netdata
174
can collect from your systems, containers, and applications.
175
176
-For a more user-friendly anomaly detection experience, try out the [Metric
177
-Correlations](https://learn.netdata.cloud/docs/cloud/insights/metric-correlations) feature in Netdata Cloud. Metric
178
-Correlations runs only at your requests, removing unrelated charts from the dashboard to help you focus on root cause
179
-analysis.
176
+Keep on moving to [part 2](/docs/guides/monitor/visualize-monitor-anomalies.md), which covers the charts and alarms
177
+Netdata creates for unsupervised anomaly detection.
178
181
-Stay tuned for the next two parts of this guide, which provide more real-world context for the anomalies collector.
182
-First, maximize the immediate value you get from anomaly detection by tracking preconfigured alarms, visualizing
183
-anomalies in charts, and building a new dashboard tailored to your applications. Then, learn about creating custom ML
184
-models, which help you holistically monitor an application or service by monitoring anomalies across a _cluster of
185
-charts_.
179
+For a different troubleshooting experience, try out the [Metric
180
+Correlations](https://learn.netdata.cloud/docs/cloud/insights/metric-correlations) feature in Netdata Cloud. Metric
181
+Correlations helps you perform faster root cause analysis by narrowing a dashboard to only the charts most likely to be
182
+related to an anomaly.
183
184
### Related reference documentation
185
186
- [Netdata Agent · Anomalies collector](/collectors/python.d.plugin/anomalies/README.md)
187
+- [Netdata Agent · Nginx collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/nginx)
188
+- [Netdata Agent · web log collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/weblog)
189
- [Netdata Cloud · Metric Correlations](https://learn.netdata.cloud/docs/cloud/insights/metric-correlations)
190
191
[](<>)
docs/guides/monitor/kubernetes-k8s-netdata.md
+175
-199
@@ -1,11 +1,25 @@
1
<!--
2
-title: "Monitor a Kubernetes (k8s) cluster with Netdata"
3
-description: "Use Netdata's helmchart, service discovery plugin, and Kubelet/kube-proxy collectors for real-time visibility into your Kubernetes cluster."
2
+title: "Kubernetes monitoring with Netdata: Overview and visualizations"
3
+description: "Learn how to navigate Netdata's Kubernetes monitoring features for visualizing the health and performance of a Kubernetes cluster with per-second granulrity."
4
image: /img/seo/guides/monitor/kubernetes-k8s-netdata.png
5
+author: "Joel Hans"
6
+author_title: "Editorial Director, Technical & Educational Resources"
7
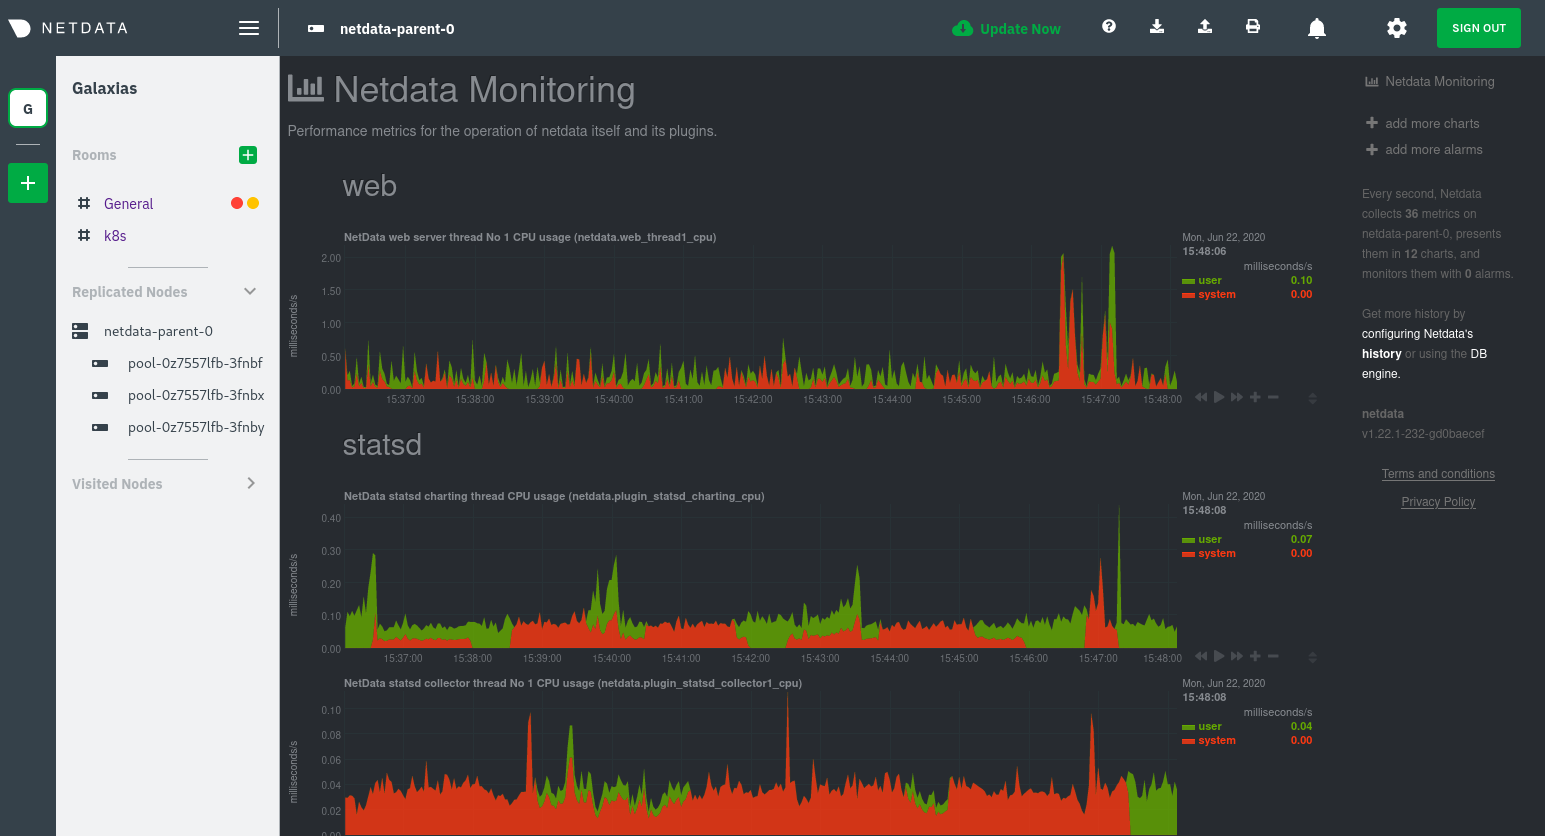
+author_img: "/img/authors/joel-hans.jpg"
8
custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/guides/monitor/kubernetes-k8s-netdata.md
9
-->
10
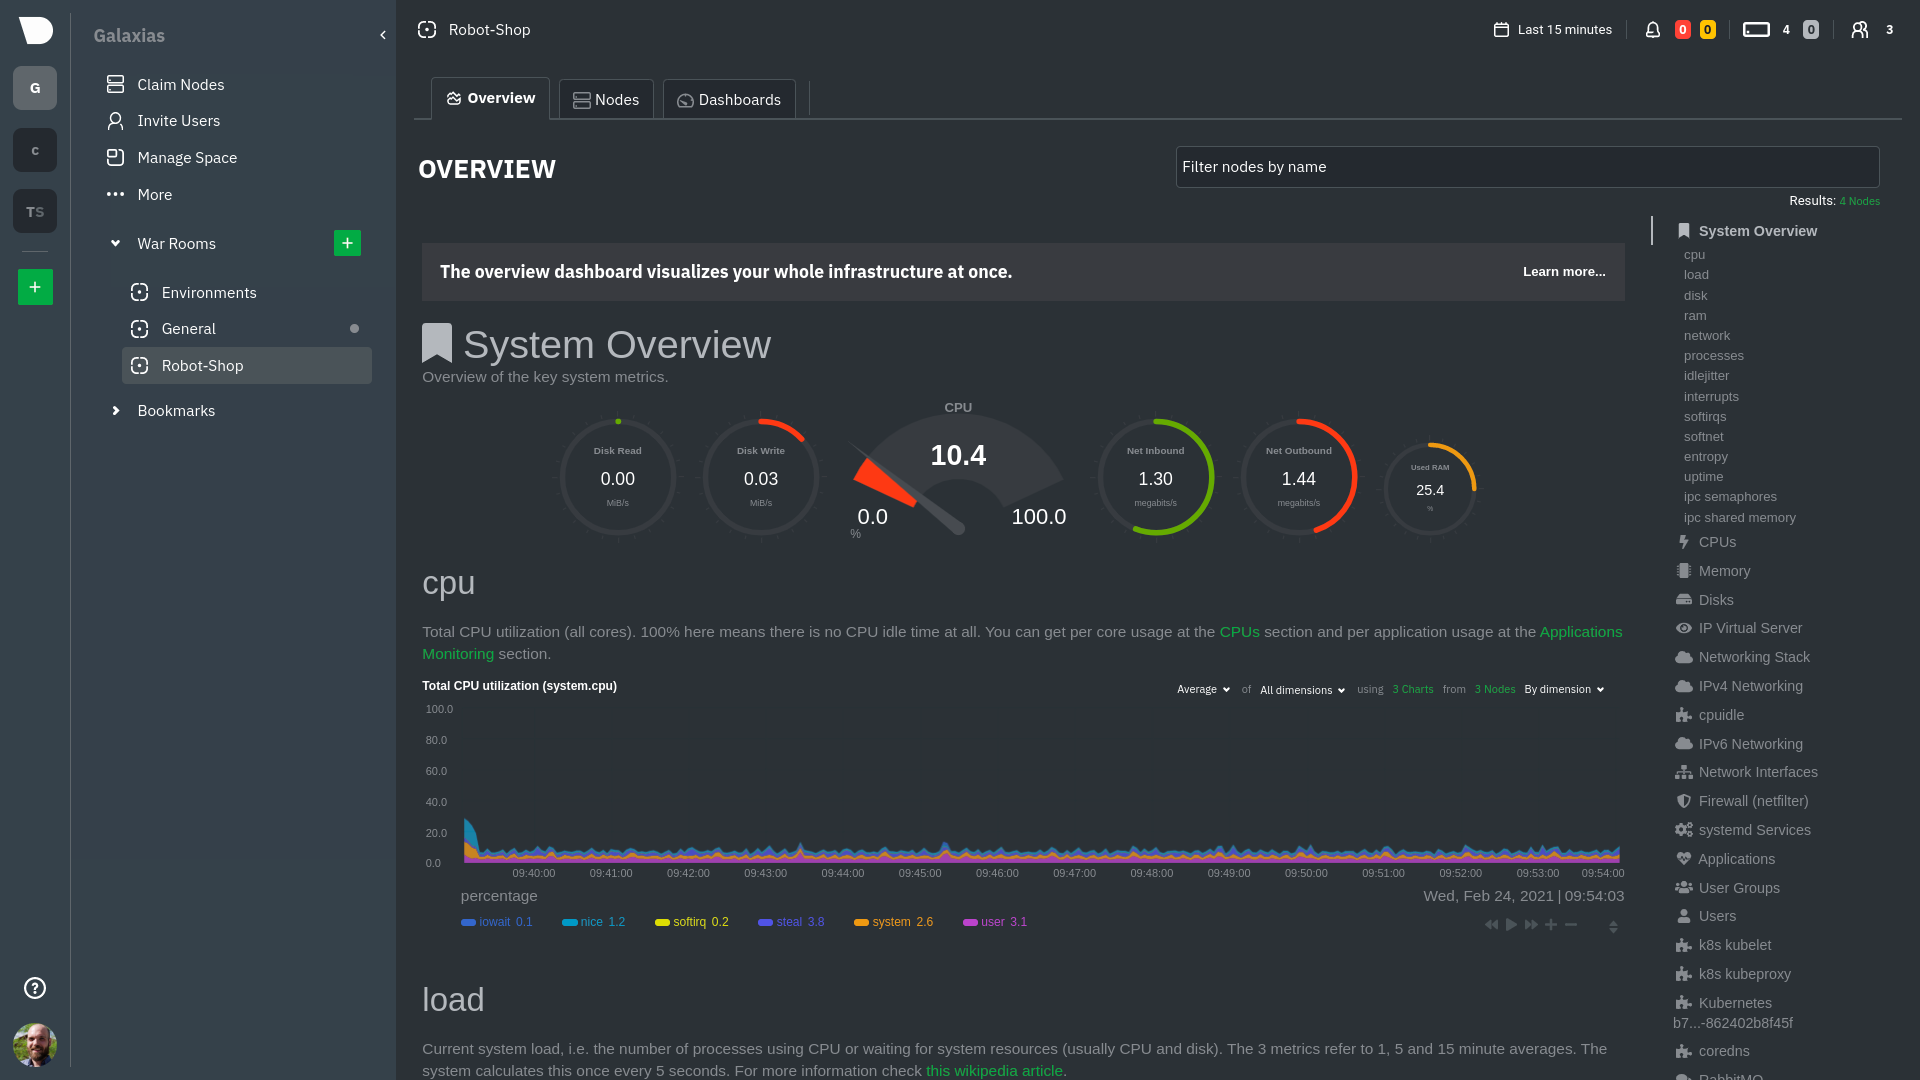
8
-# Monitor a Kubernetes cluster with Netdata
11
+# Kubernetes monitoring with Netdata: Overview and visualizations
12
+
13
+At Netdata, we've built Kubernetes monitoring tools that add visibility without complexity while also helping you
14
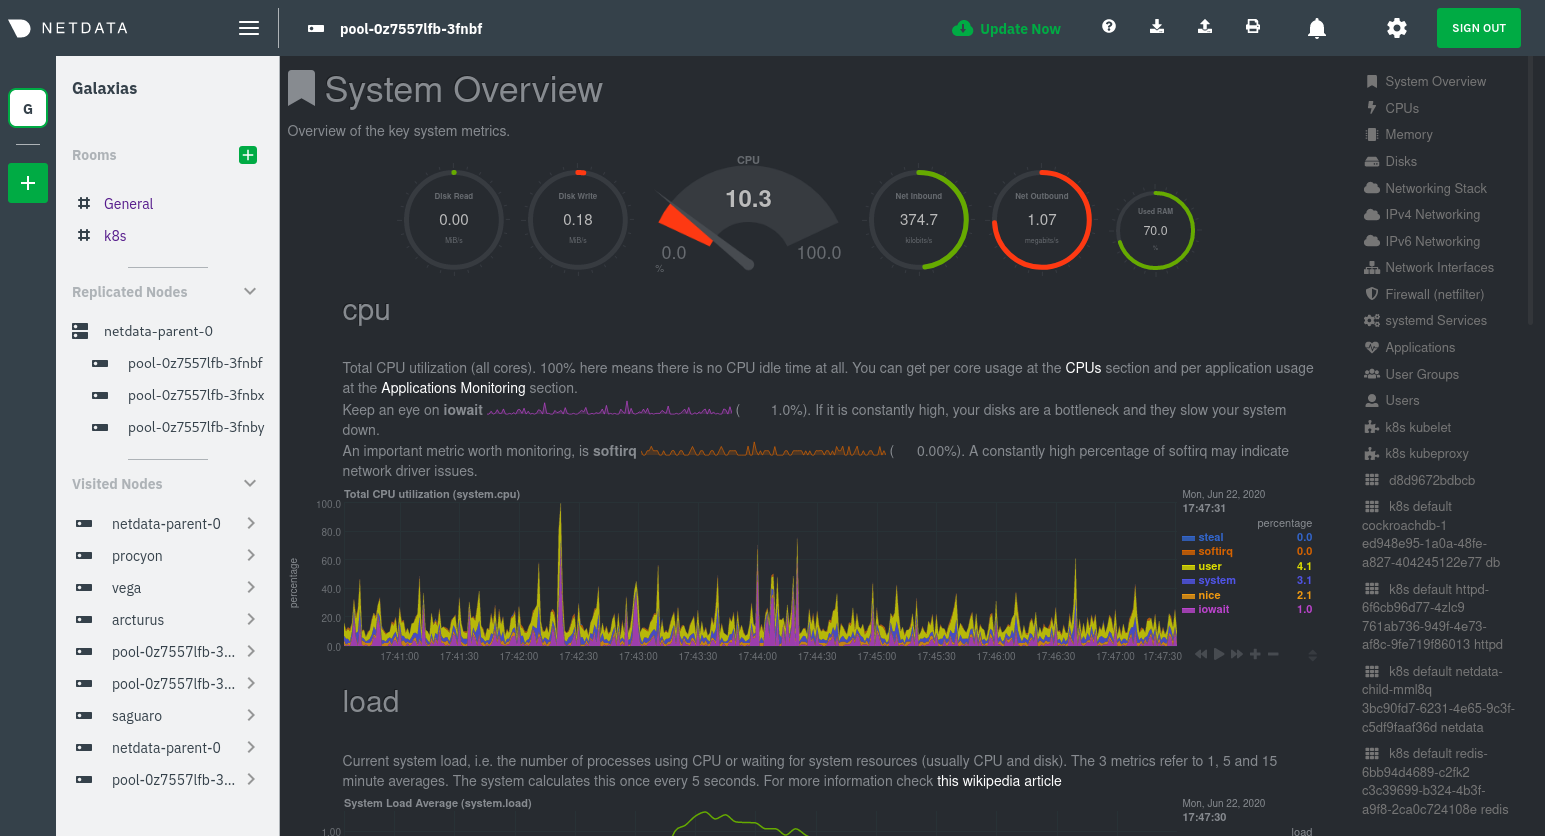
+actively troubleshoot anomalies or outages. This guide walks you through each of the visualizations and offers best
15
+practices on how to use them to start Kubernetes monitoring in a matter of minutes, not hours or days.
16
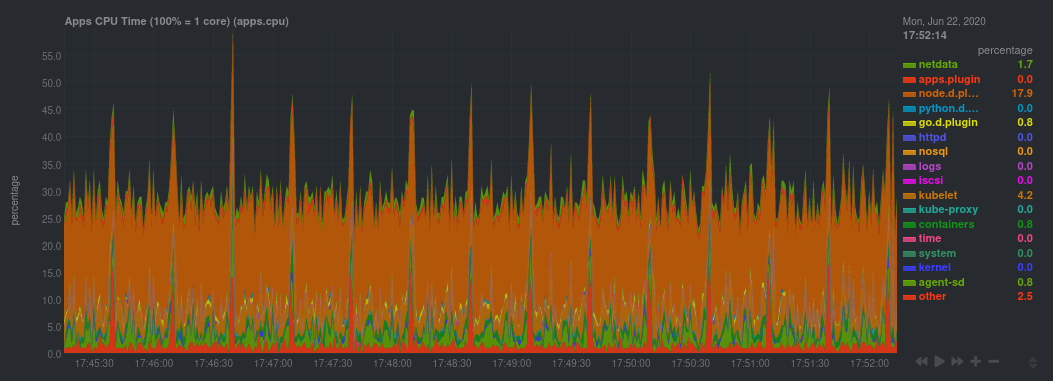
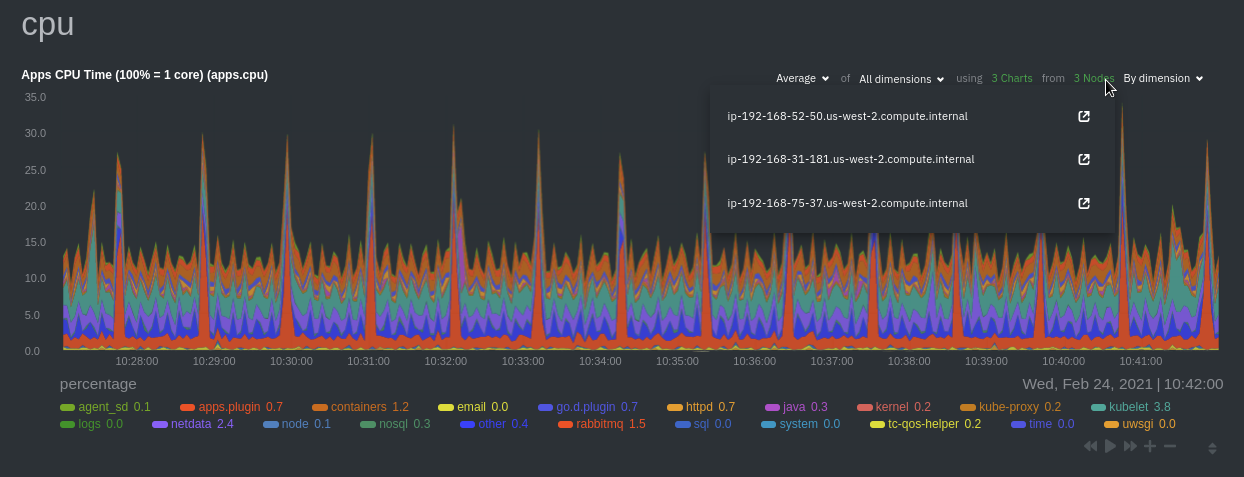
+
17
+Netdata's Kubernetes monitoring solution uses a handful of [complementary tools and
18
+collectors](#related-reference-documentation) for peeling back the many complex layers of a Kubernetes cluster,
19
+_entirely for free_. These methods work together to give you every metric you need to troubleshoot performance or
20
+availability issues across your Kubernetes infrastructure.
21
+
22
+## Challenge
23
24
While Kubernetes (k8s) might simplify the way you deploy, scale, and load-balance your applications, not all clusters
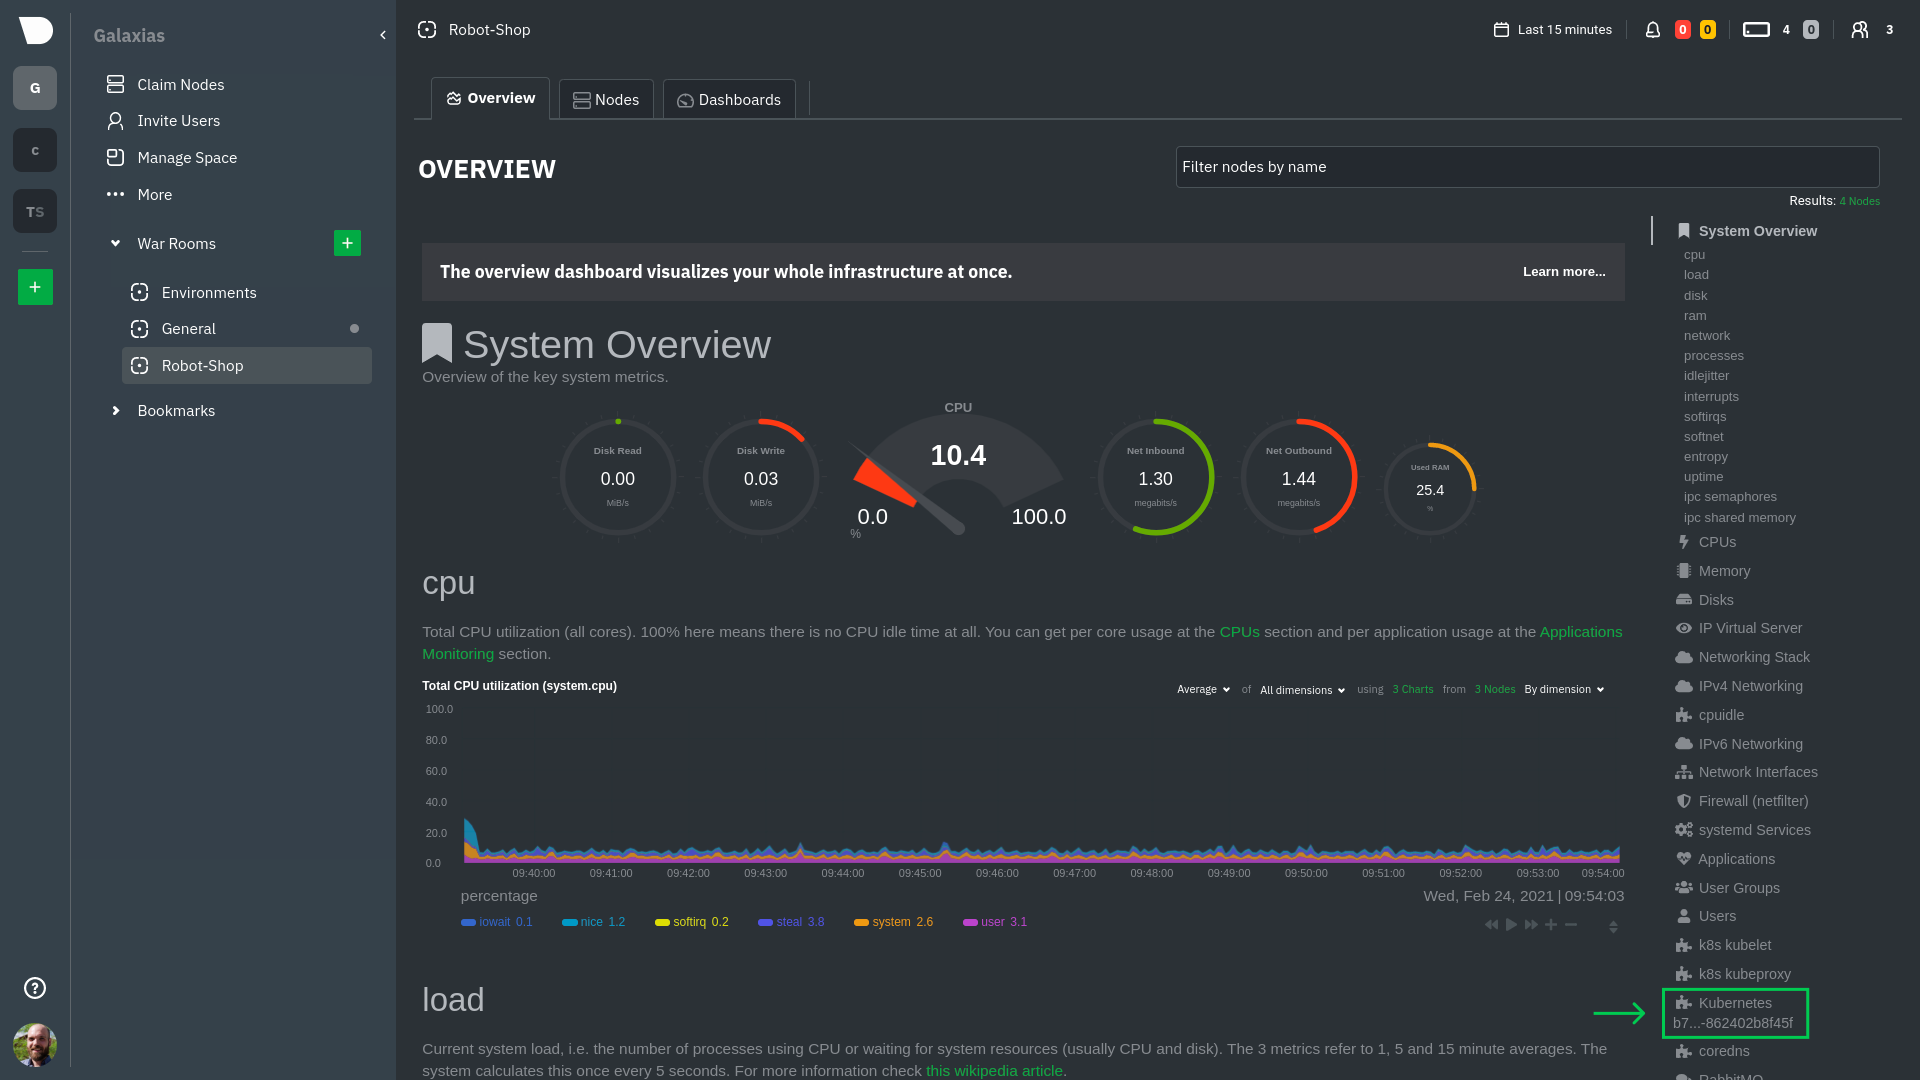
25
come with "batteries included" when it comes to monitoring. Doubly so for a monitoring stack that helps you actively
@@ -18,261 +32,223 @@ customization, or integration with your preferred alerting methods.
32
Without this visibility, it's like you built an entire house and _then_ smashed your way through the finished walls to
33
add windows.
34
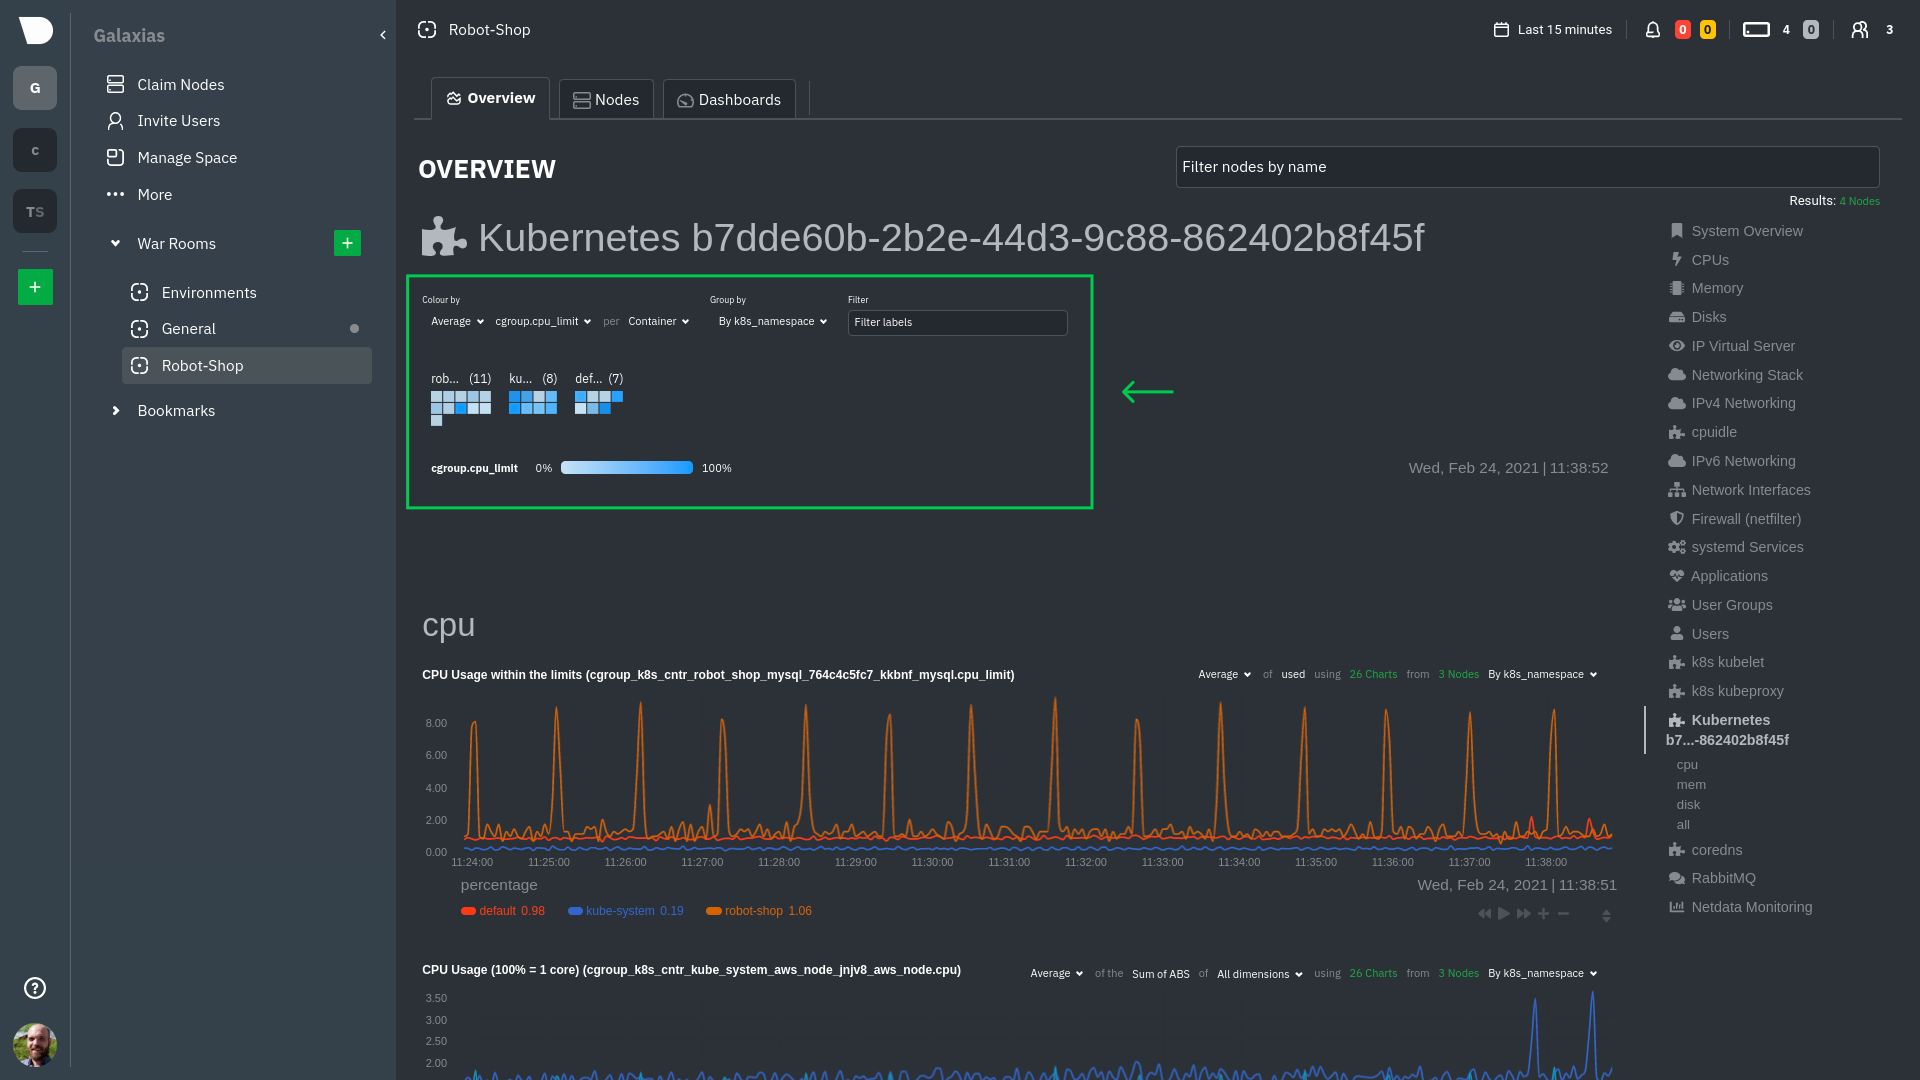
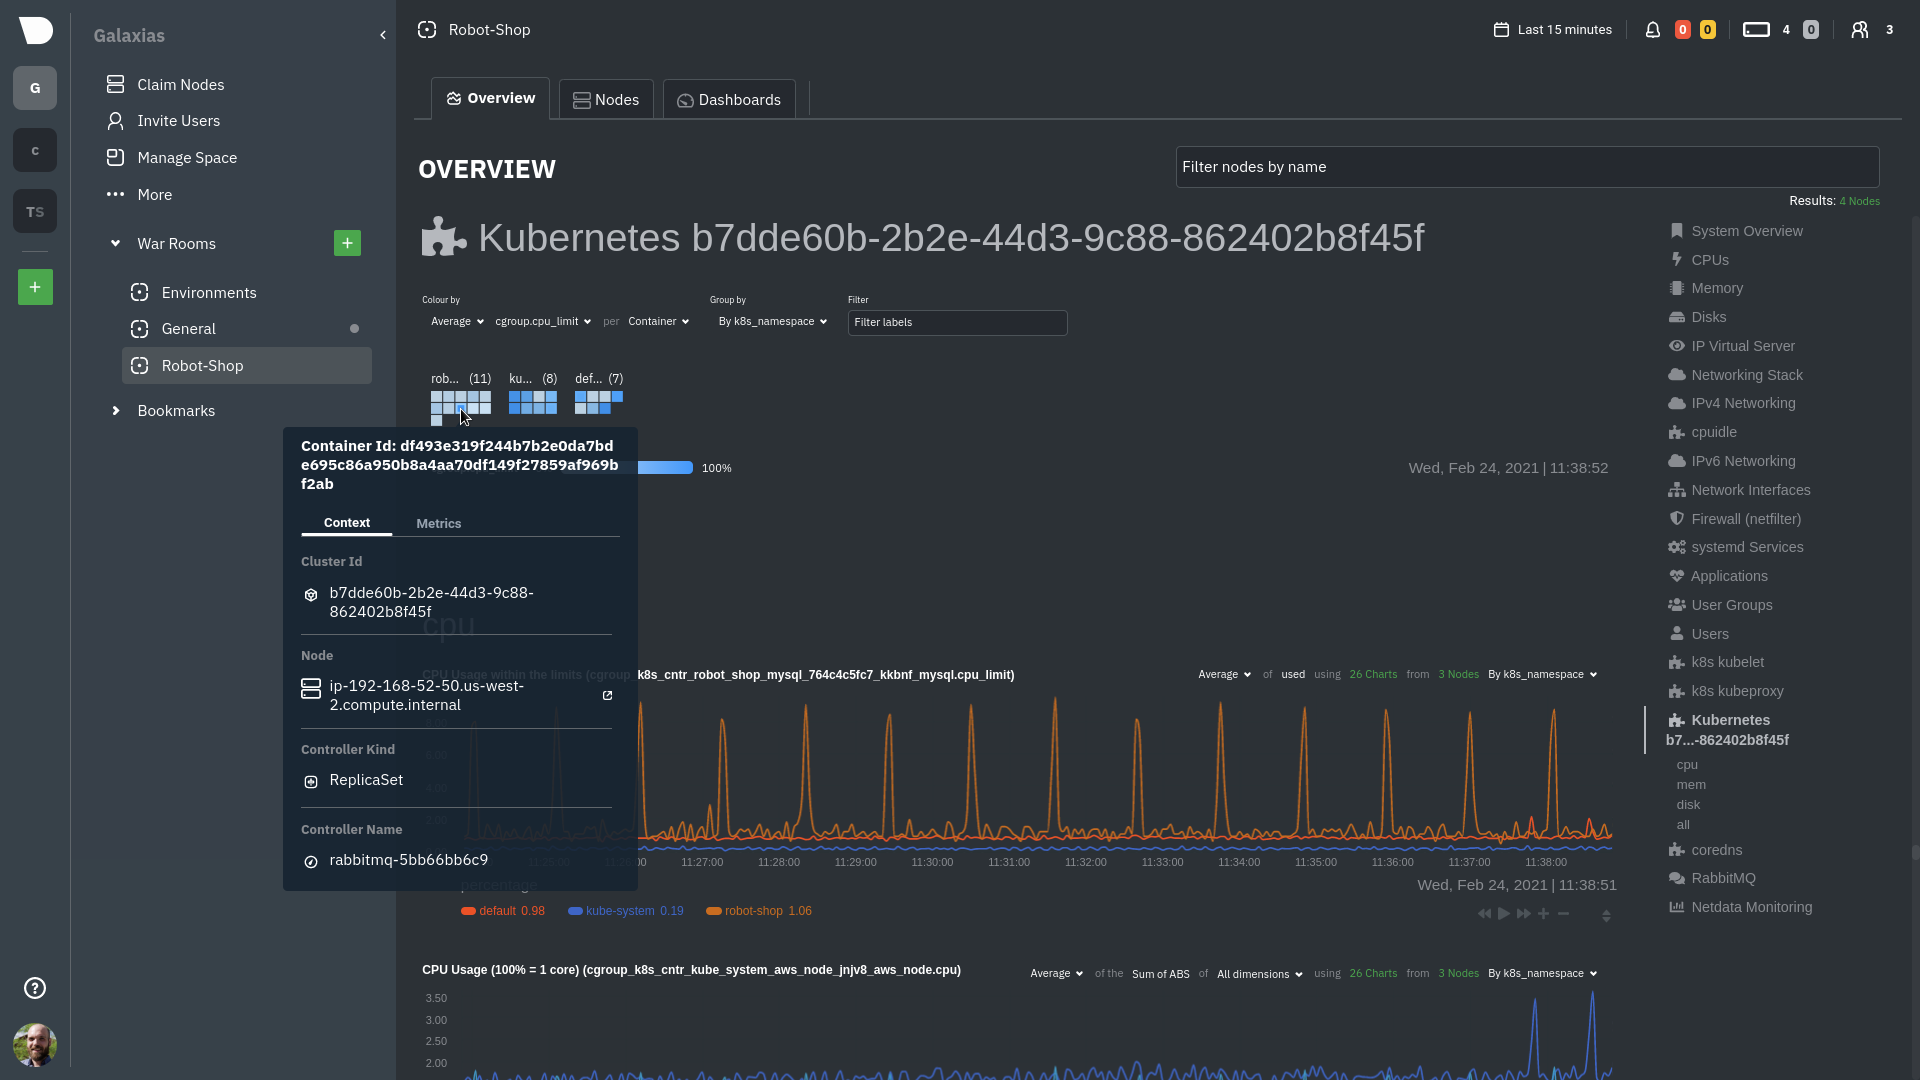
21
-At Netdata, we're working to build Kubernetes monitoring tools that add visibility without complexity while also helping
22
-you actively troubleshoot anomalies or outages. Better yet, this toolkit includes a few complementary collectors that
23
-let you monitor the many layers of a Kubernetes cluster entirely for free.
24
-
25
-We already have a few complementary tools and collectors for monitoring the many layers of a Kubernetes cluster,
26
-_entirely for free_. These methods work together to help you troubleshoot performance or availability issues across
27
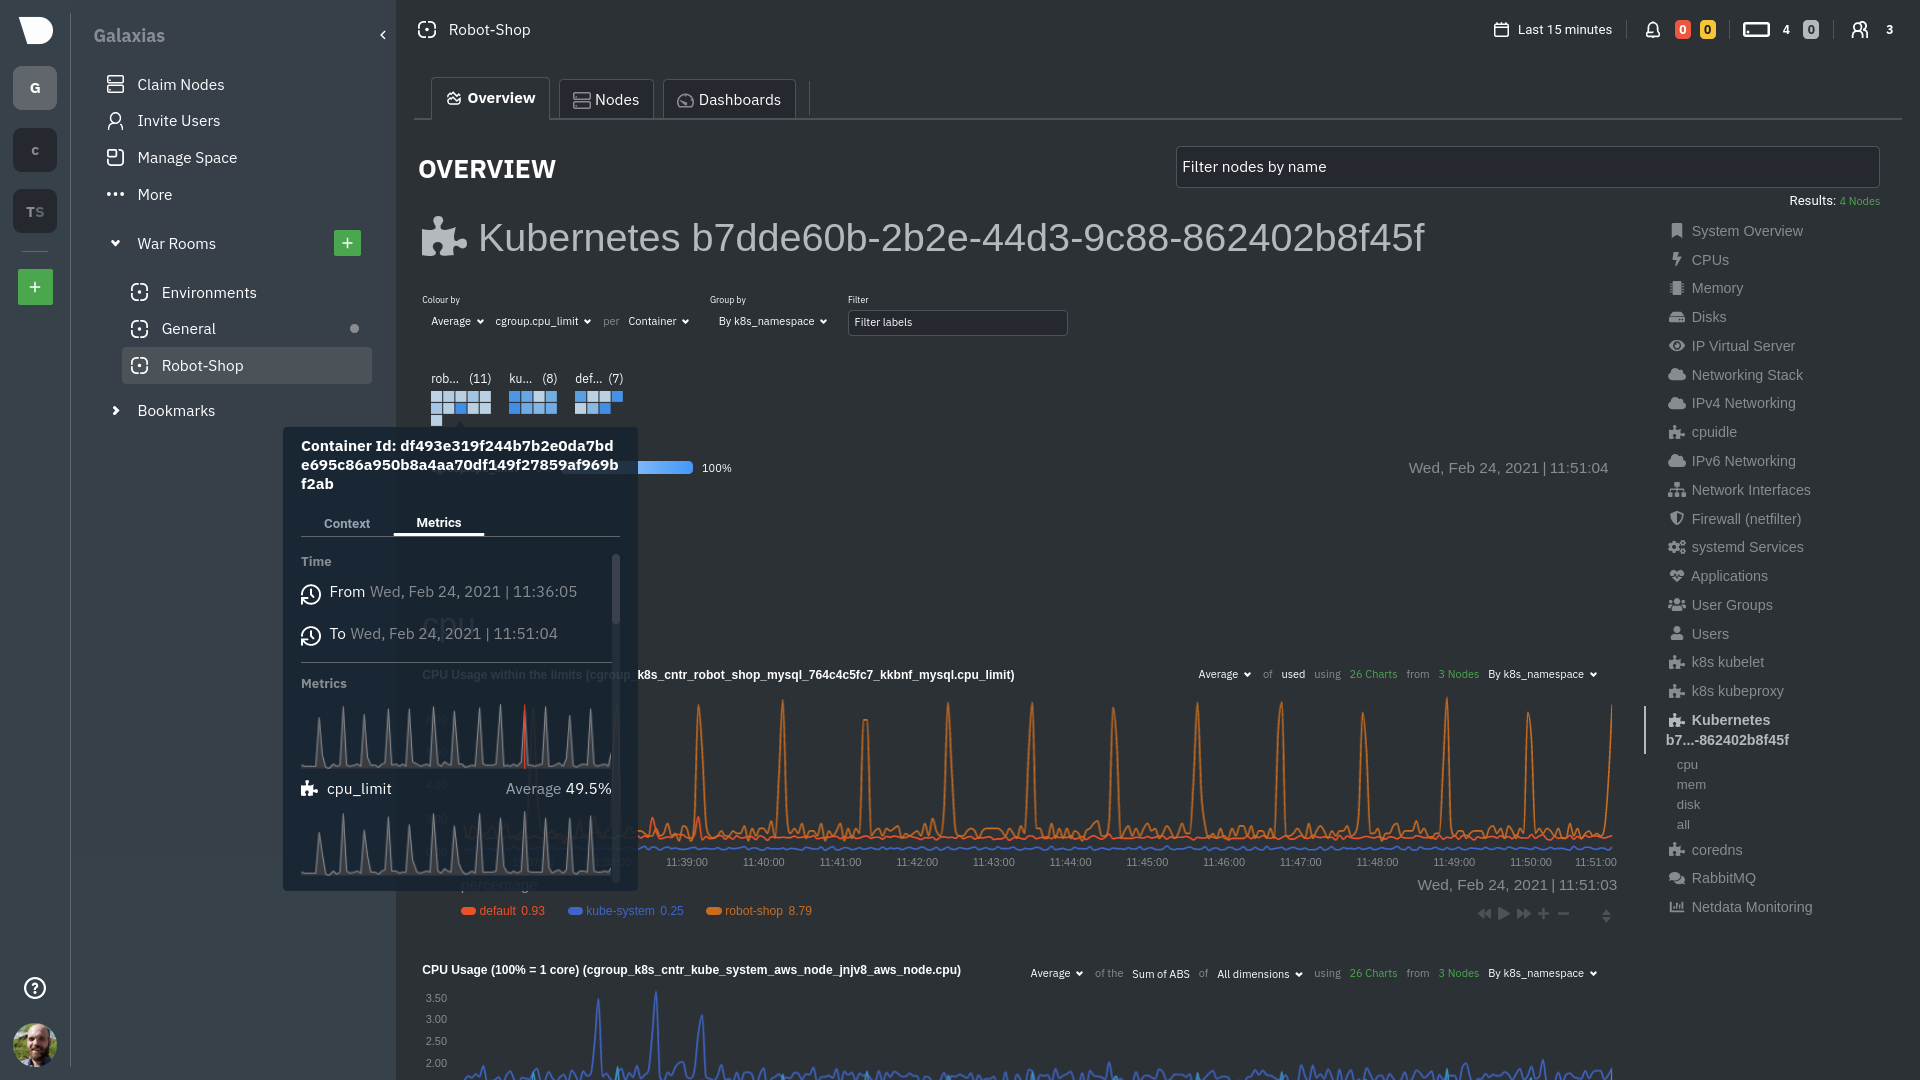
-your k8s infrastructure.
28
-
29
-- A [Helm chart](https://github.com/netdata/helmchart), which bootstraps a Netdata Agent pod on every node in your
30
- cluster, plus an additional parent pod for storing metrics and managing alarm notifications.
31
-- A [service discovery plugin](https://github.com/netdata/agent-service-discovery), which discovers and creates
32
- configuration files for [compatible
33
- applications](https://github.com/netdata/helmchart#service-discovery-and-supported-services) and any endpoints
34
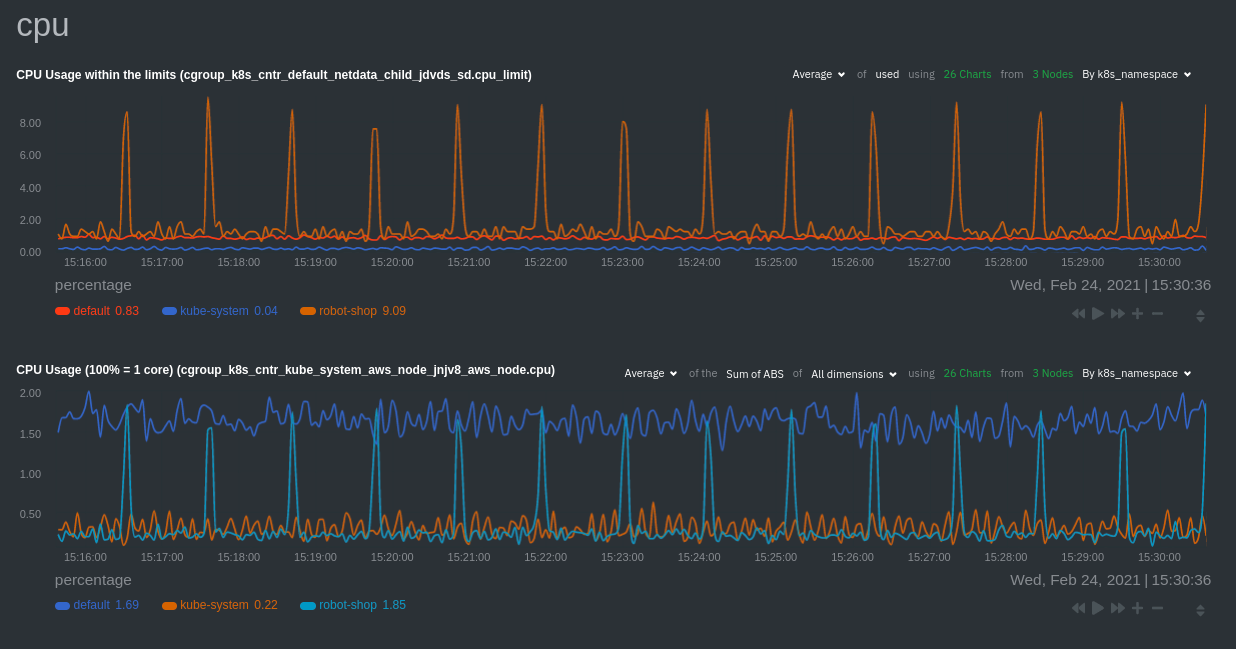
- covered by our [generic Prometheus
35
- collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/prometheus). With these
36
- configuration files, Netdata collects metrics from any compatible applications as they run _inside_ of a pod.
37
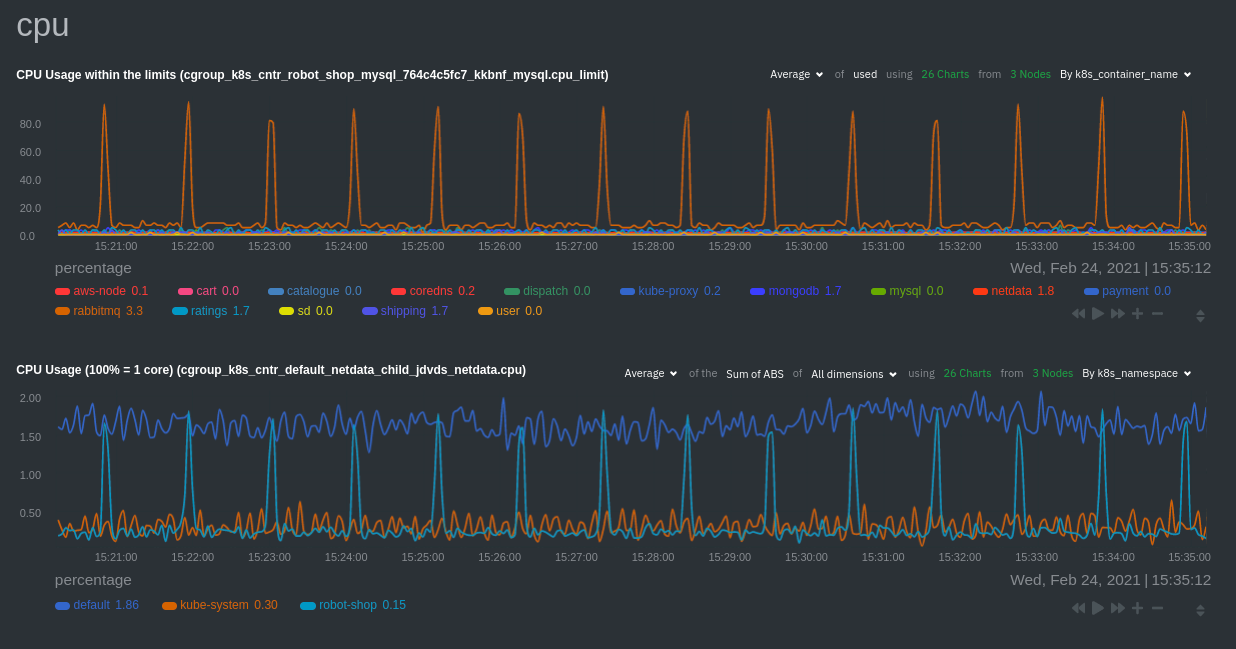
- Service discovery happens without manual intervention as pods are created, destroyed, or moved between nodes.
38
-- A [Kubelet collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/k8s_kubelet), which runs
39
- on each node in a k8s cluster to monitor the number of pods/containers, the volume of operations on each container,
40
- and more.
41
-- A [kube-proxy collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/k8s_kubeproxy), which
42
- also runs on each node and monitors latency and the volume of HTTP requests to the proxy.
43
-- A [cgroups collector](/collectors/cgroups.plugin/README.md), which collects CPU, memory, and bandwidth metrics for
44
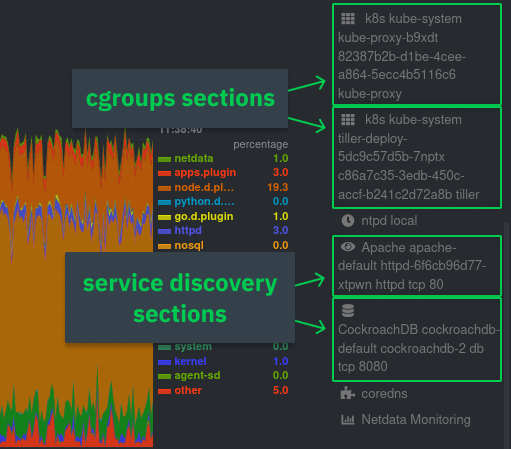
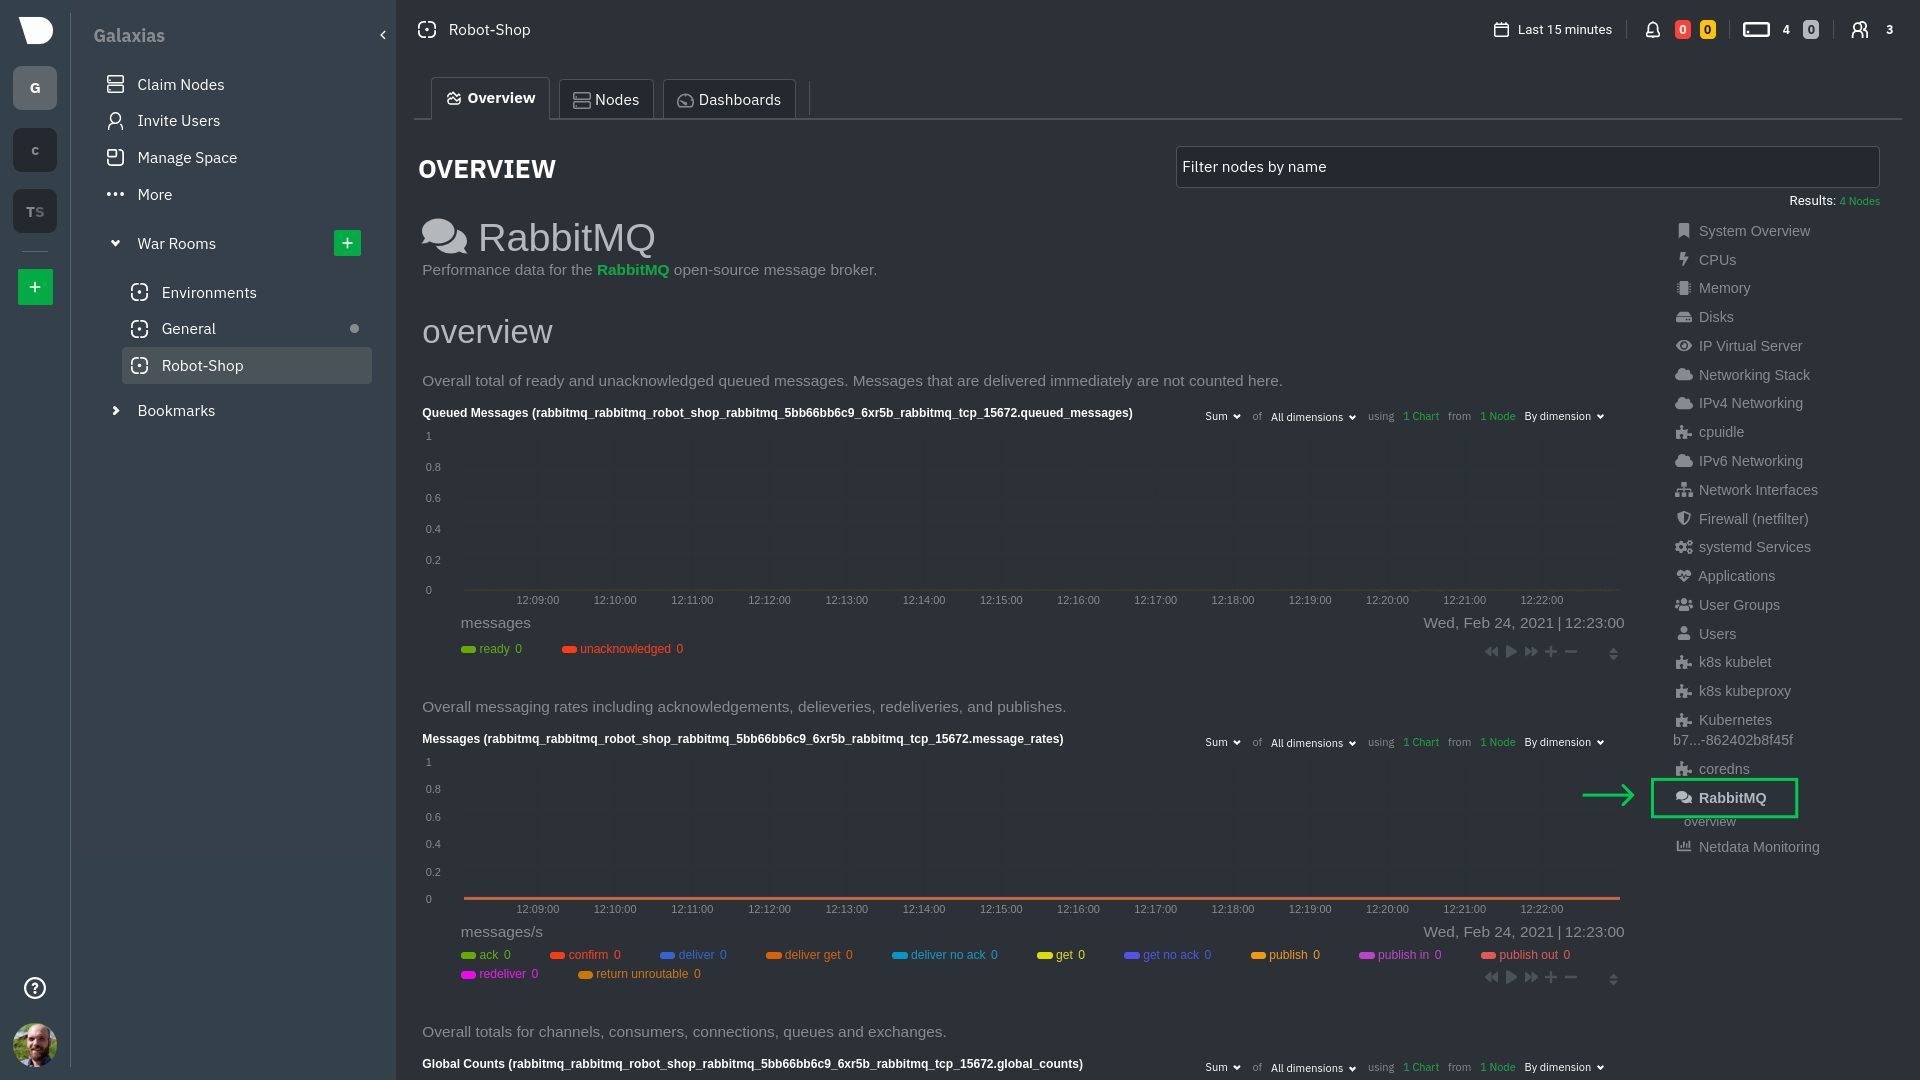
- each container running on your k8s cluster.
45
-
46
-By following this guide, you'll learn how to discover, explore, and take away insights from each of these layers in your
47
-Kubernetes cluster. Let's get started.
48
-
49
-## Prerequisites
50
-
51
-To follow this guide, you need:
52
-
53
-- A working cluster running Kubernetes v1.9 or newer.
54
-- The [kubectl](https://kubernetes.io/docs/reference/kubectl/overview/) command line tool, within [one minor version
35
+## Solution
36
+
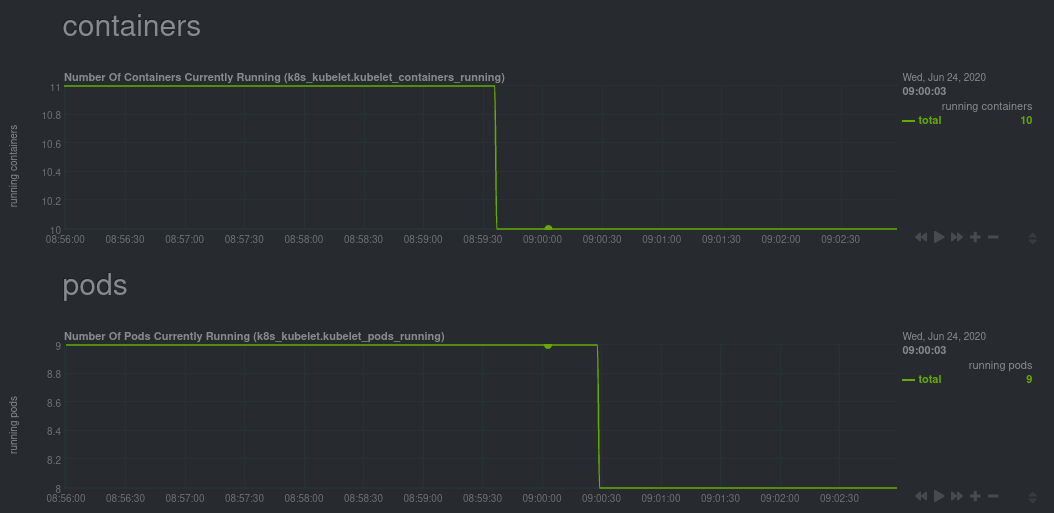
37
+In this tutorial, you'll learn how to navigate Netdata's Kubernetes monitoring features, using
38
+[robot-shop](https://github.com/instana/robot-shop) as an example deployment. Deploying robot-shop is purely optional.
39
+You can also follow along with your own Kubernetes deployment if you choose. While the metrics might be different, the
40
+navigation and best practices are the same for every cluster.
41
+
42
+## What you need to get started
43
+
44
+To follow this tutorial, you need:
45
+
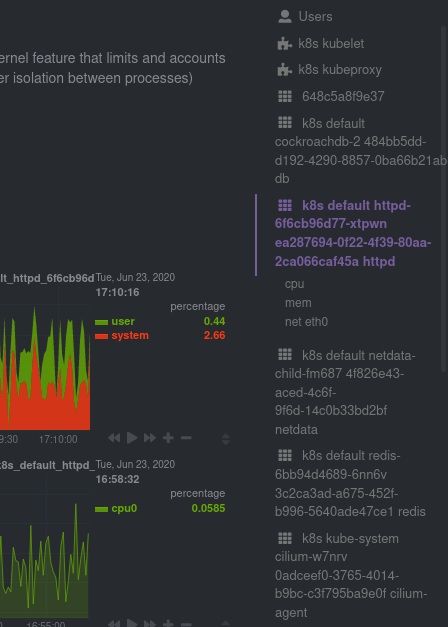
46
+- A free Netdata Cloud account. [Sign up](https://app.netdata.cloud/sign-up?cloudRoute=/spaces) if you don't have one
47
+ already.
48
+- A working cluster running Kubernetes v1.9 or newer, with a Netdata deployment and claimed parent/child nodes. See
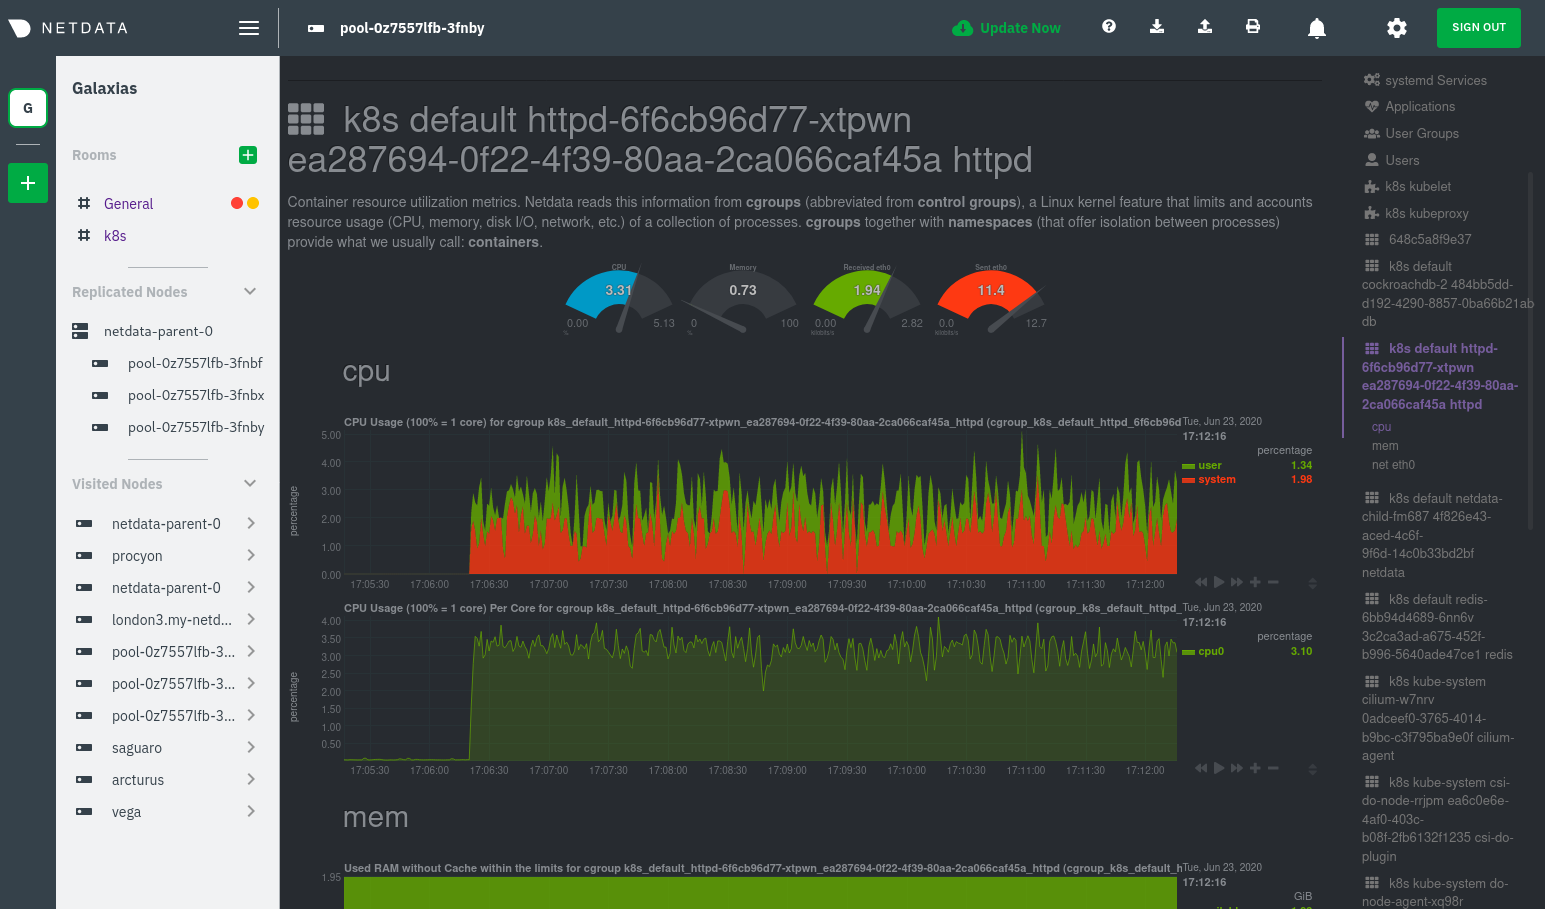
49
+ our [Kubernetes deployment process](/packaging/installer/methods/kubernetes.md) for details on deployment and
50
+ claiming.
51
+- The [`kubectl`](https://kubernetes.io/docs/reference/kubectl/overview/) command line tool, within [one minor version
52
difference](https://kubernetes.io/docs/tasks/tools/install-kubectl/#before-you-begin) of your cluster, on an
53
administrative system.
54
- The [Helm package manager](https://helm.sh/) v3.0.0 or newer on the same administrative system.
55
59
-**You need to install the Netdata Helm chart on your cluster** before you proceed. See our [Kubernetes installation
60
-process](/packaging/installer/methods/kubernetes.md) for details.
56
+### Install the `robot-shop` demo (optional)
57
62
-This guide uses a 3-node cluster, running on Digital Ocean, as an example. This cluster runs CockroachDB, Redis, and
63
-Apache, which we'll use as examples of how to monitor a Kubernetes cluster with Netdata.
58
+Begin by downloading the robot-shop code and using `helm` to create a new deployment.
59
60
```bash
66
-kubectl get nodes
67
-NAME STATUS ROLES AGE VERSION
68
-pool-0z7557lfb-3fnbf Ready <none> 51m v1.17.5
69
-pool-0z7557lfb-3fnbx Ready <none> 51m v1.17.5
70
-pool-0z7557lfb-3fnby Ready <none> 51m v1.17.5
71
-
72
-kubectl get pods
73
-NAME READY STATUS RESTARTS AGE
74
-cockroachdb-0 1/1 Running 0 44h
75
-cockroachdb-1 1/1 Running 0 44h
76
-cockroachdb-2 1/1 Running 1 44h
77
-cockroachdb-init-q7mp6 0/1 Completed 0 44h
78
-httpd-6f6cb96d77-4zlc9 1/1 Running 0 2m47s
79
-httpd-6f6cb96d77-d9gs6 1/1 Running 0 2m47s
80
-httpd-6f6cb96d77-xtpwn 1/1 Running 0 11m
81
-netdata-child-5p2m9 2/2 Running 0 42h
82
-netdata-child-92qvf 2/2 Running 0 42h
83
-netdata-child-djc6w 2/2 Running 0 42h
84
-netdata-parent-0 1/1 Running 0 42h
85
-redis-6bb94d4689-6nn6v 1/1 Running 0 73s
86
-redis-6bb94d4689-c2fk2 1/1 Running 0 73s
87
-redis-6bb94d4689-tjcz5 1/1 Running 0 88s
61
+git clone git@github.com:instana/robot-shop.git
62
+cd robot-shop/K8s/helm
63
+kubectl create ns robot-shop
64
+helm install robot-shop --namespace robot-shop .
65
```
66
90
-## Explore Netdata's Kubernetes charts
67
+Running `kubectl get pods` shows both the Netdata and robot-shop deployments.
68
92
-The Helm chart installs and enables everything you need for visibility into your k8s cluster, including the service
93
-discovery plugin, Kubelet collector, kube-proxy collector, and cgroups collector.
94
-
95
-To get started, open your browser and navigate to your cluster's Netdata dashboard. See our [Kubernetes installation
96
-instructions](/packaging/installer/methods/kubernetes.md) for how to access the dashboard based on your cluster's
97
-configuration.
98
-
99
-You'll see metrics from the parent pod as soon as you navigate to the dashboard:
100
-
101
-
103
-
104
-Remember that the parent pod is responsible for storing metrics from all the child pods and sending alarms.
69
+```bash
70
+kubectl get pods --all-namespaces
71
+NAMESPACE NAME READY STATUS RESTARTS AGE
72
+default netdata-child-29f9c 2/2 Running 0 10m
73
+default netdata-child-8xphf 2/2 Running 0 10m
74
+default netdata-child-jdvds 2/2 Running 0 11m
75
+default netdata-parent-554c755b7d-qzrx4 1/1 Running 0 11m
76
+kube-system aws-node-jnjv8 1/1 Running 0 17m
77
+kube-system aws-node-svzdb 1/1 Running 0 17m
78
+kube-system aws-node-ts6n2 1/1 Running 0 17m
79
+kube-system coredns-559b5db75d-f58hp 1/1 Running 0 22h
80
+kube-system coredns-559b5db75d-tkzj2 1/1 Running 0 22h
81
+kube-system kube-proxy-9p9cd 1/1 Running 0 17m
82
+kube-system kube-proxy-lt9ss 1/1 Running 0 17m
83
+kube-system kube-proxy-n75t9 1/1 Running 0 17m
84
+robot-shop cart-b4bbc8fff-t57js 1/1 Running 0 14m
85
+robot-shop catalogue-8b5f66c98-mr85z 1/1 Running 0 14m
86
+robot-shop dispatch-67d955c7d8-lnr44 1/1 Running 0 14m
87
+robot-shop mongodb-7f65d86c-dsslc 1/1 Running 0 14m
88
+robot-shop mysql-764c4c5fc7-kkbnf 1/1 Running 0 14m
89
+robot-shop payment-67c87cb7d-5krxv 1/1 Running 0 14m
90
+robot-shop rabbitmq-5bb66bb6c9-6xr5b 1/1 Running 0 14m
91
+robot-shop ratings-94fd9c75b-42wvh 1/1 Running 0 14m
92
+robot-shop redis-0 0/1 Pending 0 14m
93
+robot-shop shipping-7d69cb88b-w7hpj 1/1 Running 0 14m
94
+robot-shop user-79c445b44b-hwnm9 1/1 Running 0 14m
95
+robot-shop web-8bb887476-lkcjx 1/1 Running 0 14m
96
+```
97
106
-Take note of the **Replicated Nodes** menu, which shows not only the parent pod, but also the three child pods. This
107
-example cluster has three child pods, but the number of child pods depends entirely on the number of nodes in your
108
-cluster.
98
+## Explore Netdata's Kubernetes monitoring charts
99
110
-You'll use the links in the **Replicated Nodes** menu to navigate between the various pods in your cluster. Let's do
111
-that now to explore the pod-level Kubernetes monitoring Netdata delivers.
100
+The Netdata Helm chart deploys and enables everything you need for monitoring Kubernetes on every layer. Once you deploy
101
+Netdata and claim your cluster's nodes, you're ready to check out the visualizations **with zero configuration**.
102
113
-### Pods
103
+To get started, [sign in](https://app.netdata.cloud/sign-in?cloudRoute=/spaces) to your Netdata Cloud account. Head over
104
+to the War Room you claimed your cluster to, if not **General**.
105
115
-Click on any of the nodes under **netdata-parent-0**. Netdata redirects you to a separate instance of the Netdata
116
-dashboard, run by the Netdata child pod, which visualizes thousands of metrics from that node.
106
+Netdata Cloud is already visualizing your Kubernetes metrics, streamed in real-time from each node, in the
107
+[Overview](https://learn.netdata.cloud/docs/cloud/visualize/overview):
108
118
-
109
+
111
121
-From this dashboard, you can see all the familiar charts showing the health and performance of an individual node, just
122
-like you would if you installed Netdata on a single physical system. Explore CPU, memory, bandwidth, networking, and
123
-more.
112
+Let's walk through monitoring each layer of a Kubernetes cluster using the Overview as our framework.
113
125
-You can use the menus on the right-hand side of the dashboard to navigate between different sections of charts and
126
-metrics.
114
+## Cluster and node metrics
115
128
-For example, click on the **Applications** section to view per-application metrics, collected by
129
-[apps.plugin](/collectors/apps.plugin/README.md). The first chart you see is **Apps CPU Time (100% = 1 core)
130
-(apps.cpu)**, which shows the CPU utilization of various applications running on the node. You shouldn't be surprised to
131
-find Netdata processes (`netdata`, `sd-agent`, and more) alongside Kubernetes processes (`kubelet`, `kube-proxy`, and
132
-`containers`).
116
+The gauges and time-series charts you see right away in the Overview show aggregated metrics from every node in your
117
+cluster.
118
134
-
119
+For example, the `apps.cpu` chart (in the **Applications** menu item), visualizes the CPU utilization of various
120
+applications/services running on each of the nodes in your cluster. The **X Nodes** dropdown shows which nodes
121
+contribute to the chart and links to jump a single-node dashboard for further investigation.
122
137
-Beneath the **Applications** section, you'll begin to see sections for **k8s kubelet**, **k8s kubeproxy**, and long
138
-strings that start with **k8s**, which are sections for metrics collected by
139
-[`cgroups.plugin`](/collectors/cgroups.plugin/README.md). Let's skip over those for now and head further down to see
140
-Netdata's service discovery in action.
123
+
125
142
-### Service discovery (services running inside of pods)
126
+For example, the chart above shows a spike in the CPU utilization from `rabbitmq` every minute or so, along with a
127
+baseline CPU utilization of 10-15% across the cluster.
128
144
-Thanks to Netdata's service discovery feature, you monitor containerized applications running in k8s pods with zero
145
-configuration or manual intervention. Service discovery is like a watchdog for created or deleted pods, recognizing the
146
-service they run based on the image name and port and immediately attempting to apply a logical default configuration.
129
+Read about the [Overview](https://learn.netdata.cloud/docs/cloud/visualize/overview) and some best practices on [viewing
130
+an overview of your infrastructure](/docs/visualize/overview-infrastructure.md) for details on using composite charts to
131
+drill down into per-node performance metrics.
132
148
-Service configuration supports [popular
149
-applications](https://github.com/netdata/helmchart#service-discovery-and-supported-services), plus any endpoints covered
150
-by our [generic Prometheus collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/prometheus),
151
-which are automatically added or removed from Netdata as soon as the pods are created or destroyed.
133
+## Pod and container metrics
134
153
-You can find these service discovery sections near the bottom of the menu. The names for these sections follow a
154
-pattern: the name of the detected service, followed by a string of the module name, pod TUID, service type, port
155
-protocol, and port number. See the graphic below to help you identify service discovery sections.
135
+Click on the **Kubernetes xxxxxxx...** section to jump down to Netdata Cloud's unique Kubernetes visualizations for view
136
+real-time resource utilization metrics from your Kubernetes pods and containers.
137
157
-
138
+
140
160
-For example, the first service discovery section shows metrics for a pod running an Apache web server running on port 80
161
-in a pod named `httpd-6f6cb96d77-xtpwn`.
141
+### Health map
142
163
-> If you don't see any service discovery sections, it's either because your services are not compatible with service
164
-> discovery or you changed their default configuration, such as the listening port. See the [list of supported
165
-> services](https://github.com/netdata/helmchart#service-discovery-and-supported-services) for details about whether
166
-> your installed services are compatible with service discovery, or read the [configuration
167
-> instructions](/packaging/installer/methods/kubernetes.md#configure-service-discovery) to change how it discovers the
168
-> supported services.
143
+The first visualization is the [health map](https://learn.netdata.cloud/docs/cloud/visualize/kubernetes#health-map),
144
+which places each container into its own box, then varies the intensity of their color to visualize the resource
145
+utilization. By default, the health map shows the **average CPU utilization as a percentage of the configured limit**
146
+for every container in your cluster.
147
170
-Click on any of these service discovery sections to see metrics from that particular service. For example, click on the
171
-**Apache apache-default httpd-6f6cb96d77-xtpwn httpd tcp 80** section brings you to a series of charts populated by the
172
-[Apache collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/apache) itself.
148
+
150
174
-With service discovery, you can now see valuable metrics like requests, bandwidth, workers, and more for this pod.
151
+Let's explore the most colorful box by hovering over it.
152
176
-
153
+
155
179
-The same goes for metrics coming from the CockroachDB pod running on this same node.
156
+The **Context** tab shows `rabbitmq-5bb66bb6c9-6xr5b` as the container's image name, which means this container is
157
+running a [RabbitMQ](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/rabbitmq) workload.
158
181
-
159
+Click the **Metrics** tab to see real-time metrics from that container. Unsurprisingly, it shows a spike in CPU
160
+utilization at regular intervals.
161
184
-Service discovery helps you monitor the health of specific applications running on your Kubernetes cluster, which in
185
-turn gives you a complete resource when troubleshooting your infrastructure's health and performance.
162
+
164
187
-### Kubelet
165
+### Time-series charts
166
189
-Let's head back up the menu to the **k8s kubelet** section. Kubelet is an agent that runs on every node in a cluster. It
190
-receives a set of PodSpecs from the Kubernetes Control Plane and ensures the pods described there are both running and
191
-healthy. Think of it as a manager for the various pods on that node.
167
+Beneath the health map is a variety of time-series charts that help you visualize resource utilization over time, which
168
+is useful for targeted troubleshooting.
169
193
-Monitoring each node's Kubelet can be invaluable when diagnosing issues with your Kubernetes cluster. For example, you
194
-can see when the volume of running containers/pods has dropped.
170
+The default is to display metrics grouped by the `k8s_namespace` label, which shows resource utilization based on your
171
+different namespaces.
172
196
-
173
+
175
199
-This drop might signal a fault or crash in a particular Kubernetes service or deployment (see `kubectl get services` or
200
-`kubectl get deployments` for more details). If the number of pods increases, it may be because of something more
201
-benign, like another member of your team scaling up a service with `kubectl scale`.
176
+Each composite chart has a [definition bar](https://learn.netdata.cloud/docs/cloud/visualize/overview#definition-bar)
177
+for complete customization. For example, grouping the top chart by `k8s_container_name` reveals new information.
178
203
-You can also view charts for the Kubelet API server, the volume of runtime/Docker operations by type,
204
-configuration-related errors, and the actual vs. desired numbers of volumes, plus a lot more.
179
+
180
206
-Kubelet metrics are collected and visualized thanks to the [kubelet
207
-collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/k8s_kubelet), which is enabled with
208
-zero configuration on most Kubernetes clusters with standard configurations.
181
+## Service metrics
182
210
-### kube-proxy
183
+Netdata has a [service discovery plugin](https://github.com/netdata/agent-service-discovery), which discovers and
184
+creates configuration files for [compatible
185
+services](https://github.com/netdata/helmchart#service-discovery-and-supported-services) and any endpoints covered by
186
+our [generic Prometheus collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/prometheus).
187
+Netdata uses these files to collect metrics from any compatible application as they run _inside_ of a pod. Service
188
+discovery happens without manual intervention as pods are created, destroyed, or moved between nodes.
189
212
-Scroll down into the **k8s kubeproxy** section to see metrics about the network proxy that runs on each node in your
213
-Kubernetes cluster. kube-proxy allows for pods to communicate with each other and accept sessions from outside your
214
-cluster.
190
+Service metrics show up on the Overview as well, beneath the **Kubernetes** section, and are labeled according to the
191
+service in question. For example, the **RabbitMQ** section has numerous charts from the [`rabbitmq`
192
+collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/rabbitmq):
193
216
-With Netdata, you can monitor how often your k8s proxies are syncing proxy rules between nodes. Dramatic changes in
217
-these figures could indicate an anomaly in your cluster that's worthy of further investigation.
194
+
196
219
-kube-proxy metrics are collected and visualized thanks to the [kube-proxy
220
-collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/k8s_kubeproxy), which is enabled with
221
-zero configuration on most Kubernetes clusters with standard configurations.
197
+> The robot-shop cluster has more supported services, such as MySQL, which are not visible with zero configuration. This
198
+> is usually because of services running on non-default ports, using non-default names, or required passwords. Read up
199
+> on [configuring service discovery](/packaging/installer/methods/kubernetes.md#configure-service-discovery) to collect
200
+> more service metrics.
201
223
-### Containers
202
+Service metrics are essential to infrastructure monitoring, as they're the best indicator of the end-user experience,
203
+and key signals for troubleshooting anomalies or issues.
204
225
-We can finally talk about the final piece of Kubernetes monitoring: containers. Each Kubernetes pod is a set of one or
226
-more cooperating containers, sharing the same namespace, all of which are resourced and tracked by the cgroups feature
227
-of the Linux kernel. Netdata automatically detects and monitors each running container by interfacing with the cgroups
228
-feature itself.
205
+## Kubernetes components
206
230
-You can find these sections beneath **Users**, **k8s kubelet**, and **k8s kubeproxy**. Below, a number of containers
231
-devoted to running services like CockroachDB, Apache, Redis, and more.
207
+Netdata also automatically collects metrics from two essential Kubernetes processes.
208
233
-
209
+### kubelet
210
236
-Let's look at the section devoted to the container that runs the Apache pod named `httpd-6f6cb96d77-xtpwn`, as described
237
-in the previous part on [service discovery](#service-discovery-services-running-inside-of-pods).
211
+The **k8s kubelet** section visualizes metrics from the Kubernetes agent responsible for managing every pod on a given
212
+node. This also happens without any configuration thanks to the [kubelet
213
+collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/k8s_kubelet).
214
239
-
215
+Monitoring each node's kubelet can be invaluable when diagnosing issues with your Kubernetes cluster. For example, you
216
+can see if the number of running containers/pods has dropped, which could signal a fault or crash in a particular
217
+Kubernetes service or deployment (see `kubectl get services` or `kubectl get deployments` for more details). If the
218
+number of pods increases, it may be because of something more benign, like another team member scaling up a
219
+service with `kubectl scale`.
220
242
-At first glance, these sections might seem redundant. You might ask, "Why do I need both a service discovery section
243
-_and_ a container section? It's just one pod, after all!"
221
+You can also view charts for the Kubelet API server, the volume of runtime/Docker operations by type,
222
+configuration-related errors, and the actual vs. desired numbers of volumes, plus a lot more.
223
245
-The difference is that while the service discovery section shows _Apache_ metrics, the equivalent cgroups section shows
246
-that container's CPU, memory, and bandwidth usage. You can use the two sections in conjunction to monitor the health and
247
-performance of your pods and the services they run.
224
+### kube-proxy
225
249
-For example, let's say you get an alarm notification from `netdata-parent-0` saying the
250
-`ea287694-0f22-4f39-80aa-2ca066caf45a` container (also known as the `httpd-6f6cb96d77-xtpwn` pod) is using 99% of its
251
-available RAM. You can then hop over to the **Apache apache-default httpd-6f6cb96d77-xtpwn httpd tcp 80** section to
252
-further investigate why Apache is using an unexpected amount of RAM.
226
+The **k8s kube-proxy** section displays metrics about the network proxy that runs on each node in your Kubernetes
227
+cluster. kube-proxy lets pods communicate with each other and accept sessions from outside your cluster. Its metrics are
228
+collected by the [kube-proxy
229
+collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/k8s_kubeproxy).
230
254
-All container metrics, whether they're managed by Kubernetes or the Docker service directly, are collected by the
255
-[cgroups collector](/collectors/cgroups.plugin/README.md). Because this collector integrates with the cgroups Linux
256
-kernel feature itself, monitoring containers requires zero configuration on most Kubernetes clusters.
231
+With Netdata, you can monitor how often your k8s proxies are syncing proxy rules between nodes. Dramatic changes in
232
+these figures could indicate an anomaly in your cluster that's worthy of further investigation.
233
234
## What's next?
235
260
-After following this guide, you should have a more comprehensive understanding of how to monitor your Kubernetes cluster
261
-with Netdata. With this setup, you can monitor the health and performance of all your nodes, pods, services, and k8s
262
-agents. Pre-configured alarms will tell you when something goes awry, and this setup gives you every per-second metric
263
-you need to make informed decisions about your cluster.
236
+After reading this guide, you should now be able to monitor any Kubernetes cluster with Netdata, including nodes, pods,
237
+containers, services, and more.
238
265
-The best part of monitoring a Kubernetes cluster with Netdata is that you don't have to worry about constantly running
266
-complex `kubectl` commands to see hundreds of highly granular metrics from your nodes. And forget about using `kubectl
267
-exec -it pod bash` to start up a shell on a pod to find and diagnose an issue with any given pod on your cluster.
239
+With the health map, time-series charts, and the ability to drill down into individual nodes, you can see hundreds of
240
+per-second metrics with zero configuration and less time remembering all the `kubectl` options. Netdata moves with your
241
+cluster, automatically picking up new nodes or services as your infrastructure scales. And it's entirely free for
242
+clusters of all sizes.
243
269
-And with service discovery, all your compatible pods will automatically appear and disappear as they scale up, move, or
270
-scale down across your cluster.
244
+### Related reference documentation
245
272
-To monitor your Kubernetes cluster with Netdata, start by [installing the Helm
273
-chart](/packaging/installer/methods/kubernetes.md) if you haven't already. The Netdata Agent is open source and entirely
274
-free for every cluster and every organization, whether you have 10 or 10,000 pods. A few minutes and one `helm install`
275
-later and you'll have started on the path of building an effective platform for troubleshooting the next performance or
276
-availability issue on your Kubernetes cluster.
246
+- [Netdata Helm chart](https://github.com/netdata/helmchart)
247
+- [Netdata service discovery](https://github.com/netdata/agent-service-discovery)
248
+- [Netdata Agent · `kubelet`
249
+ collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/k8s_kubelet)
250
+- [Netdata Agent · `kube-proxy`
251
+ collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/k8s_kubeproxy)
252
+- [Netdata Agent · `cgroups.plugin`](/collectors/cgroups.plugin/README.md)
253
254
[](<>)
docs/guides/monitor/visualize-monitor-anomalies.md
-3
@@ -136,9 +136,6 @@ unsupervised anomaly detection, or would like to see something added to it. You
136
that works well for monitoring some other popular application, like MySQL, PostgreSQL, Redis, or anything else we
137
[support through collectors](/collectors/COLLECTORS.md).
138
139
-In part 3 of this series on unsupervised anomaly detection using Netdata, we'll create a custom model to apply
140
-unsupervised anomaly detection to an entire mission-critical application. Stay tuned!
141
-
139
### Related reference documentation
140
141
- [Netdata Agent · Anomalies collector](/collectors/python.d.plugin/anomalies/README.md)
docs/visualize/overview-infrastructure.md
+12
-3
@@ -14,6 +14,9 @@ With Overview's composite charts, you can see your infrastructure from a single
14
anomalies, then drill down with filtering or single-node dashboards to see more. In the screenshot below,
15
each chart visualizes average or sum metrics values from across 5 distributed nodes.
16
17
+Netdata also supports robust Kubernetes monitoring using the Overview. Read our [deployment
18
+doc](/packaging/installer/methods/kubernetes.md) for details on visualizing Kubernetes metrics in Netdata Cloud.
19
+
20
22
@@ -93,10 +96,16 @@ To troubleshoot complex performance issues using Netdata, you need to understand
96
visualizations. Learn more about [interaction](/docs/visualize/interact-dashboards-charts.md) to see historical metrics,
97
highlight timeframes for targeted analysis, and more.
98
99
+If you're a Kubernetes user, read about Netdata's [Kubernetes
100
+visualizations](https://learn.netdata.cloud/docs/cloud/visualize/kubernetes) for details about the health map and
101
+time-series k8s charts, and our tutorial, [_Kubernetes monitoring with Netdata: Overview and
102
+visualizations_](/docs/guides/monitor/kubernetes-k8s-netdata.md), for a full walkthrough.
103
+
104
### Related reference documentation
105
98
-- [Netdata Cloud · War Rooms](https://learn.netdata.cloud/docs/cloud/war-rooms)
99
-- [Netdata Cloud · Overview](https://learn.netdata.cloud/docs/cloud/visualize/overview)
100
-- [Netdata Cloud · Nodes view](https://learn.netdata.cloud/docs/cloud/visualize/nodes)
106
+- [Netdata Cloud · War Rooms](https://learn.netdata.cloud/docs/cloud/war-rooms)
107
+- [Netdata Cloud · Overview](https://learn.netdata.cloud/docs/cloud/visualize/overview)
108
+- [Netdata Cloud · Nodes view](https://learn.netdata.cloud/docs/cloud/visualize/nodes)
109
+- [Netdata Cloud · Kubernetes visualizations](https://learn.netdata.cloud/docs/cloud/visualize/kubernetes)
110
111
[](<>)
packaging/installer/methods/kubernetes.md
+11
-10
@@ -41,7 +41,7 @@ dashboards available in Netdata Cloud.
41
42
## Claim your Kubernetes cluster to Netdata Cloud
43
44
-To start [Kubernetes monitoring](https://learn.netdata.cloud/docs/cloud/visualizations/kubernetes/), you must first
44
+To start [Kubernetes monitoring](https://learn.netdata.cloud/docs/cloud/visualize/kubernetes/), you must first
45
[claim](/claim/README.md) your Kubernetes cluster to [Netdata Cloud](https://app.netdata.cloud). Claiming securely
46
connects your Kubernetes cluster to stream metrics data to Netdata Cloud, enabling Kubernetes-specific visualizations
47
like the health map and time-series composite charts.
@@ -107,7 +107,7 @@ Read up on the various configuration options in the [Helm chart
107
documentation](https://github.com/netdata/helmchart#configuration) if you need to tweak your Kubernetes monitoring.
108
109
Your first option is to create an `override.yml` file, if you haven't created one already for
110
-[claim](#claim-your-kubernetes-cluster-to-netdata-cloud), then apply the new configuration to your cluster with `helm
110
+[claiming](#claim-your-kubernetes-cluster-to-netdata-cloud), then apply the new configuration to your cluster with `helm
111
upgrade`.
112
113
```bash
@@ -123,9 +123,9 @@ helm upgrade --set parent.database.volumesize=4Gi netdata netdata/netdata
123
124
### Configure service discovery
125
126
-Netdata's [service discovery](https://github.com/netdata/agent-service-discovery/#service-discovery), which is
127
-installed as part of the Helm chart installation, finds what services are running on a cluster's pods, converts that
128
-into configuration files, and exports them so they can be monitored.
126
+Netdata's [service discovery](https://github.com/netdata/agent-service-discovery/#service-discovery), installed as part
127
+of the Helm chart installation, finds what services are running in a cluster's containers and automatically collects
128
+service-level metrics from them.
129
130
Service discovery supports [popular applications](https://github.com/netdata/helmchart#applications) and [Prometheus
131
endpoints](https://github.com/netdata/helmchart#prometheus-endpoints).
@@ -171,16 +171,17 @@ helm upgrade netdata netdata/netdata
171
172
## What's next?
173
174
-[Start Kubernetes monitoring](https://learn.netdata.cloud/docs/cloud/visualizations/kubernetes/) in Netdata Cloud, which
174
+[Start Kubernetes monitoring](https://learn.netdata.cloud/docs/cloud/visualize/kubernetes/) in Netdata Cloud, which
175
comes with meaningful visualizations out of the box.
176
177
-Read our guide, [_Kubernetes monitoring with Netdata_](/docs/guides/monitor/kubernetes-k8s-netdata.md), for a complete
178
-walkthrough of Netdata's Kubernetes monitoring capabilities, including a health map of every container in your
179
-infrastructure, aggregated resource utilization metrics, and application metrics.
177
+Read our guide, [_Kubernetes monitoring with Netdata: Overview and
178
+visualizations_](/docs/guides/monitor/kubernetes-k8s-netdata.md), for a complete walkthrough of Netdata's Kubernetes
179
+monitoring capabilities, including a health map of every container in your infrastructure, aggregated resource
180
+utilization metrics, and application metrics.
181
182
### Related reference documentation
183
183
-- [Netdata Cloud · Kubernetes monitoring](https://learn.netdata.cloud/docs/cloud/visualizations/kubernetes/)
184
+- [Netdata Cloud · Kubernetes monitoring](https://learn.netdata.cloud/docs/cloud/visualize/kubernetes/)
185
- [Netdata Helm chart](https://github.com/netdata/helmchart)
186
- [Netdata service discovery](https://github.com/netdata/agent-service-discovery/)
187