@cryptotaxi247 / netdata-1 / commits / 61d7e23ee

Add docsv2 project to master branch (#10000)

* Add overview docs to docsv2 project * Add quickstart docs to docsv2 project (#9865) * Init quickstart docs * Begin work on quickstart guides * Finish quickstart drafts * Tweaks to both quickstarts * Add titles * Copyedit pass to both docs * Fixes for Amy and Jen * Add Get doc to docsv2 project (#9854) * Init get file * Add some links * Change h2 to h1 * Rephrase * Add configure docs to docsv2 project (#9878) * Add overview docs to docsv2 project (#9849) * Init files * Add drafts of what and why * Finish initial drafts * Fix edit URL * Copyedit pass * Finish initial drafts of configure docs * Copyedit all docs * Fixes for Amy * Fixes for Jen * Add collect docs to the docsv2 project (#9932) * Init files * Finish first two collect docs * Finish drafts of collect docs * Copyedit pass * Fixes for Amy * Fix for Jen * Add visualize docs to the docsv2 project (#9943) * Add visualize docs * Copyedits and cleanup * New images and features * Copyedit pass and cleanup * Missing word * Fixes for Jen * Add monitor docs to docsv2 project (#9949) * Finish drafts of monitor docs * Copyedit pass * Remove whitespace * Fixes for Jen * Add store docs to docsv2 project (#9969) * Finalize store documents * Fix import path * Finishing edit section * Copyedit pass * Add export docs to docsv2 project (#9986) * Add install and claim videos to Get doc * Finish drafts of exporting docs plus other tweaks * Init new exporting READMEs * Copyedit pass and new links * Fixes for Amy, Vlad, Jen * Fix links in docsv2 project (#9993) * Fix links * Fix a bunch of links ahead of export merge * Fix additional links * Fix links, nuke what-is-netdata * Fixing a few last links * Improve product images in overview * Remove extra paren * Quick tweaks for Jen * Fixes for Jen * Access fix * Remove extra word

Joel Hans committed Sep 29, 2020 at 10:57 UTC 61d7e23eed0503bf591274df70713970213b5c7f
38 files changed +2392 -628
backends/README.md
+1 -2
@@ -7,8 +7,7 @@ custom_edit_url: https://github.com/netdata/netdata/edit/master/backends/README.
7
8 # Metrics long term archiving
9
10 -> ⚠️ The backends system is now deprecated in favor of the [exporting engine](/exporting/README.md). Please see the
11 -> [migration guide](/docs/export/) for details on how to get started with exporting.
10 +> ⚠️ The backends system is now deprecated in favor of the [exporting engine](/exporting/README.md).
11
12 Netdata supports backends for archiving the metrics, or providing long term dashboards, using Grafana or other tools,
13 like this:
database/engine/README.md
+9 -8
@@ -44,9 +44,9 @@ section for details.
44
45 The `dbengine multihost disk space` option determines the amount of disk space in **MiB** that is dedicated to storing
46 Netdata metric values and all related metadata describing them. You can use the [**database engine
47 -calculator**](https://learn.netdata.cloud/docs/agent/database/calculator) to correctly set `dbengine multihost disk
48 -space` based on your metrics retention policy. The calculator gives an accurate estimate based on how many child nodes
49 -you have, how many metrics your Agent collects, and more.
47 +calculator**](/docs/store/change-metrics-storage.md#calculate-the-system-resources-RAM-disk-space-needed-to-store-metrics)
48 +to correctly set `dbengine multihost disk space` based on your metrics retention policy. The calculator gives an
49 +accurate estimate based on how many child nodes you have, how many metrics your Agent collects, and more.
50
51 ### Legacy configuration
52
@@ -62,9 +62,9 @@ Netdata metric values per legacy database engine instance (see [details on the l
62
63 When using the multihost database engine, all parent and child nodes share the same `page cache size` and `dbengine
64 multihost disk space` in a single dbengine instance. The [**database engine
65 -calculator**](https://learn.netdata.cloud/docs/agent/database/calculator) helps you properly set `page cache size` and
66 -`dbengine multihost disk space` on your parent node to allocate enough resources based on your metrics retention policy
67 -and how many child nodes you have.
65 +calculator**](/docs/store/change-metrics-storage.md#calculate-the-system-resources-RAM-disk-space-needed-to-store-metrics)
66 +helps you properly set `page cache size` and `dbengine multihost disk space` on your parent node to allocate enough
67 +resources based on your metrics retention policy and how many child nodes you have.
68
69 #### Legacy mode
70
@@ -111,8 +111,9 @@ There are explicit memory requirements **per** DB engine **instance**:
111 An important observation is that RAM usage depends on both the `page cache size` and the `dbengine multihost disk space`
112 options.
113
114 -You can use our [database engine calculator](https://learn.netdata.cloud/docs/agent/database/calculator) to
115 -validate the memory requirements for your particular system(s) and configuration (**out-of-date**).
114 +You can use our [database engine
115 +calculator](/docs/store/change-metrics-storage.md#calculate-the-system-resources-RAM-disk-space-needed-to-store-metrics)
116 +to validate the memory requirements for your particular system(s) and configuration (**out-of-date**).
117
118 ### Disk space requirements
119
docs/collect/application-metrics.md new
+76
@@ -0,0 +1,76 @@
1 +<!--
2 +title: "Collect application metrics with Netdata"
3 +sidebar_label: "Application metrics"
4 +description: "Monitor and troubleshoot every application on your infrastructure with per-second metrics, zero configuration, and meaningful charts."
5 +custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/collect/application-metrics.md
6 +-->
7 +
8 +# Collect application metrics with Netdata
9 +
10 +Netdata instantly collects per-second metrics from many different types of applications running on your systems, such as
11 +web servers, databases, message brokers, email servers, search platforms, and much more. Metrics collectors are
12 +pre-installed with every Netdata Agent and usually require zero configuration. Netdata also collects and visualizes
13 +resource utilization per application on Linux systems using `apps.plugin`.
14 +
15 +[**apps.plugin**](/collectors/apps.plugin/README.md) looks at the Linux process tree every second, much like `top` or
16 +`ps fax`, and collects resource utilization information on every running process. By reading the process tree, Netdata
17 +shows CPU, disk, networking, processes, and eBPF for every application or Linux user. Unlike `top` or `ps fax`, Netdata
18 +adds a layer of meaningful visualization on top of the process tree metrics, such as grouping applications into useful
19 +dimensions, and then creates per-application charts under the **Applications** section of a Netdata dashboard, per-user
20 +charts under **Users**, and per-user group charts under **User Groups**.
21 +
22 +Our most popular application collectors:
23 +
24 +- [Prometheus endpoints](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/prometheus): Gathers
25 + metrics from one or more Prometheus endpoints that use the OpenMetrics exposition format. Autodetects more than 600
26 + endpoints.
27 +- [Web server logs (Apache, NGINX)](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/weblog/):
28 + Tail access logs and provide very detailed web server performance statistics. This module is able to parse 200k+
29 + rows in less than half a second.
30 +- [MySQL](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/mysql/): Collect database global,
31 + replication, and per-user statistics.
32 +- [Redis](/collectors/python.d.plugin/redis/): Monitor database status by reading the server's response to the `INFO`
33 + command.
34 +- [Apache](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/apache/): Collect Apache web
35 + server performance metrics via the `server-status?auto` endpoint.
36 +- [Nginx](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/nginx/): Monitor web server
37 + status information by gathering metrics via `ngx_http_stub_status_module`.
38 +- [Postgres](/collectors/python.d.plugin/postgres/README.md): Collect database health and performance metrics.
39 +- [ElasticSearch](/collectors/python.d.plugin/elasticsearch/README.md): Collect search engine performance and health
40 + statistics. Optionally collects per-index metrics.
41 +- [PHP-FPM](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/phpfpm/): Collect application
42 + summary and processes health metrics by scraping the status page (`/status?full`).
43 +
44 +Our [supported collectors list](/collectors/COLLECTORS.md#service-and-application-collectors) shows all Netdata's
45 +application metrics collectors, including those for containers/k8s clusters.
46 +
47 +## Collect metrics from applications running on Windows
48 +
49 +Netdata is fully capable of collecting and visualizing metrics from applications running on Windows systems. The only
50 +caveat is that you must [install the Agent](/docs/get/README.md) on a separate system or a compatible VM because there
51 +is no native Windows version of the Netdata Agent.
52 +
53 +Once you have the Agent running on that separate system, you can follow the [enable and configure
54 +doc](/docs/collect/enable-configure.md) to tell the collector to look for exposed metrics on the Windows system's IP
55 +address or hostname, plus the applicable port.
56 +
57 +For example, you have a MySQL database with a root password of `my-secret-pw` running on a Windows system with the IP
58 +address 203.0.113.0. you can configure the [MySQL
59 +collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/mysql) to look at `203.0.113.0:3306`:
60 +
61 +```yml
62 +jobs:
63 + - name: local
64 + dsn: root:my-secret-pw@tcp(203.0.113.0:3306)/
65 +```
66 +
67 +This same logic applies to any application in our [supported collectors
68 +list](/collectors/COLLECTORS.md#service-and-application-collectors) that can run on Windows.
69 +
70 +## What's next?
71 +
72 +Collecting all the available metrics on your nodes, and across your entire infrastructure, is just one piece of the
73 +puzzle. Next, learn more about Netdata's famous real-time visualizations by [viewing all your nodes at a
74 +glance](/docs/visualize/view-all-nodes.md).
75 +
76 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fdocs%2Fcollect%2Fapplication-metrics&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
docs/collect/container-metrics.md new
+97
@@ -0,0 +1,97 @@
1 +<!--
2 +title: "Collect container metrics with Netdata"
3 +sidebar_label: "Container metrics"
4 +description: "Use Netdata to collect per-second utilization and application-level metrics from Linux/Docker containers and Kubernetes clusters."
5 +custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/collect/container-metrics.md
6 +-->
7 +
8 +# Collect container metrics with Netdata
9 +
10 +Thanks to close integration with Linux cgroups and the virtual files it maintains under `/sys/fs/cgroup`, Netdata can
11 +monitor the health, status, and resource utilization of many different types of Linux containers.
12 +
13 +Netdata uses [cgroups.plugin](/collectors/cgroups.plugin/README.md) to poll `/sys/fs/cgroup` and convert the raw data
14 +into human-readable metrics and meaningful visualizations. Through cgroups, Netdata is compatible with **all Linux
15 +containers**, such as Docker, LXC, LXD, Libvirt, systemd-nspawn, and more. Read more about [Docker-specific
16 +monitoring](#collect-docker-metrics) below.
17 +
18 +Netdata also has robust **Kubernetes monitoring** support thanks to a
19 +[Helmchart](/packaging/installer/methods/kubernetes.md) to automate deployment, collectors for k8s agent services, and
20 +robust [service discovery](https://github.com/netdata/agent-service-discovery/#service-discovery) to monitor the
21 +services running inside of pods in your k8s cluster. Read more about [Kubernetes
22 +monitoring](#collect-kubernetes-metrics) below.
23 +
24 +A handful of additional collectors gather metrics from container-related services, such as
25 +[dockerd](/collectors/python.d.plugin/dockerd/README.md) or [Docker
26 +Engine](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/docker_engine/). You can find all
27 +container collectors in our supported collectors list under the
28 +[containers/VMs](/collectors/COLLECTORS.md#containers-and-vms) and
29 +[Kubernetes](/collectors/COLLECTORS.md#containers-and-vms) headings.
30 +
31 +## Collect Docker metrics
32 +
33 +Netdata has robust Docker monitoring thanks to the aforementioned
34 +[cgroups.plugin](/collectors/cgroups.plugin/README.md). By polling cgroups every second, Netdata can produce meaningful
35 +visualizations about the CPU, memory, disk, and network utilization of all running containers on the host system with
36 +zero configuration.
37 +
38 +Netdata also collects metrics from applications running inside of Docker containers. For example, if you create a MySQL
39 +database container using `docker run --name some-mysql -e MYSQL_ROOT_PASSWORD=my-secret-pw -d mysql:tag`, it exposes
40 +metrics on port 3306. You can configure the [MySQL
41 +collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/mysql) to look at `127.0.0.0:3306` for
42 +MySQL metrics:
43 +
44 +```yml
45 +jobs:
46 + - name: local
47 + dsn: root:my-secret-pw@tcp(127.0.0.1:3306)/
48 +```
49 +
50 +Netdata then collects metrics from the container itself, but also dozens [MySQL-specific
51 +metrics](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/mysql#charts) as well.
52 +
53 +### Collect metrics from applications running in Docker containers
54 +
55 +You could use this technique to monitor an entire infrastructure of Docker containers. The same [enable and
56 +configure](/docs/collect/enable-configure.md) procedures apply whether an application runs on the host system or inside
57 +a container. You may need to configure the target endpoint if it's not the application's default.
58 +
59 +Netdata can even [run in a Docker container](/packaging/docker/README.md) itself, and then collect metrics about the
60 +host system, its own container with cgroups, and any applications you want to monitor.
61 +
62 +See our [application metrics doc](/docs/collect/application-metrics.md) for details about Netdata's application metrics
63 +collection capabilities.
64 +
65 +## Collect Kubernetes metrics
66 +
67 +We already have a few complementary tools and collectors for monitoring the many layers of a Kubernetes cluster,
68 +_entirely for free_. These methods work together to help you troubleshoot performance or availablility issues across
69 +your k8s infrastructure.
70 +
71 +- A [Helm chart](https://github.com/netdata/helmchart), which bootstraps a Netdata Agent pod on every node in your
72 + cluster, plus an additional parent pod for storing metrics and managing alarm notifications.
73 +- A [service discovery plugin](https://github.com/netdata/agent-service-discovery), which discovers and immediately
74 + monitors 22 different services that might be running inside of your cluster's pods. Service discovery happens
75 + without manual intervention as pods are created, destroyed, or moved between nodes. [Compatible
76 + services](https://github.com/netdata/helmchart#service-discovery-and-supported-services) include Nginx, Apache,
77 + MySQL, CoreDNS, and much more.
78 +- A [Kubelet collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/k8s_kubelet), which runs
79 + on each node in a k8s cluster to monitor the number of pods/containers, the volume of operations on each container,
80 + and more.
81 +- A [kube-proxy collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/k8s_kubeproxy), which
82 + also runs on each node and monitors latency and the volume of HTTP requests to the proxy.
83 +- A [cgroups collector](/collectors/cgroups.plugin/README.md), which collects CPU, memory, and bandwidth metrics for
84 + each container running on your k8s cluster.
85 +
86 +For a holistic view of Netdata's Kubernetes monitoring capabilities, see our guide: [_Monitor a Kubernetes (k8s) cluster
87 +with Netdata_](https://learn.netdata.cloud/guides/monitor/kubernetes-k8s-netdata).
88 +
89 +## What's next?
90 +
91 +Netdata is capable of collecting metrics from hundreds of applications, such as web servers, databases, messaging
92 +brokers, and more. See more in the [application metrics doc](/docs/collect/application-metrics.md).
93 +
94 +If you already have all the information you need about collecting metrics, move into Netdata's meaningful visualizations
95 +with [viewing all nodes at a glance](/docs/visualize/view-all-nodes.md).
96 +
97 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fdocs%2Fcollect%2Fcontainer-metrics&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
docs/collect/enable-configure.md new
+65
@@ -0,0 +1,65 @@
1 +<!--
2 +title: "Enable or configure a collector"
3 +description: "Every collector is highly configurable, allowing them to collect metrics from any node and any infrastructure."
4 +custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/collect/enable-configure.md
5 +-->
6 +
7 +# Enable or configure a collector
8 +
9 +When Netdata starts up, each collector searches for exposed metrics on the default endpoint established by that service
10 +or application's standard installation procedure. For example, the [Nginx
11 +collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/nginx) searches at
12 +`http://127.0.0.1/stub_status` for exposed metrics in the correct format. If an Nginx web server is running and exposes
13 +metrics on that endpoint, the collector begins gathering them.
14 +
15 +However, not every node or infrastructure uses standard ports, paths, files, or naming conventions. You may need to
16 +enable or configure a collector to gather all available metrics from your systems, containers, or applications.
17 +
18 +## Enable a collector or its orchestrator
19 +
20 +You can enable/disable collectors individually, or enable/disable entire orchestrators, using their configuration files.
21 +For example, you can change the behavior of the Go orchestator, or any of its collectors, by editing `go.d.conf`.
22 +
23 +Use `edit-config` from your [Netdata config directory](/docs/configure/nodes.md#the-netdata-config-directory) to open
24 +the orchestrator's primary configuration file:
25 +
26 +```bash
27 +cd /etc/netdata
28 +sudo ./edit-config go.d.conf
29 +```
30 +
31 +Within this file, you can either disable the orchestrator entirely (`enabled: yes`), or find a specific collector and
32 +enable/disable it with `yes` and `no` settings. Uncomment any line you change to ensure the Netdata deamon reads it on
33 +start.
34 +
35 +After you make your changes, restart the Agent with `service netdata restart`.
36 +
37 +## Configure a collector
38 +
39 +First, [find the collector](/collectors/COLLECTORS.md) you want to edit and open its documentation. Some software has
40 +collectors written in multiple languages. In these cases, you should always pick the collector written in Go.
41 +
42 +Use `edit-config` from your [Netdata config directory](/docs/configure/nodes.md#the-netdata-config-directory) to open a
43 +collector's configuration file. For example, edit the Nginx collector with the following:
44 +
45 +```bash
46 +./edit-config go.d/nginx.conf
47 +```
48 +
49 +Each configuration file describes every available option and offers examples to help you tweak Netdata's settings
50 +according to your needs. In addition, every collector's documentation shows the exact command you need to run to
51 +configure that collector. Uncomment any line you change to ensure the collector's orchestrator or the Netdata daemon
52 +read it on start.
53 +
54 +After you make your changes, restart the Agent with `service netdata restart`.
55 +
56 +## What's next?
57 +
58 +Read high-level overviews on how Netdata collects [system metrics](/docs/collect/system-metrics.md), [container
59 +metrics](/docs/collect/container-metrics.md), and [application metrics](/docs/collect/application-metrics.md).
60 +
61 +If you're already collecting all metrics from your systems, containers, and applications, it's time to move into
62 +Netdata's visualization features. [View all your nodes at a glance](/docs/visualize/view-all-nodes.md) or learn how to
63 +[interact with dashboards and charts](/docs/visualize/interact-dashboards-charts.md).
64 +
65 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fdocs%2Fcollect%2Fenable-configure&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
docs/collect/how-collectors-work.md new
+80
@@ -0,0 +1,80 @@
1 +<!--
2 +title: "How Netdata's metrics collectors work"
3 +description: "When Netdata starts, and with zero configuration, it auto-detects thousands of data sources and immediately collects per-second metrics."
4 +custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/collect/how-collectors-work.md
5 +-->
6 +
7 +# How Netdata's metrics collectors work
8 +
9 +When Netdata starts, and with zero configuration, it auto-detects thousands of data sources and immediately collects
10 +per-second metrics.
11 +
12 +Netdata can immediately collect metrics from these endpoints thanks to 300+ **collectors**, which all come pre-installed
13 +when you [install the Netdata Agent](/docs/get/README.md#install-the-netdata-agent).
14 +
15 +Every collector has two primary jobs:
16 +
17 +- Look for exposed metrics at a pre- or user-defined endpoint.
18 +- Gather exposed metrics and use additional logic to build meaningful, interactive visualizations.
19 +
20 +If the collector finds compatible metrics exposed on the configured endpoint, it begins a per-second collection job. The
21 +Netdata Agent gathers these metrics, sends them to the [database engine for
22 +storage](/docs/store/change-metrics-storage.md), and immediately [visualizes them
23 +meaningfully](/docs/visualize/interact-dashboards-charts.md) on dashboards.
24 +
25 +Each collector comes with a pre-defined configuration that matches the default setup for that application. This endpoint
26 +can be a URL and port, a socket, a file, a web page, and more.
27 +
28 +For example, the [Nginx collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/nginx) searches
29 +at `http://127.0.0.1/stub_status`, which is the default endpoint for exposing Nginx metrics. The [web log collector for
30 +Nginx or Apache](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/weblog) searches at
31 +`/var/log/nginx/access.log` and `/var/log/apache2/access.log`, respectively, both of which are standard locations for
32 +access log files on Linux systems.
33 +
34 +The endpoint is user-configurable, as are many other specifics of what a given collector does.
35 +
36 +## What can Netdata collect?
37 +
38 +To quickly find your answer, see our [list of supported collectors](/collectors/COLLECTORS.md).
39 +
40 +Generally, Netdata's collectors can be grouped into three types:
41 +
42 +- [Systems](/docs/collect/system-metrics.md): Monitor CPU, memory, disk, networking, systemd, eBPF, and much more.
43 + Every metric exposed by `/proc`, `/sys`, and other Linux kernel sources.
44 +- [Containers](/docs/collect/container-metrics.md): Gather metrics from container agents, like `dockerd` or `kubectl`,
45 + along with the resource usage of containers and the applications they run.
46 +- [Applications](/docs/collect/application-metrics.md): Collect per-second metrics from web servers, databases, logs,
47 + message brokers, APM tools, email servers, and much more.
48 +
49 +## Collector architecture and terminology
50 +
51 +**Collector** is a catch-all term for any Netdata process that gathers metrics from an endpoint.
52 +
53 +While we use _collector_ most often in documentation, release notes, and educational content, you may encounter other
54 +terms related to collecting metrics.
55 +
56 +- **Modules** are a type of collector.
57 +- **Orchestrators** are external plugins that run and manage one or more modules. They run as independent processes.
58 + The Go orchestator is in active development.
59 + - [go.d.plugin](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/): An orchestrator for data
60 + collection modules written in `go`.
61 + - [python.d.plugin](/collectors/python.d.plugin/README.md): An orchestrator for data collection modules written in
62 + `python` v2/v3.
63 + - [charts.d.plugin](/collectors/charts.d.plugin/README.md): An orchestrator for data collection modules written in
64 + `bash` v4+.
65 + - [node.d.plugin](/collectors/node.d.plugin/README.md): An orchestrator for data collection modules written in
66 + `node.js`.
67 +- **External plugins** gather metrics from external processes, such as a webserver or database, and run as independent
68 + processes that communicate with the Netdata daemon via pipes.
69 +- **Internal plugins** gather metrics from `/proc`, `/sys`, and other Linux kernel sources. They are written in `C`,
70 + and run as threads within the Netdata daemon.
71 +
72 +## What's next?
73 +
74 +[Enable or configure a collector](/docs/collect/enable-configure.md) if the default settings are not compatible with
75 +your infrastructure.
76 +
77 +See our [collectors reference](/collectors/REFERENCE.md) for detailed information on Netdata's collector architecture,
78 +troubleshooting a collector, developing a custom collector, and more.
79 +
80 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fdocs%2Fcollect%2Fhow-collectors-work&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
docs/collect/system-metrics.md new
+62
@@ -0,0 +1,62 @@
1 +<!--
2 +title: "Collect system metrics with Netdata"
3 +sidebar_label: "System metrics"
4 +description: "Netdata collects thousands of metrics from physical and virtual systems, IoT/edge devices, and containers with zero configuration."
5 +custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/collect/system-metrics.md
6 +-->
7 +
8 +# Collect system metrics with Netdata
9 +
10 +Netdata collects thousands of metrics directly from the operating systems of physical and virtual systems, IoT/edge
11 +devices, and [containers](/docs/collect/container-metrics.md) with zero configuration.
12 +
13 +To gather system metrics, Netdata uses roughly a dozen plugins, each of which has one or more collectors for very
14 +specific metrics exposed by the host. The system metrics Netdata users interact with most for health monitoring and
15 +performance troubleshooting are collected and visualized by `proc.plugin`, `cgroups.plugin`, and `ebpf.plugin`.
16 +
17 +[**proc.plugin**](/collectors/proc.plugin/README.md) gathers metrics from the `/proc` and `/sys` folders in Linux
18 +systems, along with a few other endpoints, and is responsible for the bulk of the system metrics collected and
19 +visualized by Netdata. It collects CPU, memory, disks, load, networking, mount points, and more with zero configuration.
20 +It even allows Netdata to monitor its own resource utilization!
21 +
22 +[**cgroups.plugin**](/collectors/cgroups.plugin/README.md) collects rich metrics about containers and virtual machines
23 +using the virtual files under `/sys/fs/cgroup`. By reading cgroups, Netdata can instantly collect resource utilization
24 +metrics for systemd services, all containers (Docker, LXC, LXD, Libvirt, systemd-nspawn), and more. Learn more in the
25 +[collecting container metrics](/docs/collect/container-metrics.md) doc.
26 +
27 +[**ebpf.plugin**](/collectors/ebpf.plugin/README.md): Netdata's extended Berkeley Packet Filter (eBPF) collector
28 +monitors Linux kernel-level metrics for file descriptors, virtual filesystem IO, and process management. You can use our
29 +eBPF collector to analyze how and when a process accesses files, when it makes system calls, whether it leaks memory or
30 +creating zombie processes, and more.
31 +
32 +While the above plugins and associated collectors are the most important for system metrics, there are many others. You
33 +can find all system collectors in our [supported collectors list](/collectors/COLLECTORS.md#system-metrics).
34 +
35 +## Collect Windows system metrics
36 +
37 +Netdata is also capable of monitoring Windows systems. The [WMI
38 +collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/wmi) integrates with
39 +[windows_exporter](https://github.com/prometheus-community/windows_exporter), a small Go-based binary that you can run
40 +on Windows systems. The WMI collector then gathers metrics from an endpoint created by windows_exporter.
41 +
42 +First, [install
43 +windows_exporter](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/wmi#configuration) and run it:
44 +`windows_exporter-0.13.0-amd64.exe --collectors.enabled="cpu,memory,net,logical_disk,os,system,logon"`.
45 +
46 +Next, [configure the WMI
47 +collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/wmi#configuration) to point to the URL
48 +and port of your exposed endpoint. Restart Netdata with `service netdata restart` and you'll start seeing Windows system
49 +metrics, such as CPU utilization, memory, bandwidth per NIC, number of processes, and much more.
50 +
51 +For information about collecting metrics from applications _running on Windows systems_, see the [application metrics
52 +doc](/docs/collect/application-metrics.md#collect-metrics-from-applications-running-on-windows).
53 +
54 +## What's next?
55 +
56 +Because there's some overlap between system metrics and [container metrics](/docs/collect/container-metrics.md), you
57 +should investigate Netdata's container compatibility if you use them heavily in your infrastructure.
58 +
59 +If you don't use containers, skip ahead to collecting [application metrics](/docs/collect/application-metrics.md) with
60 +Netdata.
61 +
62 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fdocs%2Fcollect%2Fsystem-metrics&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
docs/configure/invite-collaborate.md new
+58
@@ -0,0 +1,58 @@
1 +<!--
2 +title: "Invite your team and collaborate"
3 +description: "Invite your SRE, DevOPs, or ITOps teams to Netdata Cloud to give everyone insights into your infrastructure from a single pane of glass."
4 +custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/configure/invite-collaborate.md
5 +-->
6 +
7 +# Invite your team and collaborate
8 +
9 +Netdata is designed to make an infrastructure's real-time metrics available and actionable to all organization members.
10 +By inviting others, you can better synchronize with your team or colleagues to understand your infrastructure's
11 +heartbeat. When something goes wrong, you'll be ready to collaboratively troubleshoot complex performance problems from
12 +a single pane of glass.
13 +
14 +## Invite new members
15 +
16 +Invite new users by clicking on your Space's name in the top navigation, and then **Invite more users**, to open the
17 +invitation pane. Admins manage user permissions and have control over who can access specific Spaces and War Rooms.
18 +
19 +![Opening and navigating the invitation
20 +panel](https://user-images.githubusercontent.com/1153921/92025596-a618e680-ed14-11ea-9c1f-a61fdcb8aa4e.png)
21 +
22 +Enter their email address and name. They can change this name once they accept your invitation.
23 +
24 +Choose which War Rooms you want to add this user to, then click the plus **+** button to add the invitation to the
25 +**New invitations to be sent** queue. Repeat the process with everyone you want to invite to your Space.
26 +
27 +When you're ready to send the new invitations you created, hit the **Send** button. Netdata Cloud sends these
28 +invitations and moves them to the **Invitations awaiting response** category.
29 +
30 +Your team will receive their email invitations momentarily with a prompt to sign in to join your Space.
31 +
32 +## Collaboration with Netdata Cloud
33 +
34 +Netdata Cloud gives teams a single interface to view real-time metrics across their entire infrastructure. Having all
35 +the metrics, alarm statuses, dashboards, and people in one place is a powerful asset for any infrastructure monitoring
36 +team.
37 +
38 +Assets like dashboards and bookmarks are shared between members of a War Room. As soon as one member creates a
39 +dashboard, for example, other members of the same War Room can see it in the War Room's dropdown and supplement it with
40 +additional charts/text.
41 +
42 +Let's say you get an alert from your nodes about an excess of 500-type errors in your Nginx logs. Your team can hop on a
43 +Slack call to begin working together. While one engineer handles creating a new dashboard with a half-dozen relevant
44 +Nginx log metrics, another can dive into the real-time node dashboard and investigate correlated charts in granular
45 +detail.
46 +
47 +## What's next?
48 +
49 +If your team members have trouble signing in, direct them to the [Netdata Cloud sign in
50 +doc](https://learn.netdata.cloud/docs/cloud/manage/sign-in). Or, find answers to other common questions about Netdata
51 +Cloud in our [FAQ](https://learn.netdata.cloud/docs/cloud/faq-glossary).
52 +
53 +Next, we recommend you learn the [basics of node configuration](/docs/configure/nodes.md). While the Netdata Agent is
54 +proudly zero-configuration in most cases, you should understand how to tweak its settings to give you the best Netdata,
55 +for example, to [increase metrics retention](/docs/store/change-metrics-storage.md) and [improve
56 +security](/docs/configure/secure-nodes.md).
57 +
58 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fdocs%2Fconfigure%2Finvite-collaborate&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
docs/configure/nodes.md new
+121
@@ -0,0 +1,121 @@
1 +<!--
2 +title: "Configure your nodes"
3 +description: "Netdata is zero-configuration for most users, but complex infrastructures may require you to tweak some of the Agent's granular settings."
4 +custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/configure/nodes.md
5 +-->
6 +
7 +# Configure your nodes
8 +
9 +Netdata's zero-configuration collection, storage, and visualization features work for many users, infrastructures, and
10 +use cases, but there are some situations where you might want to configure your nodes.
11 +
12 +For example, you might want to increase metrics retention, configure a collector based on your infrastructure's unique
13 +setup, or secure the local dashboard by restricting it to only connections from `localhost`.
14 +
15 +Whatever the reason, Netdata users should know how to configure individual nodes to act decisively if an incident,
16 +anomaly, or change in infrastructure affects how their Agents should peform.
17 +
18 +## The Netdata config directory
19 +
20 +On most Linux systems, using our [recommended one-line installation](/docs/get/README.md#install-the-netdata-agent), the
21 +**Netdata config directory** is `/etc/netdata/`. The config directory contains several configuration files with the
22 +`.conf` extension, a few directories, and a shell script named `edit-config`.
23 +
24 +> Some operating systems will use `/opt/netdata/etc/netdata/` as the config directory. If you're not sure where yours
25 +> is, navigate to `http://NODE:19999/netdata.conf` in your browser, replacing `NODE` with the IP address or hostname of
26 +> your node, and find the `# config directory = ` setting. The value listed is the config directory for your system.
27 +
28 +All of Netdata's documentation assumes that your config directory is at `/etc/netdata`, and that you're running any
29 +scripts from inside that directory.
30 +
31 +## Netdata's configuration files
32 +
33 +Upon installation, the Netdata config directory contains a few files and directories.
34 +
35 +- `netdata.conf` is the main configuration file. This is where you'll find most configuration options. This doc won't
36 + go into exhaustive detail about each setting. You can read descriptions for each in the [daemon config
37 + doc](/daemon/config/README.md).
38 +- `orig` is a symbolic link to the directory `/usr/lib/netdata/conf.d`, which contains stock configuration files.
39 + Stock versions are copied into the config directory when opened with `edit-config`. _Do not edit the files in
40 + `/usr/lib/netdata/conf.d`, as they are overwritten by updates to the Netdata Agent._
41 +- `edit-config` is a shell script used for [editing configuration files](#use-edit-config-to-edit-netdataconf).
42 +- `go.d/`, `python.d/`, `charts.d/`, `node.d`/, and `custom-plugins.d/`, which are directories for each of Netdata's
43 + [orchestrators](/collectors/plugins.d/README.md#external-plugins-overview). These directories can each contain
44 + additional `.conf` files for configuring specific collectors.
45 +
46 +## Use `edit-config` to edit `netdata.conf`
47 +
48 +The best way to edit any configuration file is with `edit-config` script. This script opens existing Netdata
49 +configuration files using your system's `$EDITOR`. If the file doesn't yet exist in your config directory, the script
50 +copies the stock version from `/usr/lib/netdata/conf.d` and opens it for editing.
51 +
52 +`edit-config` is the recommended way to easily and safely edit Netdata's configuration.
53 +
54 +Run `edit-config` without any options to see details on its usage and a list of all the configuration files you can
55 +edit.
56 +
57 +```bash
58 +./edit-config
59 +USAGE:
60 + ./edit-config FILENAME
61 +
62 + Copy and edit the stock config file named: FILENAME
63 + if FILENAME is already copied, it will be edited as-is.
64 +
65 + The EDITOR shell variable is used to define the editor to be used.
66 +
67 + Stock config files at: '/usr/lib/netdata/conf.d'
68 + User config files at: '/etc/netdata'
69 +
70 + Available files in '/usr/lib/netdata/conf.d' to copy and edit:
71 +
72 +./apps_groups.conf ./health.d/phpfpm.conf
73 +./aws_kinesis.conf ./health.d/pihole.conf
74 +./charts.d/ap.conf ./health.d/portcheck.conf
75 +./charts.d/apcupsd.conf ./health.d/postgres.conf
76 +...
77 +```
78 +
79 +To edit `netdata.conf`, run `./edit-config netdata.conf`. You may need to elevate your privileges with `sudo` or another
80 +method for `edit-config` to write into the config directory. Use your `$EDITOR`, make your changes, and save the file.
81 +
82 +> `edit-config` uses the `EDITOR` environment variable on your system to edit the file. On many systems, that is
83 +> defaulted to `vim` or `nano`. To change this variable for the current session (it will revert to the default when you
84 +> reboot), export a new value: `export EDITOR=nano`. Or, [make the change
85 +> permanent](https://stackoverflow.com/questions/13046624/how-to-permanently-export-a-variable-in-linux).
86 +
87 +After you make your changes, you need to restart the Agent with `service netdata restart`.
88 +
89 +Here's an example of editing the node's hostname, which appears in both the local dashboard and in Netdata Cloud.
90 +
91 +![Animated GIF of editing the hostname option in
92 +netdata.conf](https://user-images.githubusercontent.com/1153921/80994808-1c065300-8df2-11ea-81af-d28dc3ba27c8.gif)
93 +
94 +### Other configuration files
95 +
96 +You can edit any Netdata configuration file using `edit-config`. A few examples:
97 +
98 +```bash
99 +./edit-config apps_groups.conf
100 +./edit-config ebpf.conf
101 +./edit-config health.d/load.conf
102 +./edit-config go.d/prometheus.conf
103 +```
104 +
105 +The documentation for each of Netdata's components explains which file(s) to edit to achieve the desired behavior.
106 +
107 +## What's next?
108 +
109 +Take advantage of this newfound understanding of node configuration to [add security to your
110 +node](/docs/configure/secure-nodes.md). We have a few best practices based on how you use the Netdata Agent and Netdata
111 +Cloud.
112 +
113 +You can also take what you've learned about node configuration to tweak the Agent's behavior or enable new features:
114 +
115 +- [Enable new collectors](/docs/collect/enable-configure.md) or tweak their behavior.
116 +- [Configure existing health alarms](/docs/monitor/configure-alarms.md) or create new ones.
117 +- [Enable notifications](/docs/monitor/enable-notifications.md) to receive updates about the health of your
118 + infrastructure.
119 +- Change [the long-term metrics retention period](/docs/store/change-metrics-storage.md) using the database engine.
120 +
121 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fdocs%2Fconfigure%2Fnodesa&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
docs/configure/secure-nodes.md new
+121
@@ -0,0 +1,121 @@
1 +<!--
2 +title: "Secure your nodes"
3 +description: "Your data and systems are safe with Netdata, but
4 +
5 +we recommend a few easy ways to improve the security of your infrastructure."
6 +custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/configure/secure-nodes.md
7 +-->
8 +
9 +# Secure your nodes
10 +
11 +Upon installation, the Netdata Agent serves the local dashboard at port `19999`. If the node is accessible to the
12 +internet at large, anyone can access the dashboard and your node's metrics at `http://NODE:19999`. We made this decision
13 +so that the local dashboard was immediately accessible to users, and so that we don't dictate how professionals set up
14 +and secure their infrastructures.
15 +
16 +Despite this design decision, your [data](/docs/netdata-security.md#your-data-are-safe-with-netdata) and your
17 +[systems](/docs/netdata-security.md#your-systems-are-safe-with-netdata) are safe with Netdata. Netdata is read-only,
18 +cannot do anything other than present metrics, and runs without special/`sudo` privileges. Also, the local dashboard
19 +only exposes chart metadata and metric values, not raw data.
20 +
21 +While Netdata is secure by design, we believe you should [protect your
22 +nodes](/docs/netdata-security.md#why-netdata-should-be-protected). If left accessible to the internet at large, the
23 +local dashboard could reveal sensitive information about your infrastructure. For example, an attacker can view which
24 +applications you run (databases, webservers, and so on), or see every user account on a node.
25 +
26 +Instead of dictating how to secure your infrastructure, we give you many options to establish security best practices
27 +that align with your goals and your organization's standards.
28 +
29 +- [Disable the local dashboard](#disable-the-local-dashboard): **Simplest and recommended method** for those who have
30 + added nodes to Netdata Cloud and view metrics there.
31 +- [Restrict access to the local dashboard](#restrict-access-to-the-local-dashboard): Allow dashboard access from only
32 + certain IP addresses, such as a trusted static IP or connections from behind a management LAN. Full support for
33 + Netdata Cloud.
34 +- [Use a reverse proxy](#use-a-reverse-proxy): Password-protect a local dashboard and enable TLS to secure it. Full
35 + support for Netdata Cloud.
36 +
37 +## Disable the local dashboard
38 +
39 +This is the _recommended method for those who have claimed their nodes to Netdata Cloud_ and prefer viewing real-time
40 +metrics using the Nodes view and Cloud dashboards.
41 +
42 +You can disable the local dashboard entirely but retain the encrypted Agent-Cloud link ([ACLK](/aclk/README.md)) that
43 +allows you to stream metrics on demand from your nodes via the Netdata Cloud interface. This change mitigates all
44 +concerns about revealing metrics and system design to the internet at large, while keeping all the functionality you
45 +need to view metrics and troubleshoot issues.
46 +
47 +Open `netdata.conf` with `./edit-config netdata.conf`. Scroll down to the `[web]` section, and find the `mode =
48 +static-threaded` setting. To disable the local dashboard, change this setting to `none`.
49 +
50 +```conf
51 +[web]
52 + mode = none
53 +```
54 +
55 +Save and close the editor, then restart your Agent using `service netdata restart`. If you try to visit the local
56 +dashboard to `http://NODE:19999` again, the connection will fail because that node no longer serves its local dashboard.
57 +
58 +> See the [configuration basics doc](/docs/configure/nodes.md) for details on how to find `netdata.conf` and use
59 +> `edit-config`.
60 +
61 +## Restrict access to the local dashboard
62 +
63 +If you want to keep using the local dashboard, but don't want it exposed to the internet, you can restrict access with
64 +[access lists](/web/server/README.md#access-lists). This method also fully retains the ability to stream metrics
65 +on-demand through Netdata Cloud.
66 +
67 +The `allow connections from` setting helps you allow only certain IP addresses or FQDN/hostnames, such as a trusted
68 +static IP, only `localhost`, or connections from behind a management LAN.
69 +
70 +By default, this setting is `localhost *`. This setting allows connections from `localhost` in addition to _all_
71 +connections, using the `*` wildcard. You can change this setting using Netdata's [simple
72 +patterns](/libnetdata/simple_pattern/README.md).
73 +
74 +```conf
75 +[web]
76 + # Allow only localhost connections
77 + allow connections from = localhost
78 +
79 + # Allow only from management LAN running on `10.X.X.X`
80 + allow connections from = 10.*
81 +
82 + # Allow connections only from a specific FQDN/hostname
83 + allow connections from = example*
84 +```
85 +
86 +The `allow connections from` setting is global and restricts access to the dashboard, badges, streaming, API, and
87 +`netdata.conf`, but you can also set each of those access lists more granularly if you choose:
88 +
89 +```conf
90 +[web]
91 + allow connections from = localhost *
92 + allow dashboard from = localhost *
93 + allow badges from = *
94 + allow streaming from = *
95 + allow netdata.conf from = localhost fd* 10.* 192.168.* 172.16.* 172.17.* 172.18.* 172.19.* 172.20.* 172.21.* 172.22.* 172.23.* 172.24.* 172.25.* 172.26.* 172.27.* 172.28.* 172.29.* 172.30.* 172.31.*
96 + allow management from = localhost
97 +```
98 +
99 +See the [web server](/web/server/README.md#access-lists) docs for additional details about access lists. You can take
100 +access lists one step further by [enabling SSL](/web/server/README.md#enabling-tls-support) to encrypt data in transit.
101 +
102 +## Use a reverse proxy
103 +
104 +You can also put Netdata behind a reverse proxy for additional security while retaining the functionality of both the
105 +local dashboard and Netdata Cloud dashboards. You can use a reverse proxy to password-protect the local dashboard and
106 +enable HTTPS to encrypt metadata and metric values in transit.
107 +
108 +We recommend Nginx, as it's what we use for our [demo server](https://london.my-netdata.io/), and we have a guide
109 +dedicated to [running Netdata behind Nginx](/docs/Running-behind-nginx.md).
110 +
111 +We also have guides for [Apache](/docs/Running-behind-apache.md), [Lighttpd](/docs/Running-behind-lighttpd.md),
112 +[HAProxy](/docs/Running-behind-haproxy.md), and [Caddy](/docs/Running-behind-caddy.md).
113 +
114 +## What's next?
115 +
116 +If you haven't already, be sure to read about [Netdata's security design](/docs/netdata-security.md).
117 +
118 +Next up, learn about [collectors](/docs/collect/how-collectors-work.md) to ensure you're gathering every essential
119 +metric about your node, its applications, and your infrastructure at large.
120 +
121 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fdocs%2Fconfigure%2Fsecure-nodesa&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
docs/configure/spaces-war-rooms.md new
+87
@@ -0,0 +1,87 @@
1 +<!--
2 +title: "Set up Spaces and War Rooms"
3 +description: "Netdata Cloud allows people and teams of all sizes to organize their infrastructure and collaborate on anomalies or incidents."
4 +custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/configure/spaces-war-rooms.md
5 +-->
6 +
7 +# Set up Spaces and War Rooms
8 +
9 +Spaces and War Rooms help you organize your real-time infrastructure monitoring experience in Netdata Cloud. You already
10 +created a Space and War Room when you first signed in to Cloud, assuming you weren't invited to an existing Space by
11 +someone else.
12 +
13 +In either case, you can always create new Spaces and War Rooms based on your changing needs or a scaled-up
14 +infrastructure. Let's talk through some strategies for building the most intuitive Cloud experience for your team.
15 +
16 +> This guide assumes you've already [signed in](https://app.netdata.cloud) to Netdata Cloud and finished creating your
17 +> account. If you're not interested in Netdata Cloud's features, you can skip ahead to [node configuration
18 +> basics](/docs/configure/nodes.md).
19 +
20 +## Spaces
21 +
22 +Spaces are high-level containers to help you organize your team members and the nodes they can view in each War Room.
23 +You already have at least one Space in your Netdata Cloud account.
24 +
25 +To create a new Space, click the **+** icon, enter its name, and click **Save**. Netdata Cloud distinguishes between
26 +Spaces with abbreviated versions of their name. Click on any of the icons to switch between them.
27 +
28 +![Spaces navigation in Netdata
29 +Cloud](https://user-images.githubusercontent.com/1153921/92177439-5b22d000-edf5-11ea-9323-383347f21c8d.png)
30 +
31 +The organization you choose will likely be based on two factors:
32 +
33 +1. The fact that any node can be claimed to a single Space.
34 +2. The size of your team and the complexity of the infrastructure you monitor.
35 +
36 +A single Space puts all your metrics in one easily-accessible place, while multiple Spaces creates logical division
37 +between different users and different pieces of a large infrastructure.
38 +
39 +For example, a large organization might have one SRE team for the user-facing SaaS application, and a second IT team for
40 +managing employees' hardware. Since these teams don't monitor the same nodes, they can work in separate Spaces and then
41 +further organize their nodes into War Rooms.
42 +
43 +You can also use multiple Spaces for different aspects of your monitoring "life," such as your work infrastructure
44 +versus your homelab.
45 +
46 +## War Rooms
47 +
48 +War Rooms are granular containers for organizing nodes, viewing key metrics in real-time, and monitoring the health and
49 +alarm status of many nodes.
50 +
51 +War Rooms organize the [at-a-glance Node view](/docs/visualize/view-all-nodes.md) and any [new
52 +dashboards](/docs/visualize/create-dashboards.md) you build.
53 +
54 +We recommend a few strategies for organizing your War Rooms.
55 +
56 +**Service, purpose, location, etc.**: You can group War Rooms by a service (think Nginx, MySQL, Pulsar, and so on),
57 +their purpose (webserver, database, application), their physical location, whether they're baremetal or a Docker
58 +container, the PaaS/cloud provider it runs on, and much more. This allows you to see entire slices of your
59 +infrastructure by moving from one War Room to another.
60 +
61 +**End-to-end apps/services**: If you have a user-facing SaaS product, or an internal service that said product relies
62 +on, you may want to monitor that entire stack in a single War Room. This might include Kubernetes clusters, Docker
63 +containers, proxies, databases, web servers, brokers, and more. End-to-end War Rooms are valuable tools for ensuring the
64 +health and performance of your organization's essential services.
65 +
66 +**Incident response**: You can also create new War Rooms as one of the first steps in your incident response process.
67 +For example, you have a user-facing web app that relies on Apache Pulsar for a message queue, and one of your nodes
68 +using the [Pulsar collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/pulsar) begins
69 +reporting a suspiciously low messages rate. You can create a War Room called `$year-$month-$day-pulsar-rate`, add all
70 +your Pulsar nodes in addition to nodes they connect to, and begin diagnosing the root cause in a War Room optimized for
71 +getting to resolution as fast as possible.
72 +
73 +For example, here is a War Room based on the node's provider and physical location (**us-east-1**).
74 +
75 +![An example War Room based on provider and
76 +location](https://user-images.githubusercontent.com/1153921/92178714-ff0d7b00-edf7-11ea-8411-09b2e75a5529.png)
77 +
78 +## What's next?
79 +
80 +Once you've figured out an organizational structure that works for your infrastructure, it's time to [invite your
81 +team](/docs/configure/invite-collaborate.md). You can invite any number of colleagues to help you collectively
82 +troubleshoot the most complex of infrastructure-wide performance issues.
83 +
84 +If you don't have a team or aren't ready to invite them, you can skip ahead to learn the [basics of node
85 +configuration](/docs/configure/nodes.md).
86 +
87 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fdocs%2Fconfigure%2Fspaces-war-rooms&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
docs/export/README.md deleted
-101
@@ -1,101 +0,0 @@
1 -<!--
2 -title: Export metrics
3 -description: "Archive your Netdata metrics to multiple external time series databases for long-term storage or further analysis."
4 -custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/export/README.md
5 --->
6 -
7 -# Export metrics
8 -
9 -One of Netdata's pillars is interoperability with other monitoring and visualization solutions. To this end, you can use
10 -the Agent's [exporting engine](/exporting/README.md) to send metrics to multiple external databases/services in
11 -parallel. Once you connect Netdata metrics to other solutions, you can apply machine learning analysis or correlation
12 -with other tools, such as application tracing.
13 -
14 -The exporting engine supports a number of connectors, including AWS Kinesis Data Streams, Graphite, JSON, MongoDB,
15 -OpenTSDB, Prometheus remote write, and more, via exporting **connectors**. These connectors help you seamlessly send
16 -Netdata metrics to more than 20 different endpoints, including every [service that
17 -supports](https://prometheus.io/docs/operating/integrations/#remote-endpoints-and-storage) Prometheus remote write. See
18 -the [exporting reference guide](/exporting/README.md) for the full list.
19 -
20 -## Exporting quickstart
21 -
22 -Let's cover the process of enabling an exporting connector, using the Graphite connector as an example. These steps can
23 -be applied to other connectors as well.
24 -
25 -> If you are migrating from the deprecated backends system, this quickstart will also help you update your configuration
26 -> to the new format. For the most part, the configurations are identical, but there are two exceptions. First,
27 -> `exporting.conf` uses a new `[<type>:<name>]` format for defining connector instances. Second, the `host tags` setting
28 -> is deprecated. Instead, use [host labels](/docs/guides/using-host-labels.md) to tag exported metrics.
29 -
30 -Open the `exporting.conf` file with `edit-config`.
31 -
32 -```bash
33 -cd /etc/netdata # Replace this path with your Netdata config directory
34 -sudo ./edit-config exporting.conf
35 -```
36 -
37 -### Enable the exporting engine
38 -
39 -Enable the exporting engine by setting `enabled` to `yes`:
40 -
41 -```conf
42 -[exporting:global]
43 - enabled = yes
44 -```
45 -
46 -### Change how often the exporting engine sends metrics
47 -
48 -By default, the exporting engine only sends metrics to external databases every 10 seconds to avoid congesting the
49 -destination with thousands of per-second metrics.
50 -
51 -You can change this frequency for all connectors based on how you use exported metrics or the resources you can allocate
52 -to long-term storage. Use the `update every` setting to change the frequency in seconds.
53 -
54 -```conf
55 -[exporting:global]
56 - update every = 10
57 -```
58 -
59 -### Enable a connector (Graphite)
60 -
61 -To enable the Graphite connector, find the `[graphite:my_graphite_instance]` example section in `exporting.conf`. You
62 -can use this (or the respective example for the connector you want to use) as a framework for your configration.
63 -
64 -`[graphite:my_graphite_instance]` is an example of the new `[<type>:<name>]` format for defining connector instances.
65 -
66 -Uncomment the section itself and replace `my_graphite_instance` with a name of your choice. Then set `enabled` to `yes`
67 -and uncomment the line.
68 -
69 -```conf
70 -[graphite:my_graphite_instance]
71 - enabled = yes
72 - # destination = localhost:2003
73 - # data source = average
74 - # prefix = netdata
75 - # hostname = my_hostname
76 - # update every = 10
77 - # buffer on failures = 10
78 - # timeout ms = 20000
79 - # send names instead of ids = yes
80 - # send charts matching = *
81 - # send hosts matching = localhost *
82 -```
83 -
84 -Next, edit and uncomment any other lines necessary to connect the exporting engine to your endpoint. If migrating from
85 -backends, port your settings over and uncomment any lines you change. You must edit the `destination` setting in most
86 -situations.
87 -
88 -For details on all the configuration options, see the [exporting reference](/exporting/README.md#configuration).
89 -
90 -Restart your Agent to begin exporting to the destination of your choice. Because the Agent exports metrics as they're
91 -collected, you should start seeing data in your external database after only a few seconds.
92 -
93 -## Exporting reference, guides, and related features
94 -
95 -- [Exporting reference guide](/exporting/README.md)
96 -- [Guide: Export and visualize Netdata metrics in Graphite](/docs/guides/export/export-netdata-metrics-graphite.md)
97 -- [Guide: Use host labels to organize systems, metrics, and alarms](/docs/guides/using-host-labels.md)
98 -- [Guide: Change how long Netdata stores metrics (long-term storage)](/docs/guides/longer-metrics-storage.md)
99 -- [Backends (deprecated)](/backends/README.md)
100 -
101 -[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fdocs%2Fexporting%2FREADME.md&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
docs/export/enable-connector.md new
+90
@@ -0,0 +1,90 @@
1 +<!--
2 +title: "Enable an exporting connector"
3 +description: "Learn how to enable and configure any connector using examples to start exporting metrics to external time-series databases in minutes."
4 +custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/export/enable-connector.md
5 +-->
6 +
7 +# Enable an exporting connector
8 +
9 +Now that you found the right connector for your [external time-series
10 +database](/docs/export/external-databases.md#supported-databases), you can now enable the exporting engine and the
11 +connector itself. We'll walk through the process of enabling the exporting engine itself, followed by two examples using
12 +the OpenTSDB and Graphite connectors.
13 +
14 +Once you understand the process of enabling a connector, you can translate that knowledge to any other connector.
15 +
16 +## Enable the exporting engine
17 +
18 +Use `edit-config` from your [Netdata config directory](/docs/configure/nodes.md#the-netdata-config-directory) to open
19 +`exporting.conf`:
20 +
21 +```bash
22 +sudo ./edit-config exporting.conf
23 +```
24 +
25 +Enable the exporting engine itself by setting `enabled` to `yes`:
26 +
27 +```conf
28 +[exporting:global]
29 + enabled = yes
30 +```
31 +
32 +Save the file but keep it open, as you will edit it again to enable specific connectors.
33 +
34 +## Example: Enable the OpenTSDB connector
35 +
36 +Use the following configuration as a starting point. Copy and paste it into `exporting.conf`.
37 +
38 +```conf
39 +[opentsdb:http:my_opentsdb_http_instance]
40 + enabled = yes
41 + destination = localhost:4242
42 +```
43 +
44 +Replace `my_opentsdb_http_instance` with an instance name of your choice, and change the `destination` setting to the IP
45 +address or hostname of your OpenTSDB database.
46 +
47 +Restart your Agent with `service netdata restart` to begin exporting to your OpenTSDB database. Because the
48 +Agent exports metrics as they're collected, you should start seeing data in your external database after only a few
49 +seconds.
50 +
51 +Any further configuration is optional, based on your needs and the configuration of your OpenTSDB database. See the
52 +[OpenTSDB connector doc](/exporting/opentsdb/README.md) and [exporting engine
53 +reference](/exporting/README.md#configuration) for details.
54 +
55 +## Example: Enable the Graphite connector
56 +
57 +Use the following configuration as a starting point. Copy and paste it into `exporting.conf`.
58 +
59 +```conf
60 +[graphite:my_graphite_instance]
61 + enabled = yes
62 + destination = 203.0.113.0:2003
63 +```
64 +
65 +Replace `my_graphite_instance` with an instance name of your choice, and change the `destination` setting to the IP
66 +address or hostname of your Graphite-supported database.
67 +
68 +Restart your Agent with `service netdata restart` to begin exporting to your Graphite-supported database. Because the
69 +Agent exports metrics as they're collected, you should start seeing data in your external database after only a few
70 +seconds.
71 +
72 +Any further configuration is optional, based on your needs and the configuration of your Graphite-supported database.
73 +See [exporting engine reference](/exporting/README.md#configuration) for details.
74 +
75 +## What's next?
76 +
77 +If you want to further configure your exporting connectors, see the [exporting engine
78 +reference](/exporting/README.md#configuration).
79 +
80 +For a comprehensive example of using the Graphite connector, read our guide: [_Export and visualize Netdata metrics in
81 +Graphite_](/docs/guides/export/export-netdata-metrics-graphite.md). Or, start [using host
82 +labels](/docs/guides/using-host-labels.md) on exported metrics.
83 +
84 +### Related reference documentation
85 +
86 +- [Exporting engine reference](/exporting/README.md)
87 +- [OpenTSDB connector](/exporting/opentsdb/README.md)
88 +- [Graphite connector](/exporting/graphite/README.md)
89 +
90 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fdocs%2Fexporting%2Fenable-connector&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
docs/export/external-databases.md new
+89
@@ -0,0 +1,89 @@
1 +<!--
2 +title: "Export metrics to external time-series databases"
3 +description: "Use the exporting engine to send Netdata metrics to popular external time series databases for long-term storage or further analysis."
4 +custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/export/external-databases.md
5 +-->
6 +
7 +# Export metrics to external time-series databases
8 +
9 +Netdata allows you to export metrics to external time-series databases with the [exporting
10 +engine](/exporting/README.md). This system uses a number of **connectors** to intiate connections to [more than
11 +thirty](#supported-databases) supported databases, including InfluxDB, Prometheus, Graphite, ElasticSearch, and much
12 +more.
13 +
14 +The exporting engine resamples Netdata's thousands of per-second metrics at a user-configurable interval, and can export
15 +metrics to multiple time-series databases simultaneously.
16 +
17 +Based on your needs and resources you allocated to your external time-series database, you can configure the interval
18 +that metrics are exported or export only certain charts with filtering. You can also choose whether metrics are exported
19 +as-collected, a normalized average, or the sum/volume of metrics values over the configured interval.
20 +
21 +Exporting is an important part of Netdata's effort to be [interoperable](/docs/overview/netdata-monitoring-stack.md)
22 +with other monitoring software. You can use an external time-series database for long-term metrics retention, further
23 +analysis, or correlation with other tools, such as application tracing.
24 +
25 +## Supported databases
26 +
27 +Netdata supports exporting metrics to the following databases through several
28 +[connectors](/exporting/README.md#features). Once you find the connector that works for your database, open its
29 +documentation and the [enabling a connector](/docs/export/enable-connector.md) doc for details on enabling it.
30 +
31 +- **AppOptics**: [Prometheus remote write](/exporting/prometheus/remote_write/README.md)
32 +- **AWS Kinesis**: [AWS Kinesis Data Streams](/exporting/aws_kinesis/README.md)
33 +- **Azure Data Explorer**: [Prometheus remote write](/exporting/prometheus/remote_write/README.md)
34 +- **Azure Event Hubs**: [Prometheus remote write](/exporting/prometheus/remote_write/README.md)
35 +- **Blueflood**: [Graphite](/exporting/graphite/README.md)
36 +- **Chronix**: [Prometheus remote write](/exporting/prometheus/remote_write/README.md)
37 +- **Cortex**: [Prometheus remote write](/exporting/prometheus/remote_write/README.md)
38 +- **CrateDB**: [Prometheus remote write](/exporting/prometheus/remote_write/README.md)
39 +- **ElasticSearch**: [Graphite](/exporting/graphite/README.md), [Prometheus remote
40 + write](/exporting/prometheus/remote_write/README.md)
41 +- **Gnocchi**: [Prometheus remote write](/exporting/prometheus/remote_write/README.md)
42 +- **Google BigQuery**: [Prometheus remote write](/exporting/prometheus/remote_write/README.md)
43 +- **Google Cloud Pub/Sub**: [Google Cloud Pub/Sub Service](/exporting/pubsub/README.md)
44 +- **Graphite**: [Graphite](/exporting/graphite/README.md), [Prometheus remote
45 + write](/exporting/prometheus/remote_write/README.md)
46 +- **InfluxDB**: [Graphite](/exporting/graphite/README.md), [Prometheus remote
47 + write](/exporting/prometheus/remote_write/README.md)
48 +- **IRONdb**: [Prometheus remote write](/exporting/prometheus/remote_write/README.md)
49 +- **JSON**: [JSON document databases](/exporting/json/README.md)
50 +- **Kafka**: [Prometheus remote write](/exporting/prometheus/remote_write/README.md)
51 +- **KairosDB**: [Graphite](/exporting/graphite/README.md), [OpenTSDB](/exporting/opentsdb/README.md)
52 +- **M3DB**: [Prometheus remote write](/exporting/prometheus/remote_write/README.md)
53 +- **MetricFire**: [Prometheus remote write](/exporting/prometheus/remote_write/README.md)
54 +- **MongoDB**: [MongoDB](/exporting/mongodb/)
55 +- **New Relic**: [Prometheus remote write](/exporting/prometheus/remote_write/README.md)
56 +- **OpenTSDB**: [OpenTSDB](/exporting/opentsdb/README.md), [Prometheus remote
57 + write](/exporting/prometheus/remote_write/README.md)
58 +- **PostgreSQL**: [Prometheus remote write](/exporting/prometheus/remote_write/README.md)
59 +- **Prometheus**: [Prometheus scraper](/exporting/prometheus/README.md)
60 +- **TimescaleDB**: [Prometheus remote write](/exporting/prometheus/remote_write/README.md),
61 + [netdata-timescale-relay](/exporting/TIMESCALE.md)
62 +- **QuasarDB**: [Prometheus remote write](/exporting/prometheus/remote_write/README.md)
63 +- **SignalFx**: [Prometheus remote write](/exporting/prometheus/remote_write/README.md)
64 +- **Splunk**: [Prometheus remote write](/exporting/prometheus/remote_write/README.md)
65 +- **TiKV**: [Prometheus remote write](/exporting/prometheus/remote_write/README.md)
66 +- **Thanos**: [Prometheus remote write](/exporting/prometheus/remote_write/README.md)
67 +- **VictoriaMetrics**: [Prometheus remote write](/exporting/prometheus/remote_write/README.md)
68 +- **Wavefront**: [Prometheus remote write](/exporting/prometheus/remote_write/README.md)
69 +
70 +Can't find your preferred external time-series database? Ask our [community](https://community.netdata.cloud/) for
71 +solutions, or file an [issue on
72 +GitHub](https://github.com/netdata/netdata/issues/new?labels=bug%2C+needs+triage&template=bug_report.md).
73 +
74 +## What's next?
75 +
76 +We recommend you read our document on [enabling a connector](/docs/export/enable-connector.md) to learn about the
77 +process and discover important configuration options. If you would rather skip ahead, click on any of the above links to
78 +connectors for their reference documentation, which outline any prerequisites to install for that connector, along with
79 +connector-specific configuration options.
80 +
81 +Read about one possible use case for exporting metrics in our guide: [_Export and visualize Netdata metrics in
82 +Graphite_](/docs/guides/export/export-netdata-metrics-graphite.md).
83 +
84 +### Related reference documentation
85 +
86 +- [Exporting engine reference](/exporting/README.md)
87 +- [Backends reference (deprecated)](/backends/README.md)
88 +
89 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fdocs%2Fexporting%2Fexternal-databases&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
docs/get/README.md new
+131
@@ -0,0 +1,131 @@
1 +<!--
2 +title: "Get Netdata"
3 +description: "Time to get Netdata's monitoring and troubleshooting solution. Sign in to Cloud, download the Agent everywhere, and connect it all together."
4 +custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/get/README.md
5 +-->
6 +
7 +# Get Netdata
8 +
9 +import { OneLineInstall } from '../src/components/OneLineInstall/'
10 +import { Install, InstallBox } from '../src/components/InstallBox/'
11 +
12 +Netdata uses an open-source monitoring Agent and web application [together](/docs/overview/what-is-netdata.md) to help
13 +you collect every metric, visualize the health of your systems, and troubleshoot complex performance problems. Once
14 +you've signed in to Netdata Cloud and installed the Netdata Agent on all your nodes, you can claim these nodes and see
15 +their real-time metrics on a single interface.
16 +
17 +## Sign in to Netdata Cloud
18 +
19 +If you don't already have a free Netdata Cloud account, go ahead and [create one](https://app.netdata.cloud).
20 +
21 +Choose your preferred authentication method and follow the onboarding process to create your Space.
22 +
23 +## Install the Netdata Agent
24 +
25 +The Netdata Agent runs permanently on all your physical/virtual servers, containers, cloud deployments, and edge/IoT
26 +devices. It runs on Linux distributions (**Ubuntu**, **Debian**, **CentOS**, and more), container/microservice platforms
27 +(**Kubernetes** clusters, **Docker**), and many other operating systems (**FreeBSD**, **macOS**), with no `sudo`
28 +required.
29 +
30 +> ⚠️ Many distributions ship with third-party packages of Netdata, which we cannot maintain or keep up-to-date. For the
31 +> best experience, use one of the methods described or link to below.
32 +
33 +The **recommended** way to install the Netdata Agent on a Linux system is our one-line [kickstart
34 +script](/packaging/installer/methods/kickstart.md). This script automatically installs dependencies and builds Netdata
35 +from its source code.
36 +
37 +<OneLineInstall />
38 +
39 +Copy the script, paste it into your node's terminal, and hit `Enter`.
40 +
41 +Open your favorite browser and navigate to `http://localhost:19999` or `http://REMOTE-HOST:19999` to open the dashboard.
42 +
43 +<details>
44 +<summary>Watch how the one-line installer works</summary>
45 +<iframe width="820" height="460" src="https://www.youtube.com/embed/tVIp7ycK60A" frameborder="0" allow="accelerometer; autoplay; clipboard-write; encrypted-media; gyroscope; picture-in-picture" allowfullscreen></iframe>
46 +</details>
47 +
48 +### Other operating systems/methods
49 +
50 +Want to install Netdata on a Kubernetes cluster, with Docker, or using a different method? Not a Linux user? Choose your
51 +platform to see specific instructions.
52 +
53 +<Install>
54 + <InstallBox
55 + to="/docs/agent/packaging/installer/methods/kubernetes"
56 + img="/img/index/methods/kubernetes.svg"
57 + os="Kubernetes" />
58 + <InstallBox
59 + to="/docs/agent/packaging/docker"
60 + img="/img/index/methods/docker.svg"
61 + os="Docker" />
62 + <InstallBox
63 + to="/docs/agent/packaging/installer/methods/cloud-providers"
64 + img="/img/index/methods/cloud.svg"
65 + os="Cloud providers (GCP, AWS, Azure)" />
66 + <InstallBox
67 + to="/docs/agent/packaging/installer/methods/packages"
68 + img="/img/index/methods/package.svg"
69 + os="Linux with .deb/.rpm" />
70 + <InstallBox
71 + to="/docs/agent/packaging/installer/methods/kickstart-64"
72 + img="/img/index/methods/static.svg"
73 + os="Linux with static 64-bit binary" />
74 + <InstallBox
75 + to="/docs/agent/packaging/installer/methods/manual"
76 + img="/img/index/methods/git.svg"
77 + os="Linux from Git" />
78 + <InstallBox
79 + to="/docs/agent/packaging/installer/methods/freebsd"
80 + img="/img/index/methods/freebsd.svg"
81 + os="FreeBSD" />
82 + <InstallBox
83 + to="/docs/agent/packaging/installer/methods/macos"
84 + img="/img/index/methods/macos.svg"
85 + os="MacOS" />
86 +</Install>
87 +
88 +Even more options available in our [packaging documentation](/packaging/installer/README.md#alternative-methods).
89 +
90 +## Claim your node on Netdata Cloud
91 +
92 +You need to [claim](/claim/README.md) your nodes to see them in Netdata Cloud. Claiming establishes a secure TLS
93 +connection to Netdata Cloud using the [Agent-Cloud link](/aclk/README.md), and proves you have write and administrative
94 +access to that node.
95 +
96 +When you view a node in Netdata Cloud, the Agent running on that node streams metrics, metadata, and alarm status to
97 +Netdata Cloud, which in turn streams those metrics to your web browser. Netdata Cloud does not store or log metrics or
98 +alarm status.
99 +
100 +To claim a node, you need to run the claiming script. In Netdata Cloud, click on your Space's name, then **Manage your
101 +Space** in the dropdown. Click **Nodes** in the panel that appears. Copy the script and run it in your node's terminal.
102 +For example:
103 +
104 +```bash
105 +sudo netdata-claim.sh -token=TOKEN -rooms=ROOM1,ROOM2 -url=https://app.netdata.cloud
106 +```
107 +
108 +The script should return `Agent was successfully claimed.` after creating a new RSA pair and establishing the link to
109 +Netdata Cloud.
110 +
111 +For more information on the claiming process, why we implemented it, and how it works, see the [claim](/claim/README.md)
112 +and [Agent-Cloud link](/aclk/README.md) reference docs.
113 +
114 +<details>
115 +<summary>Watch how claiming nodes works</summary>
116 +<iframe width="820" height="460" src="https://www.youtube.com/embed/UAzVvhMab8g" frameborder="0" allow="accelerometer; autoplay; clipboard-write; encrypted-media; gyroscope; picture-in-picture" allowfullscreen></iframe>
117 +</details>
118 +
119 +## What's next?
120 +
121 +At this point, you have set up your free Netdata Cloud account, installed the Agent, and claimed one or more nodes to
122 +your Space. You're ready to start monitoring, visualizing, and troubleshooting with Netdata. We have two quickstart
123 +guides based on the scope of what you need to monitor:
124 +
125 +Interested in monitoring a single node? Check out our [single-node monitoring
126 +quickstart](/docs/quickstart/single-node.md).
127 +
128 +If you're looking to monitor an entire infrastructure with Netdata, see the [infrastructure monitoring
129 +quickstart](/docs/quickstart/infrastructure.md).
130 +
131 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fdocs%2Foverview%2Fnetdata-monitoring-stacka&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
docs/getting-started.md
+3 -3
@@ -67,9 +67,9 @@ configuration keeps RAM usage low while allowing for long-term, on-disk metrics
67 You can tweak this custom _database engine_ to store a much larger dataset than your system's available RAM,
68 particularly if you allow Netdata to use slightly more RAM and disk space than the default configuration.
69
70 -Read our guide on [changing how long Netdata stores metrics](/docs/guides/longer-metrics-storage.md) to learn more
71 -and use our [database engine calculator](https://learn.netdata.cloud/docs/agent/database/calculator) to figure
72 -out the exact settings you'll need to store historical metrics right in the Agent's database.
70 +Read our guide on [changing how long Netdata stores metrics](/docs/store/change-metrics-storage.md) to learn more and
71 +use our the embedded database engine to figure out the exact settings you'll need to store historical metrics right in
72 +the Agent's database.
73
74 **What's next?**:
75
docs/guides/export/export-netdata-metrics-graphite.md
+1 -1
@@ -14,7 +14,7 @@ anomalies and discover root causes faster.
14 We designed Netdata with interoperability in mind. The Agent collects thousands of metrics every second, and then what
15 you do with them is up to you. You can [store metrics in the database engine](/docs/guides/longer-metrics-storage.md),
16 or send them to another time series database for long-term storage or further analysis using Netdata's [exporting
17 -engine](/docs/export/README.md).
17 +engine](/docs/export/external-databases.md).
18
19 In this guide, we'll show you how to export Netdata metrics to [Graphite](https://graphiteapp.org/) for long-term
20 storage and further analysis. Graphite is a free open-source software (FOSS) tool that collects graphs numeric
docs/guides/longer-metrics-storage.md
+5 -4
@@ -11,7 +11,7 @@ long term?
11
12 Many people think Netdata can only store about an hour's worth of real-time metrics, but that's simply not true any
13 more. With the right settings, Netdata is quite capable of efficiently storing hours or days worth of historical,
14 -per-second metrics without having to rely on an [exporting engine](/exporting/README.md).
14 +per-second metrics without having to rely on an [exporting engine](/docs/export/external-databases.md).
15
16 This guide gives two options for configuring Netdata to store more metrics. **We recommend the default [database
17 engine](#using-the-database-engine)**, but you can stick with or switch to the round-robin database if you prefer.
@@ -56,9 +56,10 @@ size` and `dbengine multihost disk space`.
56 compressed metrics. The default settings retain about two day's worth of metris on a system collecting 2,000 metrics
57 every second.
58
59 -[**See our database engine calculator**](https://learn.netdata.cloud/docs/agent/database/calculator) to help you
60 -correctly set `dbengine multihost disk space` based on your needs. The calculator gives an accurate estimate based on
61 -how many child nodes you have, how many metrics your Agent collects, and more.
59 +[**See our database engine
60 +calculator**](/docs/store/change-metrics-storage.md#calculate-the-system-resources-RAM-disk-space-needed-to-store-metrics)
61 +to help you correctly set `dbengine multihost disk space` based on your needs. The calculator gives an accurate estimate
62 +based on how many child nodes you have, how many metrics your Agent collects, and more.
63
64 With the database engine active, you can back up your `/var/cache/netdata/dbengine/` folder to another location for
65 redundancy.
docs/guides/monitor/pi-hole-raspberry-pi.md
+4 -3
@@ -136,9 +136,10 @@ more than 256.
136 dbengine multihost disk space = 512
137 ```
138
139 -Use our [database sizing calculator](https://learn.netdata.cloud/docs/agent/database/calculator) and [guide on storing
140 -historical metrics](/docs/guides/longer-metrics-storage.md) to help you determine the right setting for your Raspberry
141 -Pi.
139 +Use our [database sizing
140 +calculator](/docs/store/change-metrics-storage.md#calculate-the-system-resources-RAM-disk-space-needed-to-store-metrics)
141 +and [guide on storing historical metrics](/docs/guides/longer-metrics-storage.md) to help you determine the right
142 +setting for your Raspberry Pi.
143
144 ## What's next?
145
docs/guides/step-by-step/step-09.md
+3 -3
@@ -51,9 +51,9 @@ the database engine to use. The higher those values, the more metrics Netdata wi
51 512, respectively, the database engine should store about four day's worth of data on a system collecting 2,000 metrics
52 every second.
53
54 -[**See our database engine calculator**](https://learn.netdata.cloud/docs/agent/database/calculator) to help you
55 -correctly set `dbengine disk space` based on your needs. The calculator gives an accurate estimate based on how many
56 -child nodes you have, how many metrics your Agent collects, and more.
54 +[**See our database engine calculator**](/docs/store/change-metrics-storage.md) to help you correctly set `dbengine disk
55 +space` based on your needs. The calculator gives an accurate estimate based on how many child nodes you have, how many
56 +metrics your Agent collects, and more.
57
58 ```conf
59 [global]
docs/monitor/configure-alarms.md new
+144
@@ -0,0 +1,144 @@
1 +<!--
2 +title: "Configure health alarms"
3 +description: "Netdata's health monitoring watchdog is incredibly adaptable to your infrastructure's unique needs, with configurable health alarms."
4 +custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/monitor/configure-alarms.md
5 +-->
6 +
7 +# Configure health alarms
8 +
9 +Netdata's health watchdog is highly configurable, with support for dynamic thresholds, hysteresis, alarm templates, and
10 +more. You can tweak any of the existing alarms based on your infrastructure's topology or specific monitoring needs, or
11 +create new entities.
12 +
13 +You can use health alarms in conjunction with any of Netdata's [collectors](/docs/collect/how-collectors-work.md) (see
14 +the [supported collector list](/collectors/COLLECTORS.md)) to monitor the health of your systems, containers, and
15 +applications in real time.
16 +
17 +While you can see active alarms both on the local dashboard and Netdata Cloud, all health alarms are configured _per
18 +node_ via individual Netdata Agents. If you want to deploy a new alarm across your
19 +[infrastructure](/docs/quickstart/infrastructure.md), you must configure each node with the same health configuration
20 +files.
21 +
22 +## Edit health configuration files
23 +
24 +All of Netdata's [health configuration files](/health/REFERENCE.md#health-configuration-files) are in Netdata's config
25 +directory, inside the `health.d/` directory. Use Netdata's `edit-config` script to make changes to any of these files.
26 +
27 +For example, to edit the `cpu.conf` health configuration file, run:
28 +
29 +```bash
30 +sudo ./edit-config health.d/cpu.conf
31 +```
32 +
33 +Each health configuration file contains one or more health _entities_, which always begin with `alarm:` or `template:`.
34 +For example, here is the first health entity in `health.d/cpu.conf`:
35 +
36 +```yaml
37 +template: 10min_cpu_usage
38 + on: system.cpu
39 + os: linux
40 + hosts: *
41 + lookup: average -10m unaligned of user,system,softirq,irq,guest
42 + units: %
43 + every: 1m
44 + warn: $this > (($status >= $WARNING) ? (75) : (85))
45 + crit: $this > (($status == $CRITICAL) ? (85) : (95))
46 + delay: down 15m multiplier 1.5 max 1h
47 + info: average cpu utilization for the last 10 minutes (excluding iowait, nice and steal)
48 + to: sysadmin
49 +```
50 +
51 +To tune this alarm to trigger warning and critical alarms at a lower CPU utilization, change the `warn` and `crit` lines
52 +to the values of your choosing. For example:
53 +
54 +```yaml
55 + warn: $this > (($status >= $WARNING) ? (60) : (75))
56 + crit: $this > (($status == $CRITICAL) ? (75) : (85))
57 +```
58 +
59 +Save the file and [reload Netdata's health configuration](#reload-health-configuration) to make your changes live.
60 +
61 +### Silence an individual alarm
62 +
63 +Many Netdata users don't need all the default alarms enabled. Instead of disabling any given alarm, or even _all_
64 +alarms, you can silence individual alarms by changing one line in a given health entity.
65 +
66 +To silence any single alarm, change the `to:` line to `silent`.
67 +
68 +```yaml
69 + to: silent
70 +```
71 +
72 +## Write a new health entity
73 +
74 +While tuning existing alarms may work in some cases, you may need to write entirely new health entities based on how
75 +your systems and applications work.
76 +
77 +Read Netdata's [health reference](/health/REFERENCE.md#health-entity-reference) for a full listing of the format,
78 +syntax, and functionality of health entities.
79 +
80 +To write a new health entity, use `edit-config` to create a new file inside of the `health.d/` directory.
81 +
82 +```bash
83 +sudo ./edit-config health.d/example.conf
84 +```
85 +
86 +For example, here is a health entity that triggers an alarm when a node's RAM usage rises above 80%:
87 +
88 +```yaml
89 + alarm: ram_usage
90 + on: system.ram
91 +lookup: average -1m percentage of used
92 + units: %
93 + every: 1m
94 + warn: $this > 80
95 + crit: $this > 90
96 + info: The percentage of RAM being used by the system.
97 +```
98 +
99 +Let's look into each of the lines to see how they create a working health entity.
100 +
101 +- `alarm`: The name for your new entity. The name needs to follow these requirements:
102 + - Any alphabet letter or number.
103 + - The symbols `.` and `_`.
104 + - Cannot be `chart name`, `dimension name`, `family name`, or `chart variable names`.
105 +- `on`: Which chart the entity listens to.
106 +- `lookup`: Which metrics the alarm monitors, the duration of time to monitor, and how to process the metrics into a
107 + usable format.
108 + - `average`: Calculate the average of all the metrics collected.
109 + - `-1m`: Use metrics from 1 minute ago until now to calculate that average.
110 + - `percentage`: Clarify that we're calculating a percentage of RAM usage.
111 + - `of used`: Specify which dimension (`used`) on the `system.ram` chart you want to monitor with this entity.
112 +- `units`: Use percentages rather than absolute units.
113 +- `every`: How often to perform the `lookup` calculation to decide whether or not to trigger this alarm.
114 +- `warn`/`crit`: The value at which Netdata should trigger a warning or critical alarm. This example uses simple
115 + syntax, but most pre-configured health entities use
116 + [hysteresis](/health/REFERENCE.md#special-usage-of-the-conditional-operator) to avoid superfluous notifications.
117 +- `info`: A description of the alarm, which will appear in the dashboard and notifications.
118 +
119 +In human-readable format:
120 +
121 +> This health entity, named **ram_usage**, watches the **system.ram** chart. It looks up the last **1 minute** of
122 +> metrics from the **used** dimension and calculates the **average** of all those metrics in a **percentage** format,
123 +> using a **% unit**. The entity performs this lookup **every minute**.
124 +>
125 +> If the average RAM usage percentage over the last 1 minute is **more than 80%**, the entity triggers a warning alarm.
126 +> If the usage is **more than 90%**, the entity triggers a critical alarm.
127 +
128 +When you finish writing this new health entity, [reload Netdata's health configuration](#reload-health-configuration) to
129 +see it live on the local dashboard or Netdata Cloud.
130 +
131 +## Reload health configuration
132 +
133 +To make any changes to your health configuration live, you must reload Netdata's health monitoring system. To do that
134 +without restarting all of Netdata, run `netdatacli reload-health` or `killall -USR2 netdata`.
135 +
136 +## What's next?
137 +
138 +With your health entities configured properly, it's time to [enable
139 +notifications](/docs/monitor/enable-notifications.md) to get notified whenever a node reaches a warning or critical
140 +state.
141 +
142 +To build complex, dynamic alarms, read our guide on [dimension templates](/docs/guides/monitor/dimension-templates.md).
143 +
144 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fdocs%2Fmonitor%2Fview-active-alarms&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
docs/monitor/enable-notifications.md new
+126
@@ -0,0 +1,126 @@
1 +<!--
2 +title: "Enable notifications"
3 +description: "Send Netdata's alerts to platforms like email, Slack, PagerDuty, Twilio, and more to enable incident response and faster resolution."
4 +custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/monitor/enable-notifications.md
5 +-->
6 +
7 +# Enable notifications
8 +
9 +Netdata comes with a notification system that supports more than a dozen services, such as email, Slack, PagerDuty,
10 +Twilio, Amazon SNS, Discord, and much more. You can enable as many platforms as you want, and configure them to match
11 +your organization's needs with features like role-based notifications.
12 +
13 +To see all the supported platforms, visit our [notifications](/health/notifications/README.md) doc.
14 +
15 +This doc covers enabling email and Slack notifications, but the same process applies to enabling any other notification
16 +platform.
17 +
18 +## Enable email notifications
19 +
20 +To use email notifications, you need [`sendmail`](http://www.postfix.org/sendmail.1.html) or an equivalent installed on
21 +your system.
22 +
23 +Edit the `health_alarm_notify.conf` file, which resides in your Netdata [config
24 +directory](/docs/configure/nodes.md#netdata-config-directory).
25 +
26 +```bash
27 +sudo ./edit-config health_alarm_notify.conf
28 +```
29 +
30 +Look for the following lines:
31 +
32 +```conf
33 +# if a role recipient is not configured, an email will be sent to:
34 +DEFAULT_RECIPIENT_EMAIL="root"
35 +# to receive only critical alarms, set it to "root|critical"
36 +```
37 +
38 +Change the value of `DEFAULT_RECIPIENT_EMAIL` to the email address at which you'd like to receive notifications.
39 +
40 +```conf
41 +# if a role recipient is not configured, an email will be sent to:
42 +DEFAULT_RECIPIENT_EMAIL="me@example.com"
43 +# to receive only critical alarms, set it to "root|critical"
44 +```
45 +
46 +Test email notifications system by first becoming the Netdata user and then asking Netdata to send a test alarm:
47 +
48 +```bash
49 +sudo su -s /bin/bash netdata
50 +/usr/libexec/netdata/plugins.d/alarm-notify.sh test
51 +```
52 +
53 +You should see output similar to this:
54 +
55 +```bash
56 +# SENDING TEST WARNING ALARM TO ROLE: sysadmin
57 +2019-10-17 18:23:38: alarm-notify.sh: INFO: sent email notification for: hostname test.chart.test_alarm is WARNING to 'me@example.com'
58 +# OK
59 +
60 +# SENDING TEST CRITICAL ALARM TO ROLE: sysadmin
61 +2019-10-17 18:23:38: alarm-notify.sh: INFO: sent email notification for: hostname test.chart.test_alarm is CRITICAL to 'me@example.com'
62 +# OK
63 +
64 +# SENDING TEST CLEAR ALARM TO ROLE: sysadmin
65 +2019-10-17 18:23:39: alarm-notify.sh: INFO: sent email notification for: hostname test.chart.test_alarm is CLEAR to 'me@example.com'
66 +# OK
67 +```
68 +
69 +Check your email. You should receive three separate emails for each health status change: `WARNING`, `CRITICAL`, and
70 +`CLEAR`.
71 +
72 +See the [email notifications](/health/notifications/email/README.md) doc for more options and information.
73 +
74 +## Enable Slack notifications
75 +
76 +If you're one of the many who spend their workday getting pinged with GIFs by your colleagues, why not add Netdata
77 +notifications to the mix? It's a great way to immediately see, collaborate around, and respond to anomalies in your
78 +infrastructure.
79 +
80 +To get Slack notifications working, you first need to add an [incoming
81 +webhook](https://slack.com/apps/A0F7XDUAZ-incoming-webhooks) to the channel of your choice. Click the green **Add to
82 +Slack** button, choose the channel, and click the **Add Incoming WebHooks Integration** button.
83 +
84 +On the following page, you'll receive a **Webhook URL**. That's what you'll need to configure Netdata, so keep it handy.
85 +
86 +Time to dive back into your `health_alarm_notify.conf` file:
87 +
88 +```bash
89 +sudo ./edit-config health_alarm_notify.conf
90 +```
91 +
92 +Look for the `SLACK_WEBHOOK_URL=" "` line and add the incoming webhook URL you got from Slack:
93 +
94 +```conf
95 +SLACK_WEBHOOK_URL="https://hooks.slack.com/services/XXXXXXXXX/XXXXXXXXX/XXXXXXXXXXXX"
96 +```
97 +
98 +A few lines down, edit the `DEFAULT_RECIPIENT_SLACK` line to contain a single hash `#` character. This instructs Netdata
99 +to send a notification to the channel you configured with the incoming webhook.
100 +
101 +```conf
102 +DEFAULT_RECIPIENT_SLACK="#"
103 +```
104 +
105 +Time to test the notifications again:
106 +
107 +```bash
108 +sudo su -s /bin/bash netdata
109 +/usr/libexec/netdata/plugins.d/alarm-notify.sh test
110 +```
111 +
112 +You should receive three notifications in your Slack channel for each health status change: `WARNING`, `CRITICAL`, and
113 +`CLEAR`.
114 +
115 +See the [Slack notifications](/health/notifications/slack/README.md) doc for more options and information.
116 +
117 +## What's next?
118 +
119 +Learn more about Netdata's notifications system in the [notifications](/health/notifications/README.md) docs.
120 +
121 +Now that you have health entities configured to your infrastructure's needs, and notifications to inform you of
122 +anomalies, you have everything you need to monitor the health of your infrastructure. To make your dashboards most
123 +useful during root cause analysis, you can use Netdata's [distributed data
124 +architecture](/docs/store/distributed-data-architecture.md) for the best-in-class performance and scalability.
125 +
126 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fdocs%2Fmonitor%2Fenable-notifications&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
docs/monitor/view-active-alarms.md new
+76
@@ -0,0 +1,76 @@
1 +<!--
2 +title: "View active health alarms"
3 +description: "View active alarms and their rich data to discover and resolve anomalies and performance issues across your infrastructure."
4 +custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/monitor/view-active-alarms.md
5 +-->
6 +
7 +# View active health alarms
8 +
9 +Every Netdata Agent comes with hundreds of pre-installed health alarms designed to notify you when an anomaly or
10 +performance issue affects your node or the applications it runs.
11 +
12 +As soon as you launch a Netdata Agent and [claim it](/docs/get/README.md#claim-your-node-on-netdata-cloud), you can view
13 +active alarms in both the local dashboard and Netdata Cloud.
14 +
15 +## View active alarms in Netdata Cloud
16 +
17 +You can see active alarms from any node in your infrastructure in two ways: Click on the bell 🔔 icon in the top
18 +navigation, or click on the first column of any node's row in Nodes. This column's color changes based on the node's
19 +health status: gray is `CLEAR`, yellow is `WARNING`, and red is `CRITICAL`.
20 +
21 +![Screenshot from 2020-09-17
22 +17-21-24](https://user-images.githubusercontent.com/1153921/93541137-70761f00-f90a-11ea-89ef-7948c6213200.png)
23 +
24 +The Alarms panel lists all active alarms for nodes within that War Room, and tells you which chart triggered the alarm,
25 +what that chart's current value is, the alarm that triggered it, and when the alarm status first began.
26 +
27 +You can use the input field in the Alarms panel to filter active alarms. You can sort by the node's name, alarm, status,
28 +chart that triggered the alarm, or the operating system. Read more about the [filtering
29 +syntax](/docs/visualize/view-all-nodes.md#filter-and-group-your-infrastructure) to build valuable filters for your
30 +infrastructure.
31 +
32 +Click on the 3-dot icon (`⋮`) to view active alarm information or navigate directly to the offending chart in that
33 +node's Cloud dashboard with the **Go to chart** button.
34 +
35 +The active alarm information gives you in-depth information about the alarm that's been triggered. You can see the
36 +alarm's configuration, how it calculates warning or critical alarms, and which configuration file you could edit on that
37 +node if you want to tweak or disable the alarm to better suit your needs.
38 +
39 +![Screenshot from 2020-09-17
40 +17-21-29](https://user-images.githubusercontent.com/1153921/93541139-710eb580-f90a-11ea-809d-25afe1270108.png)
41 +
42 +## View active alarms in the Netdata Agent
43 +
44 +Find the bell 🔔 icon in the top navigation to bring up a modal that shows currently raised alarms, all running alarms,
45 +and the alarms log. Here is an example of a raised `system.cpu` alarm, followed by the full list and alarm log:
46 +
47 +![Animated GIF of looking at raised alarms and the alarm
48 +log](https://user-images.githubusercontent.com/1153921/80842482-8c289500-8bb6-11ea-9791-600cfdbe82ce.gif)
49 +
50 +And a static screenshot of the raised CPU alarm:
51 +
52 +![Screenshot of a raised system CPU
53 +alarm](https://user-images.githubusercontent.com/1153921/80842330-2dfbb200-8bb6-11ea-8147-3cd366eb0f37.png)
54 +
55 +The alarm itself is named **system - cpu**, and its context is `system.cpu`. Beneath that is an auto-updating badge that
56 +shows the latest value of the chart that triggered the alarm.
57 +
58 +With the three icons beneath that and the **role** designation, you can:
59 +
60 +1. Scroll to the chart associated with this raised alarm.
61 +2. Copy a link to the badge to your clipboard.
62 +3. Copy the code to embed the badge onto another web page using an `<embed>` element.
63 +
64 +The table on the right-hand side displays information about the health entity that triggered the alarm, which you can
65 +use as a reference to [configure alarms](/docs/monitor/configure-alarms.md).
66 +
67 +## What's next?
68 +
69 +With the information that appears on Netdata Cloud and the local dashboard about active alarms, you can [configure
70 +alarms](/docs/monitor/configure-alarms.md) to match your infrastructure's needs or your team's goals.
71 +
72 +If you're happy with the pre-configured alarms, skip ahead to [enable
73 +notifications](/docs/monitor/enable-notifications.md) to instantly see alarms in email, Slack, PagerDuty, Twilio, and
74 +many other platforms.
75 +
76 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fdocs%2Fmonitor%2Fview-active-alarms&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
docs/overview/netdata-monitoring-stack.md new
+62
@@ -0,0 +1,62 @@
1 +<!--
2 +title: "Use Netdata standalone or as part of your monitoring stack"
3 +description: "Netdata can run independently or as part of a larger monitoring stack thanks to its flexibility, interoperable core, and exporting features."
4 +custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/overview/netdata-monitoring-stack.md
5 +-->
6 +
7 +# Use Netdata standalone or as part of your monitoring stack
8 +
9 +Netdata is an extremely powerful monitoring, visualization, and troubleshooting platform. While you can use it as an
10 +effective standalone tool, we also designed it to be open and interoperable with other tools you might already be using.
11 +
12 +Netdata helps you collect everything and scales to infrastructure of any size, but it doesn't lock-in data or force you
13 +to use specific tools or methodologies. Each feature is extensible and interoperable so they can work in parallel with
14 +other tools. For example, you can use Netdata to collect metrics, visualize metrics with a second open-source program,
15 +and centralize your metrics in a cloud-based time-series database solution for long-term storage or further analysis.
16 +
17 +You can build a new monitoring stack, including Netdata, or integrate Netdata's metrics with your existing monitoring
18 +stack. No matter which route you take, Netdata helps you monitor infrastructure of any size.
19 +
20 +Here are a few ways to enrich your existing monitoring and troubleshooting stack with Netdata:
21 +
22 +## Collect metrics from Prometheus endpoints
23 +
24 +Netdata automatically detects 600 popular endpoints and collects per-second metrics from them via the [generic
25 +Prometheus collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/prometheus). This even
26 +includes support for Windows 10 via [`windows_exporter`](https://github.com/prometheus-community/windows_exporter).
27 +
28 +This collector is installed and enabled on all Agent installations by default, so you don't need to waste time
29 +configuring Netdata. Netdata will detect these Prometheus metrics endpoints and collect even more granular metrics than
30 +your existing solutions. You can now use all of Netdata's meaningfully-visualized charts to diagnose issues and
31 +troubleshoot anomalies.
32 +
33 +## Export metrics to external time-series databases
34 +
35 +Netdata can send its per-second metrics to external time-series databases, such as InfluxDB, Prometheus, Graphite,
36 +TimescaleDB, ElasticSearch, AWS Kinesis Data Streams, Google Cloud Pub/Sub Service, and many others.
37 +
38 +To [export metrics to external time-series databases](/docs/export/external-databases.md), you configure an [exporting
39 +_connector_](/docs/export/enable-connector.md). These connectors support filtering and resampling for granular control
40 +over which metrics you export, and at what volume. You can export resampled metrics as collected, as averages, or the
41 +sum of interpolated values based on your needs and other monitoring tools.
42 +
43 +Once you have Netdata's metrics in a secondary time-series database, you can use them however you'd like, such as
44 +additional visualization/dashboarding tools or aggregation of data from multiple sources.
45 +
46 +## Visualize metrics with Grafana
47 +
48 +One popular monitoring stack is Netdata, Graphite, and Grafana. Netdata acts as the stack's metrics collection
49 +powerhouse, Graphite the time-series database, and Grafana the visualization platform. With Netdata at the core, you can
50 +be confident that your monitoring stack is powered by all possible metrics, from all possible sources, from every node
51 +in your infrastructure.
52 +
53 +Of course, just because you export or visualize metrics elsewhere, it doesn't mean Netdata's equivalent features
54 +disappear. You can always build new dashboards in Netdata Cloud, drill down into per-second metrics using Netdata's
55 +charts, or use Netdata's health watchdog to send notifications whenever an anomaly strikes.
56 +
57 +## What's next?
58 +
59 +Whether you're using Netdata standalone or as part of a larger monitoring stack, the next step is the same: [**Get
60 +Netdata**](/docs/get/README.md).
61 +
62 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fdocs%2Foverview%2Fnetdata-monitoring-stacka&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
docs/overview/what-is-netdata.md new
+75
@@ -0,0 +1,75 @@
1 +<!--
2 +title: "What is Netdata?"
3 +description: "Netdata is distributed, real-time performance and health monitoring for systems and applications on a single node or an entire infrastructure."
4 +custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/overview/what-is-netdata.md
5 +-->
6 +
7 +# What is Netdata?
8 +
9 +Netdata helps sysadmins, SREs, DevOps engineers, and IT professionals collect all possible metrics from systems and
10 +applications, visualize these metrics in real-time, and troubleshoot complex performance problems.
11 +
12 +Netdata's solution uses two components, the Netdata Agent and Netdata Cloud, to deliver real-time performance and health
13 +monitoring for both single nodes and entire infrastructures.
14 +
15 +## Netdata Agent
16 +
17 +Netdata's distributed monitoring Agent collects thousands of metrics from systems, hardware, and applications with zero
18 +configuration. It runs permanently on all your physical/virtual servers, containers, cloud deployments, and edge/IoT
19 +devices.
20 +
21 +You can install Netdata on most Linux distributions (Ubuntu, Debian, CentOS, and more), container/microservice platforms
22 +(Kubernetes clusters, Docker), and many other operating systems (FreeBSD, macOS), with no `sudo` required.
23 +
24 +![The Netdata
25 +Agent](https://user-images.githubusercontent.com/1153921/94492596-72a86b00-019f-11eb-91ab-224e6ac9ea21.png)
26 +
27 +## Netdata Cloud
28 +
29 +Netdata Cloud is a web application that gives you real-time visibility for your entire infrastructure. With Netdata
30 +Cloud, you can view key metrics, insightful charts, and active alarms from all your nodes in a single web interface.
31 +When an anomaly strikes, seamlessly navigate to any node to troubleshoot and discover the root cause with the familiar
32 +Netdata dashboard.
33 +
34 +**[Netdata Cloud is
35 +free](https://learn.netdata.cloud/docs/cloud/faq-glossary#how-much-does-netdata-cost-how-and-why-is-it-free)**! You can
36 +add an entire infrastructure of nodes, invite all your colleagues, and visualize any number of metrics, charts, and
37 +alarms entirely for free.
38 +
39 +While Netdata Cloud offers a centralized method of monitoring your Agents, your metrics data is not stored or
40 +centralized in any way. Metrics data remains with your nodes and is only streamed to your browser, through Cloud, when
41 +you're viewing the Netdata Cloud interface.
42 +
43 +![Netdata Cloud](https://user-images.githubusercontent.com/1153921/94492597-73410180-019f-11eb-9a9e-032420baa489.png)
44 +
45 +## What you can do with Netdata
46 +
47 +Netdata is designed to be both simple to use and flexible for every monitoring, visualization, and troubleshooting use
48 +case:
49 +
50 +- **Collect**: Netdata collects all available metrics from your system and applications with 300+ collectors,
51 + Kubernetes service discovery, and in-depth container monitoring, all while using only 1% CPU and a few MB of RAM. It
52 + even collects metrics from Windows machines.
53 +- **Visualize**: The dashboard meaningfully presents charts to help you understand the relationships between your
54 + hardware, operating system, running apps/services, and the rest of your infrastructure. Add nodes to Netdata Cloud
55 + for a complete view of your infrastructure from a single pane of glass.
56 +- **Monitor**: Netdata's health watchdog uses hundreds of preconfigured alarms to notify you via Slack, email,
57 + PagerDuty and more when an anomaly strikes. Customize with dynamic thresholds, hysteresis, alarm templates, and
58 + role-based notifications.
59 +- **Troubleshoot**: 1s granularity helps you detect analyze anomalies other monitoring platforms might have missed.
60 + Interactive visualizations reduce your reliance on the console, and historical metrics help you trace issues back to
61 + their root cause.
62 +- **Store**: Netdata's efficient database engine efficiently stores per-second metrics for days, weeks, or even
63 + months. Every distributed node stores metrics locally, simplifying deployment, slashing costs, and enriching
64 + Netdata's interactive dashboards.
65 +- **Export**: Integrate per-second metrics with other time-series databases like Graphite, Prometheus, InfluxDB,
66 + TimescaleDB, and more with Netdata's interoperable and extensible core.
67 +- **Stream**: Aggregate metrics from any number of distributed nodes in one place for in-depth analysis, including
68 + ephemeral nodes in a Kubernetes cluster.
69 +
70 +## What's next?
71 +
72 +Learn more about [why you should use Netdata](/docs/overview/why-netdata.md), or [how Netdata works with your existing
73 +monitoring stack](/docs/overview/netdata-monitoring-stack.md).
74 +
75 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fdocs%2Foverview%2Fwhat-is-netdata&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
docs/overview/why-netdata.md new
+63
@@ -0,0 +1,63 @@
1 +<!--
2 +title: "Why use Netdata?"
3 +description: "Netdata is simple to deploy, scalable, and optimized for troubleshooting. Cut the complexity and expense out of your monitoring stack."
4 +custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/overview/why-netdata.md
5 +-->
6 +
7 +# Why use Netdata?
8 +
9 +Netdata takes a different approach to helping people build extraordinary infrastructure. It was built out of frustration
10 +with existing monitoring tools that are too complex, too expensive, and don't help their users actually troubleshoot
11 +complex performance and health issues.
12 +
13 +Netdata is:
14 +
15 +## Simple to deploy
16 +
17 +- **One-line deployment** for Linux distributions, plus support for Kubernetes/Docker infrastructures
18 +- **Zero configuration and maintenance** required to collect thousands of metrics, every second, from the underlying
19 + OS and running applications.
20 +- **Prebuilt charts and alarms** alert you to common anomalies and performance issues without manual configuration.
21 +- **Distributed storage** to simplify the cost and complexity of storing metrics data from any number of nodes.
22 +
23 +## Powerful and scalable
24 +
25 +- **1% CPU utilization, a few MB of RAM, and minimal disk I/O** to run the monitoring Agent on bare metal, virtual
26 + machines, containers, and even IoT devices.
27 +- **Per-second granularity** for an unlimited number of metrics based on the hardware and applications you're running
28 + on your nodes.
29 +- **Interoperable exporters** let you connect Netdata's per-second metrics with an existing monitoring stack and other
30 + time-series databases.
31 +
32 +## Optimized for troubleshooting
33 +
34 +- **Visual anomaly detection** with a UI/UX that emphasizes the relationships between charts.
35 +- **Customizable dashboards** to pinpoint correlated metrics, respond to incidents, and help you streamline your
36 + workflows.
37 +- **Distributed metrics in a centralized interface** to assist users or teams trace complex issues between distributed
38 + nodes.
39 +
40 +## Comparison with other monitoring solutions
41 +
42 +Netdata offers many benefits over the existing monitoring landscape, whether they're expensive SaaS products or other
43 +open-source tools.
44 +
45 +| Netdata | Others (open-source and commercial) |
46 +| :-------------------------------------------------------------- | :--------------------------------------------------------------- |
47 +| **High resolution metrics** (1s granularity) | Low resolution metrics (10s granularity at best) |
48 +| Collects **thousands of metrics per node** | Collects just a few metrics |
49 +| Fast UI optimized for **anomaly detection** | UI is good for just an abstract view |
50 +| **Long-term, autonomous storage** at one-second granularity | Centralized metrics in an expensive data lake at 10s granularity |
51 +| **Meaningful presentation**, to help you understand the metrics | You have to know the metrics before you start |
52 +| Install and get results **immediately** | Long sales process and complex installation process |
53 +| Use it for **troubleshooting** performance problems | Only gathers _statistics of past performance_ |
54 +| **Kills the console** for tracing performance issues | The console is always required for troubleshooting |
55 +| Requires **zero dedicated resources** | Require large dedicated resources |
56 +
57 +## What's next?
58 +
59 +Whether you already have a monitoring stack you want to integrate Netdata into, or are building something from the
60 +ground-up, you should read more on how Netdata can work either [standalone or as an interoperable part of a monitoring
61 +stack](/docs/overview/netdata-monitoring-stack.md).
62 +
63 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fdocs%2Foverview%2Fwhy-netdata&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
docs/quickstart/infrastructure.md new
+126
@@ -0,0 +1,126 @@
1 +<!--
2 +title: "Infrastructure monitoring with Netdata"
3 +sidebar_label: "Infrastructure monitoring"
4 +description: "Build a robust, infinitely scalable infrastructure monitoring solution with Netdata. Any number of nodes and every available metric."
5 +custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/quickstart/infrastructure.md
6 +-->
7 +
8 +# Infrastructure monitoring with Netdata
9 +
10 +Together, the Netdata Agent and Netdata Cloud create a powerful, infinitely-scalable infrastructure monitoring solution.
11 +
12 +The Netdata Agent uses zero-configuration collectors to gather metrics from every application and container instantly.
13 +The distributed data model lets you monitor everything without a slow and troublesome centralized data lake for your
14 +infrastructure's metrics, reducing the resources you need to invest in metrics retention. Netdata Cloud unifies all the
15 +metrics from these distributed nodes on customizable, interactive, and real-time visualizations.
16 +
17 +In this quickstart guide, you'll learn how to see key metrics from all your nodes in one interface and build your first
18 +dashboard for aggregating like metrics from many distributed nodes. You'll then take a peek into configuring individual
19 +nodes and get helpful pointers about collecting all the metrics from every critical application in your infrastructure.
20 +
21 +> This quickstart assumes you've installed the Netdata Agent on more than one node in your infrastructure, and claimed
22 +> that node to your Space in Netdata Cloud. If you haven't yet, see the [_Get Netdata_ doc](/docs/get/README.md) for
23 +> details on installation and claiming.
24 +
25 +## See your infrastructure's metrics
26 +
27 +To see all your nodes from a single pane of glass, first [sign in](https://app.netdata.cloud) to Netdata Cloud. As you
28 +sign in, Netdata Cloud pings each claimed node to start on-demand streaming from your nodes to your browser. When
29 +Netdata Cloud loads your War Room's **Nodes** view, you'll immediately see key metrics from your nodes, streamed in
30 +real time, in a single interface.
31 +
32 +![Animated GIF of Netdata
33 +Cloud](https://user-images.githubusercontent.com/1153921/80828986-1ebb3b00-8b9b-11ea-957f-2c8d0d009e44.gif)
34 +
35 +You can drill down into any node's full dashboard by clicking on that node's hostname in the Nodes view.
36 +
37 +![Screenshot of an embedded node
38 +dashboard](https://user-images.githubusercontent.com/1153921/87457036-9b678e00-c5bc-11ea-977d-ad561a73beef.png)
39 +
40 +You can use single-node dashboards in Netdata Cloud to drill down on specific issues, scrub backward in time to
41 +investigate historical data, and see like metrics presented meaningfully to help you troubleshoot performance problems.
42 +Learn about [interacting with dashboards and charts](/docs/visualize/interact-dashboards-charts.md) to get the most from
43 +all of Netdata's real-time metrics.
44 +
45 +> If you want to monitor a Kubernetes cluster with Netdata, see our [k8s installation
46 +> doc](/packaging/installer/methods/kubernetes.md) for setup details, and then read our guide, [_Monitor a Kubernetes
47 +> cluster with Netdata_](/docs/guides/monitor/kubernetes-k8s-netdata.md).
48 +
49 +## Build new dashboards for your infrastructure
50 +
51 +You can use Netdata Cloud to build new dashboards that match your infrastructure's topology or help you diagnose complex
52 +issues by aggregating correlated charts from any number of nodes.
53 +
54 +To build your first dashboard, click on the **Nodes** dropdown, then select **+ Add**. Enter a name to assign to this
55 +dashboard. Click on either of the **Add chart** buttons, then select the node you want to add a chart from. Select the
56 +context, which is Netdata's way to organize charts, and then click **Add chart**.
57 +
58 +Once you add a few charts, you can move them around, resize them, and add text. Make sure you click the **Save** button
59 +before you navigate away.
60 +
61 +Read more about [creating new dashboards](/docs/visualize/create-dashboards.md) for more details about the process and
62 +additional tips on best leveraging the feature to help you troubleshoot complex performance problems.
63 +
64 +## Configure your nodes
65 +
66 +You can configure any node in your infrastructure if you need to, although most users will find the default settings
67 +work extremely well for monitoring their infrastructures.
68 +
69 +Each node has a configuration file called `netdata.conf`, which is typically at `/etc/netdata/netdata.conf`. The best
70 +way to edit this file is using the `edit-config` script, which ensures updates to the Netdata Agent do not overwrite
71 +your changes. For example:
72 +
73 +```bash
74 +cd /etc/netdata
75 +sudo ./edit-config netdata.conf
76 +```
77 +
78 +Our [configuration basics doc](/docs/configure/nodes.md) contains more information about `netdata.conf`, `edit-config`,
79 +along with simple examples to get you familiar with editing your node's configuration.
80 +
81 +After you've learned the basics, you should [secure your infrastructure's nodes](/docs/configure/secure-nodes.md) using
82 +one of our recommended methods. These security best practices ensure no untrusted parties gain access to the metrics
83 +collected on any of your nodes.
84 +
85 +## Collect metrics from your systems and applications
86 +
87 +Netdata has [300+ pre-installed collectors](/collectors/COLLECTORS.md) that gather thousands of metrics with zero
88 +configuration. Collectors search each of your nodes in default locations and ports to find running applications and
89 +gather as many metrics as they can without you having to configure them individually.
90 +
91 +In fact, Netdata is already collecting thousands of metrics per second from your webservers, databases, containers, and
92 +much more, on each node in your infrastructure.
93 +
94 +These metrics enrich your Netdata Cloud experience. You can see metrics from systems, containers, and applications in
95 +the individual node dashboards, and you can create new dashboards around very specific charts, such as the real-time
96 +volume of 503 responses from each of your webserver nodes.
97 +
98 +Most collectors work without configuration, but you should read up on [how collectors
99 +work](/docs/collect/how-collectors-work.md) and [how to enable/configure](/docs/collect/enable-configure.md) them.
100 +
101 +In addition, find detailed information about which [system](/docs/collect/system-metrics.md),
102 +[container](/docs/collect/container-metrics.md), and [application](/docs/collect/application-metrics.md) metrics you can
103 +collect from across your infrastructure with Netdata.
104 +
105 +## What's next?
106 +
107 +Netdata has many features that help you monitor the health of your nodes and troubleshoot complex performance problems.
108 +Once you have a handle on configuration and are collecting all the right metrics, try out some of Netdata's other
109 +infrastructure-focused features:
110 +
111 +- [Organize your nodes](/docs/configure/spaces-war-rooms.md) into **War Rooms** based on your preferred strategy.
112 +- [Invite your team](/docs/configure/invite-collaborate.md) to collaborate on identifying anomalies or troubleshooting
113 + complex performance problems.
114 +- [Export metrics](/docs/export/external-databases.md) to an external time-series database to use Netdata alongside
115 + other monitoring and troubleshooting tools.
116 +
117 +To change how the Netdata Agent runs on each node, dig in to configuration files:
118 +
119 +- [Change how long nodes in your infrastructure retain metrics](/docs/store/change-metrics-storage.md) based on how
120 + many metrics each node collects, your preferred retention period, and the resources you want to dedicate toward
121 + long-term metrics retention.
122 +- [Create new alarms](/docs/monitor/configure-alarms.md), or tweak some of the pre-configured alarms, to stay on top
123 + of anomalies.
124 +- [Enable notifications](/docs/monitor/enable-notifications.md) to Slack, PagerDuty, email, and 30+ other services.
125 +
126 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fdocs%2Fquickstart%2Finfrastructure&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
docs/quickstart/single-node.md new
+96
@@ -0,0 +1,96 @@
1 +<!--
2 +title: "Single-node monitoring with Netdata"
3 +sidebar_label: "Single-node monitoring"
4 +description: "Learn dashboard basics, configuring your nodes, and collecting metrics from applications to create a powerful single-node monitoring tool."
5 +custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/quickstart/single-node.md
6 +-->
7 +
8 +# Single-node monitoring with Netdata
9 +
10 +Because it's free, open-source, and requires only 1% CPU utilization to collect thousands of metrics every second,
11 +Netdata is a superb single-node monitoring tool.
12 +
13 +In this quickstart guide, you'll learn how to access your single node's metrics through dashboards, configure your node
14 +to your liking, and make sure the Netdata Agent is collecting metrics from the applications or containers you're running
15 +on your node.
16 +
17 +> This quickstart assumes you have installed the Netdata Agent on your node. If you haven't yet, see the [_Get Netdata_
18 +> doc](/docs/get/README.md) for details on installation. In addition, this quickstart mentions features available only
19 +> through Netdata Cloud, which requires you to [claim your node](/docs/get/README.md#claim-your-node-on-netdata-cloud).
20 +
21 +## See your node's metrics
22 +
23 +To see your node's real-time metrics, you need to access its dashboard. You can either view the local dashboard, which
24 +runs on the node itself, or see the dashboard through Netdata Cloud. Both methods feature real-time, interactive, and
25 +synchronized charts, with the same metrics, and use the same UI.
26 +
27 +The primary difference is that Netdata Cloud also has a few extra features, like creating new dashboards using a
28 +drag-and-drop editor, that enhance your monitoring and troubleshooting experience.
29 +
30 +To see your node's local dashboard, open up your web browser of choice and navigate to `http://NODE:19999`, replacing
31 +`NODE` with the IP address or hostname of your Agent. Hit `Enter`.
32 +
33 +![Animated GIF of navigating to the
34 +dashboard](https://user-images.githubusercontent.com/1153921/80825153-abaec600-8b94-11ea-8b17-1b770a2abaa9.gif)
35 +
36 +To see a node's dashboard in Netdata Cloud, [sign in](https://app.netdata.cloud). From the **Nodes** view in your
37 +**General** War Room, click on the hostname of your node to access its dashboard through Netdata Cloud.
38 +
39 +![Screenshot of an embedded node
40 +dashboard](https://user-images.githubusercontent.com/1153921/87457036-9b678e00-c5bc-11ea-977d-ad561a73beef.png)
41 +
42 +Once you've decided which dashboard you prefer, learn about [interacting with dashboards and
43 +charts](/docs/visualize/interact-dashboards-charts.md) to get the most from Netdata's real-time metrics.
44 +
45 +## Configure your node
46 +
47 +The Netdata Agent is highly configurable so that you can match its behavior to your node. You will find most
48 +configuration options in the `netdata.conf` file, which is typically at `/etc/netdata/netdata.conf`. The best way to
49 +edit this file is using the `edit-config` script, which ensures updates to the Netdata Agent do not overwrite your
50 +changes. For example:
51 +
52 +```bash
53 +cd /etc/netdata
54 +sudo ./edit-config netdata.conf
55 +```
56 +
57 +Our [configuration basics doc](/docs/configure/nodes.md) contains more information about `netdata.conf`, `edit-config`,
58 +along with simple examples to get you familiar with editing your node's configuration.
59 +
60 +After you've learned the basics, you should [secure your node](/docs/configure/secure-nodes.md) using one of our
61 +recommended methods. These security best practices ensure no untrusted parties gain access to your dashboard or its
62 +metrics.
63 +
64 +## Collect metrics from your system and applications
65 +
66 +Netdata has [300+ pre-installed collectors](/collectors/COLLECTORS.md) that gather thousands of metrics with zero
67 +configuration. Collectors search your node in default locations and ports to find running applications and gather as
68 +many metrics as possible without you having to configure them individually.
69 +
70 +These metrics enrich both the local and Netdata Cloud dashboards.
71 +
72 +Most collectors work without configuration, but you should read up on [how collectors
73 +work](/docs/collect/how-collectors-work.md) and [how to enable/configure](/docs/collect/enable-configure.md) them.
74 +
75 +In addition, find detailed information about which [system](/docs/collect/system-metrics.md),
76 +[container](/docs/collect/container-metrics.md), and [application](/docs/collect/application-metrics.md) metrics you can
77 +collect from across your infrastructure with Netdata.
78 +
79 +## What's next?
80 +
81 +Netdata has many features that help you monitor the health of your node and troubleshoot complex performance problems.
82 +Once you understand configuration, and are certain Netdata is collecting all the important metrics from your node, try
83 +out some of Netdata's other visualization and health monitoring features:
84 +
85 +- [Build new dashboards](/docs/visualize/create-dashboards.md) to put disparate but relevant metrics onto a single
86 + interface.
87 +- [Create new alarms](/docs/monitor/configure-alarms.md), or tweak some of the pre-configured alarms, to stay on top
88 + of anomalies.
89 +- [Enable notifications](/docs/monitor/enable-notifications.md) to Slack, PagerDuty, email, and 30+ other services.
90 +- [Change how long your node stores metrics](/docs/store/change-metrics-storage.md) based on how many metrics it
91 + collects, your preferred retention period, and the resources you want to dedicate toward long-term metrics
92 + retention.
93 +- [Export metrics](/docs/export/external-databases.md) to an external time-series database to use Netdata alongside
94 + other monitoring and troubleshooting tools.
95 +
96 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fdocs%2Fquickstart%2Fsingle-node&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
docs/store/change-metrics-storage.md new
+72
@@ -0,0 +1,72 @@
1 +<!--
2 +title: "Change how long Netdata stores metrics"
3 +description: "With a single configuration change, the Netdata Agent can store days, weeks, or months of metrics at its famous per-second granularity."
4 +custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/store/change-metrics-storage.md
5 +-->
6 +
7 +# Change how long Netdata stores metrics
8 +
9 +import { Calculator } from '../../src/components/agent/dbCalc/'
10 +
11 +The [database engine](/database/engine/README.md) uses RAM to store recent metrics. When metrics reach a certain age,
12 +and based on how much system RAM you allocate toward storing metrics in memory, they are compressed and "spilled" to
13 +disk for long-term storage.
14 +
15 +The default settings retain about two day's worth of metrics on a system collecting 2,000 metrics every second, but the
16 +Netdata Agent is highly configurable if you want your nodes to store days, weeks, or months worth of per-second data.
17 +
18 +The Netdata Agent uses two settings in `netdata.conf` to change the behavior of the database engine:
19 +
20 +```conf
21 +[global]
22 + page cache size = 32
23 + dbengine multihost disk space = 256
24 +```
25 +
26 +`page cache size` sets the maximum amount of RAM (in MiB) the database engine uses to cache and index recent metrics.
27 +`dbengine multihost disk space` sets the maximum disk space (again, in MiB) the database engine uses to store
28 +historical, compressed metrics. When the size of stored metrics exceeds the allocated disk space, the database engine
29 +removes the oldest metrics on a rolling basis.
30 +
31 +## Calculate the system resources (RAM, disk space) needed to store metrics
32 +
33 +You can store more or less metrics using the database engine by changing the allocated disk space. Use the calculator
34 +below to find an appropriate value for `dbengine multihost disk space` based on how many metrics your node(s) collect,
35 +whether you are streaming metrics to a parent node, and more.
36 +
37 +You do not need to edit the `page cache size` setting to store more metrics using the database engine. However, if you
38 +want to store more metrics _specifically in memory_, you can increase the cache size.
39 +
40 +> ⚠️ This calculator provides an estimate of disk and RAM usage for **metrics storage**, along with its best
41 +> recommendation for the `dbengine multihost disk space` setting. Real-life usage may vary based on the accuracy of the
42 +> values you enter below, changes in the compression ratio, and the types of metrics stored.
43 +
44 +<Calculator />
45 +
46 +## Edit `netdata.conf` with recommended database engine settings
47 +
48 +Now that you have a recommended setting for `dbengine multihost disk space`, open `netdata.conf` with
49 +[`edit-config`](/docs/configure/nodes.md#use-edit-config-to-edit-netdataconf) and look for the `dbengine multihost disk
50 +space` setting. Change it to the value recommended above. For example:
51 +
52 +```conf
53 +[global]
54 + dbengine multihost disk space = 1024
55 +```
56 +
57 +Save the file and restart the Agent with `service netdata restart` to change the database engine's size.
58 +
59 +## What's next?
60 +
61 +For more information about the database engine, see our [database reference doc](/database/engine/README.md).
62 +
63 +Storing metrics with the database engine is completely interoperable with [exporting to other time-series
64 +databases](/docs/export/external-databases.md). With exporting, you can use the node's resources to surface metrics
65 +when [viewing dashboards](/docs/visualize/interact-dashboards-charts.md), while also archiving metrics elsewhere for
66 +further analysis, visualization, or correlation with other tools.
67 +
68 +If you don't want to always store metrics on the node that collects them or run ephemeral nodes without dedicated
69 +storage, you can use [streaming](/streaming/README.md). Streaming allows you to centralize your data, run Agents as
70 +headless collectors, replicate data, and more.
71 +
72 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fdocs%2Fstore%2Fchange-metrics-storage&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
docs/store/distributed-data-architecture.md new
+71
@@ -0,0 +1,71 @@
1 +<!--
2 +title: "Distributed data architecture"
3 +description: "Netdata's distributed data architecture stores metrics on individual nodes for high performance and scalability using all your granular metrics."
4 +custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/store/distributed-data.md
5 +-->
6 +
7 +# Distributed data architecture
8 +
9 +Netdata uses a distributed data architecture to help you collect and store per-second metrics from any number of nodes.
10 +Every node in your infrastructure, whether it's one or a thousand, stores the metrics it collects.
11 +
12 +Netdata Cloud bridges the gap between many distributed databases by _centralizing the interface you use_ to query and
13 +visualize your nodes' metrics. When you [look at charts in Netdata
14 +Cloud](/docs/visualize/interact-dashboards-charts.md), the metrics values are queried directly from that node's database
15 +and securely streamed to Netdata Cloud, which proxies them to your browser.
16 +
17 +Netdata's distributed data architecture has a number of benefits:
18 +
19 +- **Performance**: Every query to a node's database takes only a few milliseconds to complete for responsiveness when
20 + viewing dashboards or using features like [Metric
21 + Correlations](https://learn.netdata.cloud/docs/cloud/insights/metric-correlations).
22 +- **Scalability**: As your infrastructure scales, install the Netdata Agent on every new node to immediately add it to
23 + your monitoring solution without adding cost or complexity.
24 +- **1-second granularity**: Without an expensive centralized data lake, you can store all of your nodes' per-second
25 + metrics, for any period of time, while keeping costs down.
26 +- **No filtering or selecting of metrics**: Because Netdata's distributed data architecture allows you to store all
27 + metrics, you don't have to configure which metrics you retain. Keep everything for full visibility during
28 + troubleshooting and root cause analysis.
29 +- **Easy maintenance**: There is no centralized data lake to purchase, allocate, monitor, and update, removing
30 + complexity from your monitoring infrastructure.
31 +
32 +## Does Netdata Cloud store my metrics?
33 +
34 +Netdata Cloud does not store metric values.
35 +
36 +To enable certain features, such as [viewing active alarms](/docs/monitor/view-active-alarms.md) or [filtering by
37 +service](/docs/visualize/view-all-nodes.md#filter-and-group-your-infrastructure), Netdata Cloud does store configured
38 +alarms, their status, and a list of active collectors.
39 +
40 +Netdata does not and never will sell your personal data or data about your deployment.
41 +
42 +## Long-term metrics storage with Netdata
43 +
44 +Any node running the Netdata Agent can store long-term metrics for any retention period, given you allocate the
45 +appropriate amount of RAM and disk space.
46 +
47 +Read our document on changing [how long Netdata stores metrics](/docs/store/change-metrics-storage.md) on your nodes for
48 +details.
49 +
50 +## Other options for your metrics data
51 +
52 +While a distributed data architecture is the default when monitoring infrastructure with Netdata, you can also configure
53 +its behavior based on your needs or the type of infrastructure you manage.
54 +
55 +To archive metrics to an external time-series database, such as InfluxDB, Graphite, OpenTSDB, Elasticsearch,
56 +TimescaleDB, and many others, see details on [integrating Netdata via exporting](/docs/export/external-databases.md).
57 +
58 +You can also stream between nodes using [streaming](/streaming/README.md), allowing to replicate databases and create
59 +your own centralized data lake of metrics, if you choose to do so.
60 +
61 +When you use the database engine to store your metrics, you can always perform a quick backup of a node's
62 +`/var/cache/netdata/dbengine/` folder using the tool of your choice.
63 +
64 +## What's next?
65 +
66 +You can configure the Netdata Agent to store days, weeks, or months worth of distributed, per-second data by
67 +[configuring the database engine](/docs/store/change-metrics-storage.md). Use our calculator to determine the system
68 +resources required to retain your desired amount of metrics, and expand or contract the database by editing a single
69 +setting.
70 +
71 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fdocs%2Fstore%2Fdistributed-data&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
docs/visualize/create-dashboards.md new
+63
@@ -0,0 +1,63 @@
1 +<!--
2 +title: "Create new dashboards"
3 +description: "Create new dashboards in Netdata Cloud, with any number of metrics from any node on your infrastructure, for targeted troubleshooting."
4 +custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/visualize/create-dashboards.md
5 +-->
6 +
7 +# Create new dashboards
8 +
9 +With Netdata Cloud, you can build new dashboards that put key metrics from any number of distributed systems in one
10 +place for a bird's eye view of your infrastructure. You can create more meaningful visualizations for troubleshooting or
11 +keep a watchful eye on your infrastructure's most meaningful metrics without moving from node to node.
12 +
13 +In the War Room you want to monitor with this dashboard, click on your War Room's dropdown, then click on the green **+
14 +Add** button next to **Dashboards**. In the panel, give your new dashboard a name, and click **+ Add**.
15 +
16 +Click the **Add Chart** button to add your first chart card. From the dropdown, select the node you want to add the
17 +chart from, then the context. Netdata Cloud shows you a preview of the chart before you finish adding it. The **Add
18 +Text** button creates a new card with user-defined text, which you can use to describe or document a particular
19 +dashboard's meaning and purpose.
20 +
21 +![An example multi-node dashboard for system CPU
22 +metrics](https://user-images.githubusercontent.com/1153921/93399129-c1661480-f831-11ea-9570-a5bd401f54db.png)
23 +
24 +Charts in dashboards are [fully interactive](/docs/visualize/interact-dashboards-charts.md) and synchronized. You can
25 +pan through time, zoom, highlight specific timeframes, and more.
26 +
27 +Move any card by clicking on their top panel and dragging them to a new location. Other cards re-sort to the grid system
28 +automatically. You can also resize any card by grabbing the bottom-right corner and dragging it to its new size.
29 +
30 +Hit the **Save** button to finalize your dashboard. Any other member of the War Room can now access it and make changes.
31 +
32 +## Jump to single-node Cloud dashboards
33 +
34 +While dashboards help you associate essential charts from distributed nodes on a single pane of glass, you might need
35 +more detail when troubleshooting an issue. Quickly jump to any node's dashboard by clicking the 3-dot icon in the corner
36 +of any card to open a menu. Hit the **Go to Chart** item.
37 +
38 +Netdata Cloud takes you to the same chart on that node's dashboard. You can now navigate all that node's metrics and
39 +[interact with charts](/docs/visualize/interact-dashboards-charts.md) to further investigate anomalies or troubleshoot
40 +complex performance problems.
41 +
42 +When viewing a single-node Cloud dashboard, you can also click on the add to dashboard icon <img
43 +src="https://user-images.githubusercontent.com/1153921/87587846-827fdb00-c697-11ea-9f31-aed0b8c6afba.png" alt="Dashboard
44 +icon" class="image-inline" /> to quickly add that chart to a new or existing dashboard. You might find this useful when investigating an anomaly and want to quickly populate a dashboard with potentially correlated metrics.
45 +
46 +## Pin dashboards and navigate through Netdata Cloud
47 +
48 +Click on the **Pin** button in any dashboard to put those charts into a separate panel at the bottom of the screen. You
49 +can now navigate through Netdata Cloud freely, individual Cloud dashboards, the Nodes view, different War Rooms, or even
50 +different Spaces, and have those valuable metrics follow you.
51 +
52 +![Pinning a dashboard and navigate through Cloud](https://user-images.githubusercontent.com/1153921/93499810-4e5bad00-f8c8-11ea-9b3f-173d4ba0aaa7.gif)
53 +
54 +Pinning dashboards helps you correlate potentially related charts across your infrastructure and discover root causes
55 +faster.
56 +
57 +## What's next?
58 +
59 +While it's useful to see real-time metrics on flexible dashboards, you need ways to know precisely when an anomaly
60 +strikes. Every Netdata Agent comes with a health watchdog that uses [alarms](/docs/monitor/configure-alarms.md) and
61 +[notifications](/docs/monitor/enable-notifications.md) to notify you of issues seconds after they strike.
62 +
63 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fdocs%2Fvisualize%2Fcreate-dashboards&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
docs/visualize/interact-dashboards-charts.md new
+89
@@ -0,0 +1,89 @@
1 +<!--
2 +title: "Interact with dashboards and charts"
3 +description: "Zoom, highlight, and pan through time on hundreds of real-time, interactive charts to quickly discover the root cause of any anomaly."
4 +custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/visualize/interact-dashboards-charts.md
5 +-->
6 +
7 +# Interact with dashboards and charts
8 +
9 +You can find Netdata's dashboards in two places: locally served at `http://NODE:19999` by the Netdata Agent, and in
10 +Netdata Cloud. While you access these dashboards differently, they have similar interfaces, identical charts and
11 +metrics, and you interact with both of them the same way.
12 +
13 +> If you're not sure which option is best for you, see our [single-node](/docs/quickstart/single-node.md) and
14 +> [infrastructure](/docs/quickstart/infrastructure.md) quickstart guides.
15 +
16 +![A single-node dashboard in Netdata
17 +Cloud](https://user-images.githubusercontent.com/1153921/93500082-b01c1700-f8c8-11ea-920a-c490f05b50f5.gif)
18 +
19 +Netdata dashboards are single, scrollable pages with many charts stacked on top of one another. As you scroll up or
20 +down, charts appearing in your browser's viewport automatically load and update every second.
21 +
22 +The dashboard is broken up into multiple **sections**, such as **System Overview**, **CPU**, **Disk**, which are
23 +automatically generated based on which [collectors](/docs/collect/how-collectors-work.md) begin collecting metrics when
24 +Netdata starts up. Sections also appear in the right-hand **menu**, along with submenus based on the contexts and
25 +families Netdata creates for your node.
26 +
27 +## Charts, dimensions, families, and contexts
28 +
29 +A **chart** is an interactive visualization of one or more collected/calculated metrics. You can see the name (also
30 +known as its unique ID) of a chart by looking at the top-left corner of a chart and finding the parenthesized text. On a
31 +Linux system, one of the first charts on the dashboard will be the system CPU chart, with the name `system.cpu`.
32 +
33 +A **dimension** is any value that gets shown on a chart. The value can be raw data or calculated values, such as
34 +percentages, aggregates, and more. Most charts will have more than one dimension, in which case it will display each in
35 +a different color. You can disable or enable showing these dimensions by clicking on them.
36 +
37 +A **family** is _one_ instance of a monitored hardware or software resource that needs to be monitored and displayed
38 +separately from similar instances. For example, if your node has multiple partitions, Netdata will create different
39 +families for `/`, `/boot`, `/home`, and so on. Same goes for entire disks, network devices, and more.
40 +
41 +A **context** groups several charts based on the types of metrics being collected and displayed. For example, the
42 +**Disk** section often has many contexts: `disk.io`, `disk.ops`, `disk.backlog`, `disk.util`, and so on. Netdata uses
43 +this context to create individual charts and then groups them by family. You can always see the context of any chart by
44 +looking at its name or hovering over the chart's date.
45 +
46 +See our [dashboard docs](/web/README.md#charts-contexts-families) for more information about the above distinctions
47 +and how they're used across Netdata to meaningfully organize and present metrics.
48 +
49 +## Interact with charts
50 +
51 +Netdata's charts are fully interactive to help you find meaningful information about complex problems. You can pan
52 +through historical metrics, zoom in and out, select specific timeframes for further analysis, resize charts, and more.
53 +Whenever you use a chart in this way, Netdata synchronizes all the other charts to match it.
54 +
55 +| Change | Method #1 | Method #2 | Method #3 |
56 +| ------------------------------------------------- | ----------------------------------- | --------------------------------------------------------- | ---------------------------------------------------------- |
57 +| **Stop** a chart from updating | `click` | | |
58 +| **Reset** charts to default auto-refreshing state | `double click` | `double tap` (touchpad/touchscreen) | |
59 +| **Select** a certain timeframe | `ALT` + `mouse selection` | `⌘` + `mouse selection` (macOS) | |
60 +| **Pan** forward or back in time | `click and drag` | `touch and drag` (touchpad/touchscreen) | |
61 +| **Zoom** to a specific timeframe | `SHIFT` + `mouse selection` | | |
62 +| **Zoom** in/out | `SHIFT`/`ALT` + `mouse scrollwheel` | `SHIFT`/`ALT` + `two-finger pinch` (touchpad/touchscreen) | `SHIFT`/`ALT` + `two-finger scroll` (touchpad/touchscreen) |
63 +
64 +![Animated GIF of the standard Netdata dashboard being manipulated and synchronizing
65 +charts](https://user-images.githubusercontent.com/1153921/93497197-071fed00-f8c5-11ea-96ff-60e77ed952bd.gif)
66 +
67 +These interactions can also be triggered using the icons on the bottom-right corner of every chart. They are,
68 +respectively, `Pan Left`, `Reset`, `Pan Right`, `Zoom In`, and `Zoom Out`.
69 +
70 +You can show and hide individual dimensions by clicking on their names. Hiding dimensions simplifies the chart and can
71 +help you better discover exactly which aspect of your system is behaving strangely.
72 +
73 +You can resize any chart by clicking-and-dragging the icon on the bottom-right corner of any chart. To restore the chart
74 +to its original height, double-click the same icon.
75 +
76 +![Resizing a chart and resetting it to the default
77 +height](https://user-images.githubusercontent.com/1153921/93497272-1acb5380-f8c5-11ea-851c-6cd5ac247e41.gif)
78 +
79 +## What's next?
80 +
81 +Netdata Cloud users can [build new dashboards](/docs/visualize/create-dashboards.md) in just a few clicks. By
82 +aggregating relevant metrics from any number of nodes onto a single interface, you can respond faster to anomalies,
83 +perform more targeted troubleshooting, or keep tabs on a bird's eye view of your infrastructure.
84 +
85 +If you're finished with dashboards for now, skip to Netdata's health watchdog for information on [creating or
86 +configuring](/docs/monitor/configure-alarms.md) alarms, and [send notifications](/docs/monitor/enable-notifications.md)
87 +to get informed when something goes wrong in your infrastructure.
88 +
89 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fdocs%2Fvisualize%2Finteract-dashboards-charts&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
docs/visualize/view-all-nodes.md new
+77
@@ -0,0 +1,77 @@
1 +<!--
2 +title: "View all nodes at a glance"
3 +description: "With Netdata Cloud's War Rooms, you can see the health status and real-time key metrics from any number of nodes in your infrastructure."
4 +custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/visualize/view-all-nodes.md
5 +-->
6 +
7 +# View all nodes at a glance
8 +
9 +In Netdata Cloud, your nodes are organized into War Rooms. The default view for any War Room is called the **Nodes
10 +view**, which lets you see the health, performance, and alarm status of a particular cross-section of your
11 +infrastructure.
12 +
13 +Each node occupies a single row, first featuring that node's alarm status (yellow for warnings, red for critical alarms)
14 +and operating system, some essential information about the node, followed by any number of user-defined columns for key
15 +metrics.
16 +
17 +Click on the hostname of any node to seamlessly navigate to that node's Cloud dashboard. From here, you will see all the
18 +same charts and real-time metrics as you would if you viewed the local dashboard at `http://NODE:19999`.
19 +
20 +![Moving from Nodes view to a single-node dashboard in
21 +Cloud](https://user-images.githubusercontent.com/1153921/93496402-02a70480-f8c4-11ea-82cc-9c81abfd5b98.gif)
22 +
23 +By combining Nodes view with Cloud dashboards, you and your team can view all nodes at a glance, immediately identify
24 +anomalies with auto-updating health statuses and key metrics, then dive into individual dashboards for discovering the
25 +root cause.
26 +
27 +## Add and edit key metrics
28 +
29 +Customize any War Room by adding new key metrics or editing the existing ones. These customizations appear for anyone
30 +else with access to that War Room so that your entire team can troubleshoot from the same platform.
31 +
32 +Add more key metrics by clicking the gear icon in the Nodes view. Choose the context you'd like to add, give it a
33 +relevant name, and select whether you want to see all dimensions (the default), or only the specific dimensions your
34 +team is interested in.
35 +
36 +![GIF showing how to add new metrics to the Nodes
37 +view](https://user-images.githubusercontent.com/1153921/87456847-593e4c80-c5bc-11ea-8063-80c768d4cf6e.gif)
38 +
39 +To edit existing key metrics, click the gear icon, then the pencil icon. Use the panel to edit that metric's context or
40 +title, add or remove dimension, or delete the chart altogether.
41 +
42 +## Change the timeframe
43 +
44 +By default, the Nodes view shows the last 5 minutes of metrics data on every chart. The value displayed above the chart
45 +is the 5-minute average of those metrics.
46 +
47 +Change the timeframe, and also change both the charts and the average value, by clicking on any of the buttons
48 +next to the **Last** label. **15m** will display the last 15 minutes of metrics for each chart, **30m** for 30 minutes,
49 +and so on.
50 +
51 +![GIF showing how to change the timeframe in
52 +Nodes](https://user-images.githubusercontent.com/1153921/93496405-03d83180-f8c4-11ea-851a-d1bdede43483.gif)
53 +
54 +## Filter and group your infrastructure
55 +
56 +Use the filter input next to the Nodes heading to filter the nodes in a given War Room. The filtering feature supports
57 +relational operators (==, !=, contains, and !contains) and logical operators (AND, OR), plus the name, OS, or services
58 +running on your nodes to quickly turn any War Room into a focused troubleshooting interface. See what services Netdata
59 +Cloud can filter by in the [supported collectors list](/collectors/COLLECTORS.md).
60 +
61 +For example, `name == centos OR os == debian` filters any nodes by the exact name centos or has Debian as its operating
62 +system.
63 +
64 +You can also use parentheses around operators to create more sophisticated filters. `(name contains aws AND os contains
65 +ubuntu) OR services == apache` shows only nodes that have aws in the hostname and are Ubuntu-based, or any nodes that
66 +have an Apache webserver running on them.
67 +
68 +![Filtering a War Room in Netdata
69 +Cloud](https://user-images.githubusercontent.com/1153921/93499808-4dc31680-f8c8-11ea-884d-e8fe8c3ee474.gif)
70 +
71 +## What's next?
72 +
73 +To troubleshoot complex performance issues using Netdata, you need to understand how to interact with its meaningful
74 +visualizations. Learn more about [interaction](/docs/visualize/interact-dashboards-charts.md) to see historical metrics,
75 +highlight timeframes for targeted analysis, and more.
76 +
77 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fdocs%2Fvisualize%2Fview-all-nodes&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
docs/what-is-netdata.md deleted
-419
@@ -1,419 +0,0 @@
1 -<!--
2 ----
3 -title: "What is Netdata?"
4 -date: 2020-05-01
5 -custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/what-is-netdata.md
6 ----
7 --->
8 -
9 -# Netdata [![Build Status](https://travis-ci.com/netdata/netdata.svg?branch=master)](https://travis-ci.com/netdata/netdata) [![CII Best Practices](https://bestpractices.coreinfrastructure.org/projects/2231/badge)](https://bestpractices.coreinfrastructure.org/projects/2231) [![License: GPL v3+](https://img.shields.io/badge/License-GPL%20v3%2B-blue.svg)](https://www.gnu.org/licenses/gpl-3.0) [![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Freadme&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
10 -
11 -[![Code
12 -Climate](https://codeclimate.com/github/netdata/netdata/badges/gpa.svg)](https://codeclimate.com/github/netdata/netdata)
13 -[![Codacy
14 -Badge](https://api.codacy.com/project/badge/Grade/a994873f30d045b9b4b83606c3eb3498)](https://www.codacy.com/app/netdata/netdata?utm_source=github.com&utm_medium=referral&utm_content=netdata/netdata&utm_campaign=Badge_Grade)
15 -[![LGTM
16 -C](https://img.shields.io/lgtm/grade/cpp/g/netdata/netdata.svg?logo=lgtm)](https://lgtm.com/projects/g/netdata/netdata/context:cpp)
17 -[![LGTM
18 -JS](https://img.shields.io/lgtm/grade/javascript/g/netdata/netdata.svg?logo=lgtm)](https://lgtm.com/projects/g/netdata/netdata/context:javascript)
19 -[![LGTM
20 -PYTHON](https://img.shields.io/lgtm/grade/python/g/netdata/netdata.svg?logo=lgtm)](https://lgtm.com/projects/g/netdata/netdata/context:python)
21 -
22 ----
23 -
24 -Netdata is **distributed, real-time performance and health monitoring** for systems and applications. It is a
25 -highly-optimized monitoring agent you install on all your systems and containers.
26 -
27 -Netdata provides **unparalleled insights**, in **real-time**, of everything happening on the systems it's running on
28 -(including web servers, databases, applications), using **highly interactive web dashboards**.
29 -
30 -A highly-efficient database **stores long-term historical metrics for days, weeks, or months**, all at 1-second
31 -granularity. Run this long-term storage autonomously, or integrate Netdata with your existing monitoring toolchains
32 -(Prometheus, Graphite, OpenTSDB, Kafka, Grafana, and more).
33 -
34 -Netdata is **fast** and **efficient**, designed to permanently run on all systems (**physical** and **virtual** servers,
35 -**containers**, **IoT** devices), without disrupting their core function.
36 -
37 -Netdata is **free, open-source software** and it currently runs on **Linux**, **FreeBSD**, and **macOS**, along with
38 -other systems derived from them, such as **Kubernetes** and **Docker**.
39 -
40 -Netdata is not hosted by the CNCF but is the fourth most starred open-source project in the [Cloud Native Computing
41 -Foundation (CNCF) landscape](https://landscape.cncf.io/format=card-mode&grouping=no&sort=stars).
42 -
43 ----
44 -
45 -People get **addicted to Netdata**. Once you use it on your systems, **there is no going back**! _You've been warned..._
46 -
47 -![image](https://user-images.githubusercontent.com/2662304/48305662-9de82980-e537-11e8-9f5b-aa1a60fbb82f.png)
48 -
49 -[![Tweet about
50 -Netdata!](https://img.shields.io/twitter/url/http/shields.io.svg?style=social&label=Tweet%20about%20netdata)](https://twitter.com/intent/tweet?text=Netdata,%20real-time%20performance%20and%20health%20monitoring,%20done%20right!&url=https://my-netdata.io/&via=linuxnetdata&hashtags=netdata,monitoring)
51 -
52 -## Contents
53 -
54 -1. [What does it look like?](#what-does-it-look-like) - Take a quick tour through the dashboard
55 -2. [Our userbase](#user-base) - Enterprises we help monitor and our userbase
56 -3. [Quickstart](#quickstart) - How to try it now on your systems
57 -4. [Why Netdata](#why-netdata) - Why people love Netdata and how it compares with other solutions
58 -5. [How Netdata works](#how-it-works) - A high-level diagram of how Netdata works
59 -6. [Infographic](#infographic) - Everything about Netdata in a single graphic
60 -7. [Features](#features) - How you'll use Netdata on your systems
61 -8. [Visualization](#visualization) - Learn about visual anomaly detection
62 -9. [What Netdata monitors](#what-netdata-monitors) - See which apps/services Netdata auto-detects
63 -10. [Documentation](#documentation) - Read the documentation
64 -11. [Community](#community) - Discuss Netdata with others and get support
65 -12. [License](#license) - Check Netdata's licencing
66 -13. [Is it any good?](#is-it-any-good) - Yes.
67 -14. [Is it awesome?](#is-it-awesome) - Yes.
68 -
69 -## What does it look like?
70 -
71 -The following animated GIF shows the top part of a typical Netdata dashboard.
72 -
73 -![The Netdata dashboard in
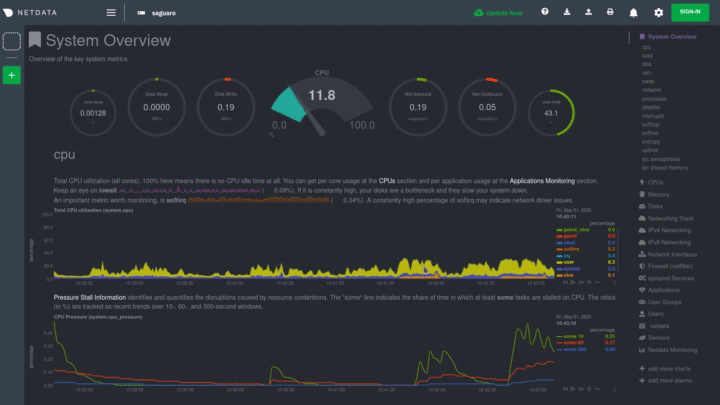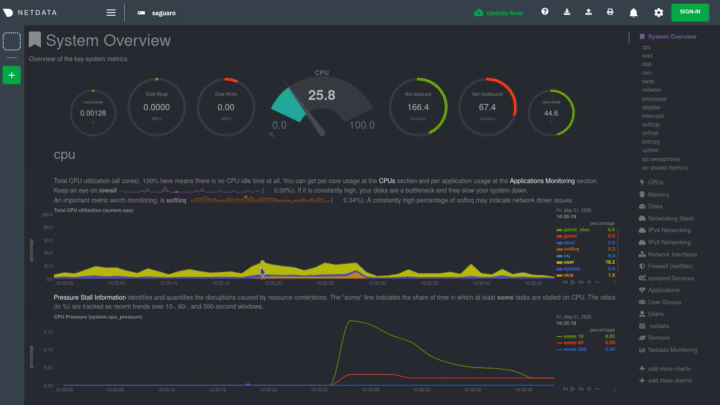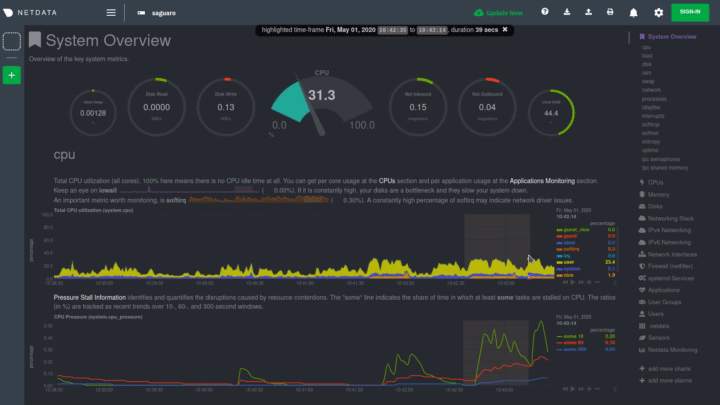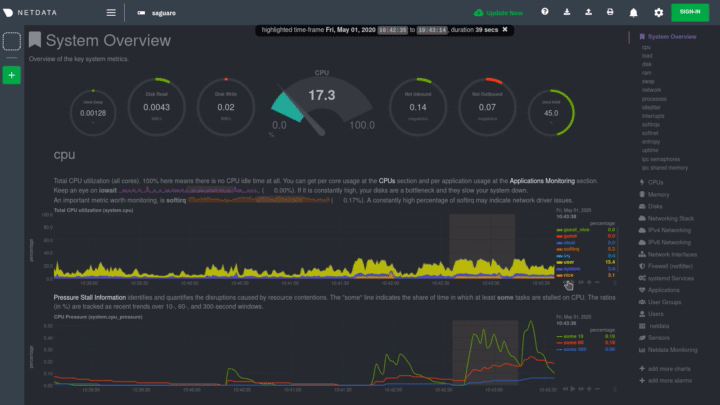
74 -action](https://user-images.githubusercontent.com/1153921/80827388-b9fee100-8b98-11ea-8f60-0d7824667cd3.gif)
75 -
76 -> A typical Netdata dashboard, in 1:1 timing. Charts can be panned by dragging them, zoomed in/out with `SHIFT` + `mouse
77 -> wheel`, an area can be selected for zoom-in with `SHIFT` + `mouse selection`. Netdata is highly interactive,
78 -> **real-time**, and optimized to get the work done!
79 -
80 -Want to try Netdata before you install? See our [live
81 -demo](https://london.my-netdata.io/default.html#menu_system_submenu_cpu;theme=slate;help=true).
82 -
83 -## User base
84 -
85 -Netdata is used by hundreds of thousands of users all over the world. Check our [GitHub watchers
86 -list](https://github.com/netdata/netdata/watchers). You will find people working for **Amazon**, **Atos**, **Baidu**,
87 -**Cisco Systems**, **Citrix**, **Deutsche Telekom**, **DigitalOcean**, **Elastic**, **EPAM Systems**, **Ericsson**,
88 -**Google**, **Groupon**, **Hortonworks**, **HP**, **Huawei**, **IBM**, **Microsoft**, **NewRelic**, **Nvidia**, **Red
89 -Hat**, **SAP**, **Selectel**, **TicketMaster**, **Vimeo**, and many more!
90 -
91 -### Docker pulls
92 -
93 -We provide Docker images for the most common architectures. These are statistics reported by Docker Hub:
94 -
95 -[![netdata/netdata
96 -(official)](https://img.shields.io/docker/pulls/netdata/netdata.svg?label=netdata/netdata+%28official%29)](https://hub.docker.com/r/netdata/netdata/)
97 -[![firehol/netdata
98 -(deprecated)](https://img.shields.io/docker/pulls/firehol/netdata.svg?label=firehol/netdata+%28deprecated%29)](https://hub.docker.com/r/firehol/netdata/)
99 -[![titpetric/netdata
100 -(donated)](https://img.shields.io/docker/pulls/titpetric/netdata.svg?label=titpetric/netdata+%28third+party%29)](https://hub.docker.com/r/titpetric/netdata/)
101 -
102 -### Registry
103 -
104 -When you install multiple Netdata, they are integrated into **one distributed application**, via a [Netdata
105 -registry](/registry/README.md). This is a web browser feature and it allows us to count the number of unique users and
106 -unique Netdata servers installed. The following information comes from the global public Netdata registry we run:
107 -
108 -[![User
109 -Base](https://registry.my-netdata.io/api/v1/badge.svg?chart=netdata.registry_entries&dimensions=persons&label=user%20base&units=M&value_color=blue&precision=2&divide=1000000&v43)](https://registry.my-netdata.io/#menu_netdata_submenu_registry)
110 -[![Monitored
111 -Servers](https://registry.my-netdata.io/api/v1/badge.svg?chart=netdata.registry_entries&dimensions=machines&label=servers%20monitored&units=k&divide=1000&value_color=orange&precision=2&v43)](https://registry.my-netdata.io/#menu_netdata_submenu_registry)
112 -[![Sessions
113 -Served](https://registry.my-netdata.io/api/v1/badge.svg?chart=netdata.registry_sessions&label=sessions%20served&units=M&value_color=yellowgreen&precision=2&divide=1000000&v43)](https://registry.my-netdata.io/#menu_netdata_submenu_registry)
114 -
115 -_In the last 24 hours:_<br/> [![New Users
116 -Today](https://registry.my-netdata.io/api/v1/badge.svg?chart=netdata.registry_entries&dimensions=persons&after=-86400&options=unaligned&group=incremental-sum&label=new%20users%20today&units=null&value_color=blue&precision=0&v42)](https://registry.my-netdata.io/#menu_netdata_submenu_registry)
117 -[![New Machines
118 -Today](https://registry.my-netdata.io/api/v1/badge.svg?chart=netdata.registry_entries&dimensions=machines&group=incremental-sum&after=-86400&options=unaligned&label=servers%20added%20today&units=null&value_color=orange&precision=0&v42)](https://registry.my-netdata.io/#menu_netdata_submenu_registry)
119 -[![Sessions
120 -Today](https://registry.my-netdata.io/api/v1/badge.svg?chart=netdata.registry_sessions&after=-86400&group=incremental-sum&options=unaligned&label=sessions%20served%20today&units=null&value_color=yellowgreen&precision=0&v42)](https://registry.my-netdata.io/#menu_netdata_submenu_registry)
121 -
122 -## Quickstart
123 -
124 -![](https://registry.my-netdata.io/api/v1/badge.svg?chart=web_log_nginx.requests_per_url&options=unaligned&dimensions=kickstart&group=sum&after=-3600&label=last+hour&units=installations&value_color=orange&precision=0)
125 -![](https://registry.my-netdata.io/api/v1/badge.svg?chart=web_log_nginx.requests_per_url&options=unaligned&dimensions=kickstart&group=sum&after=-86400&label=today&units=installations&precision=0)
126 -
127 -To install Netdata from source on any Linux system (physical, virtual, container, IoT, edge) and keep it up to date with
128 -our **nightly releases** automatically, run the following:
129 -
130 -```bash
131 -# make sure you run `bash` for your shell
132 -bash
133 -
134 -# install Netdata directly from GitHub source
135 -bash <(curl -Ss https://my-netdata.io/kickstart.sh)
136 -```
137 -
138 -Starting with v1.12, Netdata collects anonymous usage information by default and sends it to Google Analytics. Read
139 -about the information collected, and learn how to-opt, on our [anonymous statistics](/docs/anonymous-statistics.md) page.
140 -
141 -The usage statistics are _vital_ for us, as we use them to discover bugs and prioritize new features. We thank you for
142 -_actively_ contributing to Netdata's future.
143 -
144 -To learn more about the pros and cons of using _nightly_ vs. _stable_ releases, see our [notice about the two options](/packaging/installer/README.md#nightly-vs-stable-releases).
145 -
146 -The above command will:
147 -
148 -- Install any required packages on your system (it will ask you to confirm before doing so)
149 -- Compile it, install it, and start it.
150 -
151 -More installation methods and additional options can be found at the [installation
152 -page](/packaging/installer/README.md).
153 -
154 -To try Netdata in a Docker container, run this:
155 -
156 -```sh
157 -docker run -d --name=netdata \
158 - -p 19999:19999 \
159 - -v netdatalib:/var/lib/netdata \
160 - -v netdatacache:/var/cache/netdata \
161 - -v /etc/passwd:/host/etc/passwd:ro \
162 - -v /etc/group:/host/etc/group:ro \
163 - -v /proc:/host/proc:ro \
164 - -v /sys:/host/sys:ro \
165 - -v /etc/os-release:/host/etc/os-release:ro \
166 - --restart unless-stopped \
167 - --cap-add SYS_PTRACE \
168 - --security-opt apparmor=unconfined \
169 - netdata/netdata
170 -```
171 -
172 -For more information about running Netdata in Docker, check the [docker installation page](/packaging/docker/README.md).
173 -
174 -![image](https://user-images.githubusercontent.com/2662304/48304090-fd384080-e51b-11e8-80ae-eecb03118dda.png)
175 -
176 -From Netdata v1.12 and above, anonymous usage information is collected by default and sent to Google Analytics. To read
177 -more about the information collected and how to opt-out, check the [anonymous statistics
178 -page](/docs/anonymous-statistics.md).
179 -
180 -## Why Netdata
181 -
182 -Netdata has a quite different approach to monitoring.
183 -
184 -Netdata is a monitoring agent you install on all your systems. It is:
185 -
186 -- A **metrics collector** for system and application metrics (including web servers, databases, containers, and much
187 - more),
188 -- A **long-term metrics database** that stores recent metrics in memory and "spills" historical metrics to disk for
189 - efficient long-term storage,
190 -- A super fast, interactive, and modern **metrics visualizer** optimized for anomaly detection,
191 -- And an **alarms notification engine** for detecting performance and availability issues.
192 -
193 -All the above, are packaged together in a very flexible, extremely modular, distributed application.
194 -
195 -This is how Netdata compares to other monitoring solutions:
196 -
197 -| Netdata | others (open-source and commercial) |
198 -| :-------------------------------------------------------------- | :--------------------------------------------------------------- |
199 -| **High resolution metrics** (1s granularity) | Low resolution metrics (10s granularity at best) |
200 -| Monitors everything, **thousands of metrics per node** | Monitor just a few metrics |
201 -| UI is super fast, optimized for **anomaly detection** | UI is good for just an abstract view |
202 -| **Long-term, autonomous storage** at one-second granularity | Centralized metrics in an expensive data lake at 10s granularity |
203 -| **Meaningful presentation**, to help you understand the metrics | You have to know the metrics before you start |
204 -| Install and get results **immediately** | Long preparation is required to get any useful results |
205 -| Use it for **troubleshooting** performance problems | Use them to get _statistics of past performance_ |
206 -| **Kills the console** for tracing performance issues | The console is always required for troubleshooting |
207 -| Requires **zero dedicated resources** | Require large dedicated resources |
208 -
209 -Netdata is **open-source**, **free**, super **fast**, very **easy**, completely **open**, extremely **efficient**,
210 -**flexible** and integrate-able.
211 -
212 -It has been designed by **system administrators**, **DevOps engineers**, and **developers** for to not just visualize
213 -metrics, but also troubleshoot complex performance problems.
214 -
215 -## How it works
216 -
217 -Netdata is a highly efficient, highly modular, metrics management engine. Its lockless design makes it ideal for
218 -concurrent operations on the metrics.
219 -
220 -![image](https://user-images.githubusercontent.com/2662304/48323827-b4c17580-e636-11e8-842c-0ee72fcb4115.png)
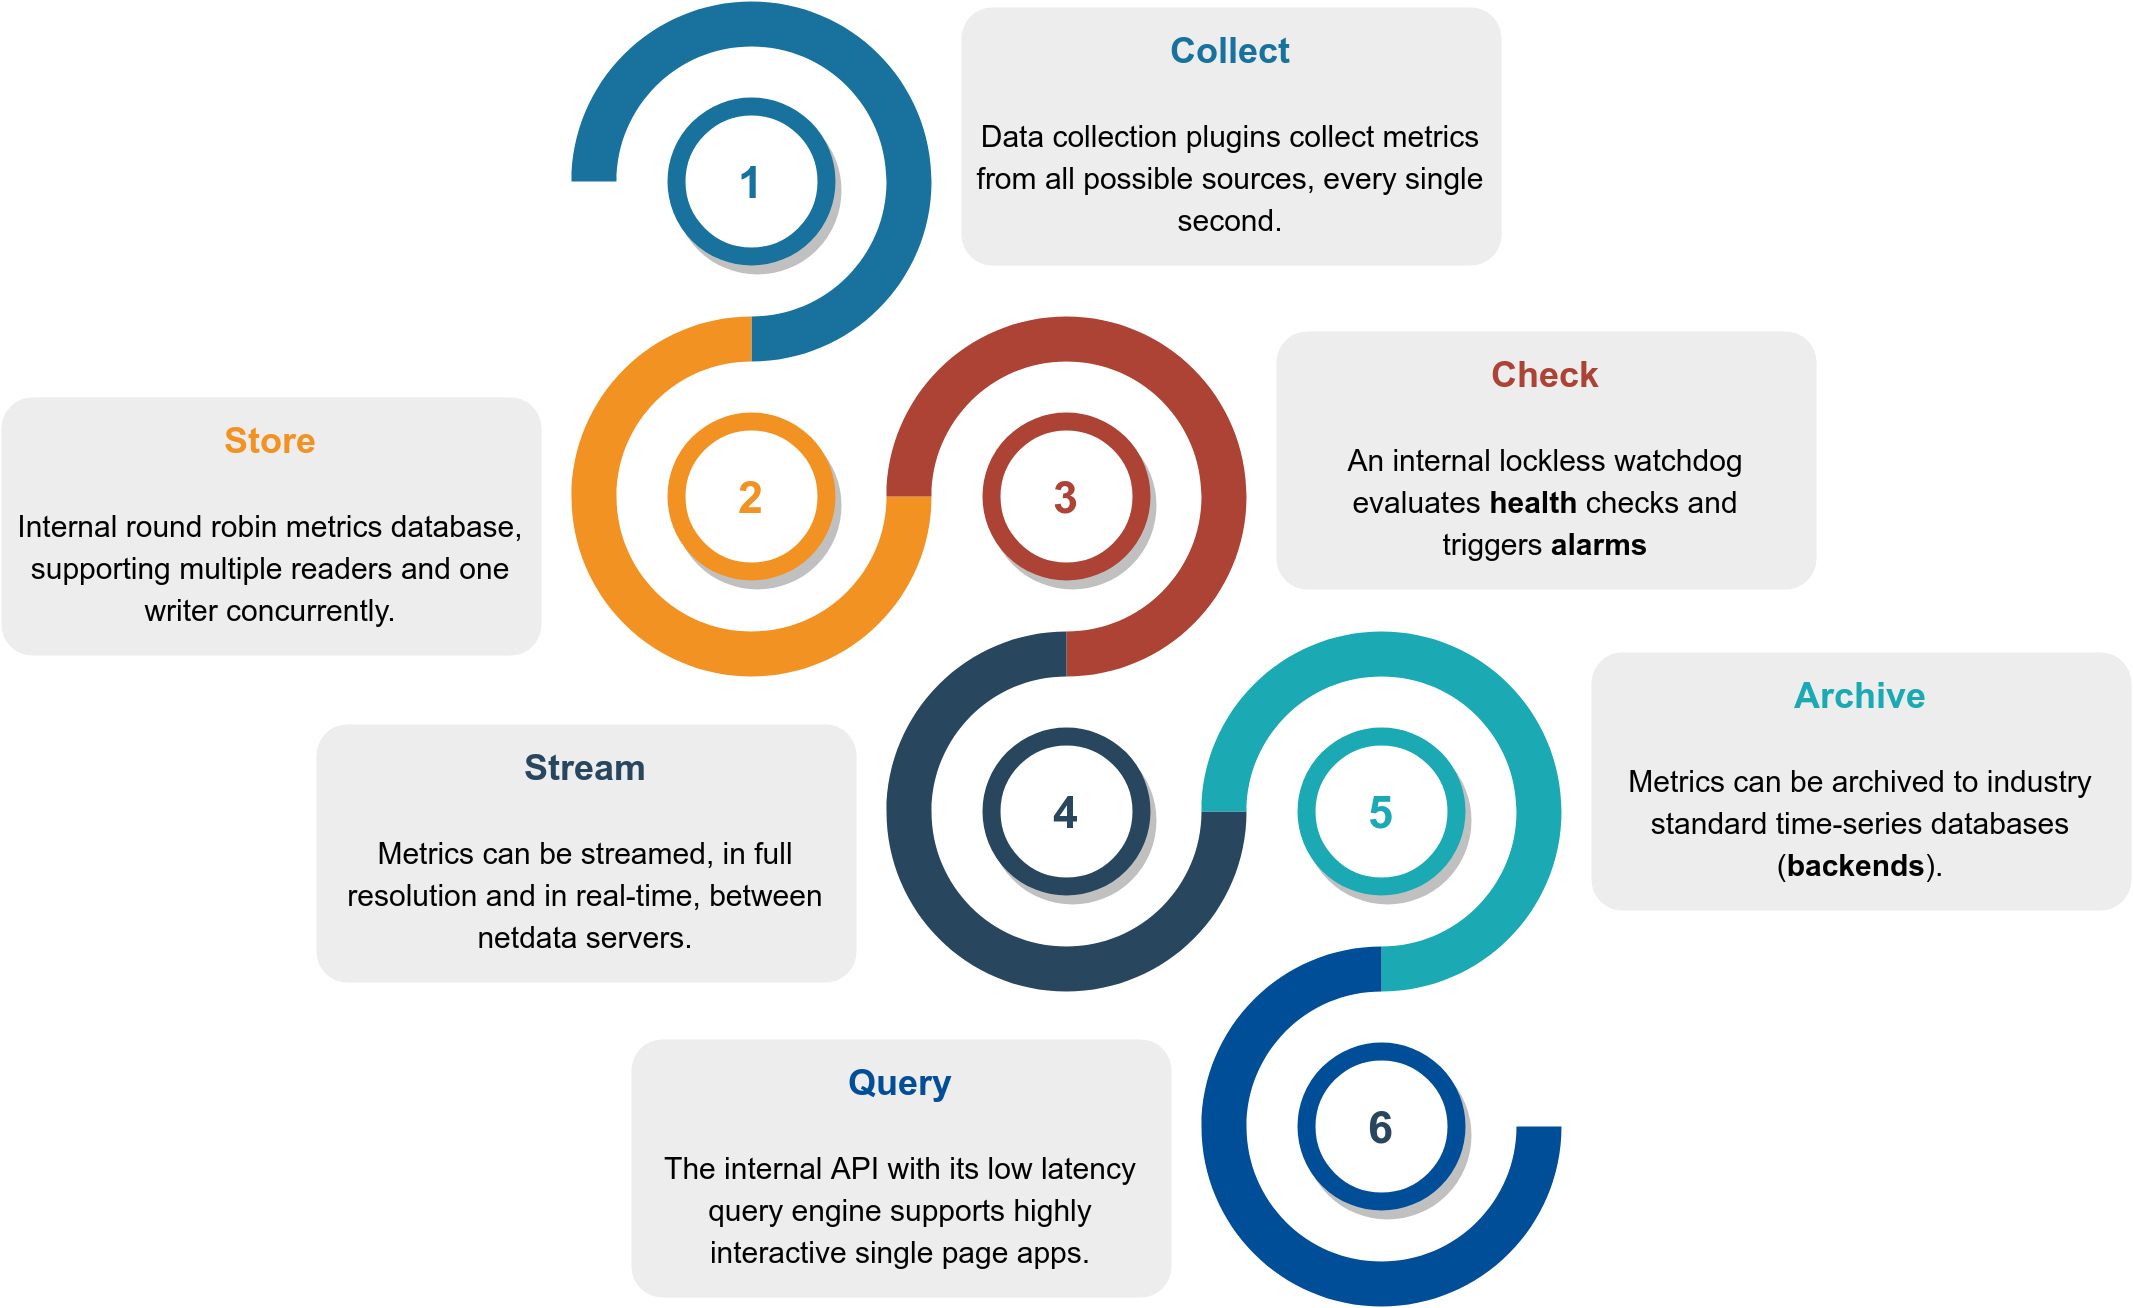
221 -
222 -This is how it works:
223 -
224 -| Function | Description | Documentation |
225 -| :---------- | :------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | :-------------------------------------------------- |
226 -| **Collect** | Multiple independent data collection workers are collecting metrics from their sources using the optimal protocol for each application and push the metrics to the database. Each data collection worker has lockless write access to the metrics it collects. | [`collectors`](/collectors/README.md) |
227 -| **Store** | Metrics are first stored in RAM in a custom database engine that then "spills" historical metrics to disk for efficient long-term metrics storage. | [`database`](/database/README.md) |
228 -| **Check** | A lockless independent watchdog is evaluating **health checks** on the collected metrics, triggers alarms, maintains a health transaction log and dispatches alarm notifications. | [`health`](/health/README.md) |
229 -| **Stream** | A lockless independent worker is streaming metrics, in full detail and in real-time, to remote Netdata servers, as soon as they are collected. | [`streaming`](/streaming/README.md) |
230 -| **Archive** | A lockless independent worker is down-sampling the metrics and pushes them to **backend** time-series databases. | [`exporting`](/docs/export/README.md) |
231 -| **Query** | Multiple independent workers are attached to the [internal web server](/web/server/README.md), servicing API requests, including [data queries](/web/api/queries/README.md). | [`web/api`](/web/api/README.md) |
232 -
233 -The result is a highly efficient, low-latency system, supporting multiple readers and one writer on each metric.
234 -
235 -## Infographic
236 -
237 -This is a high level overview of Netdata feature set and architecture. Click it to to interact with it (it has direct
238 -links to our documentation).
239 -
240 -[![image](https://user-images.githubusercontent.com/43294513/60951037-8ba5d180-a2f8-11e9-906e-e27356f168bc.png)](https://my-netdata.io/infographic.html)
241 -
242 -## Features
243 -
244 -![finger-video](https://user-images.githubusercontent.com/2662304/48346998-96cf3180-e685-11e8-9f4e-059d23aa3aa5.gif)
245 -
246 -This is what you should expect from Netdata:
247 -
248 -### General
249 -
250 -- **1s granularity** - The highest possible resolution for all metrics.
251 -- **Unlimited metrics** - Netdata collects all the available metrics—the more, the better.
252 -- **1% CPU utilization of a single core** - It's unbelievably optimized.
253 -- **A few MB of RAM** - The highly-efficient database engine stores per-second metrics in RAM and then "spills"
254 - historical metrics to disk long-term storage.
255 -- **Minimal disk I/O** - While running, Netdata only writes historical metrics and reads `error` and `access` logs.
256 -- **Zero configuration** - Netdata auto-detects everything, and can collect up to 10,000 metrics per server out of the
257 - box.
258 -- **Zero maintenance** - You just run it. Netdata does the rest.
259 -- **Zero dependencies** - Netdata runs a custom web server for its static web files and its web API (though its
260 - plugins may require additional libraries, depending on the applications monitored).
261 -- **Scales to infinity** - You can install it on all your servers, containers, VMs, and IoT devices. Metrics are not
262 - centralized by default, so there is no limit.
263 -- **Several operating modes** - Autonomous host monitoring (the default), headless data collector, forwarding proxy,
264 - store and forward proxy, central multi-host monitoring, in all possible configurations. Each node may have different
265 - metrics retention policies and run with or without health monitoring.
266 -
267 -### Health Monitoring & Alarms
268 -
269 -- **Sophisticated alerting** - Netdata comes with hundreds of alarms **out of the box**! It supports dynamic
270 - thresholds, hysteresis, alarm templates, multiple role-based notification methods, and more.
271 -- **Notifications**: [alerta.io](/health/notifications/alerta/), [amazon sns](/health/notifications/awssns/),
272 - [discordapp.com](/health/notifications/discord/), [email](/health/notifications/email/),
273 - [flock.com](/health/notifications/flock/), [hangouts](/health/notifications/hangouts/),
274 - [irc](/health/notifications/irc/), [kavenegar.com](/health/notifications/kavenegar/),
275 - [messagebird.com](/health/notifications/messagebird/), [pagerduty.com](/health/notifications/pagerduty/),
276 - [prowl](/health/notifications/prowl/), [pushbullet.com](/health/notifications/pushbullet/),
277 - [pushover.net](/health/notifications/pushover/), [rocket.chat](/health/notifications/rocketchat/),
278 - [slack.com](/health/notifications/slack/), [smstools3](/health/notifications/smstools3/),
279 - [syslog](/health/notifications/syslog/), [telegram.org](/health/notifications/telegram/),
280 - [twilio.com](/health/notifications/twilio/), [web](/health/notifications/web/) and [custom
281 - notifications](/health/notifications/custom/).
282 -
283 -### Integrations
284 -
285 -- **Time-series databases** - Netdata can archive its metrics to **Graphite**, **OpenTSDB**, **Prometheus**, **AWS
286 - Kinesis**, **MongoDB**, **JSON document DBs**, in the same or lower resolution (lower: to prevent it from congesting
287 - these servers due to the amount of data collected). Netdata also supports **Prometheus remote write API**, which
288 - allows storing metrics to **Elasticsearch**, **Gnocchi**, **InfluxDB**, **Kafka**, **PostgreSQL/TimescaleDB**,
289 - **Splunk**, **VictoriaMetrics** and a lot of other [storage
290 - providers](https://prometheus.io/docs/operating/integrations/#remote-endpoints-and-storage).
291 -
292 -## Visualization
293 -
294 -- **Stunning interactive dashboards** - Our dashboard is mouse-, touchpad-, and touch-screen friendly in 2 themes:
295 - `slate` (dark) and `white`.
296 -- **Amazingly fast visualization** - Even on low-end hardware, the dashboard responds to all queries in less than 1 ms
297 - per metric.
298 -- **Visual anomaly detection** - Our UI/UX emphasizes the relationships between charts so you can better detect
299 - anomalies visually.
300 -- **Embeddable** - Charts can be embedded on your web pages, wikis and blogs. You can even use [Atlassian's Confluence
301 - as a monitoring dashboard](/web/gui/confluence/README.md).
302 -- **Customizable** - You can build custom dashboards using simple HTML. No JavaScript needed!
303 -
304 -### Positive and negative values
305 -
306 -To improve clarity on charts, Netdata dashboards present **positive** values for metrics representing `read`, `input`,
307 -`inbound`, `received` and **negative** values for metrics representing `write`, `output`, `outbound`, `sent`.
308 -
309 -![Screenshot showing positive and negative
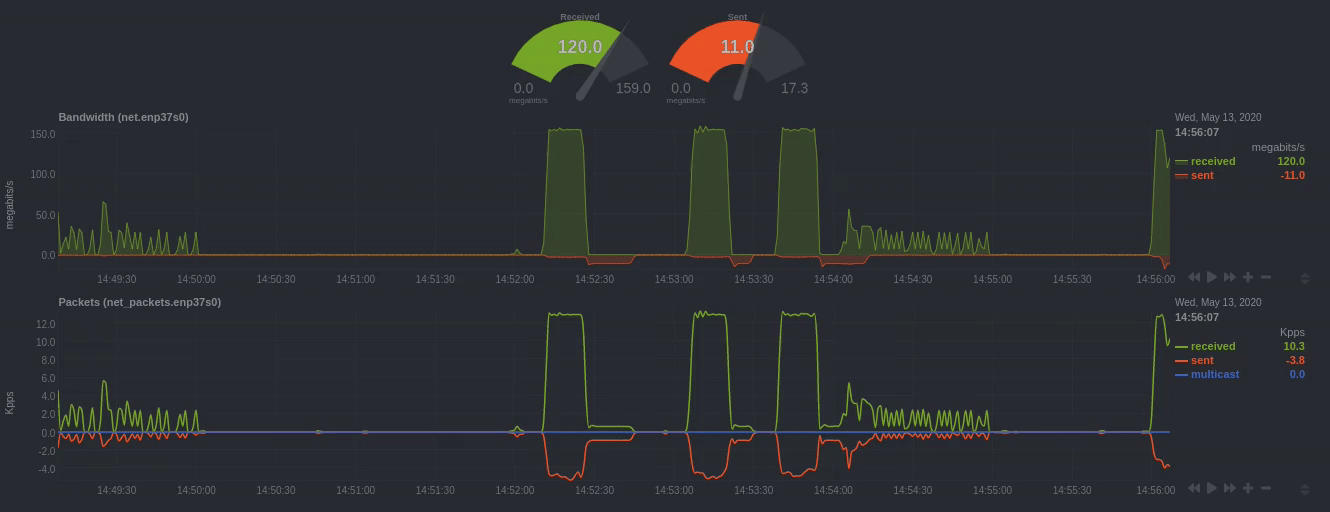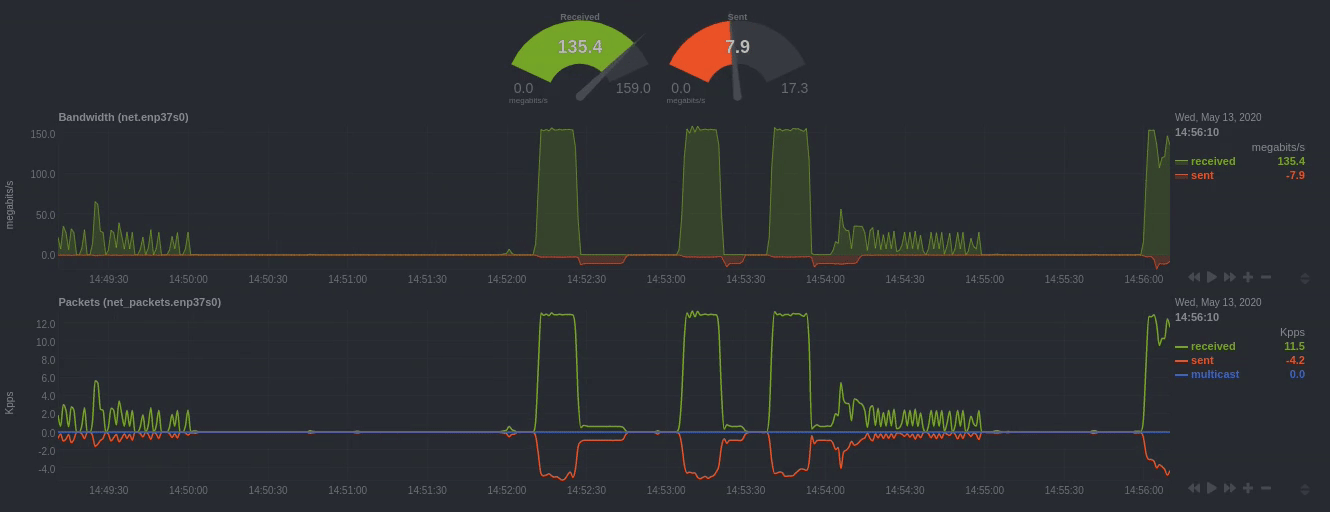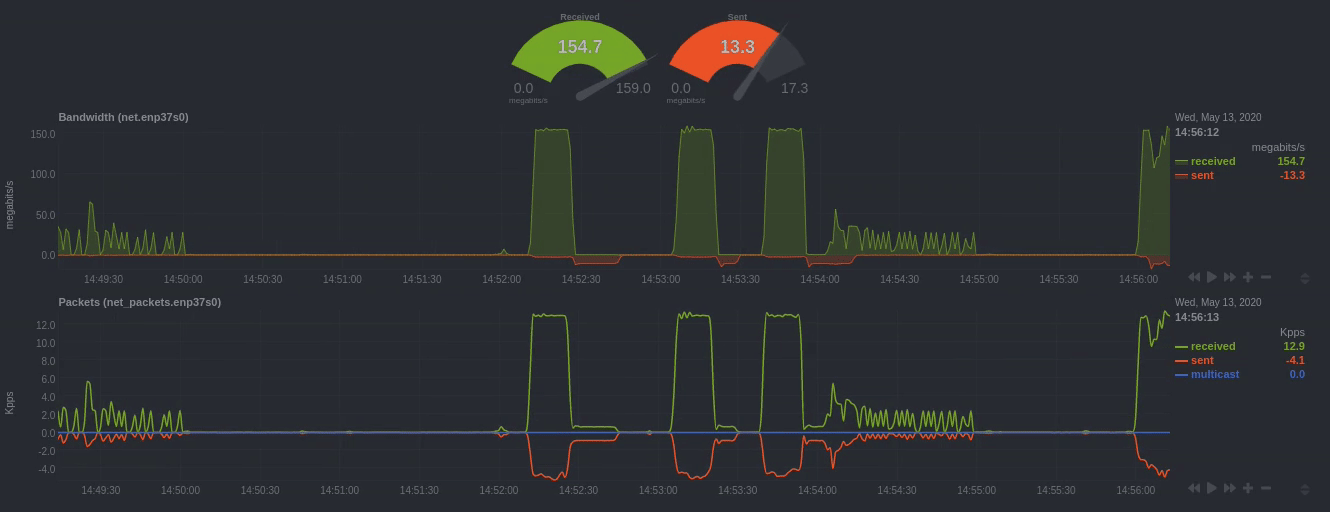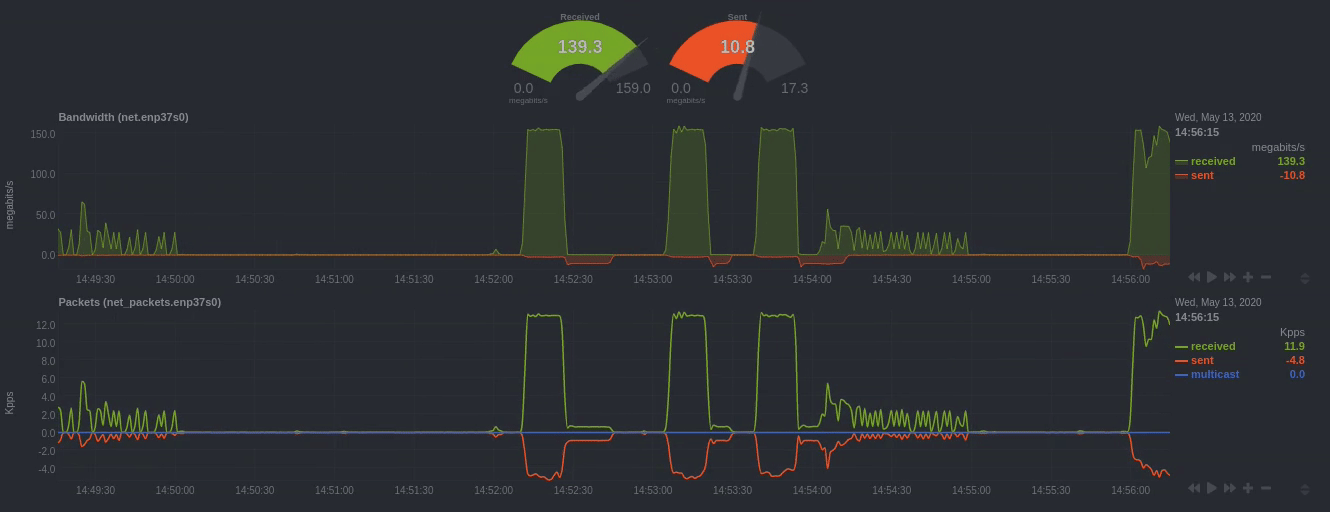
310 -values](https://user-images.githubusercontent.com/1153921/81870401-9d649080-952a-11ea-80e3-4a7b480252ee.gif)
311 -
312 -_Netdata charts showing the bandwidth and packets of a network interface. `received` is positive and `sent` is
313 -negative._
314 -
315 -### Autoscaled y-axis
316 -
317 -Netdata charts automatically zoom vertically, to visualize the variation of each metric within the visible time-frame.
318 -
319 -![Animated GIF showing the auso-scaling Y
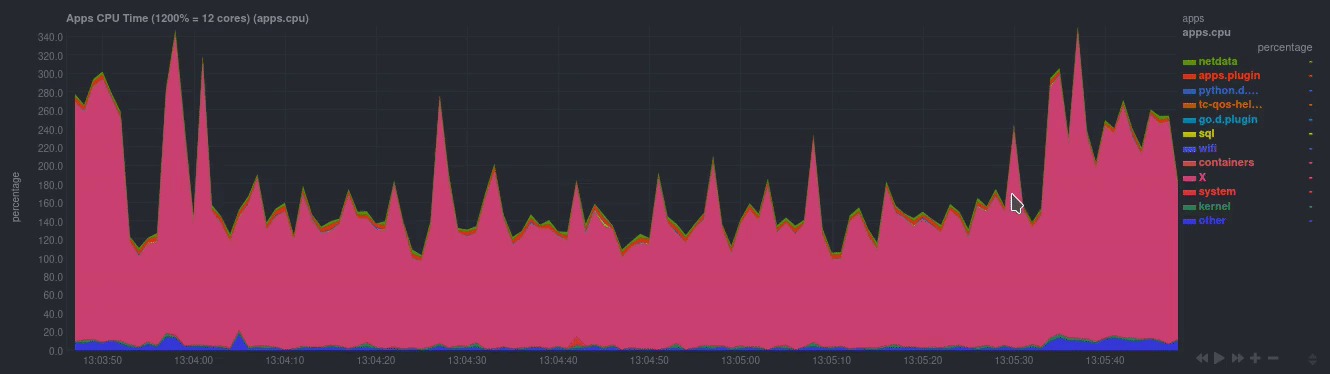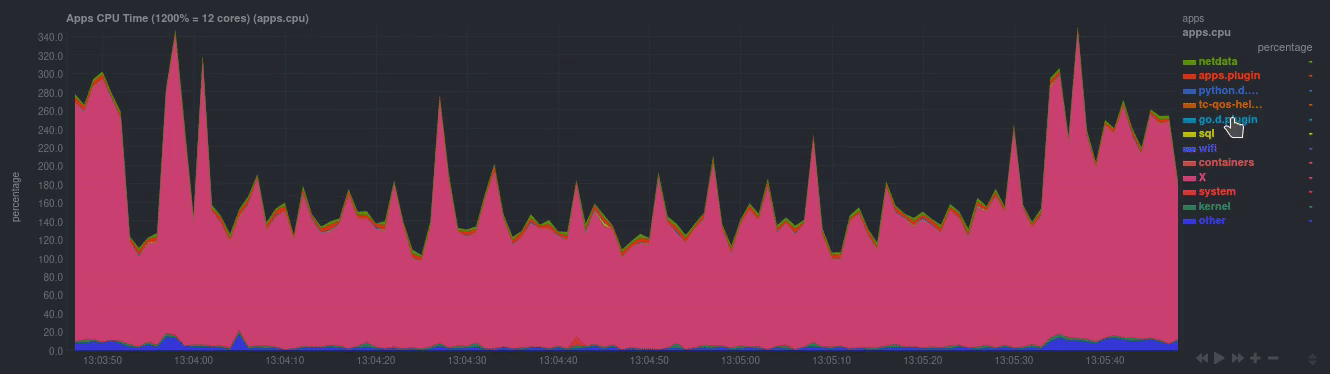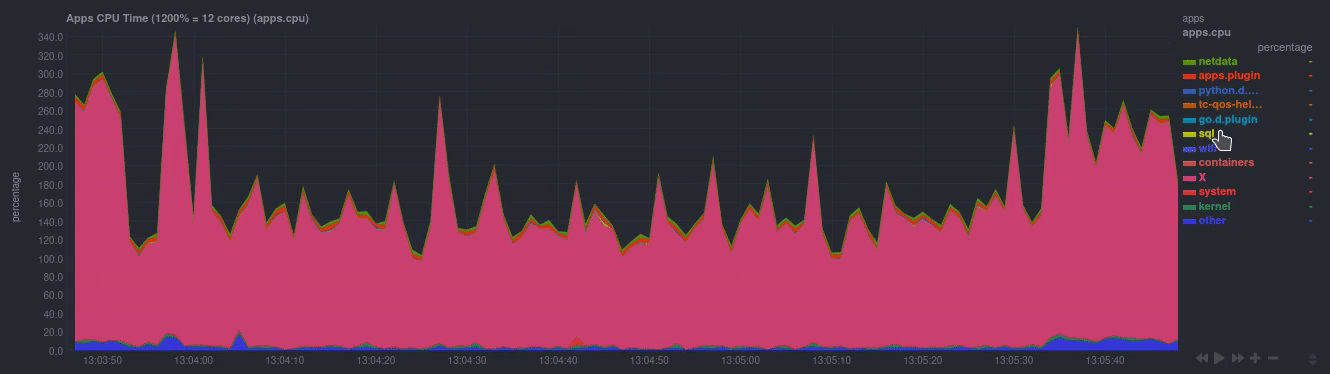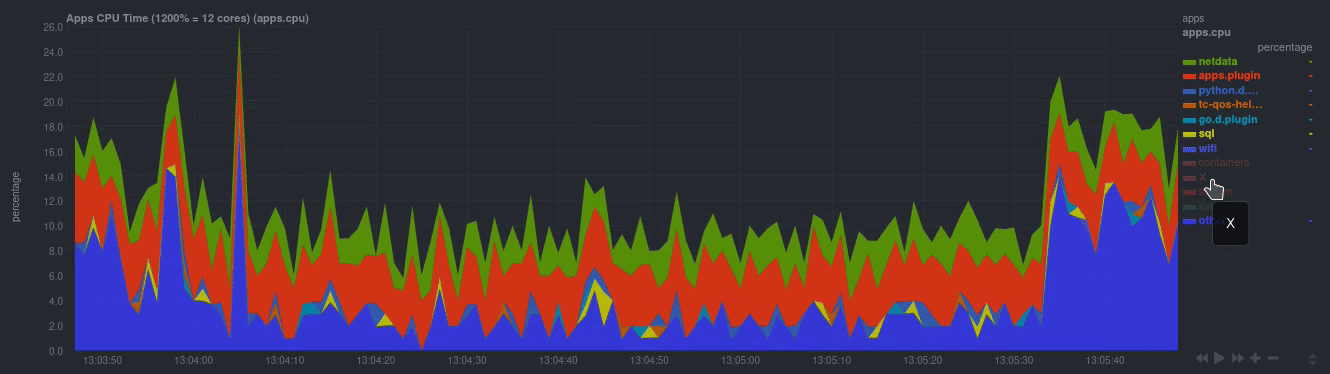
320 -axis](https://user-images.githubusercontent.com/1153921/80838276-8084a080-8bad-11ea-8167-8d5ab2fb1be1.gif)
321 -
322 -_A zero-based `stacked` chart, automatically switches to an auto-scaled `area` chart when a single dimension is
323 -selected._
324 -
325 -### Charts are synchronized
326 -
327 -Charts on Netdata dashboards are synchronized to each other. There is no master chart. Any chart can be panned or zoomed
328 -at any time, and all other charts will follow.
329 -
330 -![Animated GIF of the standard Netdata dashboard being manipulated and synchronizing
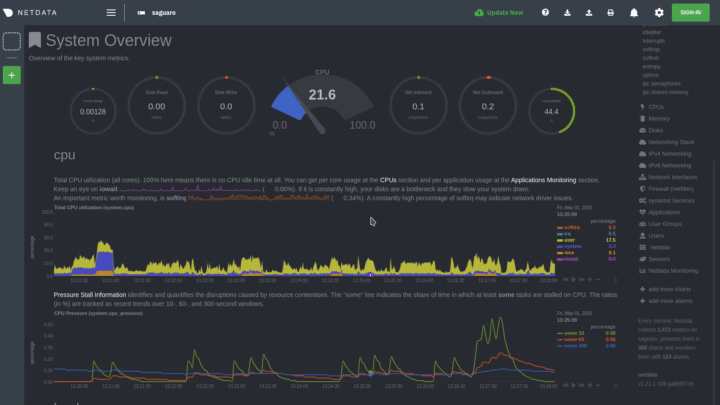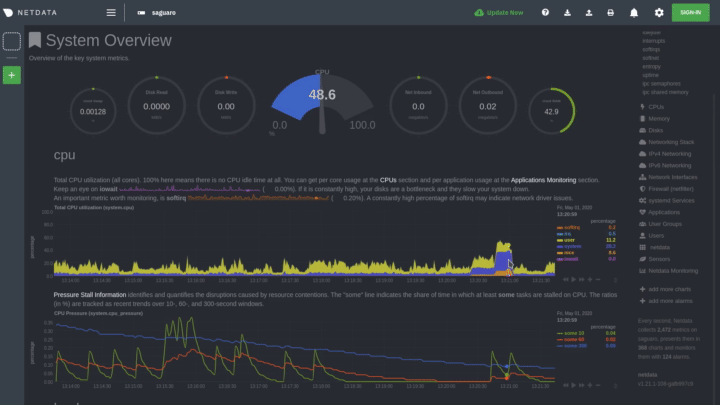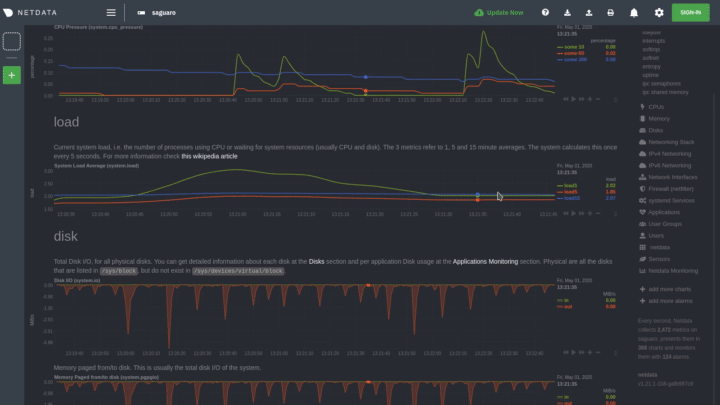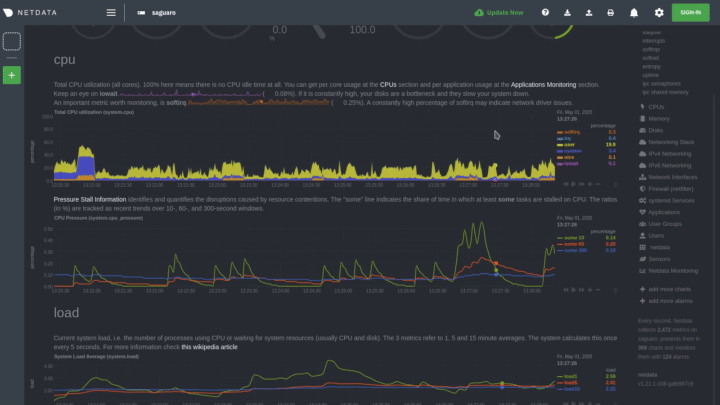
331 -charts](https://user-images.githubusercontent.com/1153921/80839230-b034a800-8baf-11ea-9cb2-99c1e10f0f85.gif)
332 -
333 -_Charts are panned by dragging them with the mouse. Charts can be zoomed in/out with`SHIFT` + `mouse wheel` while the
334 -mouse pointer is over a chart._
335 -
336 -### Highlighted time-frame
337 -
338 -To improve visual anomaly detection across charts, the user can highlight a time-frame (by pressing `Alt` + `mouse
339 -selection`) on all charts.
340 -
341 -![An animated GIF of highlighting a specific
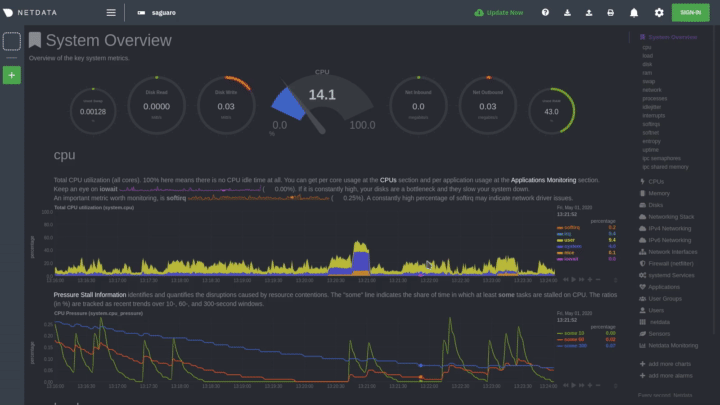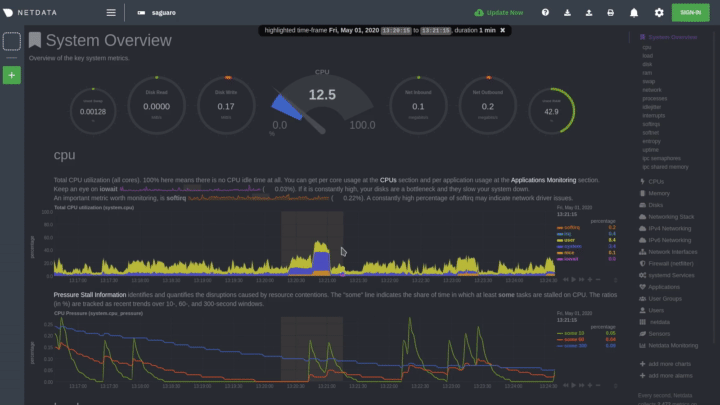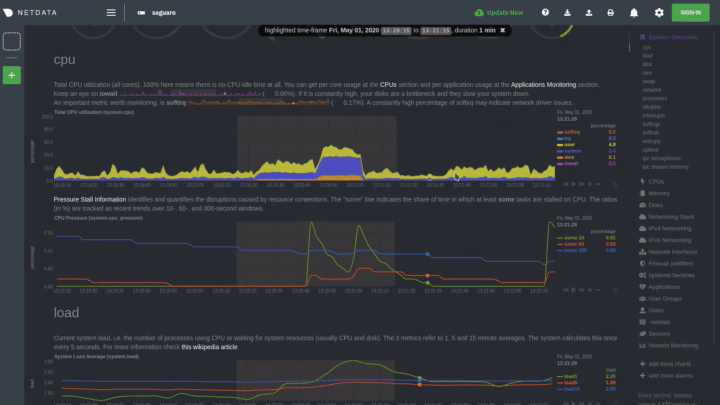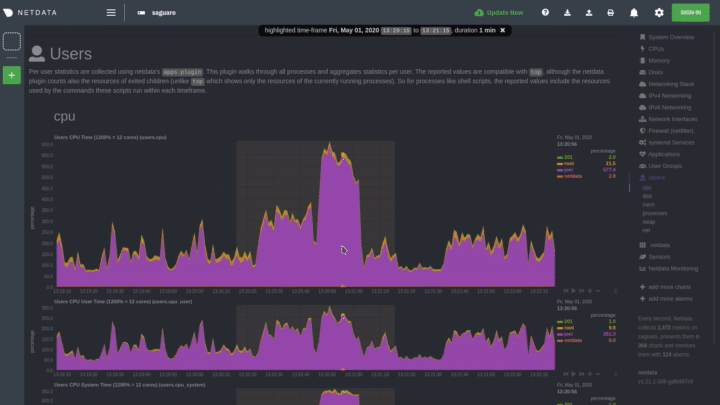
342 -timeframe](https://user-images.githubusercontent.com/1153921/80839611-6ef0c800-8bb0-11ea-9e9c-f75ec9a2e54c.gif)
343 -
344 -_A highlighted time-frame can be given by pressing `Alt` + `mouse selection` on any chart. Netdata will highlight the
345 -same range on all charts._
346 -
347 -## What Netdata monitors
348 -
349 -Netdata can collect metrics from 200+ popular services and applications, on top of dozens of system-related metrics
350 -jocs, such as CPU, memory, disks, filesystems, networking, and more. We call these **collectors**, and they're managed
351 -by [**plugins**](/collectors/plugins.d/README.md), which support a variety of programming languages, including Go and
352 -Python.
353 -
354 -Popular collectors include **Nginx**, **Apache**, **MySQL**, **statsd**, **cgroups** (containers, Docker, Kubernetes,
355 -LXC, and more), **Traefik**, **web server `access.log` files**, and much more.
356 -
357 -See the **full list of [supported collectors](/collectors/COLLECTORS.md)**.
358 -
359 -Netdata's data collection is **extensible**, which means you can monitor anything you can get a metric for. You can even
360 -write a collector for your custom application using our [plugin API](/collectors/plugins.d/README.md).
361 -
362 -## Documentation
363 -
364 -The Netdata documentation is at <https://learn.netdata.cloud>, but you can also find each page inside of Netdata's
365 -repository itself in Markdown (`.md`) files. You can find all our documentation by navigating the repository.
366 -
367 -Here is a quick list of notable documents:
368 -
369 -| Directory | Description |
370 -| :---------------------------------------------------- | :-------------------------------------------------------------------------------------------------------------------- |
371 -| [`installer`](/packaging/installer/README.md) | Instructions to install Netdata on your systems. |
372 -| [`docker`](/packaging/docker/README.md) | Instructions to install Netdata using docker. |
373 -| [`daemon`](/daemon/README.md) | Information about the Netdata daemon and its configuration. |
374 -| [`collectors`](/collectors/README.md) | Information about data collection plugins. |
375 -| [`health`](/health/README.md) | How Netdata's health monitoring works, how to create your own alarms and how to configure alarm notification methods. |
376 -| [`streaming`](/streaming/README.md) | How to build hierarchies of Netdata servers, by streaming metrics between them. |
377 -| [`exporting`](/docs/export/README.md) | Long term archiving of metrics to industry-standard time-series databases, like `prometheus`, `graphite`, `opentsdb`. |
378 -| [`web/api`](/web/api/README.md) | Learn how to query the Netdata API and the queries it supports. |
379 -| [`web/api/badges`](/web/api/badges/README.md) | Learn how to generate badges (SVG images) from live data. |
380 -| [`web/gui/custom`](/web/gui/custom/README.md) | Learn how to create custom Netdata dashboards. |
381 -| [`web/gui/confluence`](/web/gui/confluence/README.md) | Learn how to create Netdata dashboards on Atlassian's Confluence. |
382 -
383 -You can also check all the other directories. Most of them have plenty of documentation.
384 -
385 -## Community
386 -
387 -We welcome [contributions](/CONTRIBUTING.md). Feel free to join the team!
388 -
389 -To report bugs or get help, use [GitHub's issues](https://github.com/netdata/netdata/issues).
390 -
391 -You can also find Netdata on:
392 -
393 -- [Facebook](https://www.facebook.com/linuxnetdata/)
394 -- [Twitter](https://twitter.com/linuxnetdata)
395 -- [StackShare](https://stackshare.io/netdata)
396 -- [Product Hunt](https://www.producthunt.com/posts/netdata-monitoring-agent/)
397 -- [Repology](https://repology.org/metapackage/netdata/versions)
398 -
399 -## License
400 -
401 -Netdata is [GPLv3+](https://github.com/netdata/netdata/blob/master/LICENSE).
402 -
403 -Netdata re-distributes other open-source tools and libraries. Please check the [third party licenses](/REDISTRIBUTED.md).
404 -
405 -## Is it any good?
406 -
407 -Yes.
408 -
409 -_When people first hear about a new product, they frequently ask if it is any good. A Hacker News user
410 -[remarked](https://news.ycombinator.com/item?id=3067434):_
411 -
412 -> Note to self: Starting immediately, all raganwald projects will have a “Is it any good?” section in the readme, and
413 -> the answer shall be “yes.".
414 -
415 -So, we follow the tradition...
416 -
417 -## Is it awesome?
418 -
419 -[These people](https://github.com/netdata/netdata/stargazers) seem to like it.
exporting/README.md
+94 -83
@@ -7,23 +7,21 @@ custom_edit_url: https://github.com/netdata/netdata/edit/master/exporting/README
7
8 # Exporting engine reference
9
10 -Welcome to the exporting engine reference guide.
10 +Welcome to the exporting engine reference guide. This guide contains comprehensive information about enabling,
11 +configuring, and monitoring Netdata's exporting engine, which allows you to send metrics to external time-series
12 +databases.
13
12 -This guide contains comprehensive information about enabling, configuring, and monitoring Netdata's exporting engine,
13 -which allows you to send metrics to more than 20 external time series databases.
14 +For a quick introduction to the exporting engine's features, read our doc on [exporting metrics to time-series
15 +databases](/docs/export/external-databases.md), or jump in to [enabling a connector](/docs/export/enable-connector.md).
16
15 -To learn the basics of locating and editing health configuration files, read up on [how to export
16 -metrics](/docs/export/README.md), and follow the [exporting
17 -quickstart](/docs/export/README.md#exporting-quickstart).
17 +The exporting engine has a modular structure and supports metric exporting via multiple exporting connector instances at
18 +the same time. You can have different update intervals and filters configured for every exporting connector instance.
19
19 -The exporting engine is an update for the former [backends](/backends/README.md), which is deprecated and will be
20 -deleted soon. It has a modular structure and supports metric exporting via multiple exporting connector instances at the
21 -same time. You can have different update intervals and filters configured for every exporting connector instance.
22 -
23 -The exporting engine has its own configuration file `exporting.conf`. Configuration is almost similar to
24 -[backends](/backends/README.md#configuration). The most important difference is that type of a connector should be
25 -specified in a section name before a colon and an instance name after the colon. Also, you can't use `host tags`
26 -anymore. Set your labels using the [`[host labels]`](/docs/guides/using-host-labels.md) section in `netdata.conf`.
20 +The exporting engine has its own configuration file `exporting.conf`. The configuration is almost similar to the
21 +deprecated [backends](/backends/README.md#configuration) system. The most important difference is that type of a
22 +connector should be specified in a section name before a colon and an instance name after the colon. Also, you can't use
23 +`host tags` anymore. Set your labels using the [`[host labels]`](/docs/guides/using-host-labels.md) section in
24 +`netdata.conf`.
25
26 Since Netdata collects thousands of metrics per server per second, which would easily congest any database server when
27 several Netdata servers are sending data to it, Netdata allows sending metrics at a lower frequency, by resampling them.
@@ -33,51 +31,29 @@ X seconds (though, it can send them per second if you need it to).
31
32 ## Features
33
36 -1. Supported databases and services
37 -
38 - - **graphite** (`plaintext interface`, used by **Graphite**, **InfluxDB**, **KairosDB**, **Blueflood**,
39 - **ElasticSearch** via logstash tcp input and the graphite codec, etc)
40 -
41 - Metrics are sent to the database server as `prefix.hostname.chart.dimension`. `prefix` is configured below,
42 - `hostname` is the hostname of the machine (can also be configured).
43 -
44 - Learn more in our guide to [export and visualize Netdata metrics in
34 +1. The exporting engine uses a number of connectors to send Netdata metrics to external time-series databases. See our
35 + [list of supported databases](/docs/export/external-databases.md#supported-databases) for information on which
36 + connector to enable and configure for your database of choice.
37 +
38 + - [**AWS Kinesis Data Streams**](/exporting/aws_kinesis/README.md): Metrics are sent to the service in `JSON`
39 + format.
40 + - [**Google Cloud Pub/Sub Service**](/exporting/pubsub/README.md): Metrics are sent to the service in `JSON`
41 + format.
42 + - [**Graphite**](/exporting/graphite/README.md): A plaintext interface. Metrics are sent to the database server as
43 + `prefix.hostname.chart.dimension`. `prefix` is configured below, `hostname` is the hostname of the machine (can
44 + also be configured). Learn more in our guide to [export and visualize Netdata metrics in
45 Graphite](/docs/guides/export/export-netdata-metrics-graphite.md).
46 -
47 - - **opentsdb** (`telnet or HTTP interfaces`, used by **OpenTSDB**, **InfluxDB**, **KairosDB**, etc)
48 -
49 - metrics are sent to OpenTSDB as `prefix.chart.dimension` with tag `host=hostname`.
50 -
51 - - **json** document DBs
52 -
53 - metrics are sent to a document DB, `JSON` formatted.
54 -
55 - - **prometheus** is described at [prometheus page](/exporting/prometheus/README.md) since it pulls data from
56 - Netdata.
57 -
58 - - **prometheus remote write** (a binary snappy-compressed protocol buffer encoding over HTTP used by
59 - **Elasticsearch**, **Gnocchi**, **Graphite**, **InfluxDB**, **Kafka**, **OpenTSDB**, **PostgreSQL/TimescaleDB**,
60 - **Splunk**, **VictoriaMetrics**, and a lot of other [storage
61 - providers](https://prometheus.io/docs/operating/integrations/#remote-endpoints-and-storage))
62 -
63 - metrics are labeled in the format, which is used by Netdata for the [plaintext prometheus
64 - protocol](/exporting/prometheus/README.md). Notes on using the remote write connector are
65 - [here](/exporting/prometheus/remote_write/README.md).
66 -
67 - - **TimescaleDB** via [community-built connector](/exporting/TIMESCALE.md) that takes JSON streams from a Netdata
68 - client and writes them to a TimescaleDB table.
69 -
70 - - **AWS Kinesis Data Streams**
71 -
72 - metrics are sent to the service in `JSON` format.
73 -
74 - - **Google Cloud Pub/Sub Service**
75 -
76 - metrics are sent to the service in `JSON` format.
77 -
78 - - **MongoDB**
79 -
80 - metrics are sent to the database in `JSON` format.
46 + - [**JSON** document databases](/exporting/json/README.md)
47 + - [**OpenTSDB**](/exporting/opentsdb/README.md): Use a plaintext, HTTP, or HTTPS interfaces. Metrics are sent to
48 + OpenTSDB as `prefix.chart.dimension` with tag `host=hostname`.
49 + - [**MongoDB**](/exporting/mongodb/README.md): Metrics are sent to the database in `JSON` format.
50 + - [**Prometheus**](/exporting/prometheus/README.md): Use an existing Prometheus installation to scrape metrics
51 + from node using the Netdata API.
52 + - [**Prometheus remote write**](/exporting/prometheus/remote_write/README.md). A binary snappy-compressed protocol
53 + buffer encoding over HTTP. Supports many [storage
54 + providers](https://prometheus.io/docs/operating/integrations/#remote-endpoints-and-storage).
55 + - [**TimescaleDB**](/exporting/TIMESCALE.md): Use a community-built connector that takes JSON streams from a
56 + Netdata client and writes them to a TimescaleDB table.
57
58 2. Netdata can filter metrics (at the chart level), to send only a subset of the collected metrics.
59
@@ -113,7 +89,11 @@ X seconds (though, it can send them per second if you need it to).
89
90 ## Configuration
91
116 -In `/etc/netdata/exporting.conf` you should have something like this:
92 +Here are the configruation blocks for every supported connector. Your current `exporting.conf` file may look a little
93 +different.
94 +
95 +You can configure each connector individually using the available [options](#options). The
96 +`[graphite:my_graphite_instance]` block contains examples of some of these additional options in action.
97
98 ```conf
99 [exporting:global]
@@ -123,9 +103,14 @@ In `/etc/netdata/exporting.conf` you should have something like this:
103 update every = 10
104
105 [prometheus:exporter]
126 - send charts matching = system.processes
106 + send names instead of ids = yes
107 + send configured labels = yes
108 + end automatic labels = no
109 + send charts matching = *
110 + send hosts matching = localhost *
111 + prefix = netdata
112
128 -[graphite:my_instance_1]
113 +[graphite:my_graphite_instance]
114 enabled = yes
115 destination = localhost:2003
116 data source = average
@@ -137,39 +122,65 @@ In `/etc/netdata/exporting.conf` you should have something like this:
122 send charts matching = *
123 send hosts matching = localhost *
124 send names instead of ids = yes
125 + send configured labels = yes
126 + send automatic labels = yes
127 +
128 +[prometheus_remote_write:my_prometheus_remote_write_instance]
129 + enabled = yes
130 + destination = localhost
131 + remote write URL path = /receive
132
141 -[json:my_instance2]
133 +[kinesis:my_kinesis_instance]
134 + enabled = yes
135 + destination = us-east-1
136 + stream name = netdata
137 + aws_access_key_id = my_access_key_id
138 + aws_secret_access_key = my_aws_secret_access_key
139 +
140 +[pubsub:my_pubsub_instance]
141 + enabled = yes
142 + destination = pubsub.googleapis.com
143 + credentials file = /etc/netdata/pubsub_credentials.json
144 + project id = my_project
145 + topic id = my_topic
146 +
147 +[mongodb:my_mongodb_instance]
148 + enabled = yes
149 + destination = localhost
150 + database = my_database
151 + collection = my_collection
152 +
153 +[json:my_json_instance]
154 enabled = yes
155 destination = localhost:5448
144 - data source = as collected
145 - update every = 2
146 - send charts matching = system.active_processes
156
148 -[opentsdb:my_instance3]
157 +[opentsdb:my_opentsdb_plaintext_instance]
158 enabled = yes
159 destination = localhost:4242
151 - data source = sum
152 - update every = 10
153 - send charts matching = system.cpu
160
155 -[opentsdb:http:my_instance4]
161 +[opentsdb:http:my_opentsdb_http_instance]
162 enabled = yes
157 - destination = localhost:4243
158 - data source = average
159 - update every = 3
160 - send charts matching = system.active_processes
163 + destination = localhost:4242
164 +
165 +[opentsdb:https:my_opentsdb_https_instance]
166 + enabled = yes
167 + destination = localhost:8082
168 ```
169
163 -Sections:
164 -- `[exporting:global]` is a section where you can set your defaults for all exporting connectors
165 -- `[prometheus:exporter]` defines settings for Prometheus exporter API queries (e.g.:
166 - `http://your.netdata.ip:19999/api/v1/allmetrics?format=prometheus&help=yes&source=as-collected`).
167 -- `[<type>:<name>]` keeps settings for a particular exporting connector instance, where:
168 - - `type` selects the exporting connector type: graphite | opentsdb:telnet | opentsdb:http | opentsdb:https |
169 - prometheus_remote_write | json | kinesis | pubsub | mongodb
170 - - `name` can be arbitrary instance name you chose.
170 +### Sections
171 +
172 +- `[exporting:global]` is a section where you can set your defaults for all exporting connectors
173 +- `[prometheus:exporter]` defines settings for Prometheus exporter API queries (e.g.:
174 + `http://NODE:19999/api/v1/allmetrics?format=prometheus&help=yes&source=as-collected`).
175 +- `[<type>:<name>]` keeps settings for a particular exporting connector instance, where:
176 + - `type` selects the exporting connector type: graphite | opentsdb:telnet | opentsdb:http | opentsdb:https |
177 + prometheus_remote_write | json | kinesis | pubsub | mongodb
178 + - `name` can be arbitrary instance name you chose.
179 +
180 +### Options
181 +
182 +Configure individual connectors and override any global settings with the following options.
183
172 -Options:
184 - `enabled = yes | no`, enables or disables an exporting connector instance
185
186 - `destination = host1 host2 host3 ...`, accepts **a space separated list** of hostnames, IPs (IPv4 and IPv6) and
exporting/graphite/README.md new
+27
@@ -0,0 +1,27 @@
1 +<!--
2 +title: "Export metrics to Graphite providers"
3 +sidebar_label: Graphite
4 +description: "Archive your Agent's metrics to a any Graphite database provider for long-term storage, further analysis, or correlation with data from other sources."
5 +custom_edit_url: https://github.com/netdata/netdata/edit/master/exporting/graphite/README.md
6 +-->
7 +
8 +# Export metrics to Graphite providers
9 +
10 +You can use the Graphite connector for the [exporting engine](/exporting/README.md) to archive your agent's metrics to
11 +Graphite providers for long-term storage, further analysis, or correlation with data from other sources.
12 +
13 +## Configuration
14 +
15 +To enable data exporting to a Graphite database, run `./edit-config exporting.conf` in the Netdata configuration
16 +directory and set the following options:
17 +
18 +```conf
19 +[graphite:my_graphite_instance]
20 + enabled = yes
21 + destination = localhost:2003
22 +```
23 +
24 +The Graphite connector is further configurable using additional settings. See the [exporting reference
25 +doc](/exporting/README.md#options) for details.
26 +
27 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fexporting%2Fjson%2FREADME&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
exporting/json/README.md new
+27
@@ -0,0 +1,27 @@
1 +<!--
2 +title: "Export metrics to JSON document databases"
3 +sidebar_label: JSON
4 +description: "Archive your Agent's metrics to a JSON document database for long-term storage, further analysis, or correlation with data from other sources."
5 +custom_edit_url: https://github.com/netdata/netdata/edit/master/exporting/json/README.md
6 +-->
7 +
8 +# Export metrics to JSON document databases
9 +
10 +You can use the JSON connector for the [exporting engine](/exporting/README.md) to archive your agent's metrics to JSON
11 +document databases for long-term storage, further analysis, or correlation with data from other sources.
12 +
13 +## Configuration
14 +
15 +To enable data exporting to a JSON document database, run `./edit-config exporting.conf` in the Netdata configuration
16 +directory and set the following options:
17 +
18 +```conf
19 +[json:my_json_instance]
20 + enabled = yes
21 + destination = localhost:5448
22 +```
23 +
24 +The JSON connector is further configurable using additional settings. See the [exporting reference
25 +doc](/exporting/README.md#options) for details.
26 +
27 +[![analytics](https://www.google-analytics.com/collect?v=1&aip=1&t=pageview&_s=1&ds=github&dr=https%3A%2F%2Fgithub.com%2Fnetdata%2Fnetdata&dl=https%3A%2F%2Fmy-netdata.io%2Fgithub%2Fexporting%2Fjson%2FREADME&_u=MAC~&cid=5792dfd7-8dc4-476b-af31-da2fdb9f93d2&tid=UA-64295674-3)](<>)
streaming/README.md
+1 -1
@@ -492,7 +492,7 @@ this writing, Netdata supports:
492 - json document DBs
493 - all the compatibles to the above (e.g. kairosdb, influxdb, etc)
494
495 -Check the Netdata [exporting documentation](/docs/export/README.md) for configuring this.
495 +Check the Netdata [exporting documentation](/docs/export/external-databases.md) for configuring this.
496
497 This is how such a solution will work:
498