Docs: Promote DB engine/long-term metrics storage more heavily (#8031)
* Fixes to DOCS home and README * Edit conf-guide and getting-started * Add dbengine settings to map * Fix tutorial and step-by-step * Fix artifacts of old memory mode types * A few tweaks * Push a little harder on README * Fix for Markos
Joel Hans committed
Feb 11, 2020 at 06:24 UTC
64dbeb929e2437ba65e628e81a6f546b42dcd4fa
12 files changed
+114
-122
DOCUMENTATION.md
+4
-1
@@ -2,7 +2,8 @@
2
3
**Netdata is real-time health monitoring and performance troubleshooting for systems and applications.** It helps you
4
instantly diagnose slowdowns and anomalies in your infrastructure with thousands of metrics, interactive visualizations,
5
-and insightful health alarms.
5
+and insightful health alarms. Plus, long-term storage comes ready out-of-the-box, so can collect, monitor, and maintain
6
+your metrics in one insightful place.
7
8
## Navigating the Netdata documentation
9
@@ -56,6 +57,8 @@ Add as many nodes as you'd like!
57
**Advanced users**: For those who already understand how to access a Netdata dashboard and perform basic configuration,
58
feel free to see what's behind any of these other doors.
59
60
+- [Tutorial: Change how long Netdata stores metrics](docs/tutorials/longer-metrics-storage.md): Extend Netdata's
61
+ long-term metrics storage database by allowing Netdata to use more of your system's RAM and disk.
62
- [Netdata Behind Nginx](docs/Running-behind-nginx.md): Use an Nginx web server instead of Netdata's built-in server
63
to enable TLS, HTTPS, and basic authentication.
64
- [Add More Charts](docs/Add-more-charts-to-netdata.md): Enable new internal or external plugins and understand when
README.md
+24
-20
@@ -13,15 +13,17 @@ PYTHON](https://img.shields.io/lgtm/grade/python/g/netdata/netdata.svg?logo=lgtm
13
14
---
15
16
-**Netdata** is **distributed, real-time, performance and health monitoring for systems and applications**. It is a
16
+Netdata is **distributed, real-time performance and health monitoring** for systems and applications. It is a
17
highly-optimized monitoring agent you install on all your systems and containers.
18
19
-Netdata provides **unparalleled insights**, **in real-time**, of everything happening on the systems it runs (including
20
-web servers, databases, applications), using **highly interactive web dashboards**. It can run autonomously, without any
21
-third-party components, or it can be integrated to existing monitoring toolchains (Prometheus, Graphite, OpenTSDB,
22
-Kafka, Grafana, and more).
19
+Netdata provides **unparalleled insights**, in **real-time**, of everything happening on the systems it's running on
20
+(including web servers, databases, applications), using **highly interactive web dashboards**.
21
24
-Netdata is **fast** and **efficient**, designed to permanently run on all systems (**physical** & **virtual** servers,
22
+A highly-efficient database **stores long-term historical metrics for days, weeks, or months**, all at 1-second
23
+granularity. Run this long-term storage autonomously, or integrate Netdata with your existing monitoring toolchains
24
+(Prometheus, Graphite, OpenTSDB, Kafka, Grafana, and more).
25
+
26
+Netdata is **fast** and **efficient**, designed to permanently run on all systems (**physical** and **virtual** servers,
27
**containers**, **IoT** devices), without disrupting their core function.
28
29
Netdata is **free, open-source software** and it currently runs on **Linux**, **FreeBSD**, and **MacOS**, along with
@@ -171,25 +173,26 @@ Netdata is a monitoring agent you install on all your systems. It is:
173
174
- A **metrics collector** for system and application metrics (including web servers, databases, containers, and much
175
more),
174
-- A custom **database engine** to store recent metrics in memory and "spill" historical metrics to disk for efficient
175
- long-term storage,
176
+- A **long-term metrics database** that stores recent metrics in memory and "spills" historical metrics to disk for
177
+ efficient long-term storage,
178
- A super fast, interactive, and modern **metrics visualizer** optimized for anomaly detection,
177
-- And an **alarms notification engine** - an advanced watchdog for detecting performance and availability issues
179
+- And an **alarms notification engine** for detecting performance and availability issues.
180
181
All the above, are packaged together in a very flexible, extremely modular, distributed application.
182
183
This is how Netdata compares to other monitoring solutions:
184
183
-| Netdata | others (open-source and commercial) |
184
-| :-------------------------------------------------------------- | :----------------------------------------------------- |
185
-| **High resolution metrics** (1s granularity) | Low resolution metrics (10s granularity at best) |
186
-| Monitors everything, **thousands of metrics per node** | Monitor just a few metrics |
187
-| UI is super fast, optimized for **anomaly detection** | UI is good for just an abstract view |
188
-| **Meaningful presentation**, to help you understand the metrics | You have to know the metrics before you start |
189
-| Install and get results **immediately** | Long preparation is required to get any useful results |
190
-| Use it for **troubleshooting** performance problems | Use them to get _statistics of past performance_ |
191
-| **Kills the console** for tracing performance issues | The console is always required for troubleshooting |
192
-| Requires **zero dedicated resources** | Require large dedicated resources |
185
+| Netdata | others (open-source and commercial) |
186
+| :-------------------------------------------------------------- | :--------------------------------------------------------------- |
187
+| **High resolution metrics** (1s granularity) | Low resolution metrics (10s granularity at best) |
188
+| Monitors everything, **thousands of metrics per node** | Monitor just a few metrics |
189
+| UI is super fast, optimized for **anomaly detection** | UI is good for just an abstract view |
190
+| **Long-term, autonomous storage** at one-second granularity | Centralized metrics in an expensive data lake at 10s granularity |
191
+| **Meaningful presentation**, to help you understand the metrics | You have to know the metrics before you start |
192
+| Install and get results **immediately** | Long preparation is required to get any useful results |
193
+| Use it for **troubleshooting** performance problems | Use them to get _statistics of past performance_ |
194
+| **Kills the console** for tracing performance issues | The console is always required for troubleshooting |
195
+| Requires **zero dedicated resources** | Require large dedicated resources |
196
197
Netdata is **open-source**, **free**, super **fast**, very **easy**, completely **open**, extremely **efficient**,
198
**flexible** and integrate-able.
@@ -282,7 +285,8 @@ This is what you should expect from Netdata:
285
- **1s granularity** - The highest possible resolution for all metrics.
286
- **Unlimited metrics** - Netdata collects all the available metrics—the more, the better.
287
- **1% CPU utilization of a single core** - It's unbelievably optimized.
285
-- **A few MB of RAM** - The low-memory round-robin option uses 25MB RAM, and you can [resize it](database/).
288
+- **A few MB of RAM** - The highly-efficient database engine stores per-second metrics in RAM and then "spills"
289
+ historical metrics to disk long-term storage.
290
- **Minimal disk I/O** - While running, Netdata only writes historical metrics and reads `error` and `access` logs.
291
- **Zero configuration** - Netdata auto-detects everything, and can collect up to 10,000 metrics per server out of the
292
box.
daemon/README.md
+3
-3
@@ -4,9 +4,9 @@
4
5
- You can start Netdata by executing it with `/usr/sbin/netdata` (the installer will also start it).
6
7
-- You can stop Netdata by killing it with `killall netdata`. You can stop and start Netdata at any point. Netdata
8
- saves on exit its round robbin database to `/var/cache/netdata` so that it will continue from where it stopped the
9
- last time.
7
+- You can stop Netdata by killing it with `killall netdata`. You can stop and start Netdata at any point. When
8
+ exiting, the [database engine](../database/engine/README.md) saves metrics to `/var/cache/netdata/dbengine/` so that
9
+ it can continue when started again.
10
11
Access to the web site, for all graphs, is by default on port `19999`, so go to:
12
daemon/config/README.md
+5
-2
@@ -46,7 +46,7 @@ Please note that your data history will be lost if you have modified `history` p
46
| glibc malloc arena max for plugins|`1`|See [Virtual memory](../#virtual-memory).|||
47
| glibc malloc arena max for Netdata|`1`|See [Virtual memory](../#virtual-memory).|||
48
| hostname|auto-detected|The hostname of the computer running Netdata.|||
49
-| history|`3996`|The number of entries the `netdata` daemon will by default keep in memory for each chart dimension. This setting can also be configured per chart. Check [Memory Requirements](../../database/#database) for more information.|||
49
+| history|`3996`| Used with `memory mode = save/map/ram/alloc`, not the default `memory mode = dbengine`. This number reflects the number of entries the `netdata` daemon will by default keep in memory for each chart dimension. This setting can also be configured per chart. Check [Memory Requirements](../../database/README.md#database) for more information. |||
50
| update every|`1`|The frequency in seconds, for data collection. For more information see [Performance](../../docs/Performance.md#performance).|||
51
| config directory|`/etc/netdata`|The directory configuration files are kept.|||
52
| stock config directory|`/usr/lib/netdata/conf.d`||||
@@ -56,7 +56,10 @@ Please note that your data history will be lost if you have modified `history` p
56
| lib directory|`/var/lib/netdata`|Contains the alarm log and the Netdata instance guid.|||
57
| home directory|`/var/cache/netdata`|Contains the db files for the collected metrics|||
58
| plugins directory|`"/usr/libexec/netdata/plugins.d" "/etc/netdata/custom-plugins.d"`|The directory plugin programs are kept. This setting supports multiple directories, space separated. If any directory path contains spaces, enclose it in single or double quotes.|||
59
-| memory mode|`save`|When set to `save` Netdata will save its round robin database on exit and load it on startup. When set to `map` the cache files will be updated in real time (check `man mmap` - do not set this on systems with heavy load or slow disks - the disks will continuously sync the in-memory database of Netdata). When set to `dbengine` it behaves similarly to `map` but with much better disk and memory efficiency, however, with higher overhead. When set to `ram` the round robin database will be temporary and it will be lost when Netdata exits. `none` disables the database at this host. This also disables health monitoring (there cannot be health monitoring without a database). host access prefix||This is used in docker environments where /proc, /sys, etc have to be accessed via another path. You may also have to set SYS_PTRACE capability on the docker for this work. Check [issue 43](https://github.com/netdata/netdata/issues/43).|
59
+| memory mode | `dbengine` | `dbengine`: The default for long-term metrics storage with efficient RAM and disk usage. Can be extended with `page cache size` and `dbengine disk space`. <br />`save`: Netdata will save its round robin database on exit and load it on startup. <br />`map`: Cache files will be updated in real-time. Not ideal for systems with high load or slow disks (check `man mmap`). <br />`ram`: The round-robin database will be temporary and it will be lost when Netdata exits. <br />`none`: Disables the database at this host, and disables health monitoring entirely, as that requires a database of metrics. |
60
+| page cache size | 32 | Determines the amount of RAM in MiB that is dedicated to caching Netdata metric values. |||
61
+| dbengine disk space | 256 | Determines the amount of disk space in MiB that is dedicated to storing Netdata metric values and all related metadata describing them |||
62
+| host access prefix||This is used in docker environments where /proc, /sys, etc have to be accessed via another path. You may also have to set SYS_PTRACE capability on the docker for this work. Check [issue 43](https://github.com/netdata/netdata/issues/43).|
63
| memory deduplication (ksm)|`yes`|When set to `yes`, Netdata will offer its in-memory round robin database to kernel same page merging (KSM) for deduplication. For more information check [Memory Deduplication - Kernel Same Page Merging - KSM](../../database/#ksm)|||
64
| TZ environment variable|`:/etc/localtime`|Where to find the timezone|||
65
| timezone|auto-detected|The timezone retrieved from the environment variable|||
database/README.md
+17
-37
@@ -1,60 +1,40 @@
1
# Database
2
3
-Although `netdata` does all its calculations using `long double`, it stores all values using a [custom-made 32-bit
4
-number](../libnetdata/storage_number/).
3
+Netdata is fully capable of long-term metrics storage, at per-second granularity, via its default database engine
4
+(`dbengine`). But to remain as flexible as possible, Netdata supports a number of types of metrics storage:
5
6
-So, for each dimension of a chart, Netdata will need: `4 bytes for the value * the entries of its history`. It will not
7
-store any other data for each value in the time series database. Since all its values are stored in a time series with
8
-fixed step, the time each value corresponds can be calculated at run time, using the position of a value in the round
9
-robin database.
10
-
11
-The default history is 3.600 entries, thus it will need 14.4KB for each chart dimension. If you need 1.000 dimensions,
12
-they will occupy just 14.4MB.
13
-
14
-Of course, 3.600 entries is a very short history, especially if data collection frequency is set to 1 second. You will
15
-have just one hour of data.
16
-
17
-For a day of data and 1.000 dimensions, you will need: `86.400 seconds * 4 bytes * 1.000 dimensions = 345MB of RAM`.
18
-
19
-One option you have to lower this number is to use **[Memory Deduplication - Kernel Same Page Merging - KSM](#ksm)**.
20
-Another possibility is to use the **[Database Engine](engine/)**.
21
-
22
-## Memory modes
23
-
24
-Currently Netdata supports 6 memory modes:
6
+1. `dbengine`, (the default) data are in database files. The [Database Engine](engine/) works like a traditional
7
+ database. There is some amount of RAM dedicated to data caching and indexing and the rest of the data reside
8
+ compressed on disk. The number of history entries is not fixed in this case, but depends on the configured disk
9
+ space and the effective compression ratio of the data stored. This is the **only mode** that supports changing the
10
+ data collection update frequency (`update_every`) **without losing** the previously stored metrics. For more details
11
+ see [here](engine/).
12
26
-1. `ram`, data are purely in memory. Data are never saved on disk. This mode uses `mmap()` and supports [KSM](#ksm).
13
+2. `ram`, data are purely in memory. Data are never saved on disk. This mode uses `mmap()` and supports [KSM](#ksm).
14
28
-2. `save`, data are only in RAM while Netdata runs and are saved to / loaded from disk on Netdata
15
+3. `save`, data are only in RAM while Netdata runs and are saved to / loaded from disk on Netdata
16
restart. It also uses `mmap()` and supports [KSM](#ksm).
17
31
-3. `map`, data are in memory mapped files. This works like the swap. Keep in mind though, this will have a constant
18
+4. `map`, data are in memory mapped files. This works like the swap. Keep in mind though, this will have a constant
19
write on your disk. When Netdata writes data on its memory, the Linux kernel marks the related memory pages as dirty
20
and automatically starts updating them on disk. Unfortunately we cannot control how frequently this works. The Linux
21
kernel uses exactly the same algorithm it uses for its swap memory. Check below for additional information on
22
running a dedicated central Netdata server. This mode uses `mmap()` but does not support [KSM](#ksm).
23
37
-4. `none`, without a database (collected metrics can only be streamed to another Netdata).
24
+5. `none`, without a database (collected metrics can only be streamed to another Netdata).
25
39
-5. `alloc`, like `ram` but it uses `calloc()` and does not support [KSM](#ksm). This mode is the fallback for all
26
+6. `alloc`, like `ram` but it uses `calloc()` and does not support [KSM](#ksm). This mode is the fallback for all
27
others except `none`.
28
42
-6. `dbengine`, (the default) data are in database files. The [Database Engine](engine/) works like a traditional
43
- database. There is some amount of RAM dedicated to data caching and indexing and the rest of the data reside
44
- compressed on disk. The number of history entries is not fixed in this case, but depends on the configured disk
45
- space and the effective compression ratio of the data stored. This is the **only mode** that supports changing the
46
- data collection update frequency (`update_every`) **without losing** the previously stored metrics. For more details
47
- see [here](engine/).
48
-
29
You can select the memory mode by editing `netdata.conf` and setting:
30
31
```conf
32
[global]
53
- # dbengine (default), ram, save (the default if dbengine not available), map (swap like), none, alloc
54
- memory mode = dbengine
33
+ # dbengine (default), ram, save (the default if dbengine not available), map (swap like), none, alloc
34
+ memory mode = dbengine
35
56
- # the directory where data are saved
57
- cache directory = /var/cache/netdata
36
+ # the directory where data are saved
37
+ cache directory = /var/cache/netdata
38
```
39
40
## Running Netdata in embedded devices
docs/Performance.md
+17
-20
@@ -45,11 +45,15 @@ Netdata runs with the lowest possible process priority, so even if 1000 users ar
45
46
To lower the CPU utilization of Netdata when clients are accessing the dashboard, set `web compression level = 1`, or disable web compression completely by setting `enable web responses gzip compression = no`. Both settings are in the `[web]` section.
47
48
-## Monitoring a heavy loaded system
48
+## Monitoring a heavily-loaded system
49
50
-Netdata, while running, does not depend on disk I/O (apart its log files and `access.log` is written with buffering enabled and can be disabled). Some plugins that need disk may stop and show gaps during heavy system load, but the Netdata daemon itself should be able to work and collect values from `/proc` and `/sys` and serve web clients accessing it.
50
+While running, Netdata does not depend much on disk I/O aside from writing to log files and the [database
51
+engine](../database/engine/README.md) "spilling" historical metrics to disk when it uses all its available RAM.
52
52
-Keep in mind that Netdata saves its database when it exits and loads it back when restarted. While it is running though, its DB is only stored in RAM and no I/O takes place for it.
53
+Under a heavy system load, plugins that need disk may stop and show gaps during heavy system load, but the Netdata
54
+daemon itself should be able to work and collect values from `/proc` and `/sys` and serve web clients accessing it.
55
+
56
+Keep in mind that Netdata saves its database when it exits, and loads it up again when started.
57
58
## Netdata process priority
59
@@ -173,29 +177,22 @@ Normally, you will not need them. To disable them, set:
177
access log = none
178
```
179
176
-### 5. Set memory mode to RAM
180
+### 5. Lower Netdata's memory usage
181
178
-Setting the memory mode to `ram` will disable loading and saving the round robin database. This will not affect anything while running Netdata, but it might be required if you have very limited storage available.
182
+You can change the amount of RAM and disk the database engine uses for all charts and their dimensions with the
183
+following settings in the `[global]` section of `netdata.conf`:
184
180
-```
185
+```conf
186
[global]
182
- memory mode = ram
187
+ # memory mode = dbengine
188
+ # page cache size = 32
189
+ # dbengine disk space = 256
190
```
191
185
-### 6. Lower memory requirements
186
-
187
-You can set the default size of the round robin database for all charts, using:
188
-
189
-```
190
-[global]
191
- history = 600
192
-```
193
-
194
-The units for history is `[global].update every` seconds. So if `[global].update every = 6` and `[global].history = 600`, you will have an hour of data ( 6 x 600 = 3.600 ), which will store 600 points per dimension, one every 6 seconds.
195
-
196
-Check also [Database](../database) for directions on calculating the size of the round robin database.
192
+See the [database engine documentation](../database/engine/README.md) or our [tutorial on metrics
193
+retention](tutorials/longer-metrics-storage.md) for more details on lowering the database engine's memory requirements.
194
198
-### 7. Disable gzip compression of responses
195
+### 6. Disable gzip compression of responses
196
197
Gzip compression of the web responses is using more CPU that the rest of Netdata. You can lower the compression level or disable gzip compression completely. You can disable it, like this:
198
docs/configuration-guide.md
+5
-3
@@ -53,10 +53,12 @@ it there.
53
54
### Change what I see
55
56
-#### Increase the metrics retention period
56
+#### Increase the long-term metrics retention period
57
58
-Increase `history` in [netdata.conf \[global\]](../daemon/config/README.md#global-section-options). Just ensure you
59
-understand [how much memory will be required](../database/).
58
+Increase the values for the `page cache size` and `dbengine disk space` settings in the [`[global]`
59
+section](../daemon/config/README.md#global-section-options) of `netdata.conf`. Read our tutorial on [increasing
60
+long-term metrics storage](tutorials/longer-metrics-storage.md) and the [memory requirements for the database
61
+engine](../database/engine/README.md#memory-requirements).
62
63
#### Reduce the data collection frequency
64
docs/getting-started.md
+21
-23
@@ -3,8 +3,8 @@
3
Thanks for trying Netdata! In this getting started guide, we'll quickly walk you through the first steps you should take
4
after getting Netdata installed.
5
6
-Netdata can collect thousands of metrics in real-time without any configuration, but there are some valuable things to
7
-know to get the most out of Netdata based on your needs.
6
+Netdata can collect thousands of metrics in real-time and use its database for long-term metrics storage without any
7
+configuration, but there are some valuable things to know to get the most out of Netdata based on your needs.
8
9
We'll skip right into some technical details, so if you're brand-new to monitoring the health and performance of systems
10
and applications, our [**step-by-step tutorial**](step-by-step/step-00.md) might be a better fit.
@@ -42,13 +42,30 @@ Once you save your changes, [restart Netdata](#start-stop-and-restart-netdata) t
42
43
**What's next?**:
44
45
-- [Change how long Netdata stores metrics](#change-how-long-netdata-stores-metrics) by either increasing the `history`
46
- option or switching to the database engine.
45
+- [Change how long Netdata stores metrics](#change-how-long-netdata-stores-metrics) by changing the `page cache size`
46
+ and `dbengine disk space` settings in `netdata.conf`.
47
- Move Netdata's dashboard to a [different port](https://docs.netdata.cloud/web/server/) or enable TLS/HTTPS
48
encryption.
49
- See all the `netdata.conf` options in our [daemon configuration documentation](../daemon/config/).
50
- Run your own [registry](../registry/README.md#run-your-own-registry).
51
52
+## Change how long Netdata stores metrics
53
+
54
+Netdata can store long-term, historical metrics out of the box. A custom database uses RAM to store recent metrics,
55
+ensuring dashboards and API queries are extremely responsive, while "spilling" historical metrics to disk. This
56
+configuration keeps RAM usage low while allowing for long-term, on-disk metrics storage.
57
+
58
+You can tweak this custom _database engine_ to store a much larger dataset than your system's available RAM,
59
+particularly if you allow Netdata to use slightly more RAM and disk space than the default configuration.
60
+
61
+Read our tutorial, [**Changing how long Netdata stores metrics**](../docs/tutorials/longer-metrics-storage.md), to learn
62
+more.
63
+
64
+**What's next?**:
65
+
66
+- Learn more about the [memory requirements for the database engine](../database/engine/README.md#memory-requirements)
67
+ to understand how much RAM/disk space you should commit to storing historical metrics.
68
+
69
## Collect data from more sources
70
71
When Netdata _starts_, it auto-detects dozens of **data sources**, such as database servers, web servers, and more. To
@@ -162,25 +179,6 @@ Find the `SEND_EMAIL="YES"` line and change it to `SEND_EMAIL="NO"`.
179
- See all the alarm options via the [health configuration reference](../health/REFERENCE.md).
180
- Add a new notification method, like [Slack](../health/notifications/slack/).
181
165
-## Change how long Netdata stores metrics
166
-
167
-By default, Netdata uses a custom database which uses both RAM and the disk to store metrics. Recent metrics are stored
168
-in the system's RAM to keep access fast, while historical metrics are "spilled" to disk to keep RAM usage low.
169
-
170
-This custom database, which we call the _database engine_, allows you to store a much larger dataset than your system's
171
-available RAM.
172
-
173
-If you're not sure whether you're using the database engine, or want to tweak the default settings to store even more
174
-historical metrics, check out our tutorial: [**Changing how long Netdata stores
175
-metrics**](../docs/tutorials/longer-metrics-storage.md).
176
-
177
-**What's next?**:
178
-
179
-- Learn more about the [memory requirements for the database engine](../database/engine/README.md#memory-requirements)
180
- to understand how much RAM/disk space you should commit to storing historical metrics.
181
-- Read up on the memory requirements of the [round-robin database](../database/), or figure out whether your system
182
- has KSM enabled, which can [reduce the default database's memory usage](../database/README.md#ksm) by about 60%.
183
-
182
## Monitoring multiple systems with Netdata
183
184
If you have Netdata installed on multiple systems, you can have them all appear in the **My nodes** menu at the top-left
docs/step-by-step/step-00.md
+3
-2
@@ -98,8 +98,9 @@ you choose. You can even monitor many systems from a single HTML file.
98
99
[Step 9. Long-term metrics storage](step-09.md)
100
101
-Want to store lots of real-time metrics from Netdata? Tweak our custom database to your heart's content. Want to take
102
-your Netdata metrics elsewhere? We're happy to help you archive data to Prometheus, MongoDB, TimescaleDB, and others.
101
+By default, Netdata can store lots of real-time metrics, but you can also tweak our custom database engine to your
102
+heart's content. Want to take your Netdata metrics elsewhere? We're happy to help you archive data to Prometheus,
103
+MongoDB, TimescaleDB, and others.
104
105
[Step 10. Set up a proxy](step-10.md)
106
docs/step-by-step/step-01.md
+8
-7
@@ -39,9 +39,9 @@ we'll cover throughout this tutorial.
39
with hundreds of charts, is your main source of information about the health and performance of your systems/
40
applications. We designed the dashboard with anomaly detection and quick analysis in mind. We'll return to
41
dashboard-related topics in both [step 7](step-07.md) and [step 8](step-08.md).
42
-- **Netdata Cloud** is our SaaS toolkit that helps Netdata users monitor the health and performance of entire
43
- infrastructures, whether they are two or two thousand (or more!) systems. We'll cover Netdata Cloud in [step
44
- 3](step-03.md).
42
+- **Long-term metrics storage** by default. With our new database engine, you can store days, weeks, or months of
43
+ per-second historical metrics. Or you can archive metrics to another database, like MongoDB or Prometheus. We'll
44
+ cover all these options in [step 9](step-09.md).
45
- **No configuration necessary**. Without any configuration, you'll get thousands of real-time metrics and hundreds of
46
alarms designed by our community of sysadmin experts. But you _can_ configure Netdata in a lot of ways, some of
47
which we'll cover in [step 4](step-04.md).
@@ -53,9 +53,9 @@ we'll cover throughout this tutorial.
53
into how you can tune alarms, write your own alarm, and enable two types of notifications.
54
- **High-speed, low-resource collectors** that allow you to collect thousands of metrics every second while using only
55
a fraction of your system's CPU resources and a few MiB of RAM.
56
-- **Long-term metrics storage**. With our new database engine, you can store days, weeks, or months of per-second
57
- historical metrics. Or you can archive metrics to another database, like MongoDB or Prometheus. We'll cover all
58
- these options in [step 9](step-09.md).
56
+- **Netdata Cloud** is our SaaS toolkit that helps Netdata users monitor the health and performance of entire
57
+ infrastructures, whether they are two or two thousand (or more!) systems. We'll cover Netdata Cloud in [step
58
+ 3](step-03.md).
59
60
## Why you should use Netdata
61
@@ -82,7 +82,8 @@ For example, Netdata can [collect 100,000 metrics](https://github.com/netdata/ne
82
using only 9% of a single server-grade CPU core!
83
84
By decentralizing monitoring and emphasizing speed at every turn, Netdata helps you scale your health monitoring and
85
-performance troubleshooting to an infrastructure of every size. _And_ you get to keep per-second metrics.
85
+performance troubleshooting to an infrastructure of every size. _And_ you get to keep per-second metrics in long-term
86
+storage thanks to the database engine.
87
88
### Unlimited metrics
89
docs/step-by-step/step-04.md
+3
-1
@@ -117,7 +117,9 @@ Once you're done, restart Netdata and refresh the dashboard. Say hello to your r
117
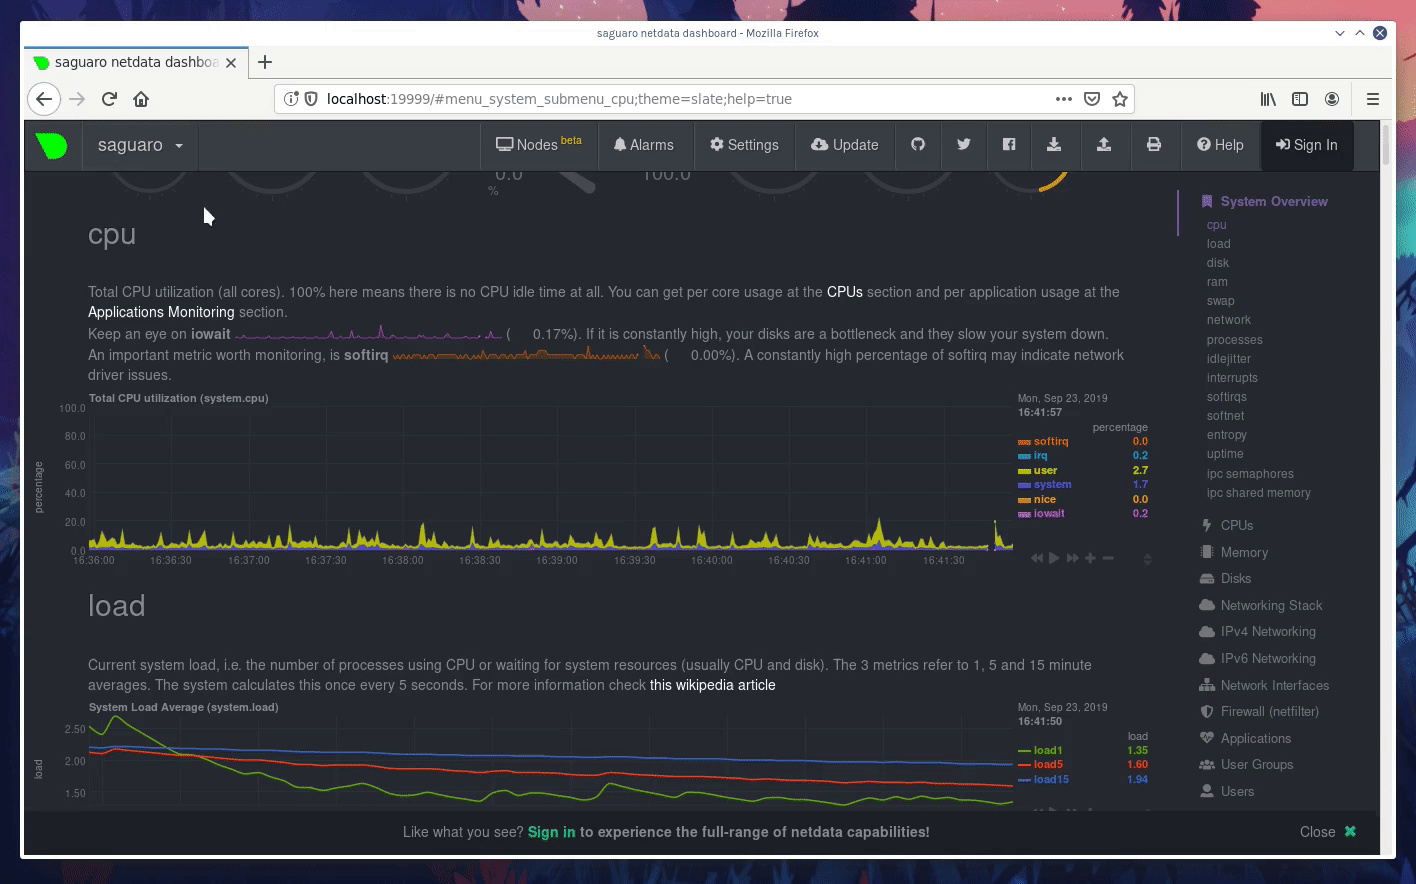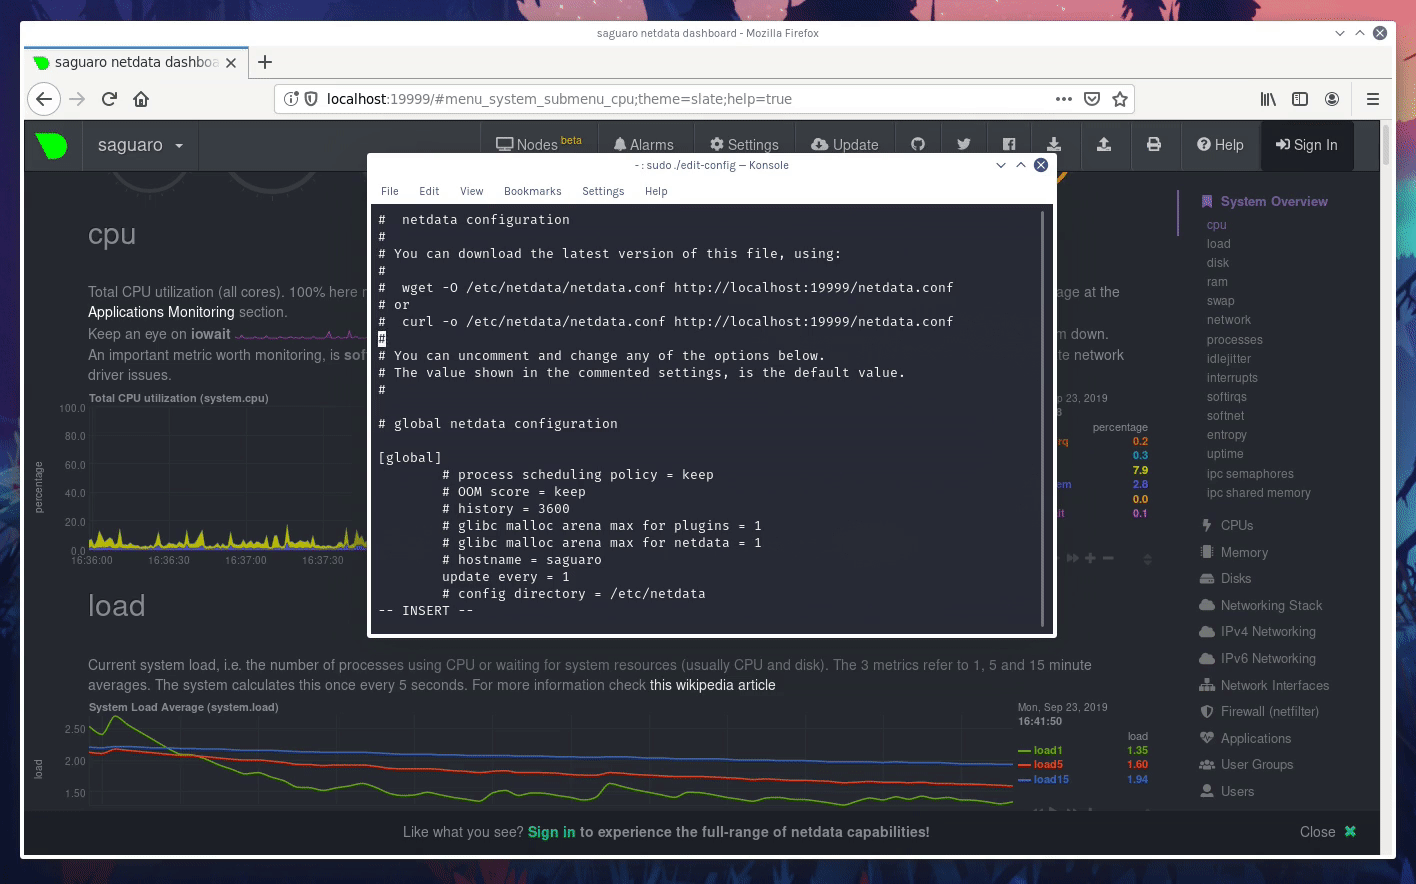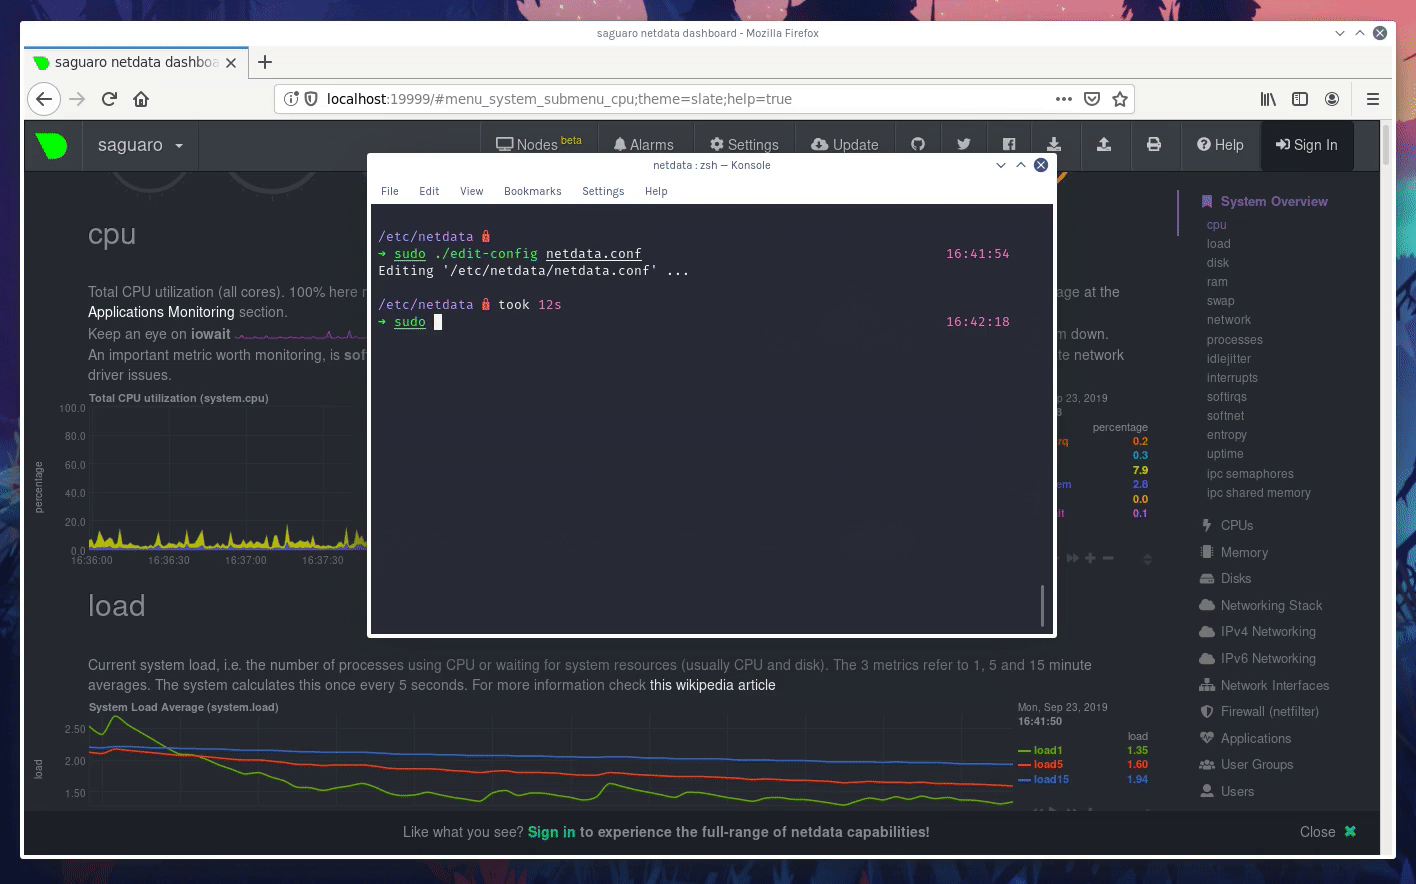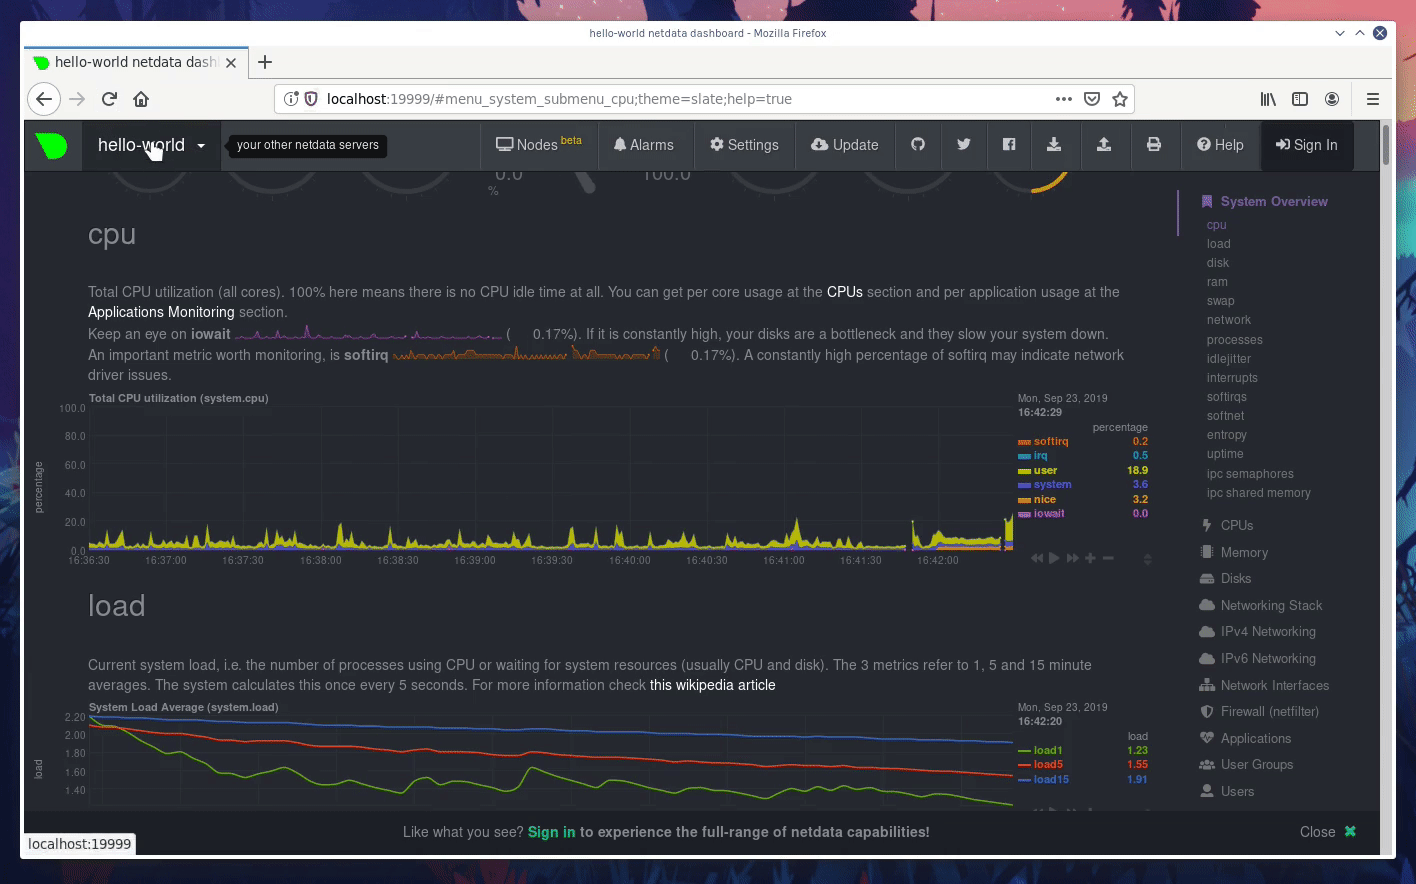
119
120
-Netdata has dozens upon dozens of options you can change. To see them all, read our [daemon configuration](../../daemon/config/).
120
+Netdata has dozens upon dozens of options you can change. To see them all, read our [daemon
121
+configuration](../../daemon/config/), or hop into our popular tutorial on [increasing long-term metrics
122
+storage](../tutorials/longer-metrics-storage.md).
123
124
## What's next?
125
docs/tutorials/longer-metrics-storage.md
+4
-3
@@ -3,9 +3,10 @@
3
Netdata helps you collect thousands of system and application metrics every second, but what about storing them for the
4
long term?
5
6
-Many people think Netdata can only store about an hour's worth of real-time metrics, but that's just the default
7
-configuration today. With the right settings, Netdata is quite capable of efficiently storing hours or days worth of
8
-historical, per-second metrics without having to rely on a [backend](../../backends/).
6
+Many people think Netdata can only store about an hour's worth of real-time metrics, but that's simply not true any
7
+more. With the right settings, Netdata is quite capable of efficiently storing hours or days worth of historical,
8
+per-second metrics without having to rely on a [backend](../../backends/) or [exporting
9
+connector](../../exporting/README.md).
10
11
This tutorial gives two options for configuring Netdata to store more metrics. **We recommend the default [database
12
engine](#using-the-database-engine)**, but you can stick with or switch to the round-robin database if you prefer.