Replace hardcoded links pointing to "learn.netdata.cloud" with github absolute links (#14779)
* Update REFERENCE.md * replace redirected links * format the files * fix redirected link * format the file * replace hardcoded links
Fotis Voutsas committed
Mar 21, 2023 at 16:41 UTC
9385b062f649fd197e7ba411120516fb5f9f46d7
19 files changed
+148
-213
collectors/COLLECTORS.md
+6
-15
@@ -1,12 +1,3 @@
1
-<!--
2
-title: "Monitor anything with Netdata"
3
-description: "Netdata gathers real-time metrics from hundreds of data sources using collectors. Most require zero configuration and are pre-configured out of the box."
4
-custom_edit_url: "https://github.com/netdata/netdata/edit/master/collectors/COLLECTORS.md"
5
-sidebar_label: "Monitor"
6
-learn_status: "Published"
7
-learn_rel_path: "Integrations/Monitor"
8
--->
9
-
1
# Monitor anything with Netdata
2
3
Netdata uses collectors to help you gather metrics from your favorite applications and services and view them in
@@ -31,13 +22,13 @@ accompanying configuration file.
22
23
If you don't see the app/service you'd like to monitor in this list:
24
34
-- If your application has a Prometheus endpoint, Netdata can monitor it! Look at our
25
+- If your application has a Prometheus endpoint, Netdata can monitor it! Look at our
26
[generic Prometheus collector](https://github.com/netdata/go.d.plugin/blob/master/modules/prometheus/README.md).
27
37
-- If your application is instrumented to expose [StatsD](https://blog.netdata.cloud/introduction-to-statsd/) metrics,
28
+- If your application is instrumented to expose [StatsD](https://blog.netdata.cloud/introduction-to-statsd/) metrics,
29
see our [generic StatsD collector](https://github.com/netdata/netdata/blob/master/collectors/statsd.plugin/README.md).
30
40
-- If you have data in CSV, JSON, XML or other popular formats, you may be able to use our
31
+- If you have data in CSV, JSON, XML or other popular formats, you may be able to use our
32
[generic structured data (Pandas) collector](https://github.com/netdata/netdata/blob/master/collectors/python.d.plugin/pandas/README.md),
33
34
- Check out our [GitHub issues](https://github.com/netdata/netdata/issues). Use the search bar to look for previous
@@ -47,12 +38,12 @@ If you don't see the app/service you'd like to monitor in this list:
38
a [feature request](https://github.com/netdata/netdata/issues/new/choose) on GitHub.
39
40
- If you have basic software development skills, you can add your own plugin
50
- in [Go](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin#how-to-develop-a-collector)
41
+ in [Go](https://github.com/netdata/go.d.plugin/blob/master/README.md#how-to-develop-a-collector)
42
or [Python](https://github.com/netdata/netdata/blob/master/docs/guides/python-collector.md)
43
44
## Available Collectors
45
55
-- [Supported collectors list](#supported-collectors-list)
46
+- [Monitor anything with Netdata](#monitor-anything-with-netdata)
47
- [Add your application to Netdata](#add-your-application-to-netdata)
48
- [Available Collectors](#available-collectors)
49
- [Service and application collectors](#service-and-application-collectors)
@@ -657,7 +648,7 @@ $ sudo echo "clickhouse: yes" >> /etc/netdata/python.d.conf
648
$ sudo vi /etc/netdata/python.d/clickhouse.conf
649
650
# restart netdata
660
-# see docs for more information: https://learn.netdata.cloud/docs/configure/start-stop-restart
651
+# see docs for more information: https://github.com/netdata/netdata/blob/master/docs/configure/start-stop-restart.md
652
$ sudo systemctl restart netdata
653
```
654
collectors/python.d.plugin/alarms/README.md
+1
-1
@@ -8,7 +8,7 @@ learn_rel_path: "Integrations/Monitor/Netdata"
8
9
# Alarms
10
11
-This collector creates an 'Alarms' menu with one line plot showing alarm states over time. Alarm states are mapped to integer values according to the below default mapping. Any alarm status types not in this mapping will be ignored (Note: This mapping can be changed by editing the `status_map` in the `alarms.conf` file). If you would like to learn more about the different alarm statuses check out the docs [here](https://learn.netdata.cloud/docs/agent/health/reference#alarm-statuses).
11
+This collector creates an 'Alarms' menu with one line plot showing alarm states over time. Alarm states are mapped to integer values according to the below default mapping. Any alarm status types not in this mapping will be ignored (Note: This mapping can be changed by editing the `status_map` in the `alarms.conf` file). If you would like to learn more about the different alarm statuses check out the docs [here](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md#alarm-statuses).
12
13
```
14
{
collectors/python.d.plugin/zscores/README.md
+1
-1
@@ -87,7 +87,7 @@ the `zscores.conf` files alone to begin with. Then you can return to it later if
87
more once the collector is running for a while.
88
89
Edit the `python.d/zscores.conf` configuration file using `edit-config` from the your
90
-agent's [config directory](https://learn.netdata.cloud/guides/step-by-step/step-04#find-your-netdataconf-file), which is
90
+agent's [config directory](https://github.com/netdata/netdata/blob/master/docs/configure/nodes.md#the-netdata-config-directory), which is
91
usually at `/etc/netdata`.
92
93
```bash
collectors/statsd.plugin/README.md
+1
-1
@@ -983,7 +983,7 @@ At this point, you have used StatsD to gather metrics for k6, creating a whole n
983
Netdata dashboard in the process. Moreover, you can further customize the icon of the particular section,
984
as well as the description for each chart.
985
986
-To edit the section, please follow the Netdata [documentation](https://learn.netdata.cloud/docs/agent/web/gui#customizing-the-local-dashboard).
986
+To edit the section, please follow the Netdata [documentation](https://github.com/netdata/netdata/blob/master/web/gui/README.md#customizing-the-local-dashboard).
987
988
While the following configuration will be placed in a new file, as the documentation suggests, it is
989
instructing to use `dashboard_info.js` as a template. Open the file and see how the rest of sections and collectors have been defined.
docs/cloud/cheatsheet.md
+2
-2
@@ -25,7 +25,7 @@ To do so, sign in to Netdata Cloud, click the `Claim Nodes` button, choose the `
25
## Metrics collection & retention
26
27
You can tweak your settings in the netdata.conf file.
28
-📄 [Find your netdata.conf file](https://learn.netdata.cloud/guides/step-by-step/step-04#find-your-netdataconf-file)
28
+📄 [Find your netdata.conf file](https://github.com/netdata/netdata/blob/master/daemon/config/README.md)
29
30
Open a new terminal and navigate to the netdata.conf file. Use the edit-config script to make changes: `sudo ./edit-config netdata.conf`
31
@@ -93,7 +93,7 @@ $ sudo ./edit-config python.d/anomalies.conf
93
#### The Netdata config directory: `/etc/netdata`
94
95
> If you don't have such a directory:
96
-> 📄 [Find your netdata.conf file](https://learn.netdata.cloud/guides/step-by-step/step-04#find-your-netdataconf-file)
96
+> 📄 [Find your netdata.conf file](https://github.com/netdata/netdata/blob/master/daemon/config/README.md)
97
> The cheatsheet assumes you’re running all commands from within the Netdata config directory!
98
99
#### Edit Netdata's main config file: `$ sudo ./edit-config netdata.conf`
docs/cloud/insights/anomaly-advisor.md
+5
-4
@@ -21,7 +21,7 @@ interest.
21
22
If you are running a Netdata version higher than `v1.35.0-29-nightly` you will be able to use the Anomaly Advisor out of the box with zero configuration. If you are on an earlier Netdata version you will need to first enable ML on your nodes by following the steps below.
23
24
-To enable the Anomaly Advisor you must first enable ML on your nodes via a small config change in `netdata.conf`. Once the anomaly detection models have trained on the Agent (with default settings this takes a couple of hours until enough data has been seen to train the models) you will then be able to enable the Anomaly Advisor feature in Netdata Cloud.
24
+To enable the Anomaly Advisor you must first enable ML on your nodes via a small config change in `netdata.conf`. Once the anomaly detection models have trained on the Agent (with default settings this takes a couple of hours until enough data has been seen to train the models) you will then be able to enable the Anomaly Advisor feature in Netdata Cloud.
25
26
### Enable ML on Netdata Agent
27
@@ -32,7 +32,7 @@ To enable ML on your Netdata Agent, you need to edit the `[ml]` section in your
32
enabled = yes
33
```
34
35
-At a minimum you just need to set `enabled = yes` to enable ML with default params. More details about configuration can be found in the [Netdata Agent ML docs](https://learn.netdata.cloud/docs/agent/ml#configuration).
35
+At a minimum you just need to set `enabled = yes` to enable ML with default params. More details about configuration can be found in the [Netdata Agent ML docs](https://github.com/netdata/netdata/blob/master/ml/README.md#configuration).
36
37
When you have finished your configuration, restart Netdata with a command like `sudo systemctl restart netdata` for the config changes to take effect. You can find more info on restarting Netdata [here](https://github.com/netdata/netdata/blob/master/docs/configure/start-stop-restart.md).
38
@@ -44,7 +44,7 @@ Once this line flattens out all configured metrics should have models trained an
44
45
## Using Anomaly Advisor
46
47
-To use the Anomaly Advisor, go to the "anomalies" tab. Once you highlight a particular timeframe of interest, a selection of the most anomalous dimensions will appear below.
47
+To use the Anomaly Advisor, go to the "anomalies" tab. Once you highlight a particular timeframe of interest, a selection of the most anomalous dimensions will appear below.
48
49
The aim here is to surface the most anomalous metrics in the space or room for the highlighted window to try and cut down on the amount of manual searching required to get to the root cause of your issues.
50
@@ -68,7 +68,7 @@ You can expand any sparkline chart to see the underlying raw data to see how it
68
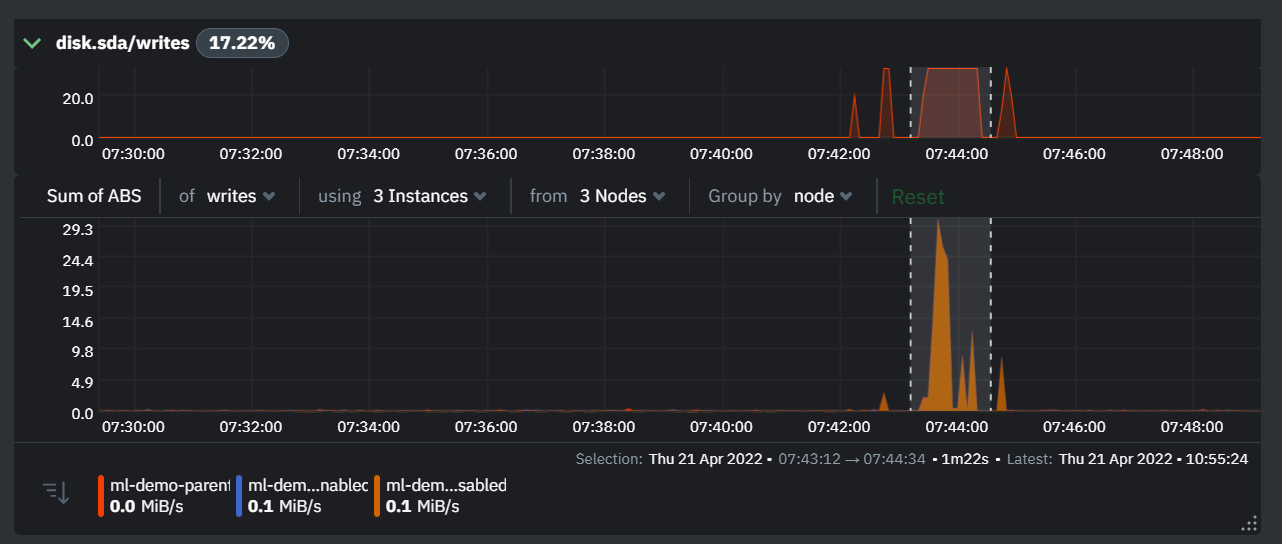
69
70
71
-On the upper right hand side of the page you can select which nodes to filter on if you wish to do so. The ML training status of each node is also displayed.
71
+On the upper right hand side of the page you can select which nodes to filter on if you wish to do so. The ML training status of each node is also displayed.
72
73
On the lower right hand side of the page an index of anomaly rates is displayed for the highlighted timeline of interest. The index is sorted from most anomalous metric (highest anomaly rate) to least (lowest anomaly rate). Clicking on an entry in the index will scroll the rest of the page to the corresponding anomaly rate sparkline for that metric.
74
@@ -80,6 +80,7 @@ On the lower right hand side of the page an index of anomaly rates is displayed
80
You can read more detail on how anomaly detection in the Netdata Agent works in our [Agent docs](https://github.com/netdata/netdata/blob/master/ml/README.md).
81
82
🚧 **Note**: This functionality is still **under active development** and considered experimental. We dogfood it internally and among early adopters within the Netdata community to build the feature. If you would like to get involved and help us with feedback, you can reach us through any of the following channels:
83
+
84
- Email us at analytics-ml-team@netdata.cloud
85
- Comment on the [beta launch post](https://community.netdata.cloud/t/anomaly-advisor-beta-launch/2717) in the Netdata community
86
- Join us in the [🤖-ml-powered-monitoring](https://discord.gg/4eRSEUpJnc) channel of the Netdata discord.
docs/cloud/insights/metric-correlations.md
+1
-1
@@ -74,7 +74,7 @@ Should you still want to, disabling nodes for Metric Correlation on the agent is
74
75
## Usage tips!
76
77
-- When running Metric Correlations from the [Overview tab](https://learn.netdata.cloud/docs/cloud/visualize/overview#overview) across multiple nodes, you might find better results if you iterate on the initial results by grouping by node to then filter to nodes of interest and run the Metric Correlations again. So a typical workflow in this case would be to:
77
+- When running Metric Correlations from the [Overview tab](https://github.com/netdata/netdata/blob/master/docs/cloud/visualize/overview.md#overview-and-single-node-view) across multiple nodes, you might find better results if you iterate on the initial results by grouping by node to then filter to nodes of interest and run the Metric Correlations again. So a typical workflow in this case would be to:
78
- If unsure which nodes you are interested in then run MC on all nodes.
79
- Within the initial results returned group the most interesting chart by node to see if the changes are across all nodes or a subset of nodes.
80
- If you see a subset of nodes clearly jump out when you group by node, then filter for just those nodes of interest and run the MC again. This will result in less aggregation needing to be done by Netdata and so should help give clearer results as you interact with the slider.
docs/cloud/manage/view-plan-billing.md
+1
-1
@@ -55,7 +55,7 @@ After an initial failed payment, we will attempt to process your payment every w
55
56
For the next 24 hours, you will be able to use all your current notification method configurations. After 24 hours, any of the notification method configurations that aren't available on your space's plan will be automatically disabled.
57
58
-Cancellation might affect users in your Space. Please check what roles are available on the [Community plan](https://learn.netdata.cloud/docs/nightly/concepts/netdata-plans#areas-impacted-by-plans). Users with unavailable roles on the Community plan will immediately have restricted access to the Space.
58
+Cancellation might affect users in your Space. Please check what roles are available on the [Community plan](https://github.com/netdata/netdata/blob/master/docs/cloud/manage/plans.md#areas-impacted-by-plans). Users with unavailable roles on the Community plan will immediately have restricted access to the Space.
59
60
#### 3. Which currencies do you support?
61
docs/cloud/visualize/dashboards.md
+1
-2
@@ -50,8 +50,7 @@ node. If you select **All Nodes**, you will add a [composite chart](/docs/cloud/
50
your new dashboard. Next, select the context. You'll see a preview of the chart before you finish adding it.
51
52
The charts you add to any dashboard are fully interactive, just like the charts in an Agent dashboard or a single node's
53
-dashboard in Cloud. Zoom in and out, highlight timeframes, and more. See our
54
-[Agent dashboard docs](https://learn.netdata.cloud/docs/agent/web#using-charts) for all the shortcuts.
53
+dashboard in Cloud. Zoom in and out, highlight timeframes, and more.
54
55
Charts also synchronize as you interact with them, even across contexts _or_ nodes.
56
docs/guides/monitor/anomaly-detection.md
+4
-4
@@ -53,13 +53,13 @@ Pressing the anomalies icon (next to the information icon in the chart header) w
53
54
## Anomaly Rate Based Alerts
55
56
-It is possible to use the `anomaly-bit` when defining traditional Alerts within netdata. The `anomaly-bit` is just another `options` parameter that can be passed as part of an [alarm line lookup](https://learn.netdata.cloud/docs/agent/health/reference#alarm-line-lookup).
56
+It is possible to use the `anomaly-bit` when defining traditional Alerts within netdata. The `anomaly-bit` is just another `options` parameter that can be passed as part of an [alarm line lookup](https://github.com/netdata/netdata/blob/master/docs/configure/start-stop-restart.md#alarm-line-lookup).
57
58
You can see some example ML based alert configurations below:
59
60
-- [Anomaly rate based CPU dimensions alarm](https://learn.netdata.cloud/docs/agent/health/reference#example-8---anomaly-rate-based-cpu-dimensions-alarm)
61
-- [Anomaly rate based CPU chart alarm](https://learn.netdata.cloud/docs/agent/health/reference#example-9---anomaly-rate-based-cpu-chart-alarm)
62
-- [Anomaly rate based node level alarm](https://learn.netdata.cloud/docs/agent/health/reference#example-10---anomaly-rate-based-node-level-alarm)
60
+- [Anomaly rate based CPU dimensions alarm](https://github.com/netdata/netdata/blob/master/docs/configure/start-stop-restart.md#example-8---anomaly-rate-based-cpu-dimensions-alarm)
61
+- [Anomaly rate based CPU chart alarm](https://github.com/netdata/netdata/blob/master/docs/configure/start-stop-restart.md#example-9---anomaly-rate-based-cpu-chart-alarm)
62
+- [Anomaly rate based node level alarm](https://github.com/netdata/netdata/blob/master/docs/configure/start-stop-restart.md#example-10---anomaly-rate-based-node-level-alarm)
63
- More examples in the [`/health/health.d/ml.conf`](https://github.com/netdata/netdata/blob/master/health/health.d/ml.conf) file that ships with the agent.
64
65
## Learn More
docs/guides/monitor/kubernetes-k8s-netdata.md
+1
-1
@@ -140,7 +140,7 @@ visualizations](https://user-images.githubusercontent.com/1153921/109049195-349f
140
141
### Health map
142
143
-The first visualization is the [health map](https://learn.netdata.cloud/docs/cloud/visualize/kubernetes#health-map),
143
+The first visualization is the [health map](https://github.com/netdata/netdata/blob/master/docs/cloud/visualize/kubernetes.md#health-map),
144
which places each container into its own box, then varies the intensity of their color to visualize the resource
145
utilization. By default, the health map shows the **average CPU utilization as a percentage of the configured limit**
146
for every container in your cluster.
docs/guides/monitor/pi-hole-raspberry-pi.md
+1
-24
@@ -65,9 +65,7 @@ populates its dashboard with more than 250 charts.
65
Open your browser of choice and navigate to `http://NODE:19999/`, replacing `NODE` with the IP address of your Raspberry
66
Pi. Not sure what that IP is? Try running `hostname -I | awk '{print $1}'` from the Pi itself.
67
68
-You'll see Netdata's dashboard and a few hundred real-time,
69
-[interactive](https://learn.netdata.cloud/guides/step-by-step/step-02#interact-with-charts) charts. Feel free to
70
-explore, but let's turn our attention to installing Pi-hole.
68
+You'll see Netdata's dashboard and a few hundred real-time, interactive charts. Feel free to explore, but let's turn our attention to installing Pi-hole.
69
70
## Install Pi-Hole
71
@@ -142,24 +140,3 @@ Use our [database sizing
140
calculator](https://github.com/netdata/netdata/blob/master/docs/store/change-metrics-storage.md#calculate-the-system-resources-ram-disk-space-needed-to-store-metrics)
141
and the [Database configuration documentation](https://github.com/netdata/netdata/blob/master/database/README.md) to help you determine the right
142
setting for your Raspberry Pi.
145
-
146
-## What's next?
147
-
148
-Now that you're monitoring Pi-hole and your Raspberry Pi with Netdata, you can extend its capabilities even further, or
149
-configure Netdata to more specific goals.
150
-
151
-Most importantly, you can always install additional services and instantly collect metrics from many of them with our
152
-[300+ integrations](https://github.com/netdata/netdata/blob/master/collectors/COLLECTORS.md).
153
-
154
-- [Optimize performance](https://github.com/netdata/netdata/blob/master/docs/guides/configure/performance.md) using tweaks developed for IoT devices.
155
-- [Stream Raspberry Pi metrics](https://github.com/netdata/netdata/blob/master/streaming/README.md) to a parent host for easy access or longer-term storage.
156
-- [Tweak alarms](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md) for either Pi-hole or the health of your Raspberry Pi.
157
-- [Export metrics to external databases](https://github.com/netdata/netdata/blob/master/exporting/README.md) with the exporting engine.
158
-
159
-Or, head over to [our guides](https://learn.netdata.cloud/guides/) for even more experiments and insights into
160
-troubleshooting the health of your systems and services.
161
-
162
-If you have any questions about using Netdata to monitor your Raspberry Pi, Pi-hole, or any other applications, head on
163
-over to our [community forum](https://community.netdata.cloud/).
164
-
165
-
docs/guides/troubleshoot/troubleshooting-agent-with-cloud-connection.md
+1
-1
@@ -65,7 +65,7 @@ Read more about [Starting, Stopping and Restarting the Agent](https://github.com
65
66
## Claiming on an older, deprecated version of the Agent
67
68
-Make sure that you are using the latest version of Netdata if you are using the [Claiming script](https://learn.netdata.cloud/docs/agent/claim#claiming-script).
68
+Make sure that you are using the latest version of Netdata if you are using the [Claiming script](https://github.com/netdata/netdata/blob/master/claim/README.md#claiming-script).
69
70
With the introduction of our new architecture, Agents running versions lower than `v1.32.0` can face claiming problems, so we recommend you [update the Netdata Agent](https://github.com/netdata/netdata/blob/master/packaging/installer/UPDATE.md) to the latest stable version.
71
docs/store/distributed-data-architecture.md
+1
-1
@@ -67,7 +67,7 @@ When you use the database engine to store your metrics, you can always perform a
67
Netdata Cloud does not store metric values.
68
69
To enable certain features, such as [viewing active alarms](https://github.com/netdata/netdata/blob/master/docs/monitor/view-active-alarms.md)
70
-or [filtering by hostname/service](https://learn.netdata.cloud/docs/cloud/war-rooms#node-filter), Netdata Cloud does
70
+or [filtering by hostname/service](https://github.com/netdata/netdata/blob/master/docs/cloud/war-rooms.md), Netdata Cloud does
71
store configured alarms, their status, and a list of active collectors.
72
73
Netdata does not and never will sell your personal data or data about your deployment.
health/REFERENCE.md
+121
-120
@@ -17,12 +17,12 @@ files.
17
18
You can configure the Agent's health watchdog service by editing files in two locations:
19
20
-- The `[health]` section in `netdata.conf`. By editing the daemon's behavior, you can disable health monitoring
21
- altogether, run health checks more or less often, and more. See
22
- [daemon configuration](https://github.com/netdata/netdata/blob/master/daemon/config/README.md#health-section-options) for a table of
20
+- The `[health]` section in `netdata.conf`. By editing the daemon's behavior, you can disable health monitoring
21
+ altogether, run health checks more or less often, and more. See
22
+ [daemon configuration](https://github.com/netdata/netdata/blob/master/daemon/config/README.md#health-section-options) for a table of
23
all the available settings, their default values, and what they control.
24
25
-- The individual `.conf` files in `health.d/`. These health entity files are organized by the type of metric they are
25
+- The individual `.conf` files in `health.d/`. These health entity files are organized by the type of metric they are
26
performing calculations on or their associated collector. You should edit these files using the `edit-config`
27
script. For example: `sudo ./edit-config health.d/cpu.conf`.
28
@@ -68,7 +68,7 @@ Save the file and [reload Netdata's health configuration](#reload-health-configu
68
## Disable or silence alerts
69
70
Alerts and notifications can be disabled permanently via configuration changes, or temporarily, via the
71
-[health management API](https://github.com/netdata/netdata/blob/master/web/api/health/README.md). The
71
+[health management API](https://github.com/netdata/netdata/blob/master/web/api/health/README.md). The
72
available options are described below.
73
74
### Disable all alerts
@@ -77,11 +77,11 @@ In the `netdata.conf` `[health]` section, set `enabled` to `no`, and restart the
77
78
### Disable some alerts
79
80
-In the `netdata.conf` `[health]` section, set `enabled alerms` to a
80
+In the `netdata.conf` `[health]` section, set `enabled alerms` to a
81
[simple pattern](https://github.com/netdata/netdata/edit/master/libnetdata/simple_pattern/README.md) that
82
-excludes one or more alerts. e.g. `enabled alarms = !oom_kill *` will load all alarms except `oom_kill`.
82
+excludes one or more alerts. e.g. `enabled alarms = !oom_kill *` will load all alarms except `oom_kill`.
83
84
-You can also [edit the file where the alert is defined](#edit-individual-alerts), comment out its definition,
84
+You can also [edit the file where the alert is defined](#edit-individual-alerts), comment out its definition,
85
and [reload Netdata's health configuration](#reload-health-configuration).
86
87
### Silence an individual alert
@@ -96,16 +96,16 @@ This action requires that you [reload Netdata's health configuration](#reload-he
96
97
### Temporarily disable alerts at runtime
98
99
-When you need to frequently disable all or some alerts from triggering during certain times (for instance
100
-when running backups) you can use the
99
+When you need to frequently disable all or some alerts from triggering during certain times (for instance
100
+when running backups) you can use the
101
[health management API](https://github.com/netdata/netdata/blob/master/web/api/health/README.md).
102
The API allows you to issue commands to control the health engine's behavior without changing configuration,
103
or restarting the agent.
104
105
### Temporarily silence notifications at runtime
106
107
-If you want health checks to keep running and alerts to keep getting triggered, but notifications to be
108
-suppressed temporarily, you can use the
107
+If you want health checks to keep running and alerts to keep getting triggered, but notifications to be
108
+suppressed temporarily, you can use the
109
[health management API](https://github.com/netdata/netdata/blob/master/web/api/health/README.md).
110
The API allows you to issue commands to control the health engine's behavior without changing configuration,
111
or restarting the agent.
@@ -144,36 +144,36 @@ lookup: average -1m percentage of used
144
145
Let's look into each of the lines to see how they create a working health entity.
146
147
-- `alarm`: The name for your new entity. The name needs to follow these requirements:
148
- - Any alphabet letter or number.
149
- - The symbols `.` and `_`.
150
- - Cannot be `chart name`, `dimension name`, `family name`, or `chart variable names`.
147
+- `alarm`: The name for your new entity. The name needs to follow these requirements:
148
+ - Any alphabet letter or number.
149
+ - The symbols `.` and `_`.
150
+ - Cannot be `chart name`, `dimension name`, `family name`, or `chart variable names`.
151
152
-- `on`: Which chart the entity listens to.
152
+- `on`: Which chart the entity listens to.
153
154
-- `lookup`: Which metrics the alarm monitors, the duration of time to monitor, and how to process the metrics into a
154
+- `lookup`: Which metrics the alarm monitors, the duration of time to monitor, and how to process the metrics into a
155
usable format.
156
- - `average`: Calculate the average of all the metrics collected.
157
- - `-1m`: Use metrics from 1 minute ago until now to calculate that average.
158
- - `percentage`: Clarify that we're calculating a percentage of RAM usage.
159
- - `of used`: Specify which dimension (`used`) on the `system.ram` chart you want to monitor with this entity.
156
+ - `average`: Calculate the average of all the metrics collected.
157
+ - `-1m`: Use metrics from 1 minute ago until now to calculate that average.
158
+ - `percentage`: Clarify that we're calculating a percentage of RAM usage.
159
+ - `of used`: Specify which dimension (`used`) on the `system.ram` chart you want to monitor with this entity.
160
161
-- `units`: Use percentages rather than absolute units.
161
+- `units`: Use percentages rather than absolute units.
162
163
-- `every`: How often to perform the `lookup` calculation to decide whether or not to trigger this alarm.
163
+- `every`: How often to perform the `lookup` calculation to decide whether or not to trigger this alarm.
164
165
-- `warn`/`crit`: The value at which Netdata should trigger a warning or critical alarm. This example uses simple
165
+- `warn`/`crit`: The value at which Netdata should trigger a warning or critical alarm. This example uses simple
166
syntax, but most pre-configured health entities use
167
[hysteresis](#special-use-of-the-conditional-operator) to avoid superfluous notifications.
168
169
-- `info`: A description of the alarm, which will appear in the dashboard and notifications.
169
+- `info`: A description of the alarm, which will appear in the dashboard and notifications.
170
171
-In human-readable format:
171
+In human-readable format:
172
173
> This health entity, named **ram_usage**, watches the **system.ram** chart. It looks up the last **1 minute** of
174
> metrics from the **used** dimension and calculates the **average** of all those metrics in a **percentage** format,
175
-> using a **% unit**. The entity performs this lookup **every minute**.
176
->
175
+> using a **% unit**. The entity performs this lookup **every minute**.
176
+>
177
> If the average RAM usage percentage over the last 1 minute is **more than 80%**, the entity triggers a warning alarm.
178
> If the usage is **more than 90%**, the entity triggers a critical alarm.
179
@@ -207,14 +207,14 @@ to the same chart, Netdata will use the alarm.
207
208
Netdata parses the following lines. Beneath the table is an in-depth explanation of each line's purpose and syntax.
209
210
-- The `alarm` or `template` line must be the first line of any entity.
211
-- The `on` line is **always required**.
212
-- The `every` line is **required** if not using `lookup`.
213
-- Each entity **must** have at least one of the following lines: `lookup`, `calc`, `warn`, or `crit`.
214
-- A few lines use space-separated lists to define how the entity behaves. You can use `*` as a wildcard or prefix with
210
+- The `alarm` or `template` line must be the first line of any entity.
211
+- The `on` line is **always required**.
212
+- The `every` line is **required** if not using `lookup`.
213
+- Each entity **must** have at least one of the following lines: `lookup`, `calc`, `warn`, or `crit`.
214
+- A few lines use space-separated lists to define how the entity behaves. You can use `*` as a wildcard or prefix with
215
`!` for a negative match. Order is important, too! See our [simple patterns docs](https://github.com/netdata/netdata/blob/master/libnetdata/simple_pattern/README.md) for
216
more examples.
217
-- Lines terminated by a `\` are spliced together with the next line. The backslash is removed and the following line is
217
+- Lines terminated by a `\` are spliced together with the next line. The backslash is removed and the following line is
218
joined with the current one. No space is inserted, so you may split a line anywhere, even in the middle of a word.
219
This comes in handy if your `info` line consists of several sentences.
220
@@ -262,7 +262,7 @@ alarm: NAME
262
template: NAME
263
```
264
265
-`NAME` can be any alpha character, with `.` (period) and `_` (underscore) as the only allowed symbols, but the names
265
+`NAME` can be any alpha character, with `.` (period) and `_` (underscore) as the only allowed symbols, but the names
266
cannot be `chart name`, `dimension name`, `family name`, or `chart variables names`.
267
268
#### Alarm line `on`
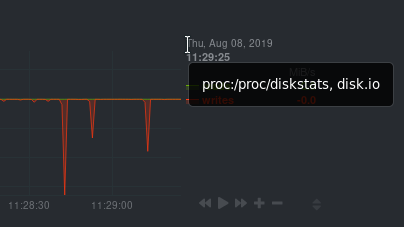
@@ -294,7 +294,7 @@ shows a disk I/O chart, the tooltip reads: `proc:/proc/diskstats, disk.io`.
294
295
296
297
-You're interested in what comes after the comma: `disk.io`. That's the name of the chart's context.
297
+You're interested in what comes after the comma: `disk.io`. That's the name of the chart's context.
298
299
If you create a template using the `disk.io` context, it will apply an alarm to every disk available on your system.
300
@@ -316,7 +316,6 @@ class: Latency
316
| Utilization |
317
| Workload |
318
319
-
319
</details>
320
321
`class` will default to `Unknown` if the line is missing from the alarm configuration.
@@ -328,6 +327,7 @@ Type can be used to indicate the broader area of the system that the alarm appli
327
```yaml
328
type: Database
329
```
330
+
331
<details>
332
<summary>Netdata's stock alarms use the following `type` attributes by default, but feel free to adjust for your own requirements.</summary>
333
@@ -368,6 +368,7 @@ Component can be used to narrow down what the previous `type` value specifies fo
368
```yaml
369
component: MySQL
370
```
371
+
372
As with the `class` and `type` line, if `component` is missing from the configuration, its value will default to `Unknown`.
373
374
#### Alarm line `os`
@@ -420,7 +421,7 @@ module: isc_dhcpd
421
422
#### Alarm line `charts`
423
423
-The `charts` line filters which chart this alarm should apply to. It is only available on entities using the
424
+The `charts` line filters which chart this alarm should apply to. It is only available on entities using the
425
[`template`](#alarm-line-alarm-or-template) line.
426
The value is a space-separated list of [simple patterns](https://github.com/netdata/netdata/blob/master/libnetdata/simple_pattern/README.md). For
427
example, a template that applies to `disk.svctm` (Average Service Time) context, but excludes the disk `sdb` from alarms:
@@ -457,33 +458,33 @@ lookup: METHOD AFTER [at BEFORE] [every DURATION] [OPTIONS] [of DIMENSIONS] [for
458
459
Everything is the same with [badges](https://github.com/netdata/netdata/blob/master/web/api/badges/README.md). In short:
460
460
-- `METHOD` is one of `average`, `min`, `max`, `sum`, `incremental-sum`.
461
+- `METHOD` is one of `average`, `min`, `max`, `sum`, `incremental-sum`.
462
This is required.
463
463
-- `AFTER` is a relative number of seconds, but it also accepts a single letter for changing
464
+- `AFTER` is a relative number of seconds, but it also accepts a single letter for changing
465
the units, like `-1s` = 1 second in the past, `-1m` = 1 minute in the past, `-1h` = 1 hour
466
in the past, `-1d` = 1 day in the past. You need a negative number (i.e. how far in the past
467
to look for the value). **This is required**.
468
468
-- `at BEFORE` is by default 0 and is not required. Using this you can define the end of the
469
+- `at BEFORE` is by default 0 and is not required. Using this you can define the end of the
470
lookup. So data will be evaluated between `AFTER` and `BEFORE`.
471
471
-- `every DURATION` sets the updated frequency of the lookup (supports single letter units as
472
+- `every DURATION` sets the updated frequency of the lookup (supports single letter units as
473
above too).
474
474
-- `OPTIONS` is a space separated list of `percentage`, `absolute`, `min2max`, `unaligned`,
475
+- `OPTIONS` is a space separated list of `percentage`, `absolute`, `min2max`, `unaligned`,
476
`match-ids`, `match-names`. Check the [badges](https://github.com/netdata/netdata/blob/master/web/api/badges/README.md) documentation for more info.
477
477
-- `of DIMENSIONS` is optional and has to be the last parameter. Dimensions have to be separated
478
+- `of DIMENSIONS` is optional and has to be the last parameter. Dimensions have to be separated
479
by `,` or `|`. The space characters found in dimensions will be kept as-is (a few dimensions
480
have spaces in their names). This accepts Netdata simple patterns _(with `words` separated by
481
`,` or `|` instead of spaces)_ and the `match-ids` and `match-names` options affect the searches
482
for dimensions.
483
483
-- `foreach DIMENSIONS` is optional, will always be the last parameter, and uses the same `,`/`|`
484
+- `foreach DIMENSIONS` is optional, will always be the last parameter, and uses the same `,`/`|`
485
rules as the `of` parameter. Each dimension you specify in `foreach` will use the same rule
486
to trigger an alarm. If you set both `of` and `foreach`, Netdata will ignore the `of` parameter
486
- and replace it with one of the dimensions you gave to `foreach`. This option allows you to
487
+ and replace it with one of the dimensions you gave to `foreach`. This option allows you to
488
[use dimension templates to create dynamic alarms](#use-dimension-templates-to-create-dynamic-alarms).
489
490
The result of the lookup will be available as `$this` and `$NAME` in expressions.
@@ -584,21 +585,21 @@ Format:
585
delay: [[[up U] [down D] multiplier M] max X]
586
```
587
587
-- `up U` defines the delay to be applied to a notification for an alarm that raised its status
588
+- `up U` defines the delay to be applied to a notification for an alarm that raised its status
589
(i.e. CLEAR to WARNING, CLEAR to CRITICAL, WARNING to CRITICAL). For example, `up 10s`, the
590
notification for this event will be sent 10 seconds after the actual event. This is used in
591
hope the alarm will get back to its previous state within the duration given. The default `U`
592
is zero.
593
593
-- `down D` defines the delay to be applied to a notification for an alarm that moves to lower
594
+- `down D` defines the delay to be applied to a notification for an alarm that moves to lower
595
state (i.e. CRITICAL to WARNING, CRITICAL to CLEAR, WARNING to CLEAR). For example, `down 1m`
596
will delay the notification by 1 minute. This is used to prevent notifications for flapping
597
alarms. The default `D` is zero.
598
598
-- `multiplier M` multiplies `U` and `D` when an alarm changes state, while a notification is
599
+- `multiplier M` multiplies `U` and `D` when an alarm changes state, while a notification is
600
delayed. The default multiplier is `1.0`.
601
601
-- `max X` defines the maximum absolute notification delay an alarm may get. The default `X`
602
+- `max X` defines the maximum absolute notification delay an alarm may get. The default `X`
603
is `max(U * M, D * M)` (i.e. the max duration of `U` or `D` multiplied once with `M`).
604
605
Example:
@@ -616,9 +617,9 @@ delay: [[[up U] [down D] multiplier M] max X]
617
618
So:
619
619
- - `U` and `D` are multiplied by `M` every time the alarm changes state (any state, not just
620
+ - `U` and `D` are multiplied by `M` every time the alarm changes state (any state, not just
621
their matching one) and a delay is in place.
621
- - All are reset to their defaults when the alarm switches state without a delay in place.
622
+ - All are reset to their defaults when the alarm switches state without a delay in place.
623
624
#### Alarm line `repeat`
625
@@ -634,11 +635,11 @@ Format:
635
repeat: [off] [warning DURATION] [critical DURATION]
636
```
637
637
-- `off`: Turns off the repeating feature for the current alarm. This is effective when the default repeat settings has
638
+- `off`: Turns off the repeating feature for the current alarm. This is effective when the default repeat settings has
639
been enabled in health configuration.
639
-- `warning DURATION`: Defines the interval when the alarm is in WARNING state. Use `0s` to turn off the repeating
640
+- `warning DURATION`: Defines the interval when the alarm is in WARNING state. Use `0s` to turn off the repeating
641
notification for WARNING mode.
641
-- `critical DURATION`: Defines the interval when the alarm is in CRITICAL state. Use `0s` to turn off the repeating
642
+- `critical DURATION`: Defines the interval when the alarm is in CRITICAL state. Use `0s` to turn off the repeating
643
notification for CRITICAL mode.
644
645
#### Alarm line `options`
@@ -686,7 +687,7 @@ line to any alarms you'd like to apply to hosts that have the label `room = serv
687
host labels: room = server
688
```
689
689
-The `host labels` is a space-separated list that accepts simple patterns. For example, you can create an alarm
690
+The `host labels` is a space-separated list that accepts simple patterns. For example, you can create an alarm
691
that will be applied to all hosts installed in the last decade with the following line:
692
693
```yaml
@@ -762,10 +763,10 @@ Expressions can have variables. Variables start with `$`. Check below for more i
763
764
There are two special values you can use:
765
765
-- `nan`, for example `$this != nan` will check if the variable `this` is available. A variable can be `nan` if the
766
+- `nan`, for example `$this != nan` will check if the variable `this` is available. A variable can be `nan` if the
767
database lookup failed. All calculations (i.e. addition, multiplication, etc) with a `nan` result in a `nan`.
768
768
-- `inf`, for example `$this != inf` will check if `this` is not infinite. A value or variable can be set to infinite
769
+- `inf`, for example `$this != inf` will check if `this` is not infinite. A value or variable can be set to infinite
770
if divided by zero. All calculations (i.e. addition, multiplication, etc) with a `inf` result in a `inf`.
771
772
### Special use of the conditional operator
@@ -784,21 +785,21 @@ crit: $this > (($status == $CRITICAL) ? (85) : (95))
785
786
The above say:
787
787
-- If the alarm is currently a warning, then the threshold for being considered a warning is 75, otherwise it's 85.
788
+- If the alarm is currently a warning, then the threshold for being considered a warning is 75, otherwise it's 85.
789
789
-- If the alarm is currently critical, then the threshold for being considered critical is 85, otherwise it's 95.
790
+- If the alarm is currently critical, then the threshold for being considered critical is 85, otherwise it's 95.
791
792
Which in turn, results in the following behavior:
793
793
-- While the value is rising, it will trigger a warning when it exceeds 85, and a critical alert when it exceeds 95.
794
+- While the value is rising, it will trigger a warning when it exceeds 85, and a critical alert when it exceeds 95.
795
795
-- While the value is falling, it will return to a warning state when it goes below 85, and a normal state when it goes
796
+- While the value is falling, it will return to a warning state when it goes below 85, and a normal state when it goes
797
below 75.
798
798
-- If the value is constantly varying between 80 and 90, then it will trigger a warning the first time it goes above
799
+- If the value is constantly varying between 80 and 90, then it will trigger a warning the first time it goes above
800
85, but will remain a warning until it goes below 75 (or goes above 85).
801
801
-- If the value is constantly varying between 90 and 100, then it will trigger a critical alert the first time it goes
802
+- If the value is constantly varying between 90 and 100, then it will trigger a critical alert the first time it goes
803
above 95, but will remain a critical alert goes below 85 (at which point it will return to being a warning).
804
805
## Variables
@@ -822,15 +823,15 @@ unless if you explicitly limit an alarm with the [alarm line `families`](#alarm-
823
824
</details>
825
825
-- **chart local variables**. All the dimensions of the chart are exposed as local variables. The value of `$this` for
826
+- **chart local variables**. All the dimensions of the chart are exposed as local variables. The value of `$this` for
827
the other configured alarms of the chart also appears, under the name of each configured alarm.
828
829
Charts also define a few special variables:
830
830
- - `$last_collected_t` is the unix timestamp of the last data collection
831
- - `$collected_total_raw` is the sum of all the dimensions (their last collected values)
832
- - `$update_every` is the update frequency of the chart
833
- - `$green` and `$red` the threshold defined in alarms (these are per chart - the charts
831
+ - `$last_collected_t` is the unix timestamp of the last data collection
832
+ - `$collected_total_raw` is the sum of all the dimensions (their last collected values)
833
+ - `$update_every` is the update frequency of the chart
834
+ - `$green` and `$red` the threshold defined in alarms (these are per chart - the charts
835
inherits them from the the first alarm that defined them)
836
837
Chart dimensions define their last calculated (i.e. interpolated) value, exactly as
@@ -839,43 +840,43 @@ unless if you explicitly limit an alarm with the [alarm line `families`](#alarm-
840
that resolves to unix timestamp the dimension was last collected (there may be dimensions
841
that fail to be collected while others continue normally).
842
842
-- **family variables**. Families are used to group charts together. For example all `eth0`
843
+- **family variables**. Families are used to group charts together. For example all `eth0`
844
charts, have `family = eth0`. This index includes all local variables, but if there are
845
overlapping variables, only the first are exposed.
846
846
-- **host variables**. All the dimensions of all charts, including all alarms, in fullname.
847
+- **host variables**. All the dimensions of all charts, including all alarms, in fullname.
848
Fullname is `CHART.VARIABLE`, where `CHART` is either the chart id or the chart name (both
849
are supported).
850
850
-- **special variables\*** are:
851
+- **special variables\*** are:
852
852
- - `$this`, which is resolved to the value of the current alarm.
853
+ - `$this`, which is resolved to the value of the current alarm.
854
854
- - `$status`, which is resolved to the current status of the alarm (the current = the last
855
+ - `$status`, which is resolved to the current status of the alarm (the current = the last
856
status, i.e. before the current database lookup and the evaluation of the `calc` line).
857
This values can be compared with `$REMOVED`, `$UNINITIALIZED`, `$UNDEFINED`, `$CLEAR`,
858
`$WARNING`, `$CRITICAL`. These values are incremental, ie. `$status > $CLEAR` works as
859
expected.
860
860
- - `$now`, which is resolved to current unix timestamp.
861
+ - `$now`, which is resolved to current unix timestamp.
862
863
## Alarm statuses
864
865
Alarms can have the following statuses:
866
866
-- `REMOVED` - the alarm has been deleted (this happens when a SIGUSR2 is sent to Netdata
867
+- `REMOVED` - the alarm has been deleted (this happens when a SIGUSR2 is sent to Netdata
868
to reload health configuration)
869
869
-- `UNINITIALIZED` - the alarm is not initialized yet
870
+- `UNINITIALIZED` - the alarm is not initialized yet
871
871
-- `UNDEFINED` - the alarm failed to be calculated (i.e. the database lookup failed,
872
+- `UNDEFINED` - the alarm failed to be calculated (i.e. the database lookup failed,
873
a division by zero occurred, etc)
874
874
-- `CLEAR` - the alarm is not armed / raised (i.e. is OK)
875
+- `CLEAR` - the alarm is not armed / raised (i.e. is OK)
876
876
-- `WARNING` - the warning expression resulted in true or non-zero
877
+- `WARNING` - the warning expression resulted in true or non-zero
878
878
-- `CRITICAL` - the critical expression resulted in true or non-zero
879
+- `CRITICAL` - the critical expression resulted in true or non-zero
880
881
The external script will be called for all status changes.
882
@@ -919,9 +920,9 @@ The above applies the **template** to all charts that have `context = apache.req
920
calc: $now - $last_collected_t
921
```
922
922
-- `$now` is a standard variable that resolves to the current timestamp.
923
+- `$now` is a standard variable that resolves to the current timestamp.
924
924
-- `$last_collected_t` is the last data collection timestamp of the chart.
925
+- `$last_collected_t` is the last data collection timestamp of the chart.
926
So this calculation gives the number of seconds passed since the last data collection.
927
928
```yaml
@@ -937,7 +938,7 @@ The alarm will be evaluated every 10 seconds.
938
939
If these result in non-zero or true, they trigger the alarm.
940
940
-- `$this` refers to the value of this alarm (i.e. the result of the `calc` line.
941
+- `$this` refers to the value of this alarm (i.e. the result of the `calc` line.
942
We could also use `$apache_last_collected_secs`.
943
944
`$update_every` is the update frequency of the chart, in seconds.
@@ -1092,9 +1093,9 @@ lookup: mean -10s of user
1093
1094
Since [`z = (x - mean) / stddev`](https://en.wikipedia.org/wiki/Standard_score) we create two input alarms, one for `mean` and one for `stddev` and then use them both as inputs in our final `cpu_user_zscore` alarm.
1095
1095
-### Example 8 - [Anomaly rate](https://learn.netdata.cloud/docs/agent/ml#anomaly-rate) based CPU dimensions alarm
1096
+### Example 8 - [Anomaly rate](https://github.com/netdata/netdata/blob/master/ml/README.md#anomaly-rate) based CPU dimensions alarm
1097
1097
-Warning if 5 minute rolling [anomaly rate](https://learn.netdata.cloud/docs/agent/ml#anomaly-rate) for any CPU dimension is above 5%, critical if it goes above 20%:
1098
+Warning if 5 minute rolling [anomaly rate](https://github.com/netdata/netdata/blob/master/ml/README.md#anomaly-rate) for any CPU dimension is above 5%, critical if it goes above 20%:
1099
1100
```yaml
1101
template: ml_5min_cpu_dims
@@ -1113,9 +1114,9 @@ template: ml_5min_cpu_dims
1114
The `lookup` line will calculate the average anomaly rate of each `system.cpu` dimension over the last 5 minues. In this case
1115
Netdata will create alarms for all dimensions of the chart.
1116
1116
-### Example 9 - [Anomaly rate](https://learn.netdata.cloud/docs/agent/ml#anomaly-rate) based CPU chart alarm
1117
+### Example 9 - [Anomaly rate](https://github.com/netdata/netdata/blob/master/ml/README.md#anomaly-rate) based CPU chart alarm
1118
1118
-Warning if 5 minute rolling [anomaly rate](https://learn.netdata.cloud/docs/agent/ml#anomaly-rate) averaged across all CPU dimensions is above 5%, critical if it goes above 20%:
1119
+Warning if 5 minute rolling [anomaly rate](https://github.com/netdata/netdata/blob/master/ml/README.md#anomaly-rate) averaged across all CPU dimensions is above 5%, critical if it goes above 20%:
1120
1121
```yaml
1122
template: ml_5min_cpu_chart
@@ -1134,9 +1135,9 @@ template: ml_5min_cpu_chart
1135
The `lookup` line will calculate the average anomaly rate across all `system.cpu` dimensions over the last 5 minues. In this case
1136
Netdata will create one alarm for the chart.
1137
1137
-### Example 10 - [Anomaly rate](https://learn.netdata.cloud/docs/agent/ml#anomaly-rate) based node level alarm
1138
+### Example 10 - [Anomaly rate](https://github.com/netdata/netdata/blob/master/ml/README.md#anomaly-rate) based node level alarm
1139
1139
-Warning if 5 minute rolling [anomaly rate](https://learn.netdata.cloud/docs/agent/ml#anomaly-rate) averaged across all ML enabled dimensions is above 5%, critical if it goes above 20%:
1140
+Warning if 5 minute rolling [anomaly rate](https://github.com/netdata/netdata/blob/master/ml/README.md#anomaly-rate) averaged across all ML enabled dimensions is above 5%, critical if it goes above 20%:
1141
1142
```yaml
1143
template: ml_5min_node
@@ -1152,12 +1153,12 @@ template: ml_5min_node
1153
info: rolling 5min anomaly rate for all ML enabled dims
1154
```
1155
1155
-The `lookup` line will use the `anomaly_rate` dimension of the `anomaly_detection.anomaly_rate` ML chart to calculate the average [node level anomaly rate](https://learn.netdata.cloud/docs/agent/ml#node-anomaly-rate) over the last 5 minues.
1156
+The `lookup` line will use the `anomaly_rate` dimension of the `anomaly_detection.anomaly_rate` ML chart to calculate the average [node level anomaly rate](https://github.com/netdata/netdata/blob/master/ml/README.md#node-anomaly-rate) over the last 5 minues.
1157
1158
## Use dimension templates to create dynamic alarms
1159
1159
-In v1.18 of Netdata, we introduced **dimension templates** for alarms, which simplifies the process of
1160
-writing [alarm entities](#health-entity-reference) for
1160
+In v1.18 of Netdata, we introduced **dimension templates** for alarms, which simplifies the process of
1161
+writing [alarm entities](#health-entity-reference) for
1162
charts with many dimensions.
1163
1164
Dimension templates can condense many individual entities into one—no more copy-pasting one entity and changing the
@@ -1165,13 +1166,13 @@ Dimension templates can condense many individual entities into one—no more cop
1166
1167
### The fundamentals of `foreach`
1168
1168
-Our dimension templates update creates a new `foreach` parameter to the
1169
-existing [`lookup` line](#alarm-line-lookup). This
1169
+Our dimension templates update creates a new `foreach` parameter to the
1170
+existing [`lookup` line](#alarm-line-lookup). This
1171
is where the magic happens.
1172
1173
You use the `foreach` parameter to specify which dimensions you want to monitor with this single alarm. You can separate
1173
-them with a comma (`,`) or a pipe (`|`). You can also use
1174
-a [Netdata simple pattern](https://github.com/netdata/netdata/blob/master/libnetdata/simple_pattern/README.md) to create
1174
+them with a comma (`,`) or a pipe (`|`). You can also use
1175
+a [Netdata simple pattern](https://github.com/netdata/netdata/blob/master/libnetdata/simple_pattern/README.md) to create
1176
many alarms with a regex-like syntax.
1177
1178
The `foreach` parameter _has_ to be the last parameter in your `lookup` line, and if you have both `of` and `foreach` in
@@ -1240,7 +1241,7 @@ Let's look at some other examples of how `foreach` works so you can best apply i
1241
### Using a Netdata simple pattern in `foreach`
1242
1243
In the last example, we used `foreach system,user,nice` to create three distinct alarms using dimension templates. But
1243
-what if you want to quickly create alarms for _all_ the dimensions of a given chart?
1244
+what if you want to quickly create alarms for _all_ the dimensions of a given chart?
1245
1246
Use a [simple pattern](https://github.com/netdata/netdata/blob/master/libnetdata/simple_pattern/README.md)! One example of a simple pattern is a single wildcard
1247
(`*`).
@@ -1260,14 +1261,14 @@ lookup: average -10m percentage foreach *
1261
This entity will now create alarms for every dimension in the `apps.cpu` chart. Given that most `apps.cpu` charts have
1262
10 or more dimensions, using the wildcard ensures you catch every CPU-hogging process.
1263
1263
-To learn more about how to use simple patterns with dimension templates, see
1264
+To learn more about how to use simple patterns with dimension templates, see
1265
our [simple patterns documentation](https://github.com/netdata/netdata/blob/master/libnetdata/simple_pattern/README.md).
1266
1267
### Using `foreach` with alarm templates
1268
1268
-Dimension templates also work
1269
-with [alarm templates](#alarm-line-alarm-or-template).
1270
-Alarm templates help you create alarms for all the charts with a given context—for example, all the cores of your
1269
+Dimension templates also work
1270
+with [alarm templates](#alarm-line-alarm-or-template).
1271
+Alarm templates help you create alarms for all the charts with a given context—for example, all the cores of your
1272
system's CPU.
1273
1274
By combining the two, you can create dozens of individual alarms with a single template entity. Here's how you would
@@ -1286,27 +1287,27 @@ template: cpu_template
1287
On a system with a 6-core, 12-thread Ryzen 5 1600 CPU, this one entity creates alarms on the following charts and
1288
dimensions:
1289
1289
-- `cpu.cpu0`
1290
- - `cpu_template_user`
1291
- - `cpu_template_system`
1292
- - `cpu_template_nice`
1290
+- `cpu.cpu0`
1291
+ - `cpu_template_user`
1292
+ - `cpu_template_system`
1293
+ - `cpu_template_nice`
1294
1294
-- `cpu.cpu1`
1295
- - `cpu_template_user`
1296
- - `cpu_template_system`
1297
- - `cpu_template_nice`
1295
+- `cpu.cpu1`
1296
+ - `cpu_template_user`
1297
+ - `cpu_template_system`
1298
+ - `cpu_template_nice`
1299
1299
-- `cpu.cpu2`
1300
- - `cpu_template_user`
1301
- - `cpu_template_system`
1302
- - `cpu_template_nice`
1300
+- `cpu.cpu2`
1301
+ - `cpu_template_user`
1302
+ - `cpu_template_system`
1303
+ - `cpu_template_nice`
1304
1304
-- ...
1305
+- ...
1306
1306
-- `cpu.cpu11`
1307
- - `cpu_template_user`
1308
- - `cpu_template_system`
1309
- - `cpu_template_nice`
1307
+- `cpu.cpu11`
1308
+ - `cpu_template_user`
1309
+ - `cpu_template_system`
1310
+ - `cpu_template_nice`
1311
1312
And how just a few of those dimension template-generated alarms look like in the Netdata dashboard.
1313
packaging/installer/methods/kickstart.md
-8
@@ -164,11 +164,3 @@ run the following:
164
```
165
166
If the script is valid, this command will return `OK, VALID`.
167
-
168
-## What's next?
169
-
170
-When you're finished with installation, check out [how to monitor your infrastructure](https://github.com/netdata/netdata/blob/master/docs/quickstart/infrastructure.md), or skip straight to [configuring the Netdata Agent](https://github.com/netdata/netdata/blob/master/docs/configure/nodes.md).
171
-
172
-Read through Netdata's [documentation](https://learn.netdata.cloud/docs), which is structured based on actions and
173
-solutions, to enable features like health monitoring, alarm notifications, long-term metrics storage, exporting to
174
-external databases, and more.
packaging/installer/methods/macos.md
-10
@@ -34,8 +34,6 @@ curl https://my-netdata.io/kickstart.sh > /tmp/netdata-kickstart.sh && sh /tmp/n
34
The Netdata Agent is installed under `/usr/local/netdata`. Dependencies are handled via Homebrew.
35
36
**Automatically connect to Netdata Cloud during installation**
37
-<!-- Potential reuse: https://learn.netdata.cloud/docs/agent/claim#connect-an-agent-running-in-macos-->
38
-<!--Potential reuse https://learn.netdata.cloud/docs/agent/packaging/installer/methods/kickstart#connect-node-to-netdata-cloud-during-installation The following information is copied from this link.-->
37
38
The `kickstart.sh` script accepts additional parameters to automatically [connect](https://github.com/netdata/netdata/blob/master/claim/README.md) your node to Netdata
39
Cloud immediately after installation. Find the `token` and `rooms` strings by [signing in to Netdata
@@ -102,11 +100,3 @@ We don't recommend installing Netdata from source on macOS, as it can be difficu
100
> Your Netdata configuration directory will be at `/usr/local/netdata/`.
101
> Your stock configuration directory will be at `/usr/local/lib/netdata/conf.d/`.
102
> The installer will also install a startup plist to start Netdata when your macOS system boots.
105
-
106
-## What's next?
107
-
108
-When you're finished with installation, check out [how to monitor your infrastructure](https://github.com/netdata/netdata/blob/master/docs/quickstart/infrastructure.md), or skip straight to [configuring the Netdata Agent](https://github.com/netdata/netdata/blob/master/docs/configure/nodes.md).
109
-
110
-Read through Netdata's [documentation](https://learn.netdata.cloud/docs), which is structured based on actions and
111
-solutions, to enable features like health monitoring, alarm notifications, long-term metrics storage, exporting to
112
-external databases, and more.
packaging/installer/methods/manual.md
-8
@@ -226,11 +226,3 @@ Our current build process unfortunately has some issues when using certain confi
226
If the installation fails with errors like `/bin/ld: externaldeps/libwebsockets/libwebsockets.a(context.c.o): relocation R_X86_64_32 against '.rodata.str1.1' can not be used when making a PIE object; recompile with -fPIC`, and you are trying to build with `clang` on Linux, you will need to build Netdata using GCC to get a fully functional install.
227
228
In most cases, you can do this by running `CC=gcc ./netdata-installer.sh`.
229
-
230
-## What's next?
231
-
232
-When you're finished with installation, check out [how to monitor your infrastructure](https://github.com/netdata/netdata/blob/master/docs/quickstart/infrastructure.md), or skip straight to [configuring the Netdata Agent](https://github.com/netdata/netdata/blob/master/docs/configure/nodes.md).
233
-
234
-Read through Netdata's [documentation](https://learn.netdata.cloud/docs), which is structured based on actions and
235
-solutions, to enable features like health monitoring, alarm notifications, long-term metrics storage, exporting to
236
-external databases, and more.
packaging/installer/methods/offline.md
-8
@@ -57,11 +57,3 @@ offline install source directory. It accepts all the [same options as the kickst
57
script](https://github.com/netdata/netdata/blob/master/packaging/installer/methods/kickstart.md#optional-parameters-to-alter-your-installation) for further
58
customization of the installation, though it will default to not enabling automatic updates (as they are not
59
supported on offline installs).
60
-
61
-## What's next?
62
-
63
-When you're finished with installation, check out [how to monitor your infrastructure](https://github.com/netdata/netdata/blob/master/docs/quickstart/infrastructure.md), or skip straight to [configuring the Netdata Agent](https://github.com/netdata/netdata/blob/master/docs/configure/nodes.md).
64
-
65
-Read through Netdata's [documentation](https://learn.netdata.cloud/docs), which is structured based on actions and
66
-solutions, to enable features like health monitoring, alarm notifications, long-term metrics storage, exporting to
67
-external databases, and more.