docs(systemd-journal.plugin): correct "Full-text search" (#19066)
Ilya Mashchenko committed
Nov 22, 2024 at 22:04 UTC
9ab1daf9346c6183275a2431aaa3cf8e28965a5c
1 file changed
+63
-62
src/collectors/systemd-journal.plugin/README.md
+63
-62
@@ -19,7 +19,7 @@ journal centralization servers.
19
- Supports `system`, `user`, `namespaces` and `remote` journals.
20
- Allows filtering on **any journal field** or **field value**, for any time-frame.
21
- Allows **full text search** (`grep`) on all journal fields, for any time-frame.
22
-- Provides a **histogram** for log entries over time, with a break down per field-value, for any field and any
22
+- Provides a **histogram** for log entries over time, with a breakdown per field-value, for any field and any
23
time-frame.
24
- Works directly on journal files, without any other third-party components.
25
- Supports coloring log entries, the same way `journalctl` does.
@@ -31,7 +31,7 @@ journal centralization servers.
31
`systemd-journal.plugin` is a Netdata Function Plugin.
32
33
To protect your privacy, as with all Netdata Functions, a free Netdata Cloud user account is required to access it.
34
-For more information check [this discussion](https://github.com/netdata/netdata/discussions/16136).
34
+For more information, check [this discussion](https://github.com/netdata/netdata/discussions/16136).
35
36
### Limitations
37
@@ -57,7 +57,7 @@ The following are limitations related to the availability of the plugin:
57
The following are limitations related to the features of `systemd` journal:
58
59
- This plugin assumes that binary field values are text fields with newlines in them. `systemd-journal` has the ability
60
- to support binary fields, without specifying the nature of the binary data. However, binary fields are commonly used
60
+ to support binary fields without specifying the nature of the binary data. However, binary fields are commonly used
61
to store log entries that include multiple lines of text. The plugin treats all binary fields are multi-line text.
62
- This plugin does not support multiple values per field for any given log entry. `systemd` journal has the ability to
63
accept the same field key, multiple times, with multiple values on a single log entry. This plugin will present the
@@ -65,7 +65,7 @@ The following are limitations related to the features of `systemd` journal:
65
- This plugin will only read journal files located in `/var/log/journal` or `/run/log/journal`. `systemd-journal-remote` has the
66
ability to store journal files anywhere (user configured). If journal files are not located in `/var/log/journal`
67
or `/run/log/journal` (and any of their subdirectories), the plugin will not find them. A simple solution is to link
68
- the other directories somewhere inside `/var/log/journal`. The plugin will pick them up, even if a sub-directory of
68
+ the other directories somewhere inside `/var/log/journal`. The plugin will pick them up, even if a subdirectory of
69
`/var/log/journal` is a link to a directory outside `/var/log/journal`.
70
71
Other than the above, this plugin supports all features of `systemd` journals.
@@ -77,7 +77,7 @@ The plugin automatically detects the available journal sources, based on the jou
77
78
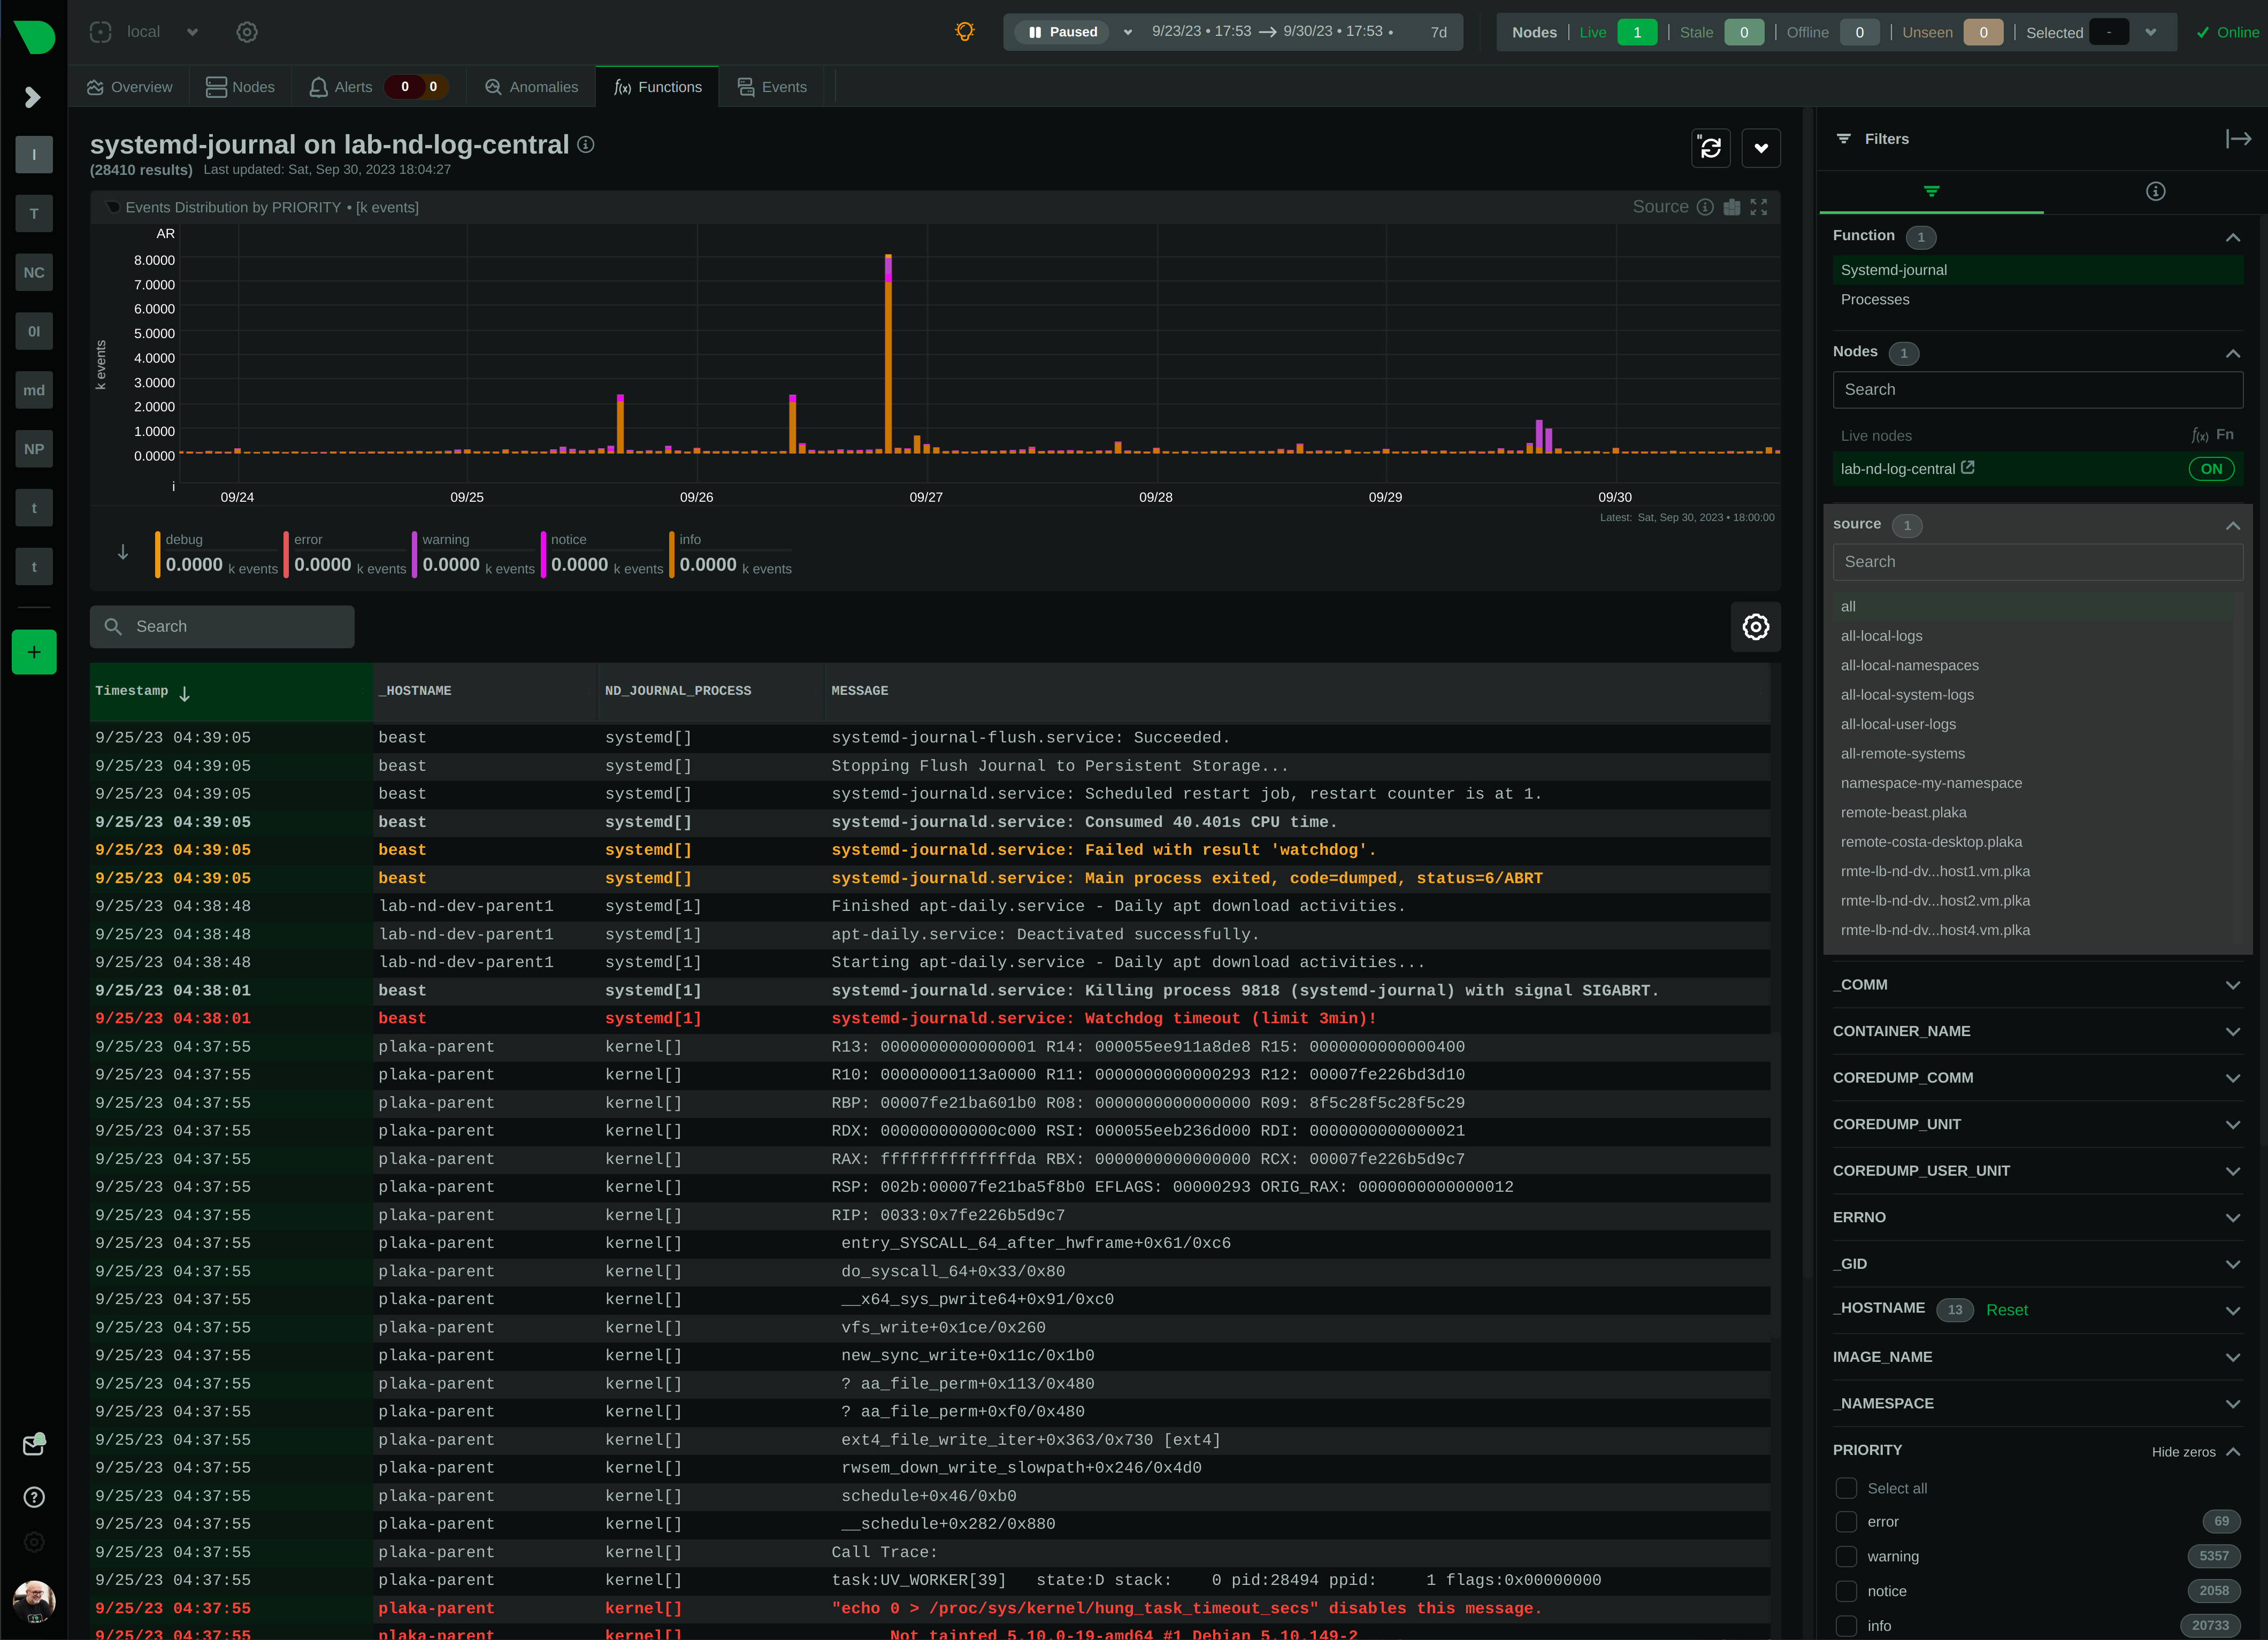
79
80
-The plugin, by default, merges all journal sources together, to provide a unified view of all log messages available.
80
+The plugin, by default, merges all journal sources to provide a unified view of all log messages available.
81
82
> To improve query performance, we recommend selecting the relevant journal source, before doing more analysis on the
83
> logs.
@@ -98,9 +98,9 @@ The plugin, by default, merges all journal sources together, to provide a unifie
98
99
Unlike `journalctl`, the Netdata plugin allows viewing, exploring and querying the journal files of **all users**.
100
101
-By default, each user, with a UID outside the range of system users (0 - 999), dynamic service users,
102
-and the nobody user (65534), will get their own set of `user` journal files. For more information about
103
-this policy check [Users, Groups, UIDs and GIDs on systemd Systems](https://systemd.io/UIDS-GIDS/).
101
+By default, each user, with a UID outside the range of system users (0–999), dynamic service users,
102
+and the nobody user (65,534), will get their own set of `user` journal files. For more information about
103
+this policy, check [Users, Groups, UIDs and GIDs on systemd Systems](https://systemd.io/UIDS-GIDS/).
104
105
Keep in mind that `user` journals are merged with the `system` journals when they are propagated to a journal
106
centralization server. So, at the centralization server, the `remote` journals contain both the `system` and `user`
@@ -155,7 +155,7 @@ The plugin automatically enriches certain fields to make them more user-friendly
155
- `_GID`, `OBJECT_GID`: the local group database is consulted to annotate them with group names.
156
- `_CAP_EFFECTIVE`: the encoded value is annotated with a human-readable list of the linux capabilities.
157
- `_SOURCE_REALTIME_TIMESTAMP`: the numeric value is annotated with human-readable datetime in UTC.
158
-- `MESSAGE_ID`: for the known `MESSAGE_ID`s, the value is replaced with the well known name of the event.
158
+- `MESSAGE_ID`: for the known `MESSAGE_ID`s, the value is replaced with the well-known name of the event.
159
160
The values of all other fields are presented as found in the journals.
161
@@ -182,17 +182,17 @@ related to this log line. You can close this `info` sidebar, by selecting the fi
182
### Journal fields as filters
183
184
The plugin presents a select list of fields as filters to the query, with counters for each of the possible values
185
-for the field. This list can used to quickly check which fields and values are available for the entire time-frame
185
+for the field. This list can be used to quickly check which fields and values are available for the entire time-frame
186
of the query.
187
188
-Internally the plugin has:
188
+Internally, the plugin has:
189
190
-1. A white-list of fields, to be presented as filters.
191
-2. A black-list of fields, to prevent them from becoming filters. This list includes fields with a very high
190
+1. An allowlist of fields to be presented as filters.
191
+2. A blocklist of fields to prevent them from becoming filters. This list includes fields with a very high
192
cardinality, like timestamps, unique message ids, etc. This is mainly for protecting the server's performance,
193
to avoid building in memory indexes for the fields that almost each of their values is unique.
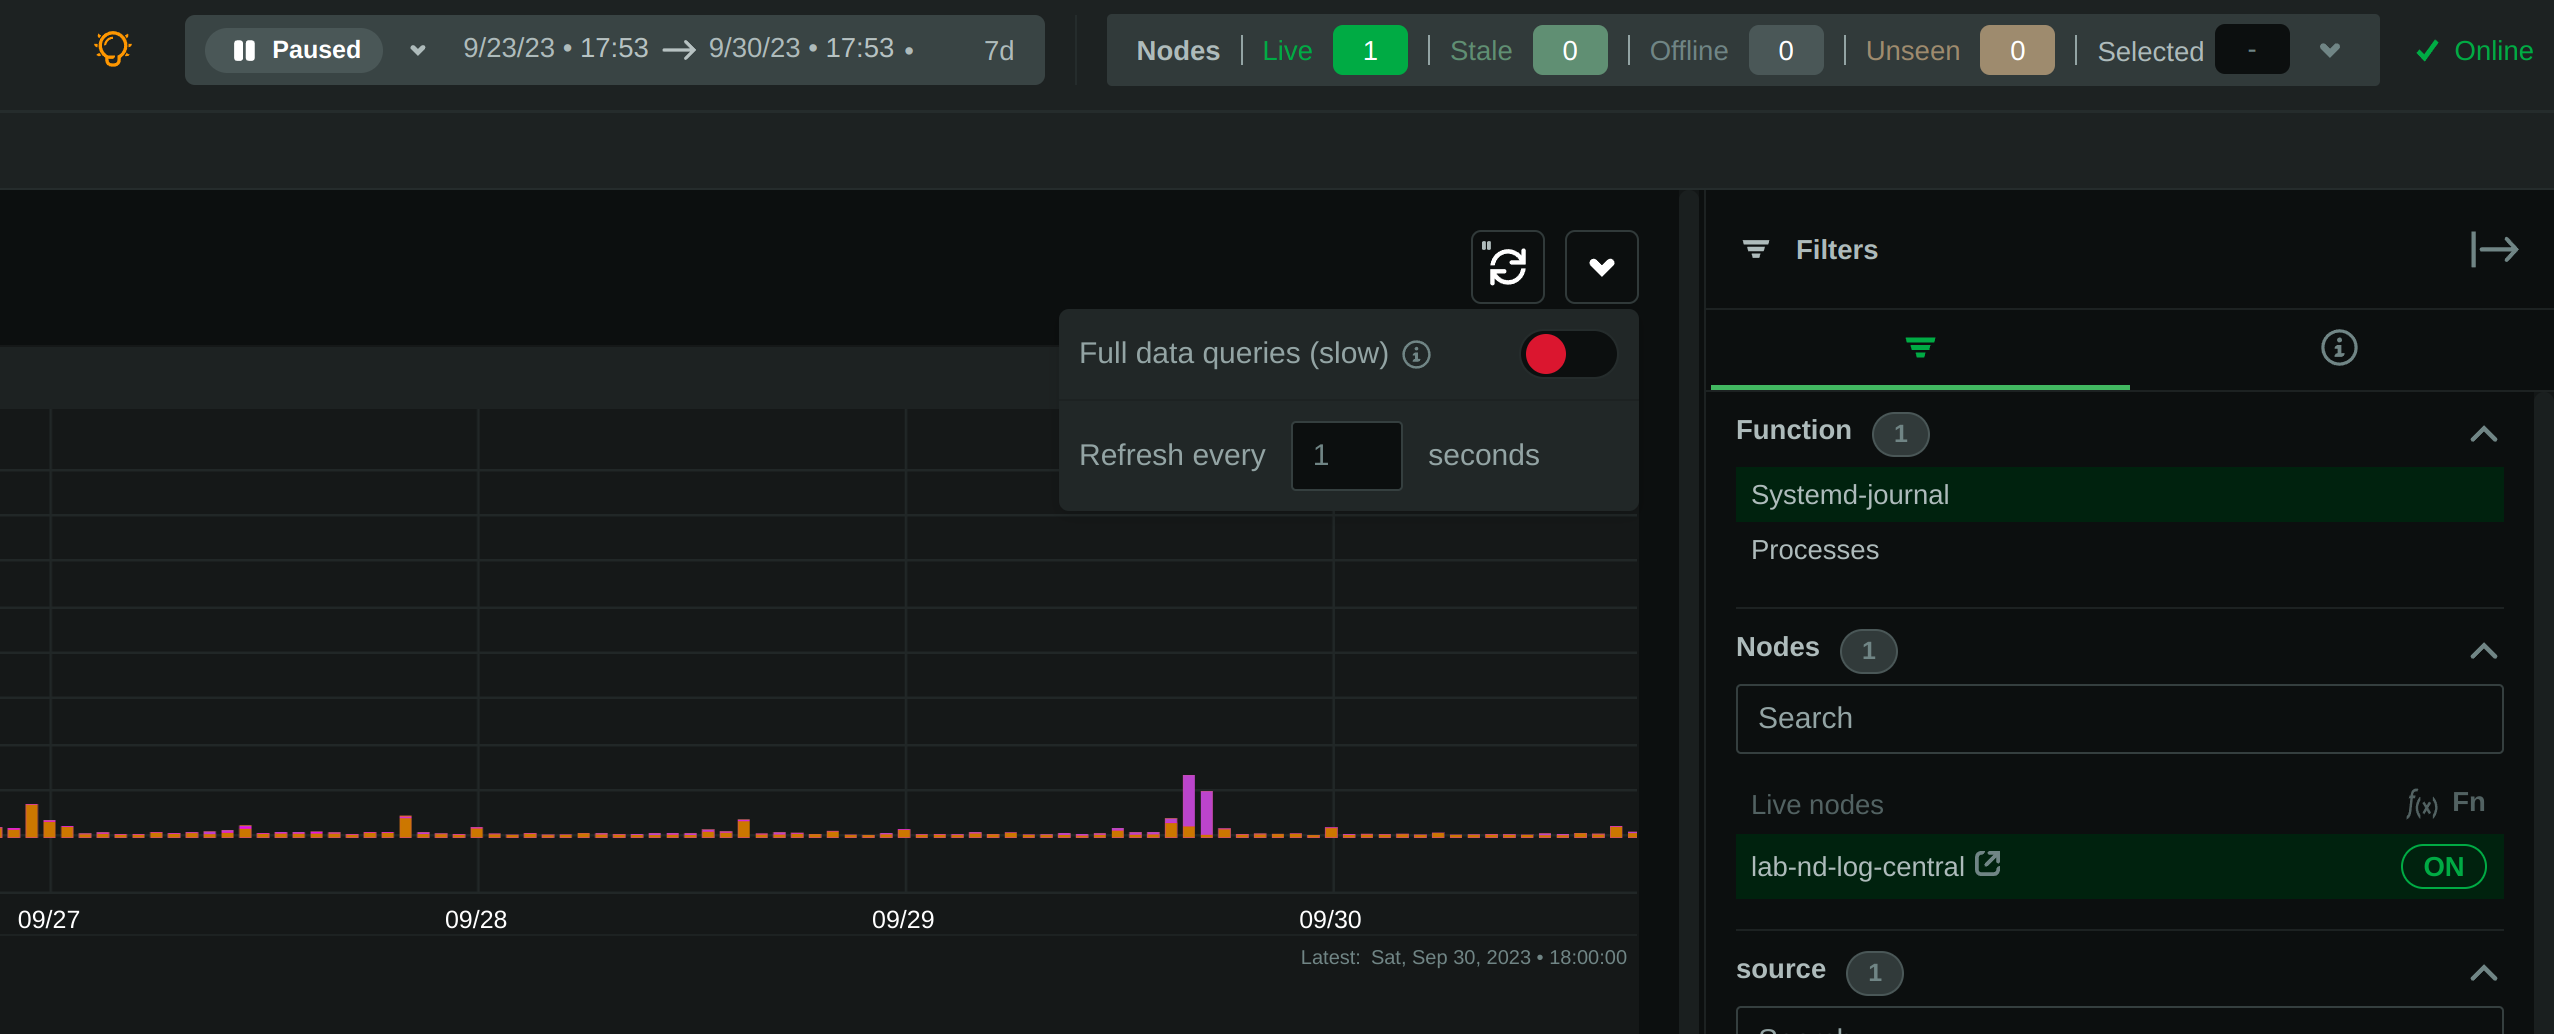
194
195
-Keep in mind that the values presented in the filters, and their sorting is affected by the "full data queries"
195
+Keep in mind that the values presented in the filters and their sorting are affected by the "full data queries"
196
setting:
197
198
@@ -206,7 +206,7 @@ the response required. So, "full data queries" can be significantly slower over
206
207
### Journal fields as histogram sources
208
209
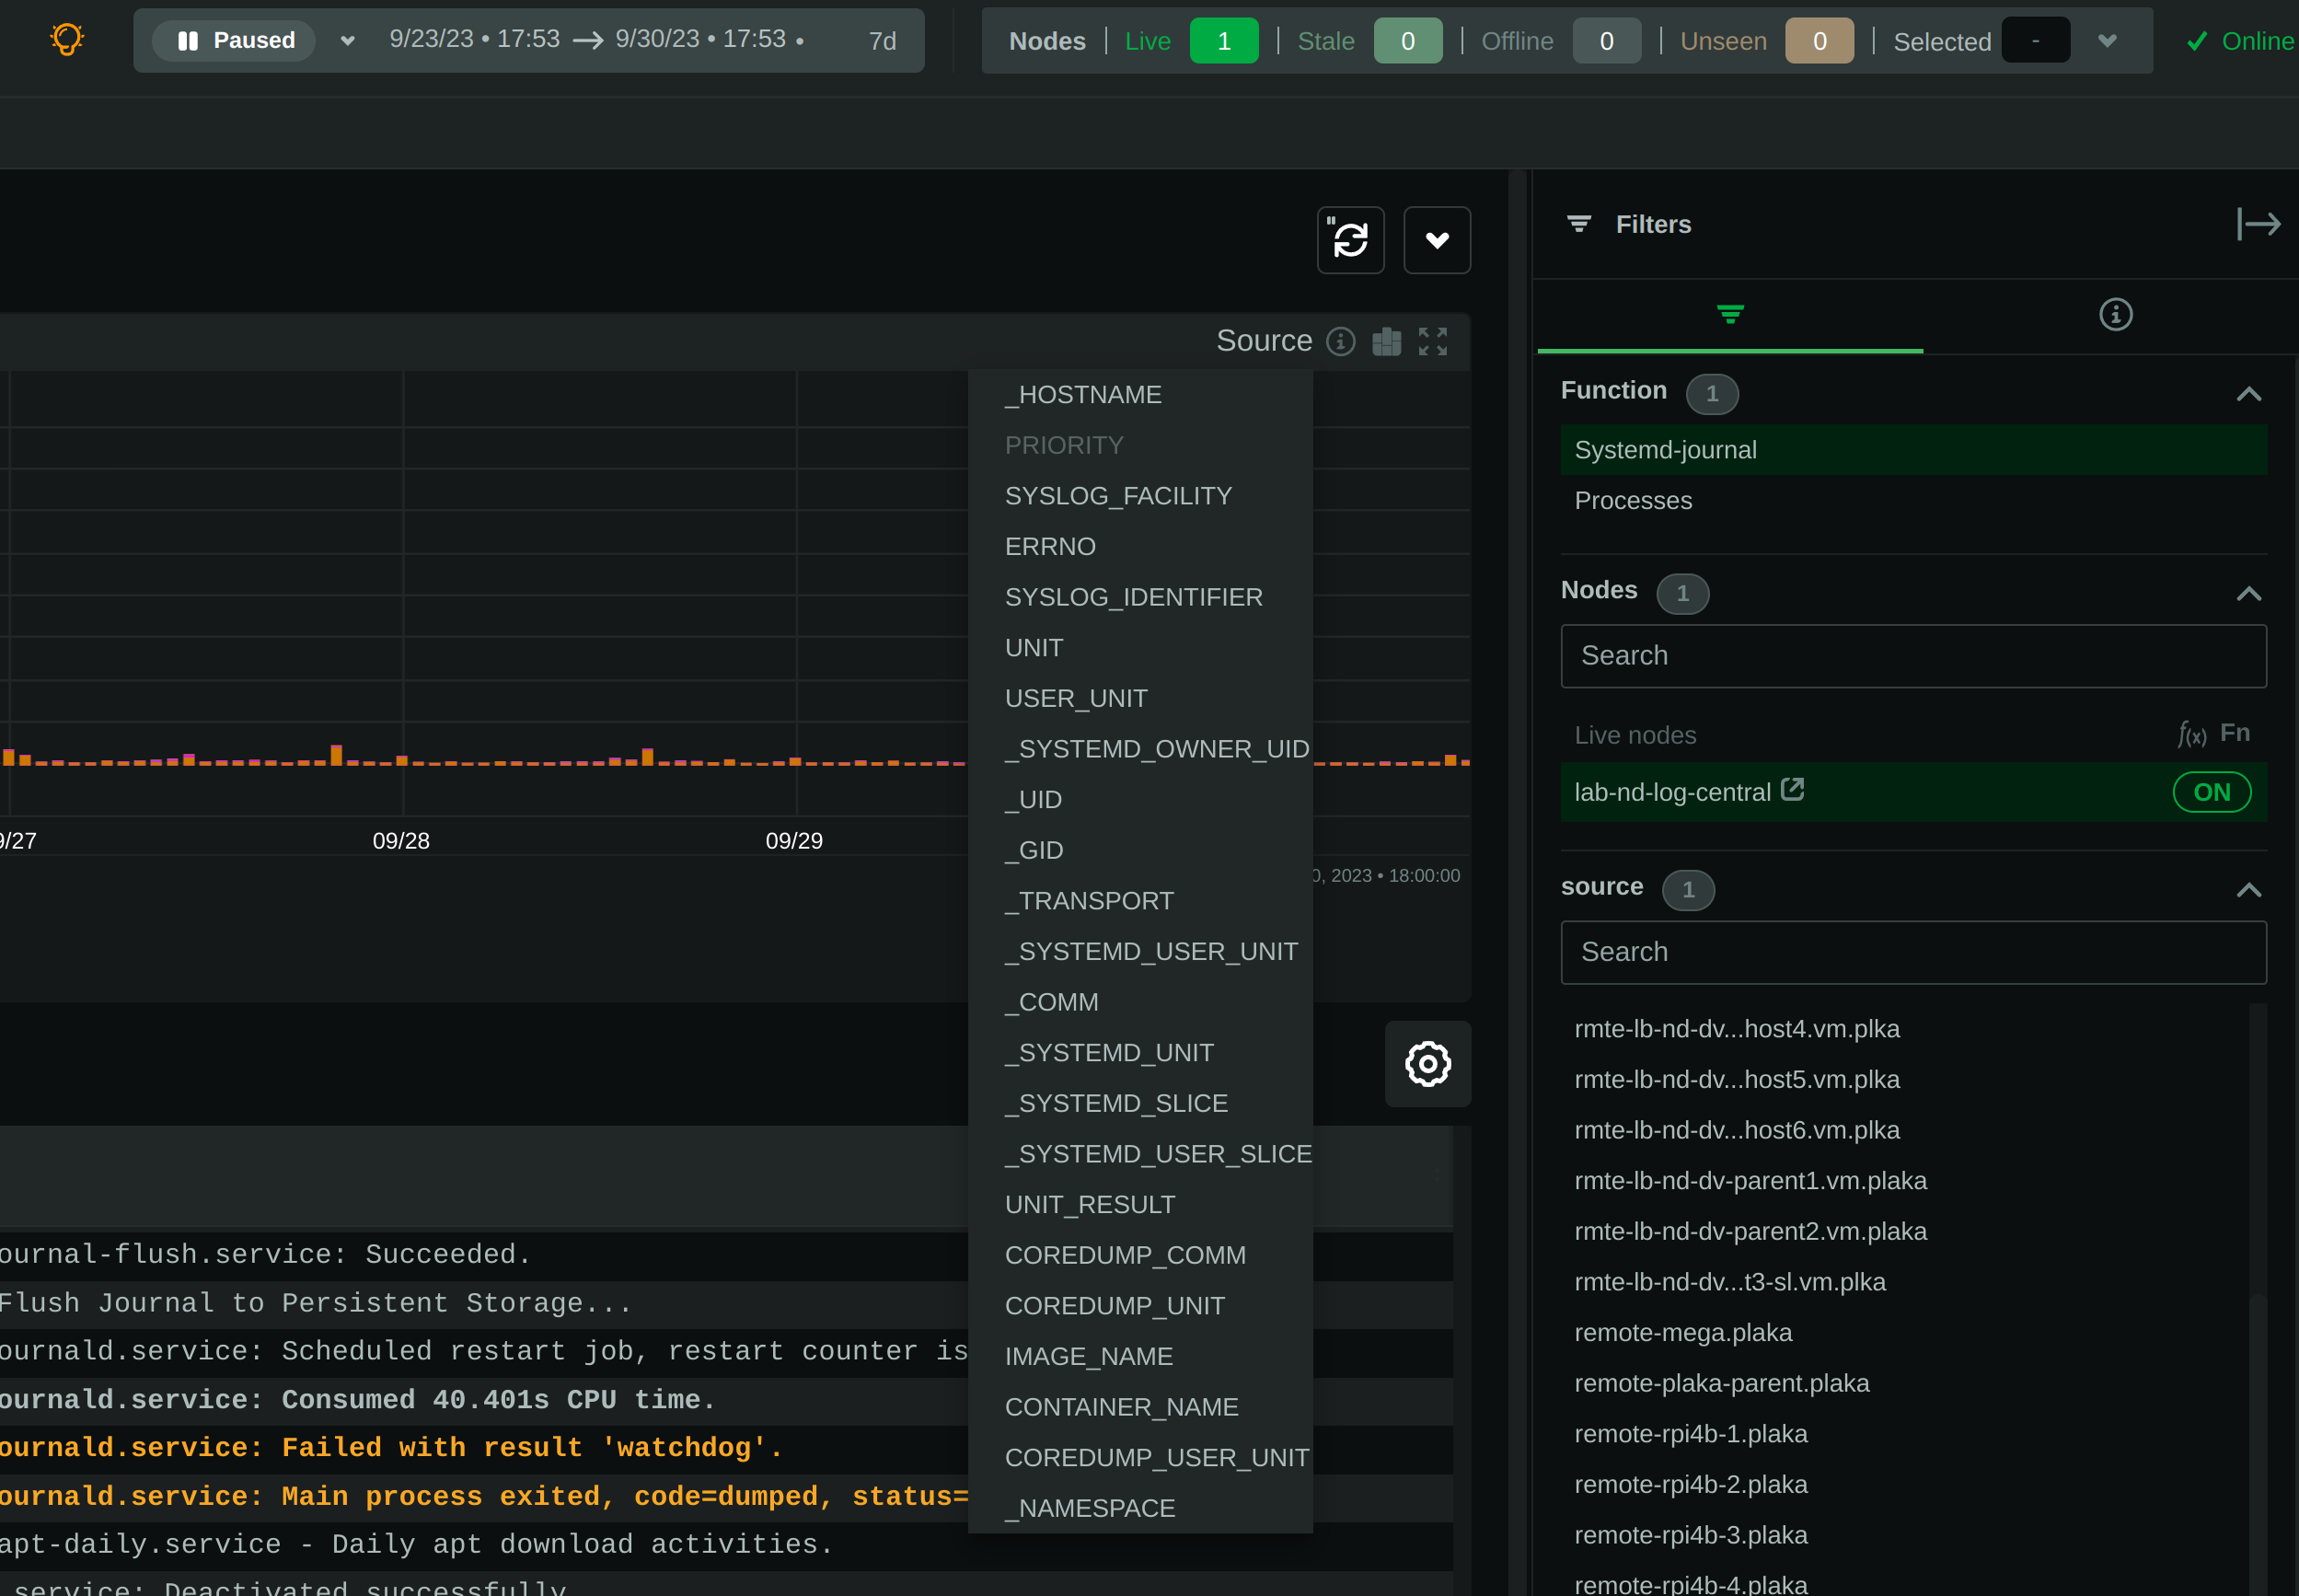
-The plugin presents a histogram of the number of log entries across time.
209
+The plugin visualizes log entry distribution over time using a histogram.
210
211
The data source of this histogram can be any of the fields that are available as filters.
212
For each of the values this field has, across the entire time-frame of the query, the histogram will get corresponding
@@ -216,16 +216,16 @@ The granularity of the histogram is adjusted automatically to have about 150 col
216
217
The histogram presented by the plugin is interactive:
218
219
-- **Zoom**, either with the global date-time picker, or the zoom tool in the histogram's toolbox.
220
-- **Pan**, either with global date-time picker, or by dragging with the mouse the chart to the left or the right.
219
+- **Zoom**, either with the global date-time picker or the zoom tool in the histogram's toolbox.
220
+- **Pan**, either with global date-time picker or by dragging with the mouse the chart to the left or the right.
221
- **Click**, to quickly jump to the highlighted point in time in the log entries.
222
223
224
225
## PLAY mode
226
227
-The plugin supports PLAY mode, to continuously update the screen with new log entries found in the journal files.
228
-Just hit the "play" button at the top of the Netdata dashboard screen.
227
+The plugin supports PLAY mode to continuously update the screen with new log entries found in the journal files.
228
+Hit the "play" button at the top of the Netdata dashboard screen.
229
230
On centralized log servers, PLAY mode provides a unified view of all the new logs encountered across the entire
231
infrastructure,
@@ -233,17 +233,25 @@ from all hosts sending logs to the central logs server via `systemd-remote`.
233
234
## Full-text search
235
236
-The plugin supports searching for any text on all fields of the log entries.
236
+The plugin supports searching through all fields of log entries using text patterns.
237
238
-Full text search is combined with the selected filters.
238
+**Pattern Matching**:
239
240
-The text box accepts asterisks `*` as wildcards. So, `a*b*c` means match anything that contains `a`, then `b` and
241
-then `c` with anything between them.
240
+- All patterns use "contains" matching (not exact match).
241
+- Patterns support wildcards (`*`) to match any characters.
242
+- Example: `error` matches "error", "errors", "error_count", etc.
243
+- Example with wildcard: `a*b` matches anything containing `a` followed by `b`, like `acb`, `a_long_b`.
244
243
-Spaces are treated as OR expressions. So that `a*b c*d` means `a*b OR c*d`.
245
+**Multiple Patterns**:
246
245
-Negative expressions are supported, by prefixing any string with `!`. Example: `!systemd *` means match anything that
246
-does not contain `systemd` on any of its fields.
247
+- Separate patterns with ` | ` (pipe character with spaces on both sides).
248
+- Multiple patterns are combined with OR logic.
249
+- Example: `error | warning` matches entries containing either `error` OR `warning`.
250
+
251
+**Negative Patterns**:
252
+
253
+- Prefix pattern with `!` to exclude matching entries.
254
+- Example: `!systemd | *` matches any entry that does NOT contain `systemd`.
255
256
## Query performance
257
@@ -252,15 +260,15 @@ Journal files are designed to be accessed by multiple readers and one writer, co
260
Readers (like this Netdata plugin), open the journal files and `libsystemd`, behind the scenes, maps regions
261
of the files into memory, to satisfy each query.
262
255
-On logs aggregation servers, the performance of the queries depend on the following factors:
263
+On logs aggregation servers, the performance of the queries depends on the following factors:
264
265
1. The **number of files** involved in each query.
266
259
- This is why we suggest to select a source when possible.
267
+ This is why we suggest selecting a source when possible.
268
269
2. The **speed of the disks** hosting the journal files.
270
263
- Journal files perform a lot of reading while querying, so the fastest the disks, the faster the query will finish.
271
+ Journal files perform a lot of reading while querying, so the faster the disks, the faster the query will finish.
272
273
3. The **memory available** for caching parts of the files.
274
@@ -273,14 +281,12 @@ On logs aggregation servers, the performance of the queries depend on the follow
281
282
In general, for a faster experience, **keep a low number of rows within the visible timeframe**.
283
276
-Even on long timeframes, selecting a couple of filters that will result in a **few dozen thousand** log entries
277
-will provide fast / rapid responses, usually less than a second. To the contrary, viewing timeframes with **millions
278
-of entries** may result in longer delays.
284
+Even with long timeframes and a few tens of thousands of matching log entries, filtering will typically yield results in under a second. Large datasets with millions of entries can impact performance and lead to longer query times.
285
286
The plugin aborts journal queries when your browser cancels inflight requests. This allows you to work on the UI
287
while there are background queries running.
288
283
-At the time of this writing, this Netdata plugin is about 25-30 times faster than `journalctl` on queries that access
289
+At the time of this writing, this Netdata plugin is about 25–30 times faster than `journalctl` on queries that access
290
multiple journal files, over long time-frames.
291
292
During the development of this plugin, we submitted, to `systemd`, a number of patches to improve `journalctl`
@@ -294,21 +300,21 @@ However, even after these patches are merged, `journalctl` will still be 2x slow
300
on multi-journal queries.
301
302
The problem lies in the way `libsystemd` handles multi-journal file queries. To overcome this problem,
297
-the Netdata plugin queries each file individually and it then it merges the results to be returned.
303
+the Netdata plugin queries each file individually, and then it merges the results to be returned.
304
This is transparent, thanks to the `facets` library in `libnetdata` that handles on-the-fly indexing, filtering,
305
and searching of any dataset, independently of its source.
306
307
## Performance at scale
308
309
On busy logs servers, or when querying long timeframes that match millions of log entries, the plugin has a sampling
304
-algorithm to allow it respond promptly. It works like this:
310
+algorithm to allow it to respond promptly. It works like this:
311
312
1. The latest 500k log entries are queried in full, evaluating all the fields of every single log entry. This evaluation
313
allows counting the unique values per field, updating the counters next to each value at the filters section of the
314
dashboard.
309
-2. When the latest 500k log entries have been processed and there are more data to read, the plugin divides evenly 500k
315
+2. When the latest 500k log entries have been processed and there is more data to read, the plugin evenly divides 500k
316
more log entries to the number of journal files matched by the query. So, it will continue to evaluate all the fields
311
- of all log entries, up to the budget per file, aiming to fully query 1 million log entries in total.
317
+ of all log entries, up to the budget per file, aiming to fully query one million log entries in total.
318
3. When the budget is hit for a given file, the plugin continues to scan log entries, but this time it does not evaluate
319
the fields and their values, so the counters per field and value are not updated. These unsampled log entries are
320
shown in the histogram with the label `[unsampled]`.
@@ -317,21 +323,16 @@ algorithm to allow it respond promptly. It works like this:
323
5. When the `[unsampled]` budget is exhausted, the plugin stops processing the journal file and based on the processing
324
completed so far and the number of entries in the journal file, it estimates the remaining number of log entries in
325
that file. This is shown as `[estimated]` at the histogram.
320
-6. In systemd versions 254 or later, the plugin fetches the unique sequence number of each log entry and calculates the
321
- the percentage of the file matched by the query, versus the total number of the log entries in the journal file.
326
+6. In systemd versions 254 or later, the plugin fetches the unique sequence number of each log entry and calculates the percentage of the file matched by the query, versus the total number of the log entries in the journal file.
327
7. In systemd versions prior to 254, the plugin estimates the number of entries the journal file contributes to the
323
- query, using the amount of log entries matched it vs. the total duration the log file has entries for.
328
+ query, using the number of log entries matched it vs. the total duration the log file has entries for.
329
325
-The above allow the plugin to respond promptly even when the number of log entries in the journal files is several
326
-dozens millions, while providing accurate estimations of the log entries over time at the histogram and enough counters
327
-at the fields filtering section to help users get an overview of the whole timeframe.
330
+The plugin efficiently handles datasets with tens of millions of log entries, providing real-time responses and accurate visualizations.
331
329
-The fact that the latest 500k log entries and 1% of all journal files (which are spread over time) have been fully
330
-evaluated, including counting the number of appearances for each field value, the plugin usually provides an accurate
331
-representation of the whole timeframe.
332
+By analyzing the latest 500 thousand log entries and 1% of all journal files, the plugin provides an accurate representation of the entire timeframe.
333
334
Keep in mind that although the plugin is quite effective and responds promptly when there are hundreds of journal files
334
-matching a query, response times may be longer when there are several thousands of smaller files. systemd versions 254+
335
+matching a query, response times may be longer when there are several thousands of smaller files. Systemd versions 254+
336
attempt to solve this problem by allowing `systemd-journal-remote` to create larger files. However, for systemd
337
versions prior to 254, `systemd-journal-remote` creates files of up to 32MB each, which when running very busy
338
journals centralization servers aggregating several thousands of log entries per second, the number of files can grow
@@ -339,7 +340,7 @@ to several dozens of thousands quickly. In such setups, the plugin should ideall
340
entirely, relying solely on the estimations of the sequence of files each file is part of. However, this has not been
341
implemented yet. To improve the query performance in such setups, the user has to query smaller timeframes.
342
342
-Another optimization taking place in huge journal centralization points, is the initial scan of the database. The plugin
343
+Another optimization taking place in huge journal centralization points is the initial scan of the database. The plugin
344
needs to know the list of all journal files available, including the details of the first and the last message in each
345
of them. When there are several thousands of files in a directory (like it usually happens in `/var/log/journal/remote`),
346
directory listing and examination of each file can take a considerable amount of time (even `ls -l` takes minutes).
@@ -355,16 +356,16 @@ that it utilizes several techniques to require minimal disk footprint (like dedu
356
values and fields, compression) the disk footprint of journal files remains significantly higher compared to other log
357
management solutions.
358
358
-The higher disk footprint results in higher disk I/O during querying, since a lot more data have to read from disk to
359
-evaluate a query. Query performance at scale can greatly benefit by utilizing a compressed filesystem (ext4, btrfs, zfs)
359
+The higher disk footprint results in higher disk I/O during querying, since a lot more data has to be read from disk to
360
+evaluate a query. Query performance at scale can greatly benefit from using a compressed filesystem (ext4, btrfs, zfs)
361
to store systemd-journal files.
362
363
systemd-journal files are cached by the operating system. There is no database server to serve queries. Each file is
364
opened and the query runs by directly accessing the data in it.
365
365
-Therefore systemd-journal relies on the caching layer of the operating system to optimize query performance. The more
366
+Therefore, systemd-journal relies on the caching layer of the operating system to optimize query performance. The more
367
RAM the system has, although it will not be reported as `used` (it will be reported as `cache`), the faster the queries
367
-will get. The first time a timeframe is accessed the query performance will be slower, but further queries on the same
368
+will get. The first time a timeframe is accessed, the query performance will be slower, but further queries on the same
369
timeframe will be significantly faster since journal data are now cached in memory.
370
371
So, on busy logs centralization systems, queries performance can be improved significantly by using a compressed
@@ -381,7 +382,7 @@ This Netdata plugin does not require any configuration or maintenance.
382
Yes. You can centralize your logs using `systemd-journal-remote`, and then install Netdata
383
on this logs centralization server to explore the logs of all your infrastructure.
384
384
-This plugin will automatically provide multi-node views of your logs and also give you the ability to combine the logs
385
+This plugin will automatically provide multi-node views of your logs and also allow you to combine the logs
386
of multiple servers, as you see fit.
387
388
Check [configuring a logs centralization server](#how-do-i-configure-a-journal-centralization-server).
@@ -391,7 +392,7 @@ Check [configuring a logs centralization server](#how-do-i-configure-a-journal-c
392
Yes. When your nodes are connected to a Netdata parent, all their functions are available
393
via the parent's UI. So, from the parent UI, you can access the functions of all your nodes.
394
394
-Keep in mind that to protect your privacy, in order to access Netdata functions, you need a
395
+Keep in mind that to protect your privacy, to access Netdata functions, you need a
396
free Netdata Cloud account.
397
398
### Is any of my data exposed to Netdata Cloud from this plugin?
@@ -404,7 +405,7 @@ to your web browser.
405
Also check [this discussion](https://github.com/netdata/netdata/discussions/16136).
406
407
When you access Netdata via `https://app.netdata.cloud`, your data travel via Netdata Cloud,
407
-but they are not stored in Netdata Cloud. This is to allow you access your Netdata Agents from
408
+but they are not stored in Netdata Cloud. This is to allow you to access your Netdata Agents from
409
anywhere. All communication from/to Netdata Cloud is encrypted.
410
411
### What are `volatile` and `persistent` journals?
@@ -417,9 +418,9 @@ disk I/O, or does not have any writable disks at all.
418
419
For more information check `man systemd-journald`.
420
420
-### I centralize my logs with Loki. Why to use Netdata for my journals?
421
+### I centralize my logs with Loki. Why use Netdata for my journals?
422
422
-`systemd` journals have almost infinite cardinality at their labels and all of them are indexed,
423
+`systemd` journals have almost infinite cardinality at their labels, and all of them are indexed,
424
even if every single message has unique fields and values.
425
426
When you send `systemd` journal logs to Loki, even if you use the `relabel_rules` argument to
@@ -437,9 +438,9 @@ So, Loki and `systemd-journal` are good for different use cases.
438
collecting the system and applications logs. And for its use case, it has advantages over other
439
centralization solutions. So, why not use it?
440
440
-### Is it worth to build a `systemd` logs centralization server?
441
+### Is it worth building a `systemd` logs centralization server?
442
442
-Yes. It is simple, fast and the software to do it is already in your systems.
443
+Yes. It is straightforward, fast, and the software to do it is already in your systems.
444
445
For application and system logs, `systemd` journal is ideal and the visibility you can get
446
by centralizing your system logs and the use of this Netdata plugin, is unparalleled.
@@ -449,18 +450,18 @@ by centralizing your system logs and the use of this Netdata plugin, is unparall
450
A short summary to get journal server running can be found below.
451
There are two strategies you can apply, when it comes down to a centralized server for `systemd` journal logs.
452
452
-1. _Active sources_, where the centralized server fetches the logs from each individual server
453
+1. _Active sources_, where the centralized server fetches the logs from each server
454
2. _Passive sources_, where the centralized server accepts a log stream from an individual server.
455
456
For more options and reference to documentation, check `man systemd-journal-remote` and `man systemd-journal-upload`.
457
458
#### _passive_ journal centralization without encryption
459
459
-If you want to setup your own passive journal centralization setup without encryption, [check out guide on it](/docs/observability-centralization-points/logs-centralization-points-with-systemd-journald/passive-journal-centralization-without-encryption.md).
460
+If you want to set up your own passive journal centralization setup without encryption, [check out guide on it](/docs/observability-centralization-points/logs-centralization-points-with-systemd-journald/passive-journal-centralization-without-encryption.md).
461
462
#### _passive_ journal centralization with encryption using self-signed certificates
463
463
-If you want to setup your own passive journal centralization setup using self-signed certificates for encryption, [check out guide on it](https://github.com/netdata/netdata/blob/master/docs/observability-centralization-points/logs-centralization-points-with-systemd-journald).
464
+If you want to set up your own passive journal centralization setup using self-signed certificates for encryption, [check out guide on it](https://github.com/netdata/netdata/blob/master/docs/observability-centralization-points/logs-centralization-points-with-systemd-journald).
465
466
#### Limitations when using a logs centralization server
467