k8s doc edits (#17471)
Co-authored-by: ilyam8 <ilya@netdata.cloud>
Fotis Voutsas committed
Apr 22, 2024 at 14:11 UTC
9cc4786a97f06fb68d421603a1a663a28262ff34
1 file changed
+27
-122
docs/cloud/visualize/kubernetes.md
+27
-122
@@ -1,137 +1,42 @@
1
-<!--
2
-title: "Kubernetes visualizations"
3
-description: "Netdata Cloud features rich, zero-configuration Kubernetes monitoring for the resource utilization and application metrics of Kubernetes (k8s) clusters."
4
-custom_edit_url: "https://github.com/netdata/netdata/blob/master/docs/cloud/visualize/kubernetes.md"
5
-sidebar_label: "Kubernetes visualizations"
6
-learn_status: "Published"
7
-learn_topic_type: "Concepts"
8
-learn_rel_path: "Operations/Visualizations"
9
--->
1
+# Kubernetes tab
2
11
-# Kubernetes visualizations
3
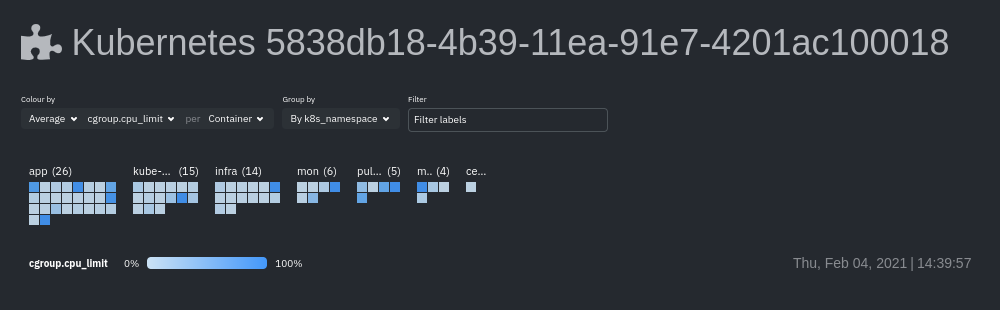
+The Netdata dashboards feature enhanced visualizations for the resource utilization of Kubernetes (k8s) clusters, embedded in the default [Metrics tab](https://github.com/netdata/netdata/blob/master/docs/dashboard/metrics-tab-and-single-node-tabs.md) dashboard.
4
13
-Netdata Cloud features enhanced visualizations for the resource utilization of Kubernetes (k8s) clusters, embedded in the default [Metrics tab](https://github.com/netdata/netdata/blob/master/docs/dashboard/metrics-tab-and-single-node-tabs.md) dashboard.
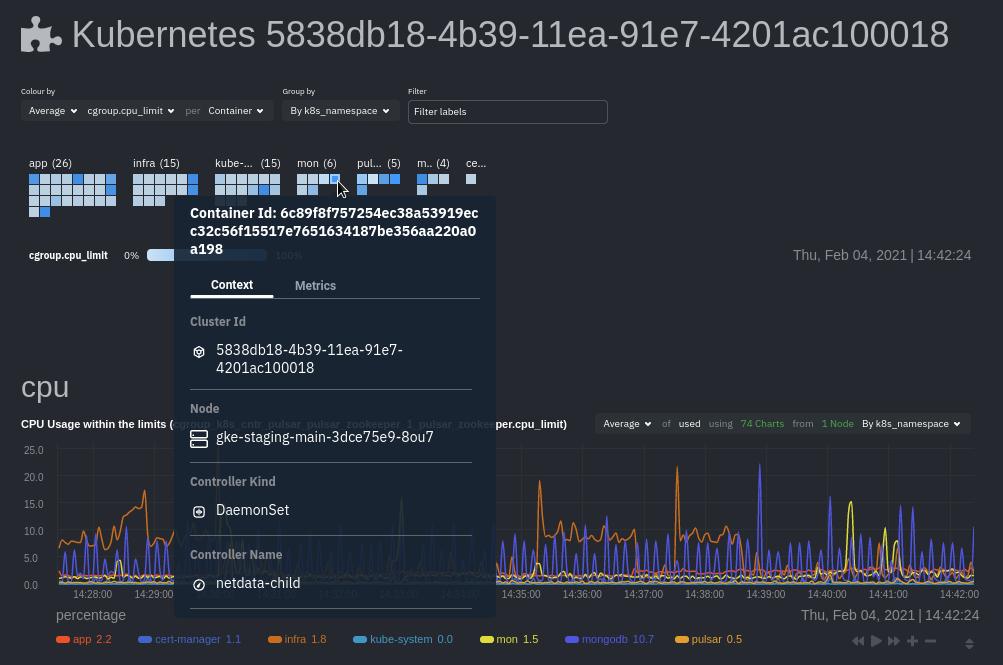
5
+These visualizations include a health map for viewing the status of k8s pods/containers, in addition to [Netdata charts](https://github.com/netdata/netdata/blob/master/docs/cloud/visualize/interact-new-charts.md) for viewing per-second CPU, memory, disk, and networking metrics from k8s nodes.
6
15
-These visualizations include a health map for viewing the status of k8s pods/containers, in addition to composite charts
16
-for viewing per-second CPU, memory, disk, and networking metrics from k8s nodes.
17
-
18
-See our [Kubernetes deployment instructions](https://github.com/netdata/netdata/blob/master/packaging/installer/methods/kubernetes.md) for details on
19
-installation and connecting to Netdata Cloud.
7
+See our [Kubernetes deployment instructions](https://github.com/netdata/netdata/blob/master/packaging/installer/methods/kubernetes.md) for details on deploying Netdata on your Kubernetes cluster.
8
9
## Available Kubernetes metrics
10
11
Netdata Cloud organizes and visualizes the following metrics from your Kubernetes cluster from every container:
12
25
-- `cpu_limit`: CPU utilization as a percentage of the limit defined by the [pod specification
26
- `spec.containers[].resources.limits.cpu`](https://kubernetes.io/docs/concepts/configuration/manage-resources-containers/#resource-requests-and-limits-of-pod-and-container)
27
- or a [`LimitRange`
28
- object](https://kubernetes.io/docs/tasks/administer-cluster/manage-resources/cpu-default-namespace/#create-a-limitrange-and-a-pod).
29
-- `cpu`: CPU utilization of the pod/container. 100% usage equals 1 fully-utilized core, 200% equals 2 fully-utilized
30
- cores, and so on.
31
-- `cpu_per_core`: CPU utilization averaged across available cores.
32
-- `mem_usage_limit`: Memory utilization, without cache, as a percentage of the limit defined by the [pod specification
33
- `spec.containers[].resources.limits.memory`](https://kubernetes.io/docs/concepts/configuration/manage-resources-containers/#resource-requests-and-limits-of-pod-and-container)
34
- or a [`LimitRange`
35
- object](https://kubernetes.io/docs/tasks/administer-cluster/manage-resources/cpu-default-namespace/#create-a-limitrange-and-a-pod).
36
-- `mem_usage`: Used memory, without cache.
37
-- `mem`: The sum of `cache` and `rss` (resident set size) memory usage.
38
-- `writeback`: The size of `dirty` and `writeback` cache.
39
-- `mem_activity`: Sum of `in` and `out` bandwidth.
40
-- `pgfaults`: Sum of page fault bandwidth, which are raised when the Kubernetes cluster tries accessing a memory page
41
- that is mapped into the virtual address space, but not actually loaded into main memory.
42
-- `throttle_io`: Sum of `read` and `write` per second across all PVs/PVCs attached to the container.
43
-- `throttle_serviced_ops`: Sum of the `read` and `write` operations per second across all PVs/PVCs attached to the
44
- container.
45
-- `net.net`: Sum of `received` and `sent` bandwidth per second.
46
-- `net.packets`: Sum of `multicast`, `received`, and `sent` packets.
47
-
48
-When viewing the [health map](#health-map), Netdata Cloud shows the above metrics per container, or aggregated based on
13
+| Metric | Description |
14
+|------------------------------------|-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
15
+| `k8s.cgroup.cpu_limit` | CPU utilization as a percentage of the limit defined by the [pod specification `spec.containers[].resources.limits.cpu`](https://kubernetes.io/docs/concepts/configuration/manage-resources-containers/#resource-requests-and-limits-of-pod-and-container) or a [`LimitRange` object](https://kubernetes.io/docs/tasks/administer-cluster/manage-resources/cpu-default-namespace/#create-a-limitrange-and-a-pod). |
16
+| `k8s.cgroup.cpu` | CPU utilization of the pod/container. 100% usage equals 1 fully-utilized core, 200% equals 2 fully-utilized cores, and so on. |
17
+| `k8s.cgroup.throttled` | The percentage of runnable periods when tasks in a cgroup have been throttled. |
18
+| `k8s.cgroup.throttled_duration` | The total time duration for which tasks in a cgroup have been throttled. |
19
+| `k8s.cgroup.mem_utilization` | Memory utilization within the configured or system-wide (if not set) limits. |
20
+| `k8s.cgroup.mem_usage_limit` | Memory utilization, without cache, as a percentage of the limit defined by the [pod specification `spec.containers[].resources.limits.memory`](https://kubernetes.io/docs/concepts/configuration/manage-resources-containers/#resource-requests-and-limits-of-pod-and-container) or a [`LimitRange` object](https://kubernetes.io/docs/tasks/administer-cluster/manage-resources/cpu-default-namespace/#create-a-limitrange-and-a-pod). |
21
+| `k8s.cgroup.mem_usage` | Used memory, without cache. |
22
+| `k8s.cgroup.mem` | The sum of `cache` and `rss` (resident set size) memory usage. |
23
+| `k8s.cgroup.writeback` | The size of `dirty` and `writeback` cache. |
24
+| `k8s.cgroup.pgfaults` | Sum of page fault bandwidth, which are raised when the Kubernetes cluster tries accessing a memory page that is mapped into the virtual address space, but not actually loaded into main memory. |
25
+| `k8s.cgroup.throttle_io` | Sum of `read` and `write` per second across all PVs/PVCs attached to the container. |
26
+| `k8s.cgroup.throttle_serviced_ops` | Sum of the `read` and `write` operations per second across all PVs/PVCs attached to the container. |
27
+| `k8s.cgroup.net_net` | Sum of `received` and `sent` bandwidth per second. |
28
+| `k8s.cgroup.net_packets` | Sum of `multicast`, `received`, and `sent` packets. |
29
+
30
+
31
+When viewing the [overview of this dashboard](#kubernetes-containers-overview), Netdata presents the above metrics per container, or aggregated based on
32
their associated pods.
33
51
-When viewing the [composite charts](#composite-charts), Netdata Cloud aggregates metrics from multiple nodes, pods, or
52
-containers, depending on the grouping chosen. For example, if you group the `cpu_limit` composite chart by
53
-`k8s_namespace`, the metrics shown will be the average of `cpu_limit` metrics from all nodes/pods/containers that are
54
-part of that namespace.
55
-
56
-## Health map
57
-
58
-The health map places each container or pod as a single box, then varies the intensity of its color to visualize the
59
-resource utilization of specific k8s pods/containers.
60
-
61
-
63
-
64
-Change the health map's coloring, grouping, and displayed nodes to customize your experience and learn more about the
65
-status of your k8s cluster.
34
+## Kubernetes Containers overview
35
67
-### Color by
36
+At the top of the Kubernetes containers section there is a map, that with a given context colorizes the containers in terms of their utilization.
37
69
-Color the health map by choosing an aggregate function to apply to an [available Kubernetes
70
-metric](#available-kubernetes-metrics), then whether you to display boxes for individual pods or containers.
71
-
72
-The default is the _average, of CPU within the configured limit, organized by container_.
73
-
74
-### Group by
75
-
76
-Group the health map by the `k8s_cluster_id`, `k8s_controller_kind`, `k8s_controller_name`, `k8s_kind`, `k8s_namespace`,
77
-and `k8s_node_name`. The default is `k8s_controller_name`.
78
-
79
-### Filtering
80
-
81
-Filtering behaves identically to the [node filter in War Rooms](https://github.com/netdata/netdata/blob/master/docs/cloud/visualize/node-filter.md), with the ability to
82
-filter pods/containers by `container_id` and `namespace`.
38
+The filtering of this map is controlled by using the [NIDL framework](https://github.com/netdata/netdata/blob/master/docs/cloud/visualize/interact-new-charts.md#nidl-framework) from the definition bar of the chart.
39
40
### Detailed information
41
86
-Hover over any of the pods/containers in the map to display a modal window, which contains contextual information
87
-and real-time metrics from that resource.
88
-
89
-
91
-
92
-The **context** tab provides the following details about a container or pod:
93
-
94
-- Cluster ID
95
-- Node
96
-- Controller Kind
97
-- Controller Name
98
-- Pod Name
99
-- Container
100
-- Kind
101
-- Pod UID
102
-
103
-This information helps orient you as to where the container/pod operates inside your cluster.
104
-
105
-The **Metrics** tab contains charts visualizing the last 15 minutes of the same metrics available in the [color by
106
-option](#color-by). Use these metrics along with the context, to identify which containers or pods are experiencing
107
-problematic behavior to investigate further, troubleshoot, and remediate with `kubectl` or another tool.
108
-
109
-## Composite charts
110
-
111
-The Kubernetes composite charts show real-time and historical resource utilization metrics from nodes, pods, or
112
-containers within your Kubernetes deployment.
113
-
114
-Kubernetes composite charts can also be
115
-grouped by the following labels:
116
-
117
-- `k8s_cluster_id`
118
-- `k8s_container_id`
119
-- `k8s_container_name`
120
-- `k8s_controller_kind`
121
-- `k8s_kind`
122
-- `k8s_namespace`
123
-- `k8s_node_name`
124
-- `k8s_pod_name`
125
-- `k8s_pod_uid`
126
-
127
-In addition, when you hover over a composite chart, the colors in the heat map changes as well, so you can see how
128
-certain pod/container-level metrics change over time.
129
-
130
-## Caveats
131
-
132
-There are some caveats and known issues with Kubernetes monitoring with Netdata Cloud.
133
-
134
-- **No way to remove any nodes** you might have
135
- [drained](https://kubernetes.io/docs/tasks/administer-cluster/safely-drain-node/) from your Kubernetes cluster. These
136
- drained nodes will be marked "unreachable" and will show up in War Room management screens/dropdowns. The same applies
137
- for any ephemeral nodes created and destroyed during horizontal scaling.
42
+Hover over any of the pods/containers in the map to display a modal window, which contains contextual information and real-time metrics from that resource.