Zscores python collector (#10673)
* adding zscores collector
Andrew Maguire committed
Apr 26, 2021 at 22:14 UTC
b053c8423e86785efa2d5c743daa331f623107c0
7 files changed
+421
collectors/python.d.plugin/Makefile.am
+1
@@ -109,6 +109,7 @@ include uwsgi/Makefile.inc
109
include varnish/Makefile.inc
110
include w1sensor/Makefile.inc
111
include web_log/Makefile.inc
112
+include zscores/Makefile.inc
113
114
pythonmodulesdir=$(pythondir)/python_modules
115
dist_pythonmodules_DATA = \
collectors/python.d.plugin/python.d.conf
+1
@@ -107,3 +107,4 @@ nginx_log: no
107
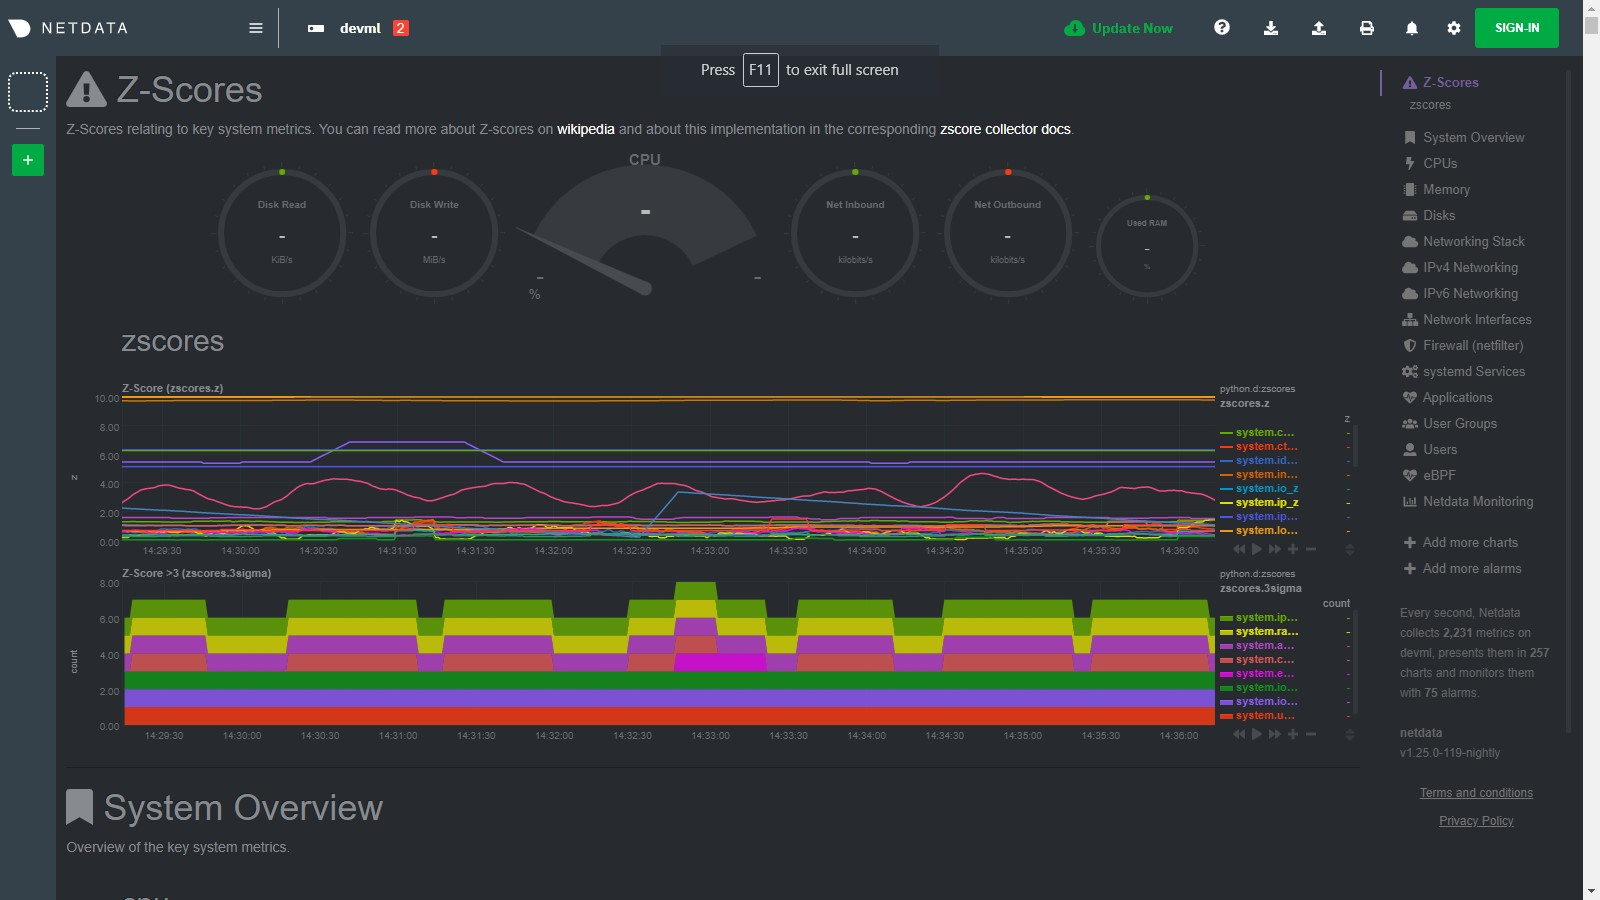
# varnish: yes
108
# w1sensor: yes
109
# web_log: yes
110
+# zscores: no
collectors/python.d.plugin/zscores/Makefile.inc
new
+12
@@ -0,0 +1,12 @@
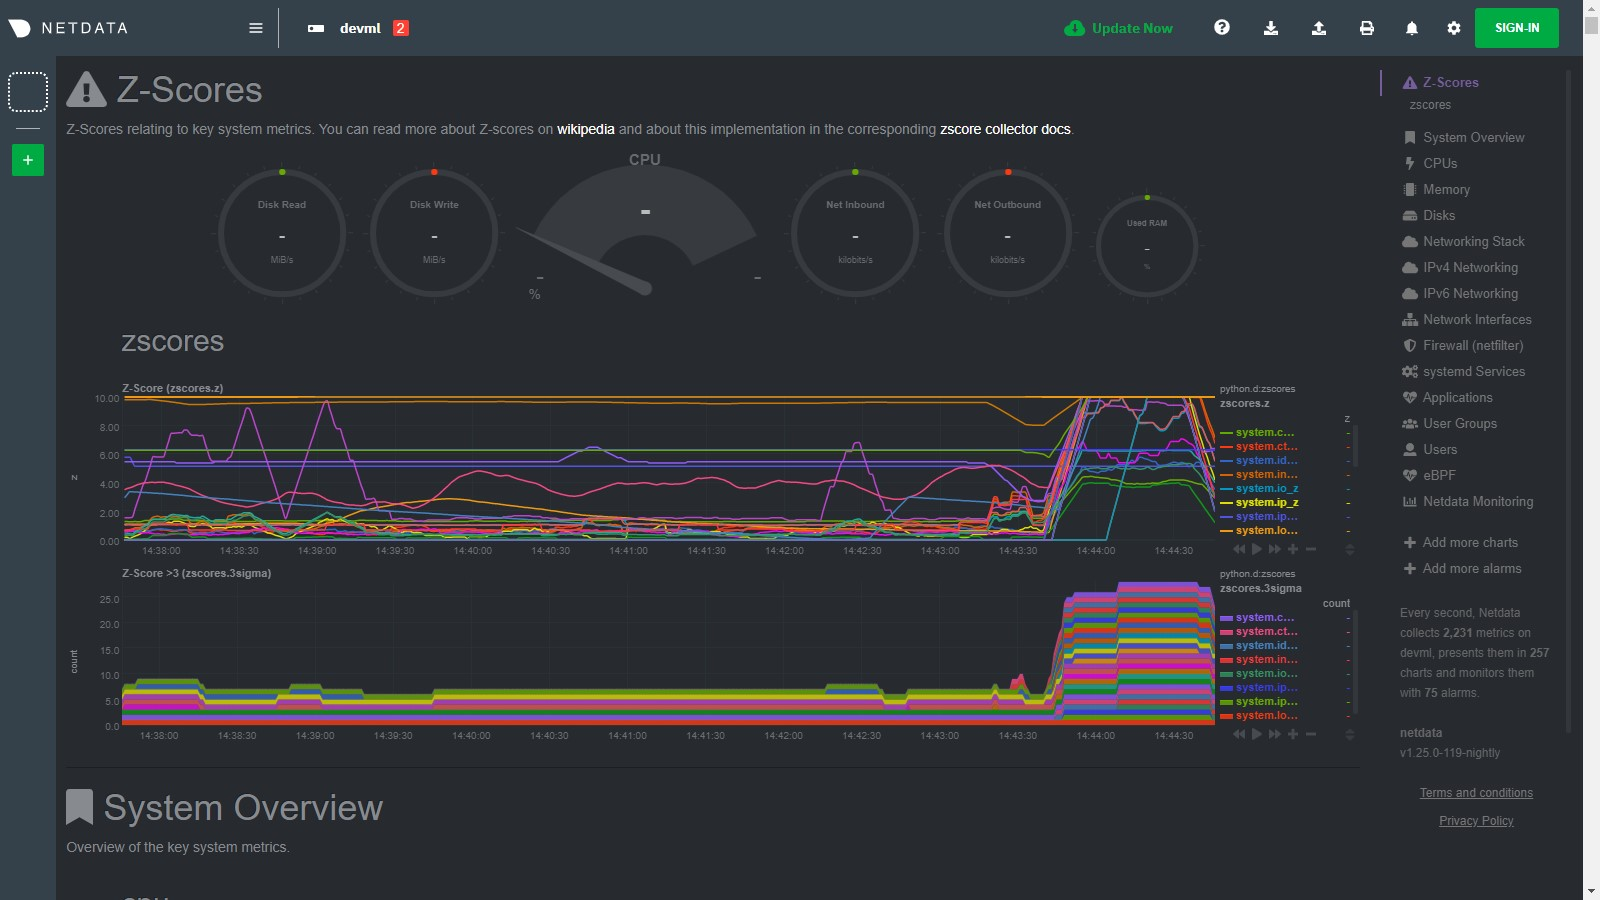
1
+# SPDX-License-Identifier: GPL-3.0-or-later
2
+
3
+# THIS IS NOT A COMPLETE Makefile
4
+# IT IS INCLUDED BY ITS PARENT'S Makefile.am
5
+# IT IS REQUIRED TO REFERENCE ALL FILES RELATIVE TO THE PARENT
6
+
7
+# install these files
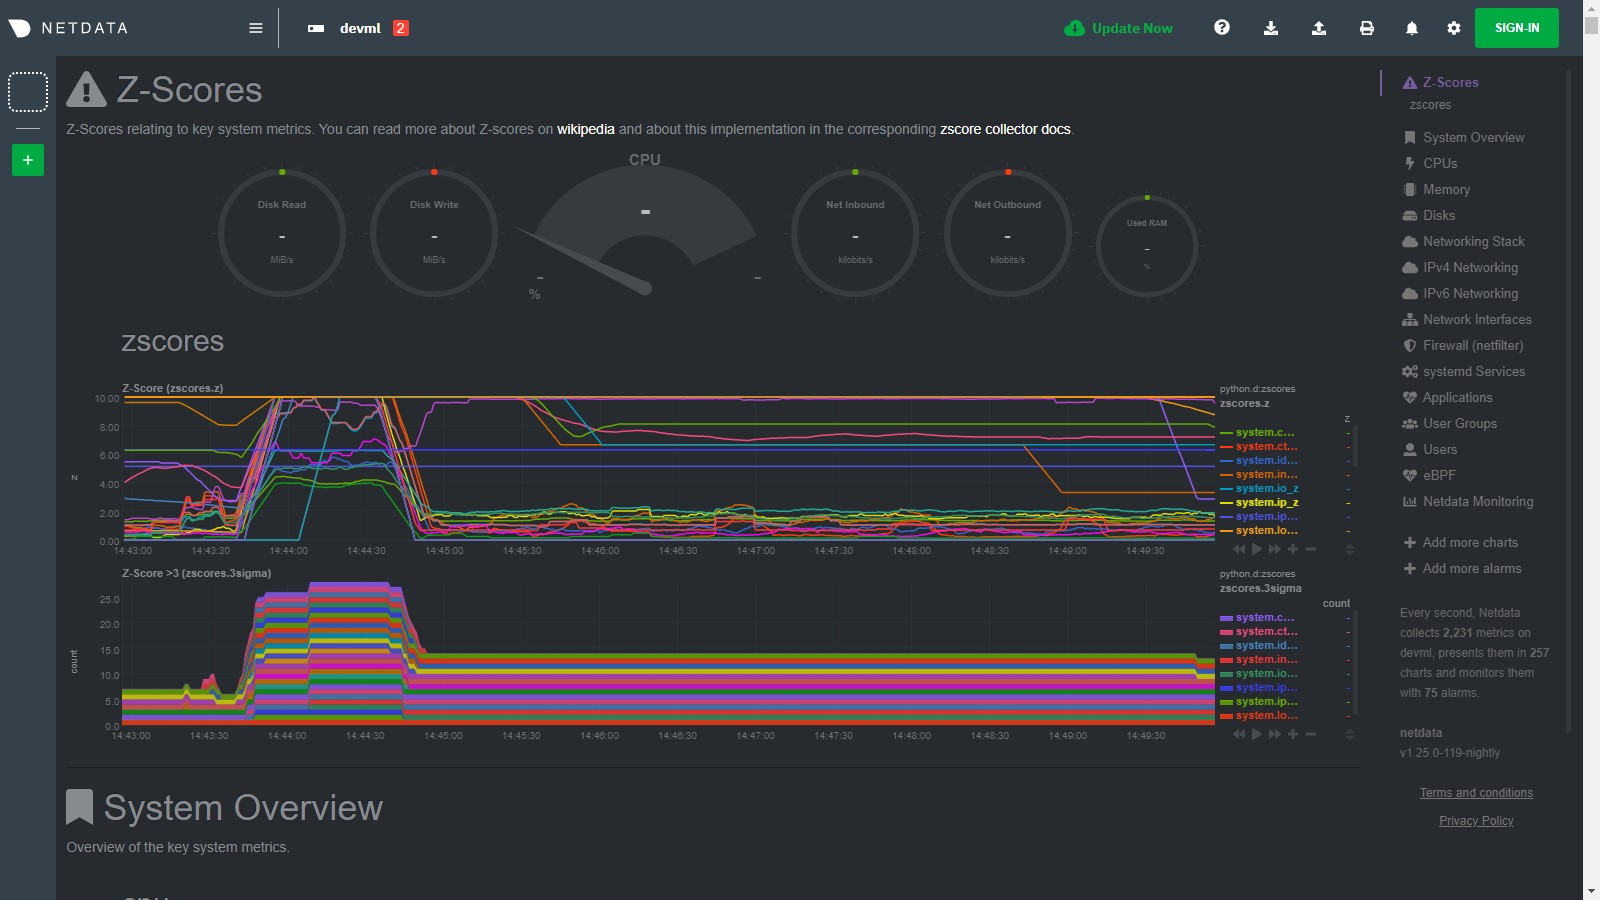
8
+dist_python_DATA += zscores/zscores.chart.py
9
+dist_pythonconfig_DATA += zscores/zscores.conf
10
+
11
+# do not install these files, but include them in the distribution
12
+dist_noinst_DATA += zscores/README.md zscores/Makefile.inc
collectors/python.d.plugin/zscores/README.md
new
+146
@@ -0,0 +1,146 @@
1
+<!--
2
+---
3
+title: "zscores"
4
+description: "Use statistical anomaly detection to narrow your focus and shorten root cause analysis."
5
+custom_edit_url: https://github.com/netdata/netdata/edit/master/collectors/python.d.plugin/zscores/README.md
6
+---
7
+-->
8
+
9
+# Z-Scores - basic anomaly detection for your key metrics and charts
10
+
11
+Smoothed, rolling [Z-Scores](https://en.wikipedia.org/wiki/Standard_score) for selected metrics or charts.
12
+
13
+This collector uses the [Netdata rest api](https://learn.netdata.cloud/docs/agent/web/api) to get the `mean` and `stddev`
14
+for each dimension on specified charts over a time range (defined by `train_secs` and `offset_secs`). For each dimension
15
+it will calculate a Z-Score as `z = (x - mean) / stddev` (clipped at `z_clip`). Scores are then smoothed over
16
+time (`z_smooth_n`) and, if `mode: 'per_chart'`, aggregated across dimensions to a smoothed, rolling chart level Z-Score
17
+at each time step.
18
+
19
+## Charts
20
+
21
+Two charts are produced:
22
+
23
+- **Z-Score** (`zscores.z`): This chart shows the calculated Z-Score per chart (or dimension if `mode='per_dim'`).
24
+- **Z-Score >3** (`zscores.3stddev`): This chart shows a `1` if the absolute value of the Z-Score is greater than 3 or
25
+ a `0` otherwise.
26
+
27
+Below is an example of the charts produced by this collector and a typical example of how they would look when things
28
+are 'normal' on the system. Most of the zscores tend to bounce randomly around a range typically between 0 to +3 (or -3
29
+to +3 if `z_abs: 'false'`), a few charts might stay steady at a more constant higher value depending on your
30
+configuration and the typical workload on your system (typically those charts that do not change that much have a
31
+smaller range of values on which to calculate a zscore and so tend to have a higher typical zscore).
32
+
33
+So really its a combination of the zscores values themselves plus, perhaps more importantly, how they change when
34
+something strange occurs on your system which can be most useful.
35
+
36
+
37
+
38
+For example, if we go onto the system and run a command
39
+like [`stress-ng --all 2`](https://wiki.ubuntu.com/Kernel/Reference/stress-ng) to create some stress, we see many charts
40
+begin to have zscores that jump outside the typical range. When the absolute zscore for a chart is greater than 3 you
41
+will see a corresponding line appear on the `zscores.3stddev` chart to make it a bit clearer what charts might be worth
42
+looking at first (for more background information on why 3 stddev
43
+see [here](https://en.wikipedia.org/wiki/68%E2%80%9395%E2%80%9399.7_rule#:~:text=In%20the%20empirical%20sciences%20the,99.7%25%20probability%20as%20near%20certainty.))
44
+.
45
+
46
+In the example below we basically took a sledge hammer to our system so its not suprising that lots of charts light up
47
+after we run the stress command. In a more realistic setting you might just see a handful of charts with strange zscores
48
+and that could be a good indication of where to look first.
49
+
50
+
51
+
52
+Then as the issue passes the zscores should settle back down into their normal range again as they are calculated in a
53
+rolling and smoothed way (as defined by your `zscores.conf` file).
54
+
55
+
56
+
57
+## Requirements
58
+
59
+This collector will only work with Python 3 and requires the below packages be installed.
60
+
61
+```bash
62
+# become netdata user
63
+sudo su -s /bin/bash netdata
64
+# install required packages
65
+pip3 install numpy pandas requests netdata-pandas==0.0.38
66
+```
67
+
68
+## Configuration
69
+
70
+Install the underlying Python requirements, Enable the collector and restart Netdata.
71
+
72
+```bash
73
+cd /etc/netdata/
74
+sudo ./edit-config python.d.conf
75
+# Set `zscores: no` to `zscores: yes`
76
+sudo systemctl restart netdata
77
+```
78
+
79
+The configuration for the zscores collector defines how it will behave on your system and might take some
80
+experimentation with over time to set it optimally. Out of the box, the config comes with
81
+some [sane defaults](https://www.netdata.cloud/blog/redefining-monitoring-netdata/) to get you started.
82
+
83
+If you are unsure about any of the below configuration options then it's best to just ignore all this and leave
84
+the `zscores.conf` files alone to begin with. Then you can return to it later if you would like to tune things a bit
85
+more once the collector is running for a while.
86
+
87
+Edit the `python.d/zscores.conf` configuration file using `edit-config` from the your
88
+agent's [config directory](https://learn.netdata.cloud/guides/step-by-step/step-04#find-your-netdataconf-file), which is
89
+usually at `/etc/netdata`.
90
+
91
+```bash
92
+cd /etc/netdata # Replace this path with your Netdata config directory, if different
93
+sudo ./edit-config python.d/zscores.conf
94
+```
95
+
96
+The default configuration should look something like this. Here you can see each parameter (with sane defaults) and some
97
+information about each one and what it does.
98
+
99
+```bash
100
+# what host to pull data from
101
+host: '127.0.0.1:19999'
102
+# What charts to pull data for - A regex like 'system\..*|' or 'system\..*|apps.cpu|apps.mem' etc.
103
+charts_regex: 'system\..*'
104
+# length of time to base calulcations off for mean and stddev
105
+train_secs: 14400 # use last 4 hours to work out the mean and stddev for the zscore
106
+# offset preceeding latest data to ignore when calculating mean and stddev
107
+offset_secs: 300 # ignore last 5 minutes of data when calculating the mean and stddev
108
+# recalculate the mean and stddev every n steps of the collector
109
+train_every_n: 900 # recalculate mean and stddev every 15 minutes
110
+# smooth the z score by averaging it over last n values
111
+z_smooth_n: 15 # take a rolling average of the last 15 zscore values to reduce sensitivity to temporary 'spikes'
112
+# cap absolute value of zscore (before smoothing) for better stability
113
+z_clip: 10 # cap each zscore at 10 so as to avoid really large individual zscores swamping any rolling average
114
+# set z_abs: 'true' to make all zscores be absolute values only.
115
+z_abs: 'true'
116
+# burn in period in which to initially calculate mean and stddev on every step
117
+burn_in: 2 # on startup of the collector continually update the mean and stddev in case any gaps or inital calculations fail to return
118
+# mode can be to get a zscore 'per_dim' or 'per_chart'
119
+mode: 'per_chart' # 'per_chart' means individual dimension level smoothed zscores will be aggregated to one zscore per chart per time step
120
+# per_chart_agg is how you aggregate from dimension to chart when mode='per_chart'
121
+per_chart_agg: 'mean' # 'absmax' will take the max absolute value accross all dimensions but will maintain the sign. 'mean' will just average.
122
+```
123
+
124
+## Notes
125
+
126
+- Python 3 is required as the [`netdata-pandas`](https://github.com/netdata/netdata-pandas) package uses python async
127
+ libraries ([asks](https://pypi.org/project/asks/) and [trio](https://pypi.org/project/trio/)) to make asynchronous
128
+ calls to the netdata rest api to get the required data for each chart when calculating the mean and stddev.
129
+- It may take a few hours or so for the collector to 'settle' into it's typical behaviour in terms of the scores you
130
+ will see in the normal running of your system.
131
+- The zscore you see for each chart when using `mode: 'per_chart'` as actually an aggregated zscore accross all the
132
+ dimensions on the underlying chart.
133
+- If you set `mode: 'per_dim'` then you will see a zscore for each dimension on each chart as opposed to one per chart.
134
+- As this collector does some calculations itself in python you may want to try it out first on a test or development
135
+ system to get a sense of its performance characteristics. Most of the work in calculating the mean and stddev will be
136
+ pushed down to the underlying Netdata C libraries via the rest api. But some data wrangling and calculations are then
137
+ done using [Pandas](https://pandas.pydata.org/) and [Numpy](https://numpy.org/) within the collector itself.
138
+- On a development n1-standard-2 (2 vCPUs, 7.5 GB memory) vm running Ubuntu 18.04 LTS and not doing any work some of the
139
+ typical performance characteristics we saw from running this collector were:
140
+ - A runtime (`netdata.runtime_zscores`) of ~50ms when doing scoring and ~500ms when recalculating the mean and
141
+ stddev.
142
+ - Typically 3%-3.5% cpu usage from scoring, jumping to ~35% for one second when recalculating the mean and stddev.
143
+ - About ~50mb of ram (`apps.mem`) being continually used by the `python.d.plugin`.
144
+- If you activate this collector on a fresh node, it might take a little while to build up enough data to calculate a
145
+ proper zscore. So until you actually have `train_secs` of available data the mean and stddev calculated will be subject
146
+ to more noise.
\ No newline at end of file
collectors/python.d.plugin/zscores/zscores.chart.py
new
+146
@@ -0,0 +1,146 @@
1
+# -*- coding: utf-8 -*-
2
+# Description: zscores netdata python.d module
3
+# Author: andrewm4894
4
+# SPDX-License-Identifier: GPL-3.0-or-later
5
+
6
+from datetime import datetime
7
+import re
8
+
9
+import requests
10
+import numpy as np
11
+import pandas as pd
12
+
13
+from bases.FrameworkServices.SimpleService import SimpleService
14
+from netdata_pandas.data import get_data, get_allmetrics
15
+
16
+priority = 60000
17
+update_every = 5
18
+disabled_by_default = True
19
+
20
+ORDER = [
21
+ 'z',
22
+ '3stddev'
23
+]
24
+
25
+CHARTS = {
26
+ 'z': {
27
+ 'options': ['z', 'Z Score', 'z', 'Z Score', 'z', 'line'],
28
+ 'lines': []
29
+ },
30
+ '3stddev': {
31
+ 'options': ['3stddev', 'Z Score >3', 'count', '3 Stddev', '3stddev', 'stacked'],
32
+ 'lines': []
33
+ },
34
+}
35
+
36
+
37
+class Service(SimpleService):
38
+ def __init__(self, configuration=None, name=None):
39
+ SimpleService.__init__(self, configuration=configuration, name=name)
40
+ self.host = self.configuration.get('host', '127.0.0.1:19999')
41
+ self.charts_regex = re.compile(self.configuration.get('charts_regex', 'system.*'))
42
+ self.charts_to_exclude = self.configuration.get('charts_to_exclude', '').split(',')
43
+ self.charts_in_scope = [
44
+ c for c in
45
+ list(filter(self.charts_regex.match,
46
+ requests.get(f'http://{self.host}/api/v1/charts').json()['charts'].keys()))
47
+ if c not in self.charts_to_exclude
48
+ ]
49
+ self.train_secs = self.configuration.get('train_secs', 14400)
50
+ self.offset_secs = self.configuration.get('offset_secs', 300)
51
+ self.train_every_n = self.configuration.get('train_every_n', 900)
52
+ self.z_smooth_n = self.configuration.get('z_smooth_n', 15)
53
+ self.z_clip = self.configuration.get('z_clip', 10)
54
+ self.z_abs = bool(self.configuration.get('z_abs', True))
55
+ self.burn_in = self.configuration.get('burn_in', 2)
56
+ self.mode = self.configuration.get('mode', 'per_chart')
57
+ self.per_chart_agg = self.configuration.get('per_chart_agg', 'mean')
58
+ self.order = ORDER
59
+ self.definitions = CHARTS
60
+ self.collected_dims = {'z': set(), '3stddev': set()}
61
+ self.df_mean = pd.DataFrame()
62
+ self.df_std = pd.DataFrame()
63
+ self.df_z_history = pd.DataFrame()
64
+
65
+ def check(self):
66
+ _ = get_allmetrics(self.host, self.charts_in_scope, wide=True, col_sep='.')
67
+ return True
68
+
69
+ def validate_charts(self, chart, data, algorithm='absolute', multiplier=1, divisor=1):
70
+ """If dimension not in chart then add it.
71
+ """
72
+ for dim in data:
73
+ if dim not in self.collected_dims[chart]:
74
+ self.collected_dims[chart].add(dim)
75
+ self.charts[chart].add_dimension([dim, dim, algorithm, multiplier, divisor])
76
+
77
+ for dim in list(self.collected_dims[chart]):
78
+ if dim not in data:
79
+ self.collected_dims[chart].remove(dim)
80
+ self.charts[chart].del_dimension(dim, hide=False)
81
+
82
+ def train_model(self):
83
+ """Calculate the mean and stddev for all relevant metrics and store them for use in calulcating zscore at each timestep.
84
+ """
85
+ before = int(datetime.now().timestamp()) - self.offset_secs
86
+ after = before - self.train_secs
87
+
88
+ self.df_mean = get_data(
89
+ self.host, self.charts_in_scope, after, before, points=10, group='average', col_sep='.'
90
+ ).mean().to_frame().rename(columns={0: "mean"})
91
+
92
+ self.df_std = get_data(
93
+ self.host, self.charts_in_scope, after, before, points=10, group='stddev', col_sep='.'
94
+ ).mean().to_frame().rename(columns={0: "std"})
95
+
96
+ def create_data(self, df_allmetrics):
97
+ """Use x, mean, stddev to generate z scores and 3stddev flags via some pandas manipulation.
98
+ Returning two dictionaries of dimensions and measures, one for each chart.
99
+
100
+ :param df_allmetrics <pd.DataFrame>: pandas dataframe with latest data from api/v1/allmetrics.
101
+ :return: (<dict>,<dict>) tuple of dictionaries, one for zscores and the other for a flag if abs(z)>3.
102
+ """
103
+ # calculate clipped z score for each available metric
104
+ df_z = pd.concat([self.df_mean, self.df_std, df_allmetrics], axis=1, join='inner')
105
+ df_z['z'] = ((df_z['value'] - df_z['mean']) / df_z['std']).clip(-self.z_clip, self.z_clip).fillna(0) * 100
106
+ if self.z_abs:
107
+ df_z['z'] = df_z['z'].abs()
108
+
109
+ # append last z_smooth_n rows of zscores to history table in wide format
110
+ self.df_z_history = self.df_z_history.append(
111
+ df_z[['z']].reset_index().pivot_table(values='z', columns='index'), sort=True
112
+ ).tail(self.z_smooth_n)
113
+
114
+ # get average zscore for last z_smooth_n for each metric
115
+ df_z_smooth = self.df_z_history.melt(value_name='z').groupby('index')['z'].mean().to_frame()
116
+ df_z_smooth['3stddev'] = np.where(abs(df_z_smooth['z']) > 300, 1, 0)
117
+ data_z = df_z_smooth['z'].add_suffix('_z').to_dict()
118
+
119
+ # aggregate to chart level if specified
120
+ if self.mode == 'per_chart':
121
+ df_z_smooth['chart'] = ['.'.join(x[0:2]) + '_z' for x in df_z_smooth.index.str.split('.').to_list()]
122
+ if self.per_chart_agg == 'absmax':
123
+ data_z = \
124
+ list(df_z_smooth.groupby('chart').agg({'z': lambda x: max(x, key=abs)})['z'].to_dict().values())[0]
125
+ else:
126
+ data_z = list(df_z_smooth.groupby('chart').agg({'z': [self.per_chart_agg]})['z'].to_dict().values())[0]
127
+
128
+ data_3stddev = {}
129
+ for k in data_z:
130
+ data_3stddev[k.replace('_z', '')] = 1 if abs(data_z[k]) > 300 else 0
131
+
132
+ return data_z, data_3stddev
133
+
134
+ def get_data(self):
135
+
136
+ if self.runs_counter <= self.burn_in or self.runs_counter % self.train_every_n == 0:
137
+ self.train_model()
138
+
139
+ data_z, data_3stddev = self.create_data(
140
+ get_allmetrics(self.host, self.charts_in_scope, wide=True, col_sep='.').transpose())
141
+ data = {**data_z, **data_3stddev}
142
+
143
+ self.validate_charts('z', data_z, divisor=100)
144
+ self.validate_charts('3stddev', data_3stddev)
145
+
146
+ return data
collectors/python.d.plugin/zscores/zscores.conf
new
+108
@@ -0,0 +1,108 @@
1
+# netdata python.d.plugin configuration for example
2
+#
3
+# This file is in YaML format. Generally the format is:
4
+#
5
+# name: value
6
+#
7
+# There are 2 sections:
8
+# - global variables
9
+# - one or more JOBS
10
+#
11
+# JOBS allow you to collect values from multiple sources.
12
+# Each source will have its own set of charts.
13
+#
14
+# JOB parameters have to be indented (using spaces only, example below).
15
+
16
+# ----------------------------------------------------------------------
17
+# Global Variables
18
+# These variables set the defaults for all JOBs, however each JOB
19
+# may define its own, overriding the defaults.
20
+
21
+# update_every sets the default data collection frequency.
22
+# If unset, the python.d.plugin default is used.
23
+update_every: 5
24
+
25
+# priority controls the order of charts at the netdata dashboard.
26
+# Lower numbers move the charts towards the top of the page.
27
+# If unset, the default for python.d.plugin is used.
28
+# priority: 60000
29
+
30
+# penalty indicates whether to apply penalty to update_every in case of failures.
31
+# Penalty will increase every 5 failed updates in a row. Maximum penalty is 10 minutes.
32
+# penalty: yes
33
+
34
+# autodetection_retry sets the job re-check interval in seconds.
35
+# The job is not deleted if check fails.
36
+# Attempts to start the job are made once every autodetection_retry.
37
+# This feature is disabled by default.
38
+# autodetection_retry: 0
39
+
40
+# ----------------------------------------------------------------------
41
+# JOBS (data collection sources)
42
+#
43
+# The default JOBS share the same *name*. JOBS with the same name
44
+# are mutually exclusive. Only one of them will be allowed running at
45
+# any time. This allows autodetection to try several alternatives and
46
+# pick the one that works.
47
+#
48
+# Any number of jobs is supported.
49
+#
50
+# All python.d.plugin JOBS (for all its modules) support a set of
51
+# predefined parameters. These are:
52
+#
53
+# job_name:
54
+# name: myname # the JOB's name as it will appear at the
55
+# # dashboard (by default is the job_name)
56
+# # JOBs sharing a name are mutually exclusive
57
+# update_every: 1 # the JOB's data collection frequency
58
+# priority: 60000 # the JOB's order on the dashboard
59
+# penalty: yes # the JOB's penalty
60
+# autodetection_retry: 0 # the JOB's re-check interval in seconds
61
+#
62
+# Additionally to the above, example also supports the following:
63
+#
64
+# - none
65
+#
66
+# ----------------------------------------------------------------------
67
+# AUTO-DETECTION JOBS
68
+# only one of them will run (they have the same name)
69
+
70
+local:
71
+ name: 'local'
72
+
73
+ # what host to pull data from
74
+ host: '127.0.0.1:19999'
75
+
76
+ # what charts to pull data for - A regex like 'system\..*|' or 'system\..*|apps.cpu|apps.mem' etc.
77
+ charts_regex: 'system\..*'
78
+
79
+ # Charts to exclude, useful if you would like to exclude some specific charts.
80
+ # Note: should be a ',' separated string like 'chart.name,chart.name'.
81
+ charts_to_exclude: 'system.uptime'
82
+
83
+ # length of time to base calculations off for mean and stddev
84
+ train_secs: 14400 # use last 4 hours to work out the mean and stddev for the zscore
85
+
86
+ # offset preceeding latest data to ignore when calculating mean and stddev
87
+ offset_secs: 300 # ignore last 5 minutes of data when calculating the mean and stddev
88
+
89
+ # recalculate the mean and stddev every n steps of the collector
90
+ train_every_n: 900 # recalculate mean and stddev every 15 minutes
91
+
92
+ # smooth the z score by averaging it over last n values
93
+ z_smooth_n: 15 # take a rolling average of the last 15 zscore values to reduce sensitivity to temporary 'spikes'
94
+
95
+ # cap absolute value of zscore (before smoothing) for better stability
96
+ z_clip: 10 # cap each zscore at 10 so as to avoid really large individual zscores swamping any rolling average
97
+
98
+ # set z_abs: 'true' to make all zscores be absolute values only.
99
+ z_abs: 'true'
100
+
101
+ # burn in period in which to initially calculate mean and stddev on every step
102
+ burn_in: 2 # on startup of the collector continually update the mean and stddev in case any gaps or inital calculations fail to return
103
+
104
+ # mode can be to get a zscore 'per_dim' or 'per_chart'
105
+ mode: 'per_chart' # 'per_chart' means individual dimension level smoothed zscores will be aggregated to one zscore per chart per time step
106
+
107
+ # per_chart_agg is how you aggregate from dimension to chart when mode='per_chart'
108
+ per_chart_agg: 'mean' # 'absmax' will take the max absolute value accross all dimensions but will maintain the sign. 'mean' will just average.
web/gui/dashboard_info.js
+7
@@ -607,6 +607,13 @@ netdataDashboard.menu = {
607
'A special <code>failed</code> state is available as well, which is very similar to <code>inactive</code> and is entered when the service failed in some way (process returned error code on exit, or crashed, an operation timed out, or after too many restarts). ' +
608
'For detailes, see <a href="https://www.freedesktop.org/software/systemd/man/systemd.html" target="_blank"> systemd(1)</a>.'
609
},
610
+
611
+ 'zscores': {
612
+ title: 'Z-Scores',
613
+ icon: '<i class="fas fa-exclamation"></i>',
614
+ info: 'Z scores scores relating to key system metrics.'
615
+ },
616
+
617
};
618
619