Add guide: Detect anomalies in nodes and applications with Netdata (#10451)
* Init new anomalies guide * Continuing work * Finish draft of part 1 * Tweak to opening * Change headline * Copyediting and fixes * Fix link * Remove with Netdata from title * Clean up frontmatter * Update docs/guides/monitor/anomaly-detection.md Co-authored-by: Andrew Maguire <andrewm4894@gmail.com> * Update docs/guides/monitor/anomaly-detection.md Co-authored-by: Andrew Maguire <andrewm4894@gmail.com> * Fixes for Jen * Fixes and improvements for Andy Co-authored-by: Andrew Maguire <andrewm4894@gmail.com>
Joel Hans committed
Jan 7, 2021 at 12:15 UTC
c4941b49274d82c2d9ee535a7fdaf932da2ebbf7
2 files changed
+193
-3
collectors/python.d.plugin/anomalies/README.md
+5
-3
@@ -1,15 +1,17 @@
1
<!--
2
-title: "Anomalies"
2
+title: "Anomaly detection with Netdata"
3
+description: "Use ML-driven anomaly detection to narrow your focus to only affected metrics and services/processes on your node to shorten root cause analysis."
4
custom_edit_url: https://github.com/netdata/netdata/edit/master/collectors/python.d.plugin/anomalies/README.md
5
+sidebar_url: anomalies
6
-->
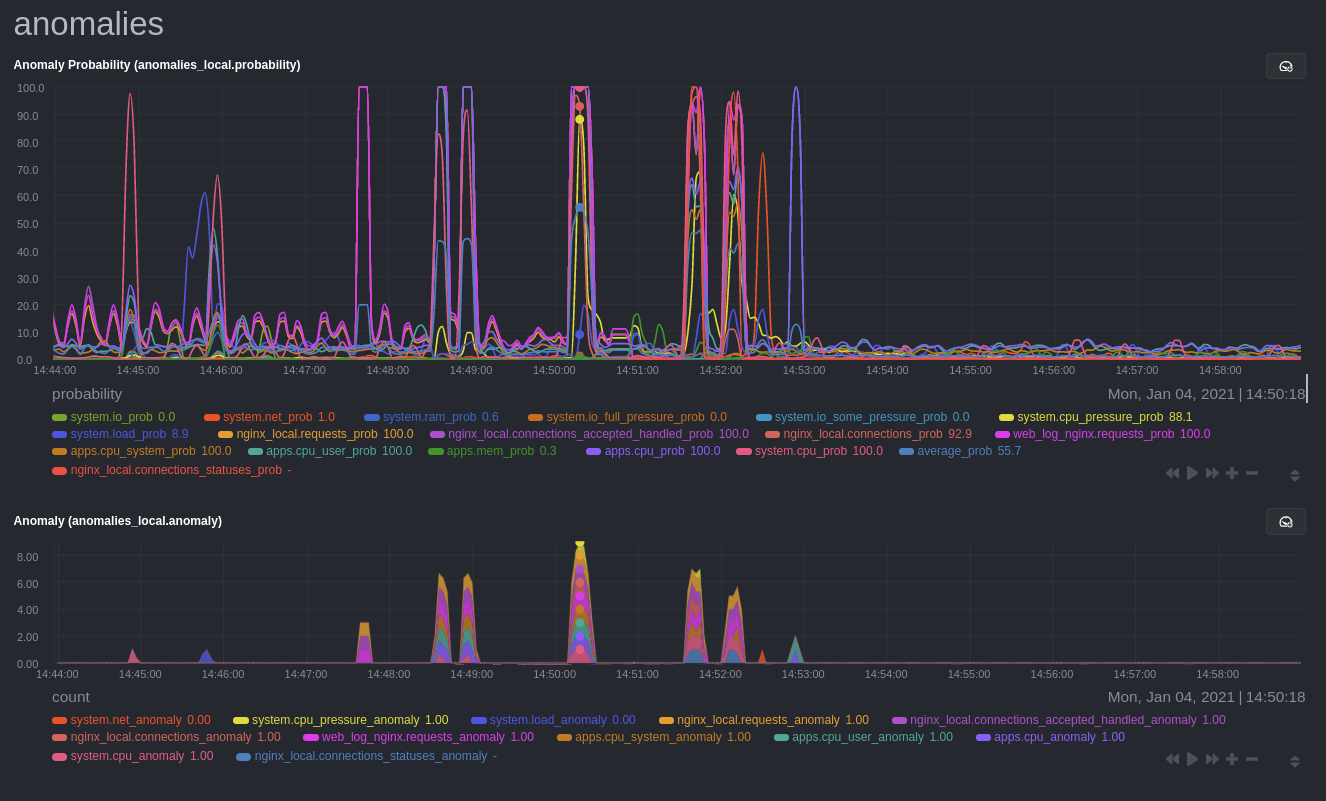
7
6
-# Anomalies: ML-driven anomaly detection for the Netdata Agent
8
+# Anomaly detection with Netdata
9
10
This collector uses the Python [PyOD](https://pyod.readthedocs.io/en/latest/index.html) library to perform unsupervised [anomaly detection](https://en.wikipedia.org/wiki/Anomaly_detection) on your Netdata charts and/or dimensions.
11
12
Instead of this collector just _collecting_ data, it also does some computation on the data it collects to return an anomaly probability and anomaly flag for each chart or custom model you define. This computation consists of a **train** function that runs every `train_n_secs` to train the ML models to learn what 'normal' typically looks like on your node. At each iteration there is also a **predict** function that uses the latest trained models and most recent metrics to produce an anomaly probability and anomaly flag for each chart or custom model you define.
13
12
-**Note**: As this is a somewhat unique collector and involves often subjective concepts like anomalies and anomaly probabilities, we would love to hear any feedback on it from the community. Please let us know on the [community forum](https://community.netdata.cloud/c/agent-development/9) or drop us a note at [analytics-ml-team@netdata.cloud](mailto:analytics-ml-team@netdata.cloud) for any and all feedback, both positive and negative. This sort of feedback is priceless to help us make complex features more useful.
14
+> As this is a somewhat unique collector and involves often subjective concepts like anomalies and anomaly probabilities, we would love to hear any feedback on it from the community. Please let us know on the [community forum](https://community.netdata.cloud/c/agent-development/9) or drop us a note at [analytics-ml-team@netdata.cloud](mailto:analytics-ml-team@netdata.cloud) for any and all feedback, both positive and negative. This sort of feedback is priceless to help us make complex features more useful.
15
16
## Charts
17
docs/guides/monitor/anomaly-detection.md
new
+188
@@ -0,0 +1,188 @@
1
+<!--
2
+title: "Detect anomalies in systems and applications"
3
+description: "Detect anomalies in any system, container, or application in your infrastructure with machine learning and the open-source Netdata Agent."
4
+image: /img/seo/guides/monitor/anomaly-detection.png
5
+custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/guides/monitor/anomaly-detection.md
6
+-->
7
+
8
+# Detect anomalies in systems and applications
9
+
10
+Beginning with v1.27, the [open-source Netdata Agent](https://github.com/netdata/netdata) is capable of unsupervised
11
+[anomaly detection](https://en.wikipedia.org/wiki/Anomaly_detection) with machine learning (ML). As with all things
12
+Netdata, the anomalies collector comes with preconfigured alarms and instant visualizations that require no query
13
+languages or organizing metrics. You configure the collector to look at specific charts, and it handles the rest.
14
+
15
+Netdata's implementation uses a handful of functions in the [Python Outlier Detection (PyOD)
16
+library](https://github.com/yzhao062/pyod/tree/master), which periodically runs a `train` function that learns what
17
+"normal" looks like on your node and creates an ML model for each chart, then utilizes the
18
+[`predict_proba()`](https://pyod.readthedocs.io/en/latest/api_cc.html#pyod.models.base.BaseDetector.predict_proba) and
19
+[`predict()`](https://pyod.readthedocs.io/en/latest/api_cc.html#pyod.models.base.BaseDetector.predict) PyOD functions to
20
+quantify how anomalous certain charts are.
21
+
22
+All these metrics and alarms are available for centralized monitoring in [Netdata Cloud](https://app.netdata.cloud). If
23
+you choose to sign up for Netdata Cloud and [claim your nodes](/claim/README.md), you will have the ability to run
24
+tailored anomaly detection on every node in your infrastructure, regardless of its purpose or workload.
25
+
26
+In this guide, you'll learn how to set up the anomalies collector to instantly detect anomalies in an Nginx web server
27
+and/or the node that hosts it, which will give you the tools to configure parallel unsupervised monitors for any
28
+application in your infrastructure. Let's get started.
29
+
30
+
32
+
33
+## Prerequisites
34
+
35
+- A node running the Netdata Agent. If you don't yet have that, [get Netdata](/docs/get/README.md).
36
+- A Netdata Cloud account. [Sign up](https://app.netdata.cloud) if you don't have one already.
37
+- Familiarity with configuring the Netdata Agent with [`edit-config`](/docs/configure/nodes.md).
38
+- _Optional_: An Nginx web server running on the same node to follow the example configuration steps.
39
+
40
+## Install required Python packages
41
+
42
+The anomalies collector uses a few Python packages, available with `pip3`, to run ML training. It requires
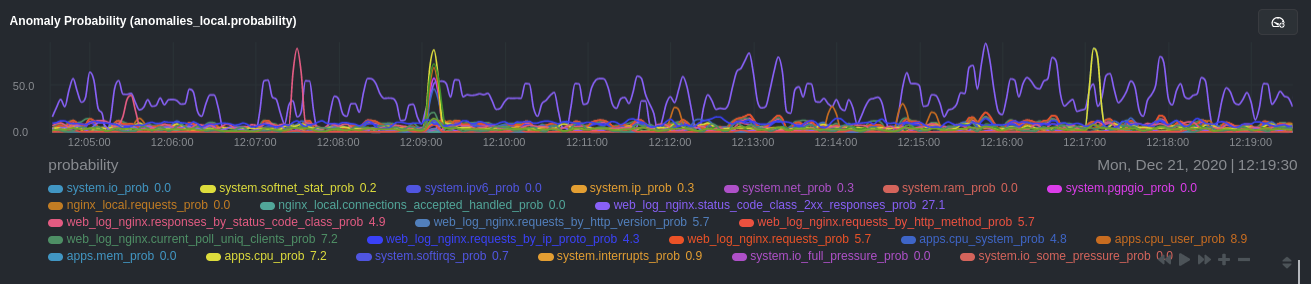
43
+[`numba`](http://numba.pydata.org/), [`scikit-learn`](https://scikit-learn.org/stable/),
44
+[`pyod`](https://pyod.readthedocs.io/en/latest/), in addition to
45
+[`netdata-pandas`](https://github.com/netdata/netdata-pandas), which is a package built by the Netdata team to pull data
46
+from a Netdata Agent's API into a [Pandas](https://pandas.pydata.org/). Read more about `netdata-pandas` on its [package
47
+repo](https://github.com/netdata/netdata-pandas) or in Netdata's [community
48
+repo](https://github.com/netdata/community/tree/main/netdata-agent-api/netdata-pandas).
49
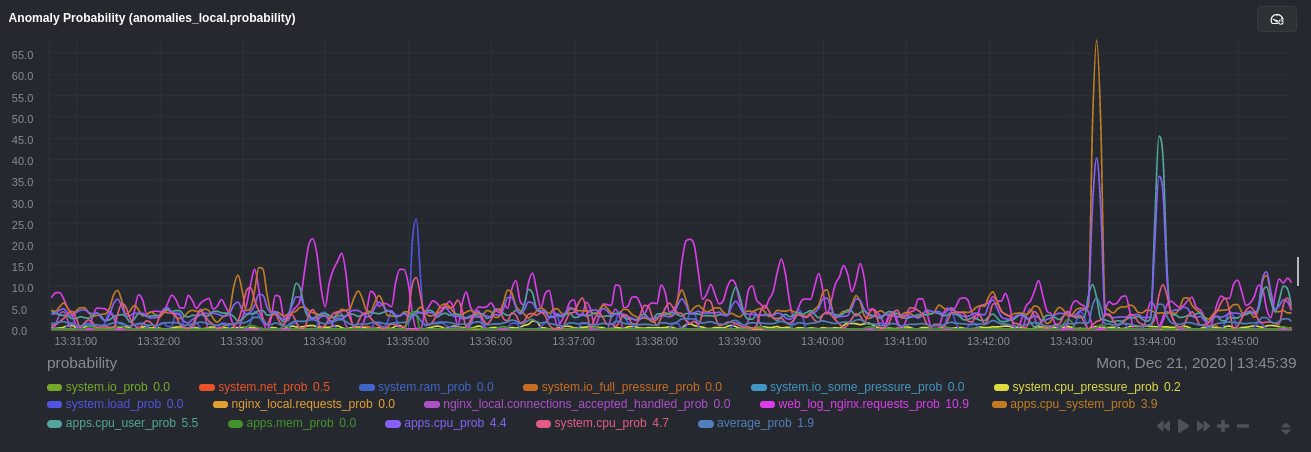
+
50
+```bash
51
+# Become the netdata user
52
+sudo su -s /bin/bash netdata
53
+
54
+# Install required packages for the netdata user
55
+pip3 install --user netdata-pandas==0.0.32 numba==0.50.1 scikit-learn==0.23.2 pyod==0.8.3
56
+```
57
+
58
+> If the `pip3` command fails, you need to install it. For example, on an Ubuntu system, use `sudo apt install
59
+> python3-pip`.
60
+
61
+Use `exit` to become your normal user again.
62
+
63
+## Enable the anomalies collector
64
+
65
+Navigate to your [Netdata config directory](/docs/configure/nodes.md#the-netdata-config-directory) and use `edit-config`
66
+to open the `python.d.conf` file.
67
+
68
+```bash
69
+sudo ./edit-config python.d.conf
70
+```
71
+
72
+In `python.d.conf` file, search for the `anomalies` line. If the line exists, set the value to `yes`. Add the line
73
+yourself if it doesn't already exist. Either way, the final result should look like:
74
+
75
+```conf
76
+anomalies: yes
77
+```
78
+
79
+[Restart the Agent](/docs/configure/start-stop-restart.md) with `sudo systemctl restart netdata` to start up the
80
+anomalies collector. By default, the model training process runs every 30 minutes, and uses the previous 4 hours of
81
+metrics to establish a baseline for health and performance across the default included charts.
82
+
83
+> 💡 The anomaly collector may need 30-60 seconds to finish its initial training and have enough data to start
84
+> generating anomaly scores. You may need to refresh your browser tab for the **Anomalies** section to appear in menus
85
+> on both the local Agent dashboard or Netdata Cloud.
86
+
87
+## Configure the anomalies collector
88
+
89
+Open `python.d/anomalies.conf` with `edit-conf`.
90
+
91
+```bash
92
+sudo ./edit-config python.d/anomalies.conf
93
+```
94
+
95
+The file contains many user-configurable settings with sane defaults. Here are some important settings that don't
96
+involve tweaking the behavior of the ML training itself.
97
+
98
+- `charts_regex`: Which charts to train models for and run anomaly detection on, with each chart getting a separate
99
+ model.
100
+- `charts_to_exclude`: Specific charts, selected by the regex in `charts_regex`, to exclude.
101
+- `train_every_n`: How often to train the ML models.
102
+- `train_n_secs`: The number of historical observations to train each model on. The default is 4 hours, but if your node
103
+ doesn't have historical metrics going back that far, consider [changing the metrics retention
104
+ policy](/docs/store/change-metrics-storage.md) or reducing this window.
105
+- `custom_models`: A way to define custom models that you want anomaly probabilities for, including multi-node or
106
+ streaming setups. More on custom models in part 3 of this guide series.
107
+
108
+> ⚠️ Setting `charts_regex` with many charts or `train_n_secs` to a very large number will have an impact on the
109
+> resources and time required to train a model for every chart. The actual performance implications depend on the
110
+> resources available on your node. If you plan on changing these settings beyond the default, or what's mentioned in
111
+> this guide, make incremental changes to observe the performance impact. Considering `train_max_n` to cap the number of
112
+> observations actually used to train on.
113
+
114
+### Run anomaly detection on Nginx and log file metrics
115
+
116
+As mentioned above, this guide uses an Nginx web server to demonstrate how the anomalies collector works. You must
117
+configure the collector to monitor charts from the
118
+[Nginx](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/nginx) and [web
119
+log](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/weblog) collectors.
120
+
121
+`charts_regex` allows for some basic regex, such as wildcards (`*`) to match all contexts with a certain pattern. For
122
+example, `system\..*` matches with any chart wit ha context that begins with `system.`, and ends in any number of other
123
+characters (`.*`). Note the escape character (`\`) around the first period to capture a period character exactly, and
124
+not any character.
125
+
126
+Change `charts_regex` in `anomalies.conf` to the following:
127
+
128
+```conf
129
+ charts_regex: 'system\..*|nginx_local\..*|web_log_nginx\..*|apps.cpu|apps.mem'
130
+```
131
+
132
+This value tells the anomaly collector to train against every `system.` chart, every `nginx_local` chart, every
133
+`web_log_nginx` chart, and specifically the `apps.cpu` and `apps.mem` charts.
134
+
135
+
137
+
138
+### Remove some metrics from anomaly detection
139
+
140
+As you can see in the above screenshot, this node is now looking for anomalies in many places. The result is a single
141
+`anomalies_local.probability` chart with more than twenty dimensions, some of which the dashboard hides at the bottom of
142
+a scroll-able area. In addition, training and analyzing the anomaly collector on many charts might require more CPU
143
+utilization that you're willing to give.
144
+
145
+First, explicitly declare which `system.` charts to monitor rather than of all of them using regex (`system\..*`).
146
+
147
+```conf
148
+ charts_regex: 'system\.cpu|system\.load|system\.io|system\.net|system\.ram|nginx_local\..*|web_log_nginx\..*|apps.cpu|apps.mem'
149
+```
150
+
151
+Next, remove some charts with the `charts_to_exclude` setting. For this example, using an Nginx web server, focus on the
152
+volume of requests/responses, not, for example, which type of 4xx response a user might receive.
153
+
154
+```conf
155
+ charts_to_exclude: 'web_log_nginx.excluded_requests,web_log_nginx.responses_by_status_code_class,web_log_nginx.status_code_class_2xx_responses,web_log_nginx.status_code_class_4xx_responses,web_log_nginx.current_poll_uniq_clients,web_log_nginx.requests_by_http_method,web_log_nginx.requests_by_http_version,web_log_nginx.requests_by_ip_proto'
156
+```
157
+
158
+
160
+
161
+Apply the ideas behind the collector's regex and exclude settings to any other
162
+[system](/docs/collect/system-metrics.md), [container](/docs/collect/container-metrics.md), or
163
+[application](/docs/collect/application-metrics.md) metrics you want to detect anomalies for.
164
+
165
+## What's next?
166
+
167
+Now that you know how to set up unsupervised anomaly detection in the Netdata Agent, using an Nginx web server as an
168
+example, it's time to apply that knowledge to other mission-critical parts of your infrastructure. If you're not sure
169
+what to monitor next, check out our list of [collectors](/collectors/COLLECTORS.md) to see what kind of metrics Netdata
170
+can collect from your systems, containers, and applications.
171
+
172
+For a more user-friendly anomaly detection experience, try out the [Metric
173
+Correlations](https://learn.netdata.cloud/docs/cloud/insights/metric-correlations) feature in Netdata Cloud. Metric
174
+Correlations runs only at your requests, removing unrelated charts from the dashboard to help you focus on root cause
175
+analysis.
176
+
177
+Stay tuned for the next two parts of this guide, which provide more real-world context for the anomalies collector.
178
+First, maximize the immediate value you get from anomaly detection by tracking preconfigured alarms, visualizing
179
+anomalies in charts, and building a new dashboard tailored to your applications. Then, learn about creating custom ML
180
+models, which help you holistically monitor an application or service by monitoring anomalies across a _cluster of
181
+charts_.
182
+
183
+### Related reference documentation
184
+
185
+- [Netdata Agent · Anomalies collector](/collectors/python.d.plugin/anomalies/README.md)
186
+- [Netdata Cloud · Metric Correlations](https://learn.netdata.cloud/docs/cloud/insights/metric-correlations)
187
+
188
+[](<>)