Add guide: Monitor and visualize anomalies with Netdata (#10480)
* Init new anomalies guide * Continuing work * Finish draft of part 1 * Tweak to opening * Change headline * Copyediting and fixes * Fix link * Remove with Netdata from title * Init new guide * Rename guide * Continue work on part 2 * Finish draft of part 2 * Editing pass * Fixes for Amy * Restore part 1 * Restore anomalies doc * Fixes for Jen
Joel Hans committed
Jan 13, 2021 at 16:57 UTC
cc2d4ffa7b6efb2226cf7d14024bc07eee82ab10
3 files changed
+151
-1
collectors/python.d.plugin/anomalies/README.md
+1
-1
@@ -2,7 +2,7 @@
2
title: "Anomaly detection with Netdata"
3
description: "Use ML-driven anomaly detection to narrow your focus to only affected metrics and services/processes on your node to shorten root cause analysis."
4
custom_edit_url: https://github.com/netdata/netdata/edit/master/collectors/python.d.plugin/anomalies/README.md
5
-sidebar_url: anomalies
5
+sidebar_url: Anomalies
6
-->
7
8
# Anomaly detection with Netdata
docs/guides/monitor/anomaly-detection.md
+3
@@ -2,6 +2,9 @@
2
title: "Detect anomalies in systems and applications"
3
description: "Detect anomalies in any system, container, or application in your infrastructure with machine learning and the open-source Netdata Agent."
4
image: /img/seo/guides/monitor/anomaly-detection.png
5
+author: "Joel Hans"
6
+author_title: "Editorial Director, Technical & Educational Resources"
7
+author_img: "/img/authors/joel-hans.jpg"
8
custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/guides/monitor/anomaly-detection.md
9
-->
10
docs/guides/monitor/visualize-monitor-anomalies.md
new
+147
@@ -0,0 +1,147 @@
1
+<!--
2
+title: "Monitor and visualize anomalies with Netdata (part 2)"
3
+description: "Using unsupervised anomaly detection and machine learning, get notified "
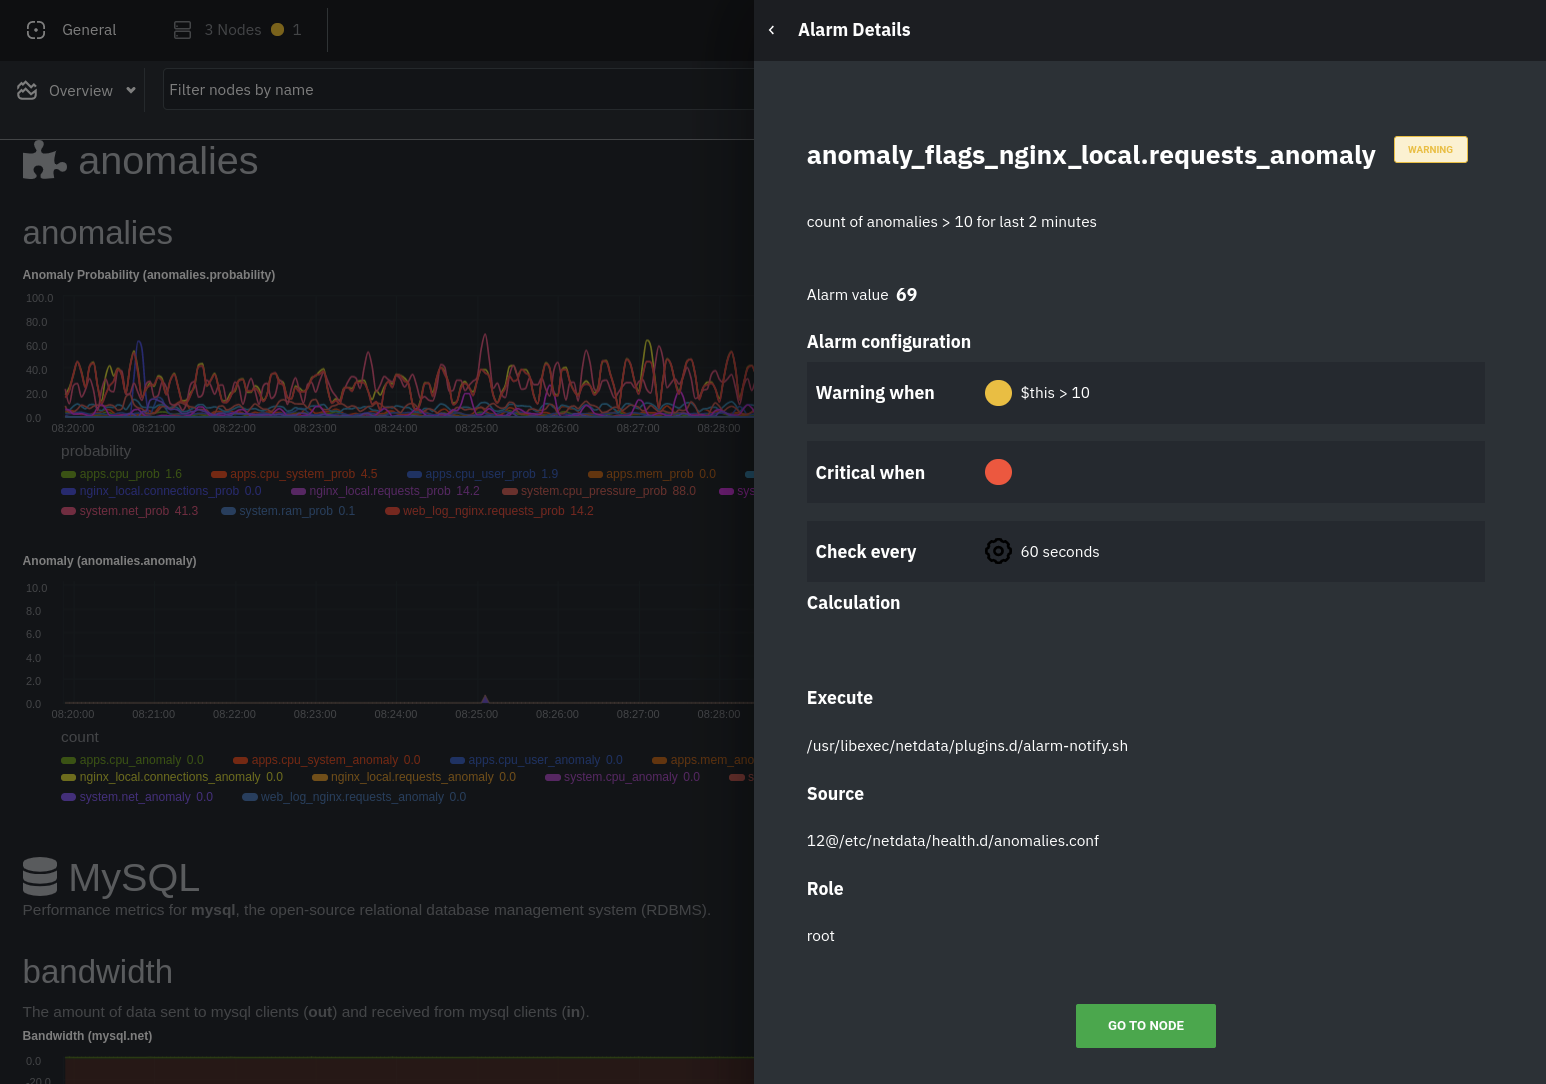
4
+image: /img/seo/guides/monitor/visualize-monitor-anomalies.png
5
+author: "Joel Hans"
6
+author_title: "Editorial Director, Technical & Educational Resources"
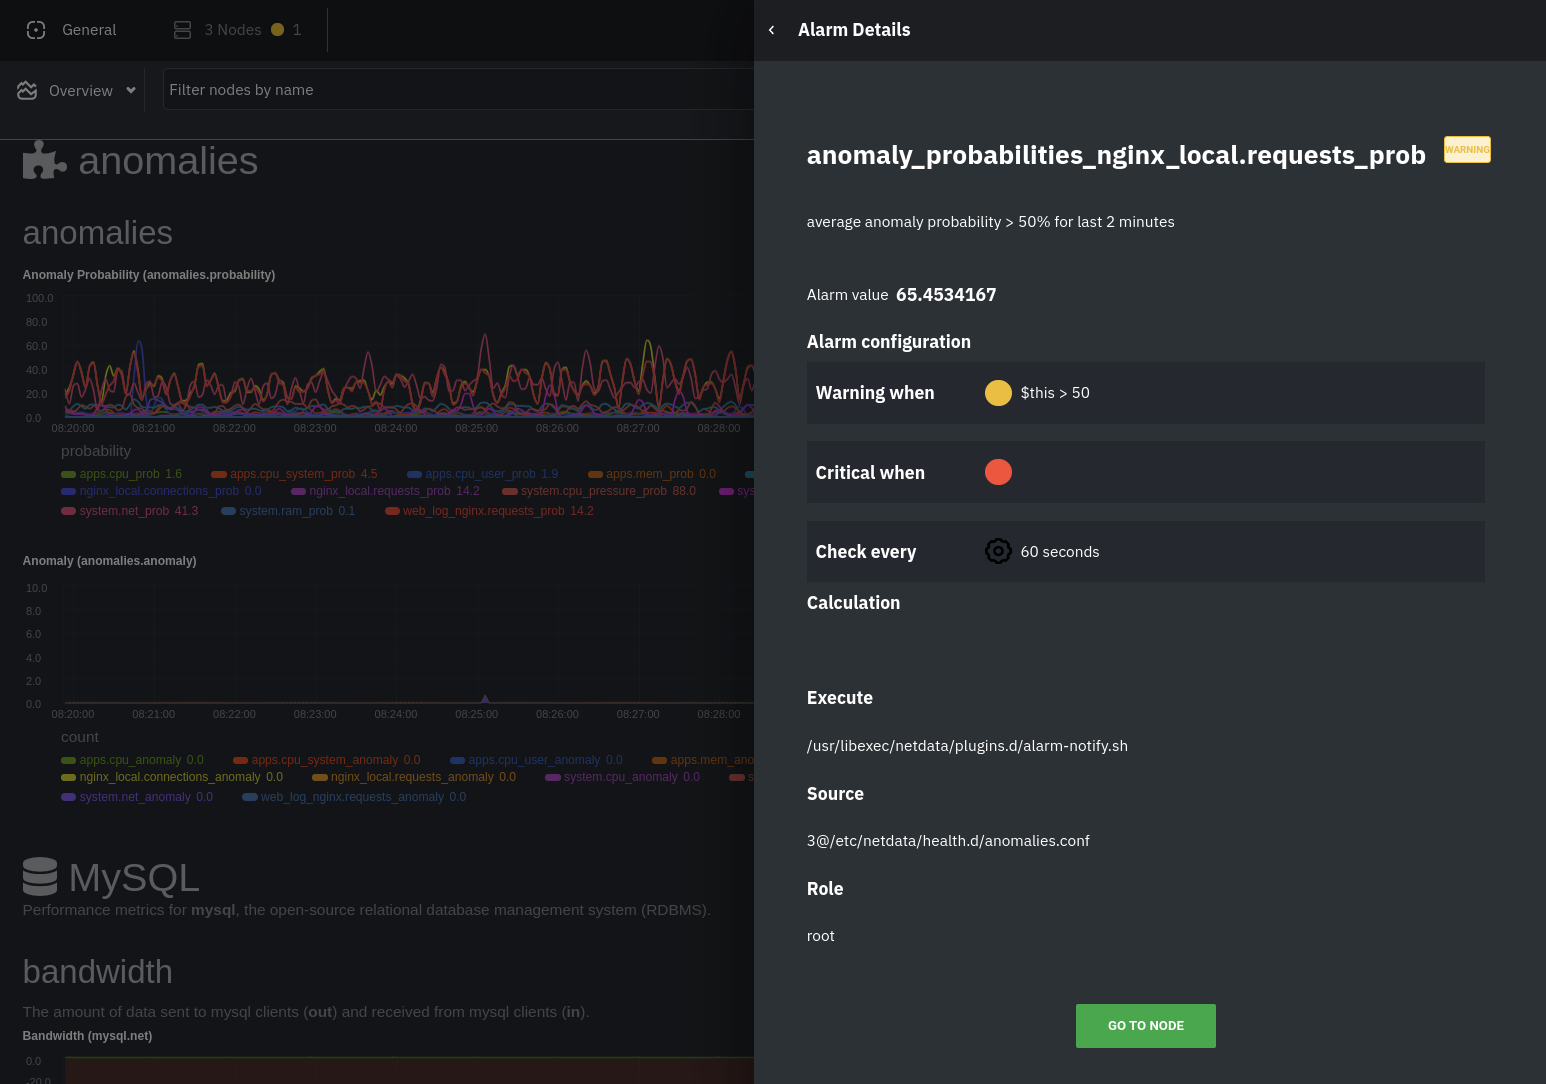
7
+author_img: "/img/authors/joel-hans.jpg"
8
+custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/guides/monitor/visualize-monitor-anomalies.md
9
+-->
10
+
11
+# Monitor and visualize anomalies with Netdata (part 2)
12
+
13
+Welcome to part 2 of our series of guides on using _unsupervised anomaly detection_ to detect issues with your systems,
14
+containers, and applications using the open-source Netdata Agent. For an introduction to detecting anomalies and
15
+monitoring associated metrics, see [part 1](/docs/guides/monitor/anomaly-detection.md), which covers prerequisites and
16
+configuration basics.
17
+
18
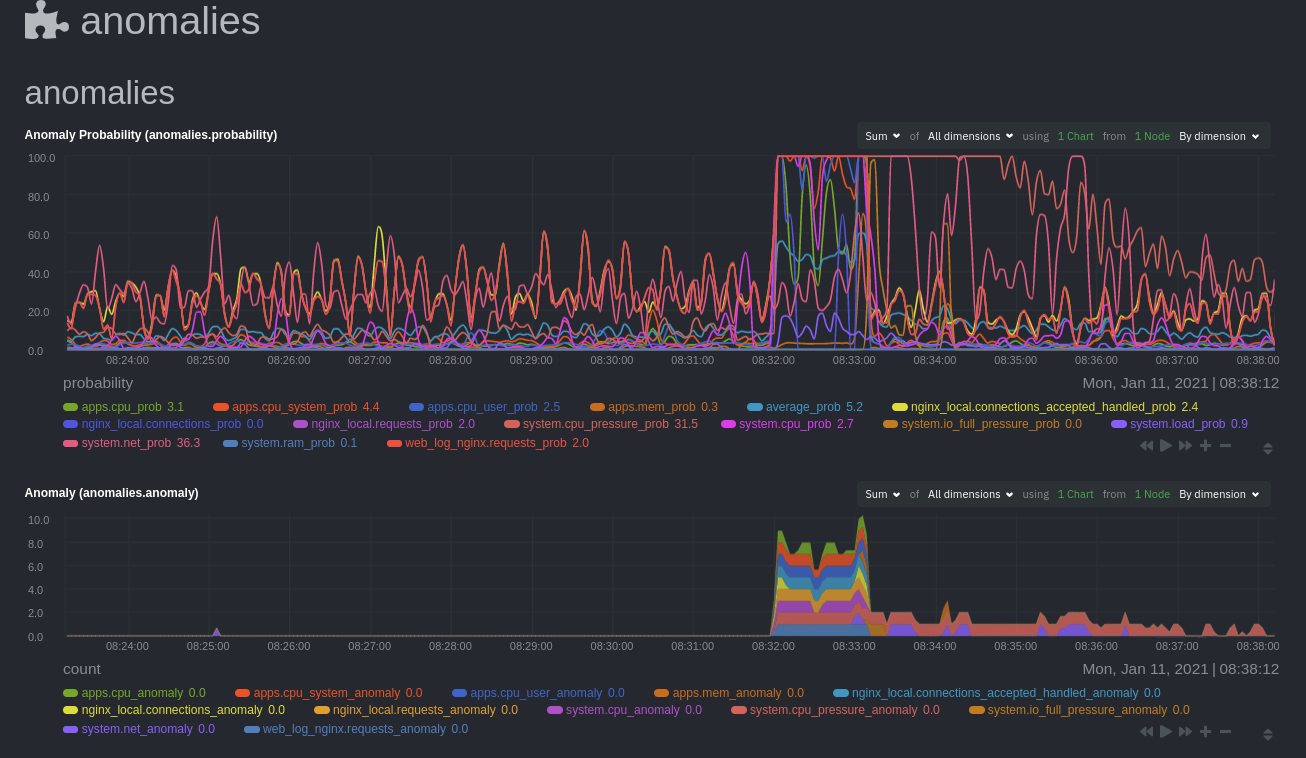
+With anomaly detection in the Netdata Agent set up, you will now want to visualize and monitor which charts have
19
+anomalous data, when, and where to look next.
20
+
21
+> 💡 In certain cases, the anomalies collector doesn't start immediately after restarting the Netdata Agent. If this
22
+> happens, you won't see the dashboard section or the relevant [charts](#visualize-anomalies-in-charts) right away. Wait
23
+> a minute or two, refresh, and look again. If the anomalies charts and alarms are still not present, investigate the
24
+> error log with `less /var/log/netdata/error.log | grep anomalies`.
25
+
26
+## Test anomaly detection
27
+
28
+Time to see the Netdata Agent's unsupervised anomaly detection in action. To trigger anomalies on the Nginx web server,
29
+use `ab`, otherwise known as [Apache Bench](https://httpd.apache.org/docs/2.4/programs/ab.html). Despite its name, it
30
+works just as well with Nginx web servers. Install it on Ubuntu/Debian systems with `sudo apt install apache2-utils`.
31
+
32
+> 💡 If you haven't followed the guide's example of using Nginx, an easy way to test anomaly detection on your node is
33
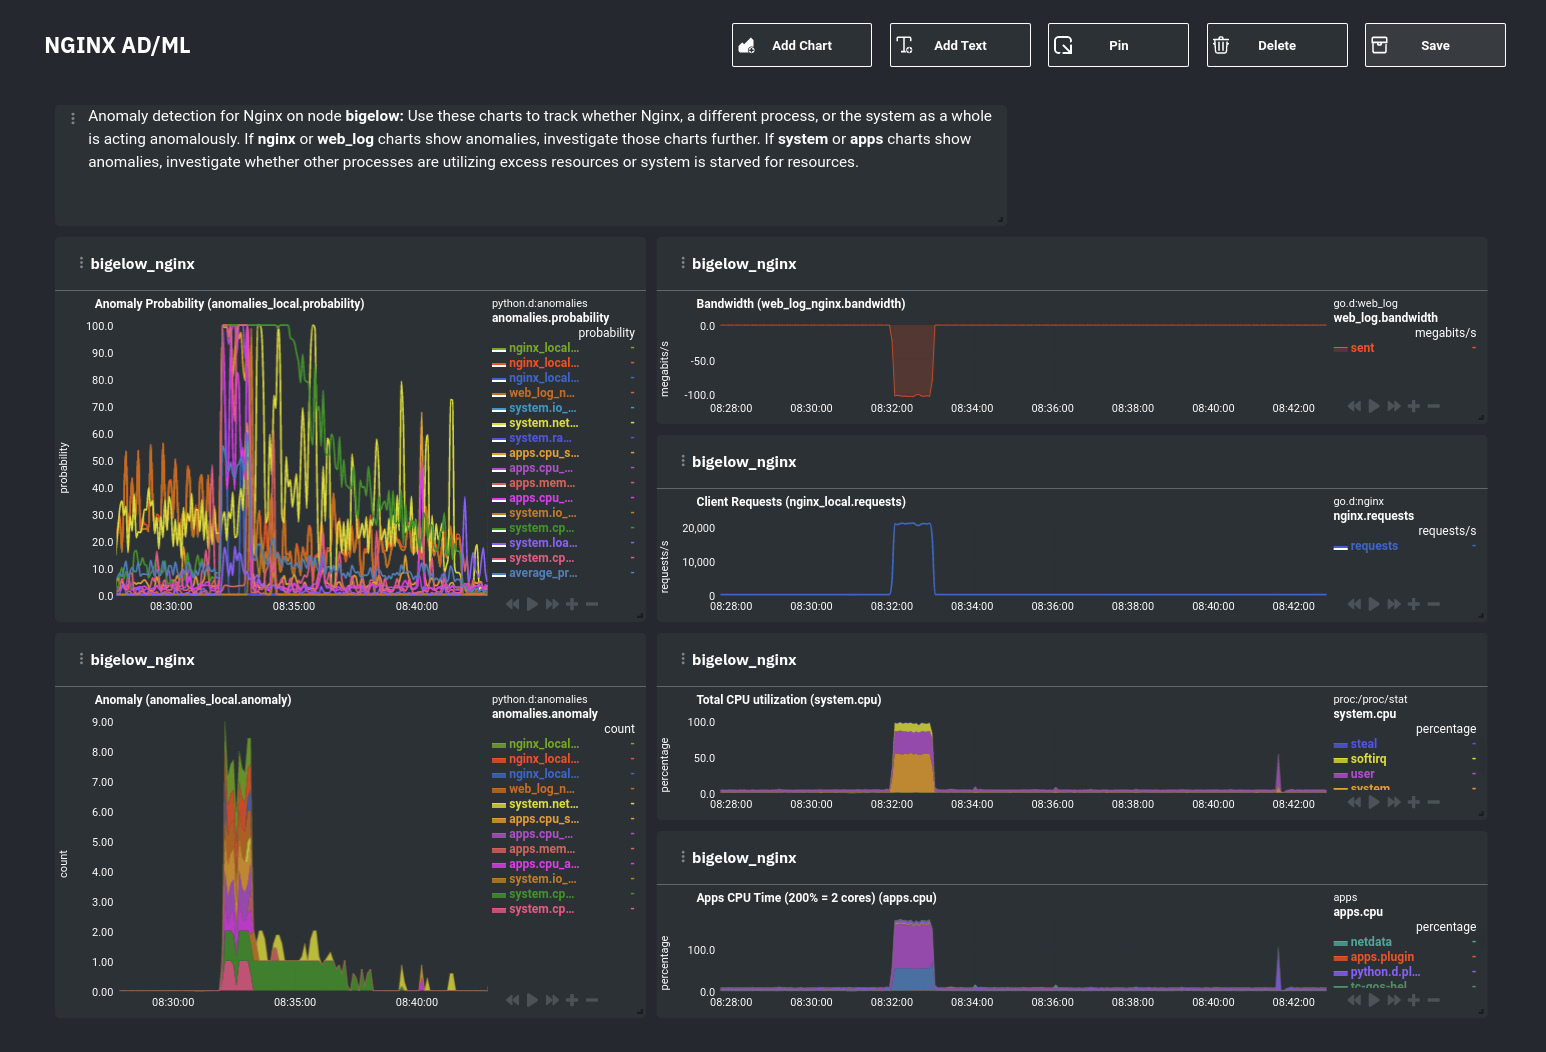
+> to use the `stress-ng` command, which is available on most Linux distributions. Run `stress-ng --cpu 0` to create CPU
34
+> stress or `stress-ng --vm 0` for RAM stress. Each test will cause some "collateral damage," in that you may see CPU
35
+> utilization rise when running the RAM test, and vice versa.
36
+
37
+The following test creates a minimum of 10,000,000 requests for Nginx to handle, with a maximum of 10 at any given time,
38
+with a run time of 60 seconds. If your system can handle those 10,000,000 in less than 60 seconds, `ab` will keep
39
+sending requests until the timer runs out.
40
+
41
+```bash
42
+ab -k -c 10 -t 60 -n 10000000 http://127.0.0.1/
43
+```
44
+
45
+Let's see how Netdata detects this anomalous behavior and propagates information to you through preconfigured alarms and
46
+dashboards that automatically organize anomaly detection metrics into meaningful charts to help you begin root cause
47
+analysis (RCA).
48
+
49
+## Monitor anomalies with alarms
50
+
51
+The anomalies collector creates two "classes" of alarms for each chart captured by the `charts_regex` setting. All these
52
+alarms are preconfigured based on your [configuration in
53
+`anomalies.conf`](/docs/guides/monitor/anomaly-detection.md#configure-the-anomalies-collector). With the `charts_regex`
54
+and `charts_to_exclude` settings from [part 1](/docs/guides/monitor/anomaly-detection.md) of this guide series, the
55
+Netdata Agent creates 32 alarms driven by unsupervised anomaly detection.
56
+
57
+The first class triggers warning alarms when the average anomaly probability for a given chart has stayed above 50% for
58
+at least the last two minutes.
59
+
60
+
62
+
63
+The second class triggers warning alarms when the number of anomalies in the last two minutes hits 10 or higher.
64
+
65
+
67
+
68
+If you see either of these alarms in Netdata Cloud, the local Agent dashboard, or on your preferred notification
69
+platform, it's a safe bet that the node's current metrics have deviated from normal. That doesn't necessarily mean
70
+there's a full-blown incident, depending on what application/service you're using anomaly detection on, but it's worth
71
+further investigation.
72
+
73
+As you use the anomalies collector, you may find that the default settings provide too many or too few genuine alarms.
74
+In this case, [configure the alarm](/docs/monitor/configure-alarms.md) with `sudo ./edit-config
75
+health.d/anomalies.conf`. Take a look at the `lookup` line syntax in the [health
76
+reference](/health/REFERENCE.md#alarm-line-lookup) to understand how the anomalies collector automatically creates
77
+alarms for any dimension on the `anomalies_local.probability` and `anomalies_local.anomaly` charts.
78
+
79
+## Visualize anomalies in charts
80
+
81
+In either [Netdata Cloud](https://app.netdata.cloud) or the local Agent dashboard at `http://NODE:19999`, click on the
82
+**Anomalies** [section](/web/gui/README.md#sections) to see the pair of anomaly detection charts, which are
83
+preconfigured to visualize per-second anomaly metrics based on your [configuration in
84
+`anomalies.conf`](/docs/guides/monitor/anomaly-detection.md#configure-the-anomalies-collector).
85
+
86
+These charts have the contexts `anomalies.probability` and `anomalies.anomaly`. Together, these charts
87
+create meaningful visualizations for immediately recognizing not only that something is going wrong on your node, but
88
+give context as to where to look next.
89
+
90
+The `anomalies_local.probability` chart shows the probability that the latest observed data is anomalous, based on the
91
+trained model. The `anomalies_local.anomaly` chart visualizes 0→1 predictions based on whether the latest observed
92
+data is anomalous based on the trained model. Both charts share the same dimensions, which you configured via
93
+`charts_regex` and `charts_to_exclude` in [part 1](/docs/guides/monitor/anomaly-detection.md).
94
+
95
+In other words, the `probability` chart shows the amplitude of the anomaly, whereas the `anomaly` chart provides quick
96
+yes/no context.
97
+
98
+
100
+
101
+Before `08:32:00`, both charts show little in the way of verified anomalies. Based on the metrics the anomalies
102
+collector has trained on, a certain percentage of anomaly probability score is normal, as seen in the
103
+`web_log_nginx_requests_prob` dimension and a few others. What you're looking for is large deviations from the "noise"
104
+in the `anomalies.probability` chart, or any increments to the `anomalies.anomaly` chart.
105
+
106
+Unsurprisingly, the stress test that began at `08:32:00` caused significant changes to these charts. The three
107
+dimensions that immediately shot to 100% anomaly probability, and remained there during the test, were
108
+`web_log_nginx.requests_prob`, `nginx_local.connections_accepted_handled_prob`, and `system.cpu_pressure_prob`.
109
+
110
+## Build an anomaly detection dashboard
111
+
112
+[Netdata Cloud](https://app.netdata.cloud) features a drag-and-drop [dashboard
113
+editor](/docs/visualize/create-dashboards.md) that helps you create entirely new dashboards with charts targeted for
114
+your specific applications.
115
+
116
+For example, here's a dashboard designed for visualizing anomalies present in an Nginx web server, including
117
+documentation about why the dashboard exists and where to look next based on what you're seeing:
118
+
119
+
121
+
122
+Use the anomaly charts for instant visual identification of potential anomalies, and then Nginx-specific charts, in the
123
+right column, to validate whether the probability and anomaly counters are showing a valid incident worth further
124
+investigation using [Metric Correlations](https://learn.netdata.cloud/docs/cloud/insights/metric-correlations) to narrow
125
+the dashboard into only the charts relevant to what you're seeing from the anomalies collector.
126
+
127
+## What's next?
128
+
129
+Between this guide and [part 1](/docs/guides/monitor/anomaly-detection.md), which covered setup and configuration, you
130
+now have a fundamental understanding of how unsupervised anomaly detection in Netdata works, from root cause to alarms
131
+to preconfigured or custom dashboards.
132
+
133
+We'd love to hear your feedback on the anomalies collector. Hop over to the [community
134
+forum](https://community.netdata.cloud/c/agent-development/9), and let us know if you're already getting value from
135
+unsupervised anomaly detection, or would like to see something added to it. You might even post a custom configuration
136
+that works well for monitoring some other popular application, like MySQL, PostgreSQL, Redis, or anything else we
137
+[support through collectors](/collectors/COLLECTORS.md).
138
+
139
+In part 3 of this series on unsupervised anomaly detection using Netdata, we'll create a custom model to apply
140
+unsupervised anomaly detection to an entire mission-critical application. Stay tuned!
141
+
142
+### Related reference documentation
143
+
144
+- [Netdata Agent · Anomalies collector](/collectors/python.d.plugin/anomalies/README.md)
145
+- [Netdata Cloud · Build new dashboards](https://learn.netdata.cloud/docs/cloud/visualize/dashboards)
146
+
147
+[](<>)