Tutorials to support v1.18 features (#6993)
* Tweaks to metrics storage for dbengine default * More work on tutorials * Finished draft of hdfs/zookeeper tutorial * A few tweaks to tutorials * Tweaks to dbengine text * Addressing comments from Ilya and Thiago * Fixing links * Changed dbengine retention and alarm numbers
Joel Hans committed
Oct 10, 2019 at 07:43 UTC
cc38b9ded4004562b06ed72bb22660cf74c802d2
4 files changed
+390
-24
docs/getting-started.md
+5
-6
@@ -159,14 +159,13 @@ Find the `SEND_EMAIL="YES"` line and change it to `SEND_EMAIL="NO"`.
159
160
## Change how long Netdata stores metrics
161
162
-By default, Netdata stores 1 hour of historical metrics and uses about 25MB of RAM.
162
+By default, Netdata uses a database engine uses RAM to store recent metrics. For long-term metrics storage, the database
163
+engine uses a "spill to disk" feature that also takes advantage of available disk space and keeps RAM usage low.
164
164
-If that's not enough for you, Netdata is quite adaptable to long-term storage of your system's metrics.
165
+The database engine allows you to store a much larger dataset than your system's available RAM.
166
166
-There are two quick ways to increase the depth of historical metrics: increase the `history` value for the round-robin
167
-that's enabled by default, or switch to the database engine.
168
-
169
-We have a tutorial that walks you through both options: [**Changing how long Netdata stores
167
+If you're not sure whether you're using the database engine, or want to tweak the default settings to store even more
168
+historical metrics, check out our tutorial: [**Changing how long Netdata stores
169
metrics**](../docs/tutorials/longer-metrics-storage.md).
170
171
**What's next?**:
docs/tutorials/dimension-templates.md
new
+169
@@ -0,0 +1,169 @@
1
+# Use dimension templates to create dynamic alarms
2
+
3
+Your ability to monitor the health of your systems and applications relies on your ability to create and maintain
4
+the best set of alarms for your particular needs.
5
+
6
+In v1.18 of Netdata, we introduced **dimension templates** for alarms, which simplifies the process of writing [alarm
7
+entities](../../health/README.md#entities-in-the-health-files) for charts with many dimensions.
8
+
9
+Dimension templates can condense many individual entities into one—no more copy-pasting one entity and changing the
10
+`alarm`/`template` and `lookup` lines for each dimension you'd like to monitor.
11
+
12
+They are, however, an advanced health monitoring feature. For more basic instructions on creating your first alarm,
13
+check out our [health monitoring documentation](../../health/), which also includes
14
+[examples](../../health/README.md#examples).
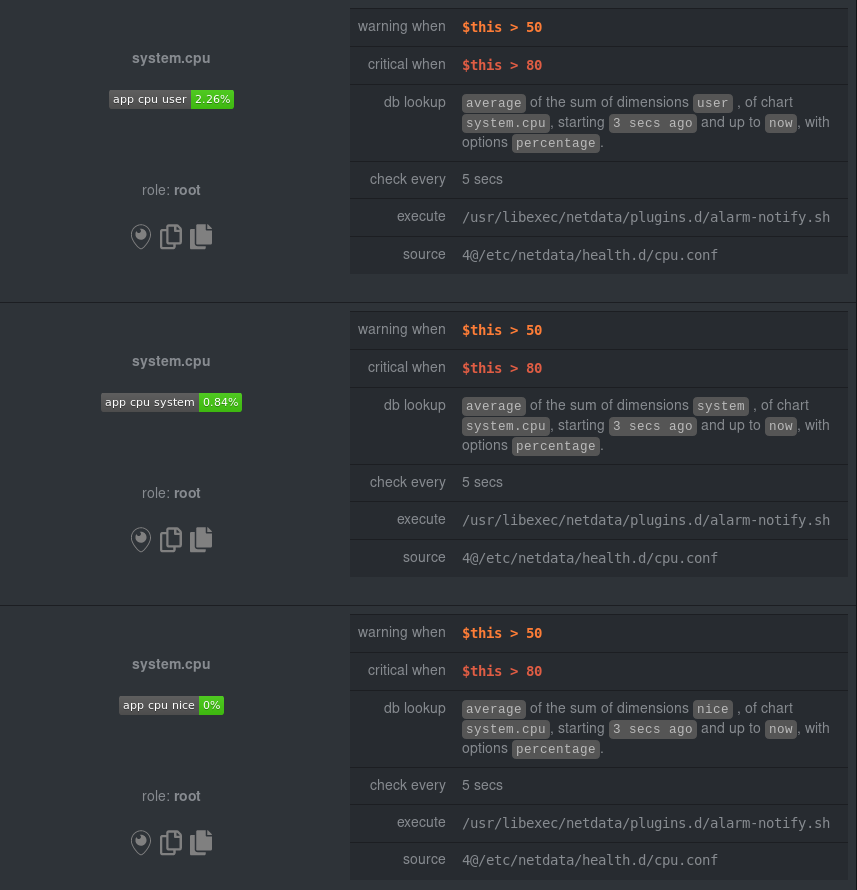
15
+
16
+## The fundamentals of `foreach`
17
+
18
+Our dimension templates update creates a new `foreach` parameter to the existing [`lookup`
19
+line](../../health/README.md#alarm-line-lookup). This is where the magic happens.
20
+
21
+You use the `foreach` parameter to specify which dimensions you want to monitor with this single alarm. You can separate
22
+them with a comma (`,`) or a pipe (`|`). You can also use a [Netdata simple pattern](../../libnetdata/simple_pattern/README.md)
23
+to create many alarms with a regex-like syntax.
24
+
25
+The `foreach` parameter _has_ to be the last parameter in your `lookup` line, and if you have both `of` and `foreach` in
26
+the same `lookup` line, Netdata will ignore the `of` parameter and use `foreach` instead.
27
+
28
+Let's get into some examples so you can see how the new parameter works.
29
+
30
+> ⚠️ The following entities are examples to showcase the functionality and syntax of dimension templates. They are not
31
+> meant to be run as-is on production systems.
32
+
33
+## Condensing entities with `foreach`
34
+
35
+Let's say you want to monitor the `system`, `user`, and `nice` dimensions in your system's overall CPU utilization.
36
+Before dimension templates, you would need the following three entities:
37
+
38
+```yaml
39
+ alarm: cpu_system
40
+ on: system.cpu
41
+lookup: average -10m percentage of system
42
+ every: 1m
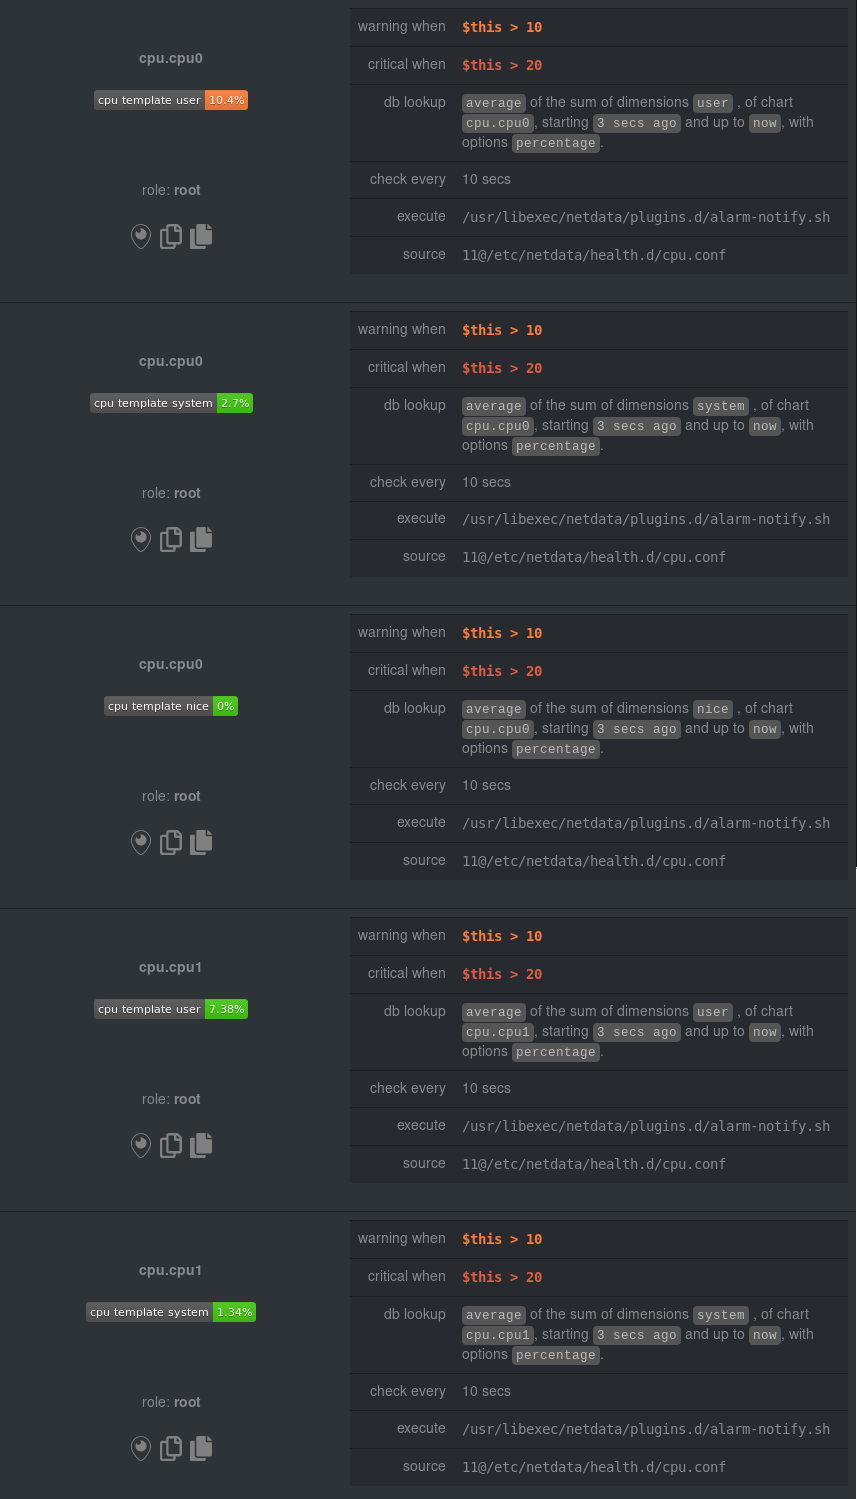
43
+ warn: $this > 50
44
+ crit: $this > 80
45
+
46
+ alarm: cpu_user
47
+ on: system.cpu
48
+lookup: average -10m percentage of user
49
+ every: 1m
50
+ warn: $this > 50
51
+ crit: $this > 80
52
+
53
+ alarm: cpu_nice
54
+ on: system.cpu
55
+lookup: average -10m percentage of nice
56
+ every: 1m
57
+ warn: $this > 50
58
+ crit: $this > 80
59
+```
60
+
61
+With dimension templates, you can condense these into a single alarm. Take note of the `alarm` and `lookup` lines.
62
+
63
+```yaml
64
+ alarm: cpu_template
65
+ on: system.cpu
66
+lookup: average -10m percentage foreach system,user,nice
67
+ every: 1m
68
+ warn: $this > 50
69
+ crit: $this > 80
70
+```
71
+
72
+The `alarm` line specifies the naming scheme Netdata will use. You can use whatever naming scheme you'd like, with `.`
73
+and `_` being the only allowed symbols.
74
+
75
+The `lookup` line has changed from `of` to `foreach`, and we're now passing three dimensions.
76
+
77
+In this example, Netdata will create three alarms with the names `cpu_template_system`, `cpu_template_user`, and
78
+`cpu_template_nice`. Every minute, each alarm will use the same database query to calculate the average CPU usage for
79
+the `system`, `user`, and `nice` dimensions over the last 10 minutes and send out alarms if necessary.
80
+
81
+You can find these three alarms active by clicking on the **Alarms** button in the top navigation, and then clicking on
82
+the **All** tab and scrolling to the **system - cpu** collapsible section.
83
+
84
+
85
+
86
+Let's look at some other examples of how `foreach` works so you can best apply it in your configurations.
87
+
88
+### Using a Netdata simple pattern in `foreach`
89
+
90
+In the last example, we used `foreach system,user,nice` to create three distinct alarms using dimension templates. But
91
+what if you want to quickly create alarms for _all_ the dimensions of a given chart?
92
+
93
+Use a [simple pattern](../../libnetdata/simple_pattern/README.md)! One example of a simple pattern is a single wildcard
94
+(`*`).
95
+
96
+Instead of monitoring system CPU usage, let's monitor per-application CPU usage using the `apps.cpu` chart. Passing a
97
+wildcard as the simple pattern tells Netdata to create a separate alarm for _every_ process on your system:
98
+
99
+```yaml
100
+ alarm: app_cpu
101
+ on: apps.cpu
102
+lookup: average -10m percentage foreach *
103
+ every: 1m
104
+ warn: $this > 50
105
+ crit: $this > 80
106
+```
107
+
108
+This entity will now create alarms for every dimension in the `apps.cpu` chart. Given that most `apps.cpu` charts have
109
+10 or more dimensions, using the wildcard ensures you catch every CPU-hogging process.
110
+
111
+To learn more about how to use simple patterns with dimension templates, see our [simple patterns
112
+documentation](../../libnetdata/simple_pattern/README.md).
113
+
114
+## Using `foreach` with alarm templates
115
+
116
+Dimension templates also work with [alarm templates](../../health/README.md#entities-in-the-health-files). Alarm
117
+templates help you create alarms for all the charts with a given context—for example, all the cores of your system's
118
+CPU.
119
+
120
+By combining the two, you can create dozens of individual alarms with a single template entity. Here's how you would
121
+create alarms for the `system`, `user`, and `nice` dimensions for every chart in the `cpu.cpu` context—or, in other
122
+words, every CPU core.
123
+
124
+```yaml
125
+template: cpu_template
126
+ on: cpu.cpu
127
+ lookup: average -10m percentage foreach system,user,nice
128
+ every: 1m
129
+ warn: $this > 50
130
+ crit: $this > 80
131
+```
132
+
133
+On a system with a 6-core, 12-thread Ryzen 5 1600 CPU, this one entity creates alarms on the following charts and
134
+dimensions:
135
+
136
+- `cpu.cpu0`
137
+ - `cpu_template_user`
138
+ - `cpu_template_system`
139
+ - `cpu_template_nice`
140
+- `cpu.cpu1`
141
+ - `cpu_template_user`
142
+ - `cpu_template_system`
143
+ - `cpu_template_nice`
144
+- `cpu.cpu2`
145
+ - `cpu_template_user`
146
+ - `cpu_template_system`
147
+ - `cpu_template_nice`
148
+- ...
149
+- `cpu.cpu11`
150
+ - `cpu_template_user`
151
+ - `cpu_template_system`
152
+ - `cpu_template_nice`
153
+
154
+And how just a few of those dimension template-generated alarms look like in the Netdata dashboard.
155
+
156
+
157
+
158
+All in all, this single entity creates 36 individual alarms. Much easier than writing 36 separate entities in your
159
+health configuration files!
160
+
161
+## What's next?
162
+
163
+We hope you're excited about the possibilities of using dimension templates! Maybe they'll inspire you to build new
164
+alarms that will help you better monitor the health of your systems.
165
+
166
+Or, at the very least, simplify your configuration files.
167
+
168
+For information about other advanced features in Netdata's health monitoring toolkit, check out our [health
169
+documentation](../../health/). And if you have some cool alarms you built using dimension templates,
docs/tutorials/longer-metrics-storage.md
+19
-18
@@ -7,30 +7,27 @@ Many people think Netdata can only store about an hour's worth of real-time metr
7
configuration today. With the right settings, Netdata is quite capable of efficiently storing hours or days worth of
8
historical, per-second metrics without having to rely on a [backend](../../backends/).
9
10
-This tutorial gives two options for configuring Netdata to store more metrics. We recommend the [**database
11
-engine**](#using-the-database-engine), as it will soon be the default configuration. However, you can stick with the
12
-current default **round-robin database** if you prefer.
10
+This tutorial gives two options for configuring Netdata to store more metrics. **We recommend the default [database
11
+engine](#using-the-database-engine)**, but you can stick with or switch to the round-robin database if you prefer.
12
13
Let's get started.
14
15
## Using the database engine
16
17
The database engine uses RAM to store recent metrics while also using a "spill to disk" feature that takes advantage of
19
-available disk space for long-term metrics storage.This feature of the database engine allows you to store a much larger
20
-dataset than your system's available RAM.
18
+available disk space for long-term metrics storage. This feature of the database engine allows you to store a much
19
+larger dataset than your system's available RAM.
20
22
-The database engine will eventually become the default method of retaining metrics, but until then, you can switch to
23
-the database engine by changing a single option.
24
-
25
-Edit your `netdata.conf` file and change the `memory mode` setting to `dbengine`:
21
+The database engine is currently the default method of storing metrics, but if you're not sure which database you're
22
+using, check out your `netdata.conf` file and look for the `memory mode` setting:
23
24
```conf
25
[global]
26
memory mode = dbengine
27
```
28
32
-Next, restart Netdata. On Linux systems, we recommend running `sudo service netdata restart`. You're now using the
33
-database engine!
29
+If `memory mode` is set to anything but `dbengine`, change it and restart Netdata using the standard command for
30
+restarting services on your system. You're now using the database engine!
31
32
> Learn more about how we implemented the database engine, and our vision for its future, on our blog: [_How and why
33
> we're bringing long-term storage to Netdata_](https://blog.netdata.cloud/posts/db-engine/).
@@ -55,10 +52,11 @@ size` and `dbengine disk space`.
52
`dbengine disk space` sets the maximum disk space (again, in MiB) the database engine will use for storing compressed
53
metrics.
54
58
-Based on our testing, these default settings will retain about two day's worth of metrics when Netdata collects 2,000
59
-metrics every second.
55
+Based on our testing, these default settings will retain about a day's worth of metrics when Netdata collects roughly
56
+4,000 metrics every second. If you increase either `page cache size` or `dbengine disk space`, Netdata will retain even
57
+more historical metrics.
58
61
-If you'd like to change these options, read more about the [database engine's memory
59
+But before you change these options too dramatically, read up on the [database engine's memory
60
footprint](../../database/engine/README.md#memory-requirements).
61
62
With the database engine active, you can back up your `/var/cache/netdata/dbengine/` folder to another location for
@@ -69,15 +67,18 @@ aren't ready to make the move.
67
68
## Using the round-robin database
69
72
-By default, Netdata uses a round-robin database to store 1 hour of per-second metrics. Here's the default setting for
73
-`history` in the `netdata.conf` file that comes pre-installed with Netdata.
70
+In previous versions, Netdata used a round-robin database to store 1 hour of per-second metrics.
71
+
72
+To see if you're still using this database, or if you would like to switch to it, open your `netdata.conf` file and see
73
+if `memory mode` option is set to `save`.
74
75
```conf
76
[global]
77
- history = 3600
77
+ memory mode = save
78
```
79
80
-One hour has 3,600 seconds, hence the `3600` value!
80
+If `memory mode` is set to `save`, then you're using the round-robin database. If so, the `history` option is set to
81
+`3600`, which is the equivalent to 3,600 seconds, or one hour.
82
83
To increase your historical metrics, you can increase `history` to the number of seconds you'd like to store:
84
docs/tutorials/monitor-hadoop-cluster.md
new
+197
@@ -0,0 +1,197 @@
1
+# Monitor a Hadoop cluster with Netdata
2
+
3
+Hadoop is an [Apache project](https://hadoop.apache.org/) is a framework for processing large sets of data across a
4
+distributed cluster of systems.
5
+
6
+And while Hadoop is designed to be a highly-available and fault-tolerant service, those who operate a Hadoop cluster
7
+will want to monitor the health and performance of their [Hadoop Distributed File System
8
+(HDFS)](https://hadoop.apache.org/docs/r1.2.1/hdfs_design.html) and [Zookeeper](https://zookeeper.apache.org/)
9
+implementations.
10
+
11
+Netdata comes with built-in and pre-configured support for monitoring both HDFS and Zookeeper.
12
+
13
+This tutorial assumes you have a Hadoop cluster, with HDFS and Zookeeper, running already. If you don't, please follow
14
+the [official Hadoop
15
+instructions](http://hadoop.apache.org/docs/stable/hadoop-project-dist/hadoop-common/SingleCluster.html) or an
16
+alternative, like the guide available from
17
+[DigitalOcean](https://www.digitalocean.com/community/tutorials/how-to-install-hadoop-in-stand-alone-mode-on-ubuntu-18-04).
18
+
19
+For more specifics on the collection modules used in this tutorial, read the respective pages in our documentation:
20
+
21
+- [HDFS](../../collectors/go.d.plugin/modules/hdfs/README.md)
22
+- [Zookeeper](../../collectors/go.d.plugin/modules/zookeeper/README.md)
23
+
24
+## Set up your HDFS and Zookeeper installations
25
+
26
+As with all data sources, Netdata can auto-detect HDFS and Zookeeper nodes if you installed them using the standard
27
+installation procedure.
28
+
29
+For Netdata to collect HDFS metrics, it needs to be able to access the node's `/jmx` endpoint. You can test whether an
30
+JMX endpoint is accessible by using `curl HDFS-IP:PORT/jmx`. For a NameNode, you should see output similar to the
31
+following:
32
+
33
+```json
34
+{
35
+ "beans" : [ {
36
+ "name" : "Hadoop:service=NameNode,name=JvmMetrics",
37
+ "modelerType" : "JvmMetrics",
38
+ "MemNonHeapUsedM" : 65.67851,
39
+ "MemNonHeapCommittedM" : 67.3125,
40
+ "MemNonHeapMaxM" : -1.0,
41
+ "MemHeapUsedM" : 154.46341,
42
+ "MemHeapCommittedM" : 215.0,
43
+ "MemHeapMaxM" : 843.0,
44
+ "MemMaxM" : 843.0,
45
+ "GcCount" : 15,
46
+ "GcTimeMillis" : 305,
47
+ "GcNumWarnThresholdExceeded" : 0,
48
+ "GcNumInfoThresholdExceeded" : 0,
49
+ "GcTotalExtraSleepTime" : 92,
50
+ "ThreadsNew" : 0,
51
+ "ThreadsRunnable" : 6,
52
+ "ThreadsBlocked" : 0,
53
+ "ThreadsWaiting" : 7,
54
+ "ThreadsTimedWaiting" : 34,
55
+ "ThreadsTerminated" : 0,
56
+ "LogFatal" : 0,
57
+ "LogError" : 0,
58
+ "LogWarn" : 2,
59
+ "LogInfo" : 348
60
+ },
61
+ { ... }
62
+ ]
63
+}
64
+```
65
+
66
+The JSON result for a DataNode's `/jmx` endpoint is slightly different:
67
+
68
+```json
69
+{
70
+ "beans" : [ {
71
+ "name" : "Hadoop:service=DataNode,name=DataNodeActivity-dev-slave-01.dev.loc
72
+al-9866",
73
+ "modelerType" : "DataNodeActivity-dev-slave-01.dev.local-9866",
74
+ "tag.SessionId" : null,
75
+ "tag.Context" : "dfs",
76
+ "tag.Hostname" : "dev-slave-01.dev.local",
77
+ "BytesWritten" : 500960407,
78
+ "TotalWriteTime" : 463,
79
+ "BytesRead" : 80689178,
80
+ "TotalReadTime" : 41203,
81
+ "BlocksWritten" : 16,
82
+ "BlocksRead" : 16,
83
+ "BlocksReplicated" : 4,
84
+ ...
85
+ },
86
+ { ... }
87
+ ]
88
+}
89
+```
90
+
91
+If Netdata can't access the `/jmx` endpoint for either a NameNode or DataNode, it will not be able to auto-detect and
92
+collect metrics from your HDFS implementation.
93
+
94
+Zookeeper auto-detection relies on an accessible client port and a whitelisted `mntr` command. For more details on
95
+`mntr`, see Zookeeper's documentation on [cluster
96
+options](https://zookeeper.apache.org/doc/current/zookeeperAdmin.html#sc_clusterOptions) and [Zookeeper
97
+commands](https://zookeeper.apache.org/doc/current/zookeeperAdmin.html#sc_zkCommands).
98
+
99
+## Configure the HDFS and Zookeeper modules
100
+
101
+To configure Netdata's HDFS module, navigate to your Netdata directory (typically at `/etc/netdata/`) and use
102
+`edit-config` to initialize and edit your HDFS configuration file.
103
+
104
+```bash
105
+cd /etc/netdata/
106
+sudo ./edit-config go.d/hdfs.conf
107
+```
108
+
109
+At the bottom of the file, you will see two example jobs, both of which are commented out:
110
+
111
+```yaml
112
+# [ JOBS ]
113
+#jobs:
114
+# - name: namenode
115
+# url: http://127.0.0.1:9870/jmx
116
+#
117
+# - name: datanode
118
+# url: http://127.0.0.1:9864/jmx
119
+```
120
+
121
+Uncomment these lines and edit the `url` value(s) according to your setup. Now's the time to add any other configuration
122
+details, which you can find inside of the `hdfs.conf` file itself. Most production implementations will require TLS
123
+certificates.
124
+
125
+The result for a simple HDFS setup, running entirely on `localhost` and without certificate authentication, might look
126
+like this:
127
+
128
+```yaml
129
+# [ JOBS ]
130
+jobs:
131
+ - name: namenode
132
+ url: http://127.0.0.1:9870/jmx
133
+
134
+ - name: datanode
135
+ url: http://127.0.0.1:9864/jmx
136
+```
137
+
138
+At this point, Netdata should be configured to collect metrics from your HDFS servers. Let's move on to Zookeeper.
139
+
140
+Next, use `edit-config` again to initialize/edit your `zookeeper.conf` file.
141
+
142
+```bash
143
+cd /etc/netdata/
144
+sudo ./edit-config go.d/zookeeper.conf
145
+```
146
+
147
+As with the `hdfs.conf` file, head to the bottom, uncomment the example jobs, and tweak the `address` values according
148
+to your setup. Again, you may need to add additional configuration options, like TLS certificates.
149
+
150
+```yaml
151
+jobs:
152
+ - name : local
153
+ address : 127.0.0.1:2181
154
+
155
+ - name : remote
156
+ address : 203.0.113.10:2182
157
+```
158
+
159
+Finally, restart Netdata.
160
+
161
+```sh
162
+sudo service restart netdata
163
+```
164
+
165
+Upon restart, Netdata should recognize your HDFS/Zookeeper servers, enable the HDFS and Zookeeper modules, and begin
166
+showing real-time metrics for both in your Netdata dashboard. 🎉
167
+
168
+## Configuring HDFS and Zookeeper alarms
169
+
170
+The Netdata community helped us create sane defaults for alarms related to both HDFS and Zookeeper. You may want to
171
+investigate these to ensure they work well with your Hadoop implementation.
172
+
173
+- [HDFS alarms](https://raw.githubusercontent.com/netdata/netdata/master/health/health.d/hdfs.conf)
174
+- [Zookeeper alarms](https://raw.githubusercontent.com/netdata/netdata/master/health/health.d/zookeeper.conf)
175
+
176
+You can also access/edit these files directly with `edit-config`:
177
+
178
+```bash
179
+sudo /etc/netdata/edit-config health.d/hdfs.conf
180
+sudo /etc/netdata/edit-config health.d/zookeeper.conf
181
+```
182
+
183
+For more information about editing the defaults or writing new alarm entities, see our [health monitoring
184
+documentation](../../health/README.md).
185
+
186
+## What's next?
187
+
188
+If you're having issues with Netdata auto-detecting your HDFS/Zookeeper servers, or want to help improve how Netdata
189
+collects or presents metrics from these services, feel free to [file an
190
+issue](https://github.com/netdata/netdata/issues/new?labels=bug%2C+needs+triage&template=bug_report.md).
191
+
192
+- Read up on the [HDFS configuration
193
+ file](https://github.com/netdata/go.d.plugin/blob/master/config/go.d/hdfs.conf) to understand how to configure
194
+ global options or per-job options, such as username/password, TLS certificates, timeouts, and more.
195
+- Read up on the [Zookeeper configuration
196
+ file](https://github.com/netdata/go.d.plugin/blob/master/config/go.d/zookeeper.conf) to understand how to configure
197
+ global options or per-job options, timeouts, TLS certificates, and more.