Pandas collector (#13773)
Add pandas collector.
Andrew Maguire committed
Oct 18, 2022 at 20:30 UTC
d41cded5def1b1046062be9e0288c214e2e088b9
7 files changed
+392
collectors/python.d.plugin/Makefile.am
+1
@@ -72,6 +72,7 @@ include nsd/Makefile.inc
72
include ntpd/Makefile.inc
73
include openldap/Makefile.inc
74
include oracledb/Makefile.inc
75
+include pandas/Makefile.inc
76
include postfix/Makefile.inc
77
include proxysql/Makefile.inc
78
include puppet/Makefile.inc
collectors/python.d.plugin/pandas/Makefile.inc
new
+13
@@ -0,0 +1,13 @@
1
+# SPDX-License-Identifier: GPL-3.0-or-later
2
+
3
+# THIS IS NOT A COMPLETE Makefile
4
+# IT IS INCLUDED BY ITS PARENT'S Makefile.am
5
+# IT IS REQUIRED TO REFERENCE ALL FILES RELATIVE TO THE PARENT
6
+
7
+# install these files
8
+dist_python_DATA += pandas/pandas.chart.py
9
+dist_pythonconfig_DATA += pandas/pandas.conf
10
+
11
+# do not install these files, but include them in the distribution
12
+dist_noinst_DATA += pandas/README.md pandas/Makefile.inc
13
+
collectors/python.d.plugin/pandas/README.md
new
+93
@@ -0,0 +1,93 @@
1
+<!--
2
+title: "Pandas"
3
+custom_edit_url: https://github.com/netdata/netdata/edit/master/collectors/python.d.plugin/pandas/README.md
4
+-->
5
+
6
+# Pandas Netdata Collector
7
+
8
+<a href="https://pandas.pydata.org/" target="_blank">
9
+ <img src="https://pandas.pydata.org/docs/_static/pandas.svg" alt="Pandas" width="100px" height="50px" />
10
+ </a>
11
+
12
+A python collector using [pandas](https://pandas.pydata.org/) to pull data and do pandas based
13
+preprocessing before feeding to Netdata.
14
+
15
+## Requirements
16
+
17
+This collector depends on some Python (Python 3 only) packages that can usually be installed via `pip` or `pip3`.
18
+
19
+```bash
20
+sudo pip install pandas requests
21
+```
22
+
23
+## Configuration
24
+
25
+Below is an example configuration to query some csv data from
26
+[london Netdata demo server](http://london.my-netdata.io/), do some data wrangling on it and save in
27
+format as expected by Netdata.
28
+
29
+```yaml
30
+# example pulling some hourly temperature data
31
+temperature:
32
+ name: "temperature"
33
+ update_every: 3
34
+ chart_configs:
35
+ - name: "temperature_by_city"
36
+ title: "Temperature By City"
37
+ family: "temperature.today"
38
+ context: "pandas.temperature"
39
+ type: "line"
40
+ units: "Celsius"
41
+ df_steps: >
42
+ pd.DataFrame.from_dict(
43
+ {city: requests.get(
44
+ f'https://api.open-meteo.com/v1/forecast?latitude={lat}&longitude={lng}&hourly=temperature_2m'
45
+ ).json()['hourly']['temperature_2m']
46
+ for (city,lat,lng)
47
+ in [
48
+ ('dublin', 53.3441, -6.2675),
49
+ ('athens', 37.9792, 23.7166),
50
+ ('london', 51.5002, -0.1262),
51
+ ('berlin', 52.5235, 13.4115),
52
+ ('paris', 48.8567, 2.3510),
53
+ ]
54
+ }
55
+ ); # use dictionary comprehension to make multiple requests;
56
+ df.describe(); # get aggregate stats for each city;
57
+ df.transpose()[['mean', 'max', 'min']].reset_index(); # just take mean, min, max;
58
+ df.rename(columns={'index':'city'}); # some column renaming;
59
+ df.pivot(columns='city').mean().to_frame().reset_index(); # force to be one row per city;
60
+ df.rename(columns={0:'degrees'}); # some column renaming;
61
+ pd.concat([df, df['city']+'_'+df['level_0']], axis=1); # add new column combining city and summary measurement label;
62
+ df.rename(columns={0:'measurement'}); # some column renaming;
63
+ df[['measurement', 'degrees']].set_index('measurement'); # just take two columns we want;
64
+ df.sort_index(); # sort by city name;
65
+ df.transpose(); # transpose so its just one wide row;
66
+```
67
+
68
+`chart_configs` is a list of dictionary objects where each one defines the sequence of `df_steps` to be run using [`pandas`](https://pandas.pydata.org/),
69
+and the `name`, `title` etc to define the
70
+[CHART variables](https://learn.netdata.cloud/docs/agent/collectors/python.d.plugin#global-variables-order-and-chart)
71
+that will control how the results will look in netdata.
72
+
73
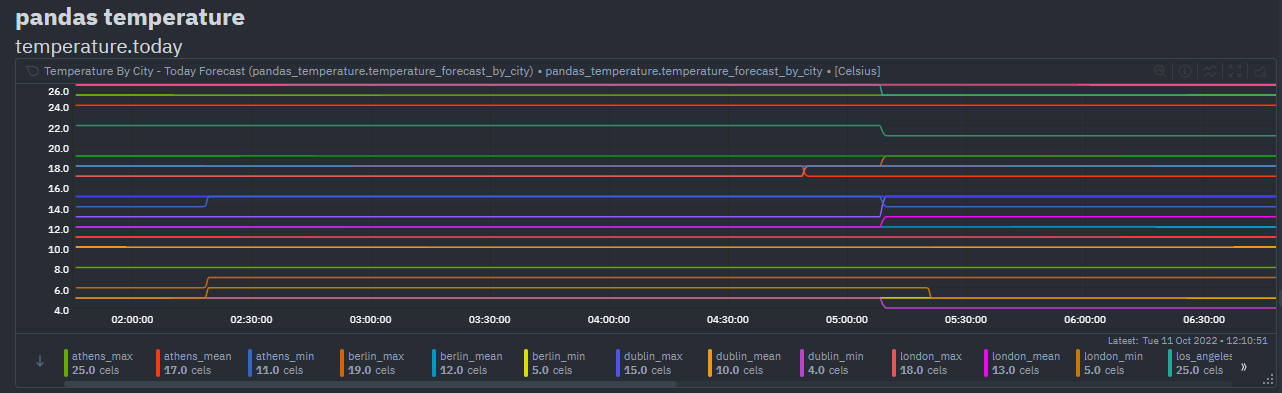
+The example configuration above would result in a `data` dictionary like the below being collected by Netdata
74
+at each time step. They keys in this dictionary will be the
75
+[dimension](https://learn.netdata.cloud/docs/agent/web#dimensions) names on the chart.
76
+
77
+```javascript
78
+{'athens_max': 26.2, 'athens_mean': 19.45952380952381, 'athens_min': 12.2, 'berlin_max': 17.4, 'berlin_mean': 10.764285714285714, 'berlin_min': 5.7, 'dublin_max': 15.3, 'dublin_mean': 12.008928571428571, 'dublin_min': 6.6, 'london_max': 18.9, 'london_mean': 12.510714285714286, 'london_min': 5.2, 'paris_max': 19.4, 'paris_mean': 12.054166666666665, 'paris_min': 4.8}
79
+```
80
+
81
+Which, given the above configuration would end up as a chart like below in Netdata.
82
+
83
+
84
+
85
+## Notes
86
+- Each line in `df_steps` must return a pandas
87
+[DataFrame](https://pandas.pydata.org/docs/reference/api/pandas.DataFrame.html) object (`df`) at each step.
88
+- You can use
89
+[this colab notebook](https://colab.research.google.com/drive/1VYrddSegZqGtkWGFuiUbMbUk5f3rW6Hi?usp=sharing)
90
+to mock up and work on your `df_steps` iteratively before adding them to your config.
91
+- This collector is expecting one row in the final pandas DataFrame. It is that first row that will be taken
92
+as the most recent values for each dimension on each chart using (`df.to_dict(orient='records')[0]`).
93
+See [pd.to_dict()](https://pandas.pydata.org/docs/reference/api/pandas.DataFrame.to_dict.html).
collectors/python.d.plugin/pandas/pandas.chart.py
new
+89
@@ -0,0 +1,89 @@
1
+# -*- coding: utf-8 -*-
2
+# Description: pandas netdata python.d module
3
+# Author: Andrew Maguire (andrewm4894)
4
+# SPDX-License-Identifier: GPL-3.0-or-later
5
+
6
+import pandas as pd
7
+
8
+try:
9
+ import requests
10
+ HAS_REQUESTS = True
11
+except ImportError:
12
+ HAS_REQUESTS = False
13
+
14
+from bases.FrameworkServices.SimpleService import SimpleService
15
+
16
+ORDER = []
17
+
18
+CHARTS = {}
19
+
20
+
21
+class Service(SimpleService):
22
+ def __init__(self, configuration=None, name=None):
23
+ SimpleService.__init__(self, configuration=configuration, name=name)
24
+ self.order = ORDER
25
+ self.definitions = CHARTS
26
+ self.chart_configs = self.configuration.get('chart_configs', None)
27
+ self.line_sep = self.configuration.get('line_sep', ';')
28
+
29
+ def run_code(self, df_steps):
30
+ """eval() each line of code and ensure the result is a pandas dataframe"""
31
+
32
+ # process each line of code
33
+ lines = df_steps.split(self.line_sep)
34
+ for line in lines:
35
+ line_clean = line.strip('\n').strip(' ')
36
+ if line_clean != '' and line_clean[0] != '#':
37
+ df = eval(line_clean)
38
+ assert isinstance(df, pd.DataFrame), 'The result of each evaluated line of `df_steps` must be of type `pd.DataFrame`'
39
+
40
+ # take top row of final df as data to be collected by netdata
41
+ data = df.to_dict(orient='records')[0]
42
+
43
+ return data
44
+
45
+ def check(self):
46
+ """ensure charts and dims all configured and that we can get data"""
47
+
48
+ if not HAS_REQUESTS:
49
+ self.warn('requests library could not be imported')
50
+
51
+ if not self.chart_configs:
52
+ self.error('chart_configs must be defined')
53
+
54
+ data = dict()
55
+
56
+ # add each chart as defined by the config
57
+ for chart_config in self.chart_configs:
58
+ if chart_config['name'] not in self.charts:
59
+ chart_template = {
60
+ 'options': [
61
+ chart_config['name'],
62
+ chart_config['title'],
63
+ chart_config['units'],
64
+ chart_config['family'],
65
+ chart_config['context'],
66
+ chart_config['type']
67
+ ],
68
+ 'lines': []
69
+ }
70
+ self.charts.add_chart([chart_config['name']] + chart_template['options'])
71
+
72
+ data_tmp = self.run_code(chart_config['df_steps'])
73
+ data.update(data_tmp)
74
+
75
+ for dim in data_tmp:
76
+ self.charts[chart_config['name']].add_dimension([dim, dim, 'absolute', 1, 1])
77
+
78
+ return True
79
+
80
+ def get_data(self):
81
+ """get data for each chart config"""
82
+
83
+ data = dict()
84
+
85
+ for chart_config in self.chart_configs:
86
+ data_tmp = self.run_code(chart_config['df_steps'])
87
+ data.update(data_tmp)
88
+
89
+ return data
collectors/python.d.plugin/pandas/pandas.conf
new
+191
@@ -0,0 +1,191 @@
1
+# netdata python.d.plugin configuration for pandas
2
+#
3
+# This file is in YaML format. Generally the format is:
4
+#
5
+# name: value
6
+#
7
+# There are 2 sections:
8
+# - global variables
9
+# - one or more JOBS
10
+#
11
+# JOBS allow you to collect values from multiple sources.
12
+# Each source will have its own set of charts.
13
+#
14
+# JOB parameters have to be indented (using spaces only, example below).
15
+
16
+# ----------------------------------------------------------------------
17
+# Global Variables
18
+# These variables set the defaults for all JOBs, however each JOB
19
+# may define its own, overriding the defaults.
20
+
21
+# update_every sets the default data collection frequency.
22
+# If unset, the python.d.plugin default is used.
23
+update_every: 5
24
+
25
+# priority controls the order of charts at the netdata dashboard.
26
+# Lower numbers move the charts towards the top of the page.
27
+# If unset, the default for python.d.plugin is used.
28
+# priority: 60000
29
+
30
+# penalty indicates whether to apply penalty to update_every in case of failures.
31
+# Penalty will increase every 5 failed updates in a row. Maximum penalty is 10 minutes.
32
+# penalty: yes
33
+
34
+# autodetection_retry sets the job re-check interval in seconds.
35
+# The job is not deleted if check fails.
36
+# Attempts to start the job are made once every autodetection_retry.
37
+# This feature is disabled by default.
38
+# autodetection_retry: 0
39
+
40
+# ----------------------------------------------------------------------
41
+# JOBS (data collection sources)
42
+#
43
+# The default JOBS share the same *name*. JOBS with the same name
44
+# are mutually exclusive. Only one of them will be allowed running at
45
+# any time. This allows autodetection to try several alternatives and
46
+# pick the one that works.
47
+#
48
+# Any number of jobs is supported.
49
+#
50
+# All python.d.plugin JOBS (for all its modules) support a set of
51
+# predefined parameters. These are:
52
+#
53
+# job_name:
54
+# name: myname # the JOB's name as it will appear on the dashboard
55
+# # dashboard (by default is the job_name)
56
+# # JOBs sharing a name are mutually exclusive
57
+# update_every: 1 # the JOB's data collection frequency
58
+# priority: 60000 # the JOB's order on the dashboard
59
+# penalty: yes # the JOB's penalty
60
+# autodetection_retry: 0 # the JOB's re-check interval in seconds
61
+#
62
+# Additionally to the above, example also supports the following:
63
+#
64
+# num_lines: 4 # the number of lines to create
65
+# lower: 0 # the lower bound of numbers to randomly sample from
66
+# upper: 100 # the upper bound of numbers to randomly sample from
67
+#
68
+# ----------------------------------------------------------------------
69
+# AUTO-DETECTION JOBS
70
+
71
+# Some example configurations, enable this collector, uncomment and example below and restart netdata to enable.
72
+
73
+# example pulling some hourly temperature data, a chart for today forecast (mean,min,max) and another chart for current.
74
+# temperature:
75
+# name: "temperature"
76
+# update_every: 5
77
+# chart_configs:
78
+# - name: "temperature_forecast_by_city"
79
+# title: "Temperature By City - Today Forecast"
80
+# family: "temperature.today"
81
+# context: "pandas.temperature"
82
+# type: "line"
83
+# units: "Celsius"
84
+# df_steps: >
85
+# pd.DataFrame.from_dict(
86
+# {city: requests.get(f'https://api.open-meteo.com/v1/forecast?latitude={lat}&longitude={lng}&hourly=temperature_2m').json()['hourly']['temperature_2m']
87
+# for (city,lat,lng)
88
+# in [
89
+# ('dublin', 53.3441, -6.2675),
90
+# ('athens', 37.9792, 23.7166),
91
+# ('london', 51.5002, -0.1262),
92
+# ('berlin', 52.5235, 13.4115),
93
+# ('paris', 48.8567, 2.3510),
94
+# ('madrid', 40.4167, -3.7033),
95
+# ('new_york', 40.71, -74.01),
96
+# ('los_angeles', 34.05, -118.24),
97
+# ]
98
+# }
99
+# );
100
+# df.describe(); # get aggregate stats for each city;
101
+# df.transpose()[['mean', 'max', 'min']].reset_index(); # just take mean, min, max;
102
+# df.rename(columns={'index':'city'}); # some column renaming;
103
+# df.pivot(columns='city').mean().to_frame().reset_index(); # force to be one row per city;
104
+# df.rename(columns={0:'degrees'}); # some column renaming;
105
+# pd.concat([df, df['city']+'_'+df['level_0']], axis=1); # add new column combining city and summary measurement label;
106
+# df.rename(columns={0:'measurement'}); # some column renaming;
107
+# df[['measurement', 'degrees']].set_index('measurement'); # just take two columns we want;
108
+# df.sort_index(); # sort by city name;
109
+# df.transpose(); # transpose so its just one wide row;
110
+# - name: "temperature_current_by_city"
111
+# title: "Temperature By City - Current"
112
+# family: "temperature.current"
113
+# context: "pandas.temperature"
114
+# type: "line"
115
+# units: "Celsius"
116
+# df_steps: >
117
+# pd.DataFrame.from_dict(
118
+# {city: requests.get(f'https://api.open-meteo.com/v1/forecast?latitude={lat}&longitude={lng}¤t_weather=true').json()['current_weather']
119
+# for (city,lat,lng)
120
+# in [
121
+# ('dublin', 53.3441, -6.2675),
122
+# ('athens', 37.9792, 23.7166),
123
+# ('london', 51.5002, -0.1262),
124
+# ('berlin', 52.5235, 13.4115),
125
+# ('paris', 48.8567, 2.3510),
126
+# ('madrid', 40.4167, -3.7033),
127
+# ('new_york', 40.71, -74.01),
128
+# ('los_angeles', 34.05, -118.24),
129
+# ]
130
+# }
131
+# );
132
+# df.transpose();
133
+# df[['temperature']];
134
+# df.transpose();
135
+
136
+# example showing a read_csv from a url and some light pandas data wrangling.
137
+# pull data in csv format from london demo server and then ratio of user cpus over system cpu averaged over last 60 seconds.
138
+# example_csv:
139
+# name: "example_csv"
140
+# update_every: 2
141
+# chart_configs:
142
+# - name: "london_system_cpu"
143
+# title: "London System CPU - Ratios"
144
+# family: "london_system_cpu"
145
+# context: "pandas"
146
+# type: "line"
147
+# units: "n"
148
+# df_steps: >
149
+# pd.read_csv('https://london.my-netdata.io/api/v1/data?chart=system.cpu&format=csv&after=-60', storage_options={'User-Agent': 'netdata'});
150
+# df.drop('time', axis=1);
151
+# df.mean().to_frame().transpose();
152
+# df.apply(lambda row: (row.user / row.system), axis = 1).to_frame();
153
+# df.rename(columns={0:'average_user_system_ratio'});
154
+# df*100;
155
+
156
+# example showing a read_json from a url and some light pandas data wrangling.
157
+# pull data in json format (using requests.get() if json data is too complex for pd.read_json() ) from london demo server and work out 'total_bandwidth'.
158
+# example_json:
159
+# name: "example_json"
160
+# update_every: 2
161
+# chart_configs:
162
+# - name: "london_system_net"
163
+# title: "London System Net - Total Bandwidth"
164
+# family: "london_system_net"
165
+# context: "pandas"
166
+# type: "area"
167
+# units: "kilobits/s"
168
+# df_steps: >
169
+# pd.DataFrame(requests.get('https://london.my-netdata.io/api/v1/data?chart=system.net&format=json&after=-1').json()['data'], columns=requests.get('https://london.my-netdata.io/api/v1/data?chart=system.net&format=json&after=-1').json()['labels']);
170
+# df.drop('time', axis=1);
171
+# abs(df);
172
+# df.sum(axis=1).to_frame();
173
+# df.rename(columns={0:'total_bandwidth'});
174
+
175
+# example showing a read_xml from a url and some light pandas data wrangling.
176
+# pull weather forecast data in xml format, use xpath to pull out temperature forecast.
177
+# example_xml:
178
+# name: "example_xml"
179
+# update_every: 2
180
+# line_sep: "|"
181
+# chart_configs:
182
+# - name: "temperature_forcast"
183
+# title: "Temperature Forecast"
184
+# family: "temp"
185
+# context: "pandas.temp"
186
+# type: "line"
187
+# units: "celsius"
188
+# df_steps: >
189
+# pd.read_xml('http://metwdb-openaccess.ichec.ie/metno-wdb2ts/locationforecast?lat=54.7210798611;long=-8.7237392806', xpath='./product/time[1]/location/temperature', parser='etree')|
190
+# df.rename(columns={'value': 'dublin'})|
191
+# df[['dublin']]|
\ No newline at end of file
collectors/python.d.plugin/python.d.conf
+1
@@ -62,6 +62,7 @@ logind: no
62
# ntpd: yes
63
# openldap: yes
64
# oracledb: yes
65
+# pandas: yes
66
# postfix: yes
67
# proxysql: yes
68
# puppet: yes
web/gui/dashboard_info.js
+4
@@ -711,6 +711,10 @@ netdataDashboard.menu = {
711
icon: '<i class="fas fa-dragon"></i>',
712
info: 'VPN network interfaces and peers traffic.'
713
},
714
+
715
+ 'pandas': {
716
+ icon: '<i class="fas fa-teddy-bear"></i>'
717
+ },
718
};
719
720