docs rename alarm to alert (#15812)
Ilya Mashchenko committed
Aug 15, 2023 at 20:56 UTC
d5bdb7cf15b73ef4e761d31298eda9b7567bc8a8
75 files changed
+704
-711
collectors/COLLECTORS.md
+2
-2
@@ -581,9 +581,9 @@ collectors are described only in code and associated charts in Netdata dashboard
581
- [ACLK (code only)](https://github.com/netdata/netdata/blob/master/aclk/legacy/aclk_stats.c): View whether a Netdata
582
Agent is connected to Netdata Cloud via the [ACLK](https://github.com/netdata/netdata/blob/master/aclk/README.md), the
583
volume of queries, process times, and more.
584
-- [Alarms](https://github.com/netdata/netdata/blob/master/collectors/python.d.plugin/alarms/README.md): This collector
584
+- [Alerts](https://github.com/netdata/netdata/blob/master/collectors/python.d.plugin/alarms/README.md): This collector
585
creates an
586
- **Alarms** menu with one line plot showing the alarm states of a Netdata Agent over time.
586
+ **Alerts** menu with one line plot showing the alert states of a Netdata Agent over time.
587
- [Anomalies](https://github.com/netdata/netdata/blob/master/collectors/python.d.plugin/anomalies/README.md): This
588
collector uses the
589
Python PyOD library to perform unsupervised anomaly detection on your Netdata charts and/or dimensions.
collectors/cgroups.plugin/README.md
+4
-4
@@ -139,10 +139,10 @@ chart instead of `auto` to enable it permanently. For example:
139
You can also set the `enable zero metrics` option to `yes` in the `[global]` section which enables charts with zero
140
metrics for all internal Netdata plugins.
141
142
-### Alarms
142
+### Alerts
143
144
-CPU and memory limits are watched and used to rise alarms. Memory usage for every cgroup is checked against `ram`
145
-and `ram+swap` limits. CPU usage for every cgroup is checked against `cpuset.cpus` and `cpu.cfs_period_us` + `cpu.cfs_quota_us` pair assigned for the cgroup. Configuration for the alarms is available in `health.d/cgroups.conf`
144
+CPU and memory limits are watched and used to rise alerts. Memory usage for every cgroup is checked against `ram`
145
+and `ram+swap` limits. CPU usage for every cgroup is checked against `cpuset.cpus` and `cpu.cfs_period_us` + `cpu.cfs_quota_us` pair assigned for the cgroup. Configuration for the alerts is available in `health.d/cgroups.conf`
146
file.
147
148
## Monitoring systemd services
@@ -264,7 +264,7 @@ Network interfaces and cgroups (containers) are self-cleaned. When a network int
264
a few errors in error.log complaining about files it cannot find, but immediately:
265
266
1. It will detect this is a removed container or network interface
267
-2. It will freeze/pause all alarms for them
267
+2. It will freeze/pause all alerts for them
268
3. It will mark their charts as obsolete
269
4. Obsolete charts are not be offered on new dashboard sessions (so hit F5 and the charts are gone)
270
5. Existing dashboard sessions will continue to see them, but of course they will not refresh
collectors/freeipmi.plugin/README.md
+2
-2
@@ -90,9 +90,9 @@ Metrics:
90
| ipmi.sensor_power | power | Watts |
91
| ipmi.sensor_reading_percent | percentage | % |
92
93
-## Alarms
93
+## Alerts
94
95
-There are 2 alarms:
95
+There are 2 alerts:
96
97
- The sensor is in a warning or critical state.
98
- System Event Log (SEL) is non-empty.
collectors/ioping.plugin/README.md
+3
-3
@@ -33,10 +33,10 @@ request_size="4k"
33
ioping_opts="-T 1000000 -R"
34
```
35
36
-## alarms
36
+## alerts
37
38
-Netdata will automatically attach a few alarms for each host.
39
-Check the [latest versions of the ioping alarms](https://raw.githubusercontent.com/netdata/netdata/master/health/health.d/ioping.conf)
38
+Netdata will automatically attach a few alerts for each host.
39
+Check the [latest versions of the ioping alerts](https://raw.githubusercontent.com/netdata/netdata/master/health/health.d/ioping.conf)
40
41
## Multiple ioping Plugins With Different Settings
42
collectors/plugins.d/README.md
+29
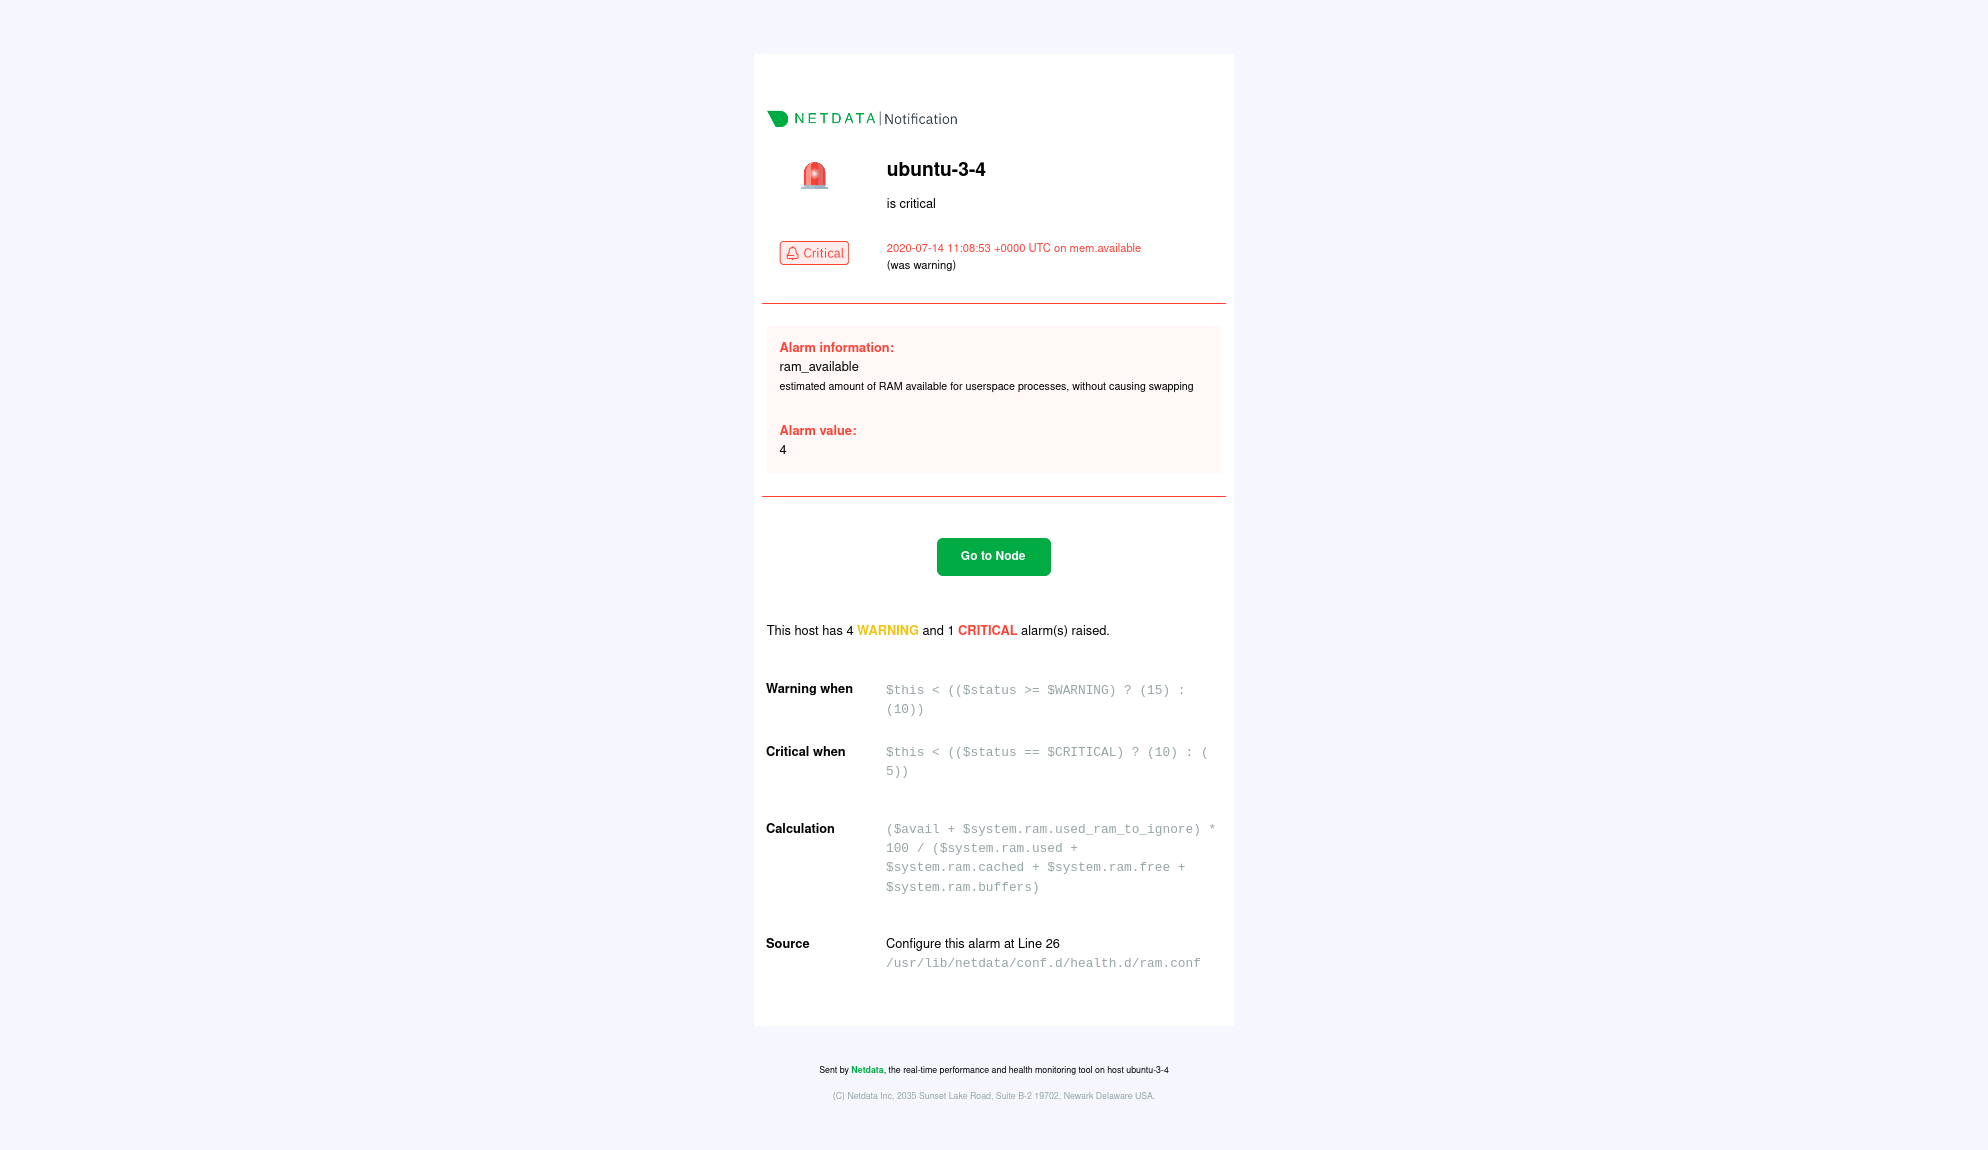
-29
@@ -14,20 +14,20 @@ from external processes, thus allowing Netdata to use **external plugins**.
14
15
## Provided External Plugins
16
17
-|plugin|language|O/S|description|
18
-|:----:|:------:|:-:|:----------|
19
-|[apps.plugin](https://github.com/netdata/netdata/blob/master/collectors/apps.plugin/README.md)|`C`|linux, freebsd|monitors the whole process tree on Linux and FreeBSD and breaks down system resource usage by **process**, **user** and **user group**.|
20
-|[charts.d.plugin](https://github.com/netdata/netdata/blob/master/collectors/charts.d.plugin/README.md)|`BASH`|all|a **plugin orchestrator** for data collection modules written in `BASH` v4+.|
21
-|[cups.plugin](https://github.com/netdata/netdata/blob/master/collectors/cups.plugin/README.md)|`C`|all|monitors **CUPS**|
22
-|[ebpf.plugin](https://github.com/netdata/netdata/blob/master/collectors/ebpf.plugin/README.md)|`C`|linux|monitors different metrics on environments using kernel internal functions.|
23
-|[go.d.plugin](https://github.com/netdata/go.d.plugin/blob/master/README.md)|`GO`|all|collects metrics from the system, applications, or third-party APIs.|
24
-|[ioping.plugin](https://github.com/netdata/netdata/blob/master/collectors/ioping.plugin/README.md)|`C`|all|measures disk latency.|
25
-|[freeipmi.plugin](https://github.com/netdata/netdata/blob/master/collectors/freeipmi.plugin/README.md)|`C`|linux|collects metrics from enterprise hardware sensors, on Linux servers.|
26
-|[nfacct.plugin](https://github.com/netdata/netdata/blob/master/collectors/nfacct.plugin/README.md)|`C`|linux|collects netfilter firewall, connection tracker and accounting metrics using `libmnl` and `libnetfilter_acct`.|
27
-|[xenstat.plugin](https://github.com/netdata/netdata/blob/master/collectors/xenstat.plugin/README.md)|`C`|linux|collects XenServer and XCP-ng metrics using `lxenstat`.|
28
-|[perf.plugin](https://github.com/netdata/netdata/blob/master/collectors/perf.plugin/README.md)|`C`|linux|collects CPU performance metrics using performance monitoring units (PMU).|
29
-|[python.d.plugin](https://github.com/netdata/netdata/blob/master/collectors/python.d.plugin/README.md)|`python`|all|a **plugin orchestrator** for data collection modules written in `python` v2 or v3 (both are supported).|
30
-|[slabinfo.plugin](https://github.com/netdata/netdata/blob/master/collectors/slabinfo.plugin/README.md)|`C`|linux|collects kernel internal cache objects (SLAB) metrics.|
17
+| plugin | language | O/S | description |
18
+|:------------------------------------------------------------------------------------------------------:|:--------:|:--------------:|:----------------------------------------------------------------------------------------------------------------------------------------|
19
+| [apps.plugin](https://github.com/netdata/netdata/blob/master/collectors/apps.plugin/README.md) | `C` | linux, freebsd | monitors the whole process tree on Linux and FreeBSD and breaks down system resource usage by **process**, **user** and **user group**. |
20
+| [charts.d.plugin](https://github.com/netdata/netdata/blob/master/collectors/charts.d.plugin/README.md) | `BASH` | all | a **plugin orchestrator** for data collection modules written in `BASH` v4+. |
21
+| [cups.plugin](https://github.com/netdata/netdata/blob/master/collectors/cups.plugin/README.md) | `C` | all | monitors **CUPS** |
22
+| [ebpf.plugin](https://github.com/netdata/netdata/blob/master/collectors/ebpf.plugin/README.md) | `C` | linux | monitors different metrics on environments using kernel internal functions. |
23
+| [go.d.plugin](https://github.com/netdata/go.d.plugin/blob/master/README.md) | `GO` | all | collects metrics from the system, applications, or third-party APIs. |
24
+| [ioping.plugin](https://github.com/netdata/netdata/blob/master/collectors/ioping.plugin/README.md) | `C` | all | measures disk latency. |
25
+| [freeipmi.plugin](https://github.com/netdata/netdata/blob/master/collectors/freeipmi.plugin/README.md) | `C` | linux | collects metrics from enterprise hardware sensors, on Linux servers. |
26
+| [nfacct.plugin](https://github.com/netdata/netdata/blob/master/collectors/nfacct.plugin/README.md) | `C` | linux | collects netfilter firewall, connection tracker and accounting metrics using `libmnl` and `libnetfilter_acct`. |
27
+| [xenstat.plugin](https://github.com/netdata/netdata/blob/master/collectors/xenstat.plugin/README.md) | `C` | linux | collects XenServer and XCP-ng metrics using `lxenstat`. |
28
+| [perf.plugin](https://github.com/netdata/netdata/blob/master/collectors/perf.plugin/README.md) | `C` | linux | collects CPU performance metrics using performance monitoring units (PMU). |
29
+| [python.d.plugin](https://github.com/netdata/netdata/blob/master/collectors/python.d.plugin/README.md) | `python` | all | a **plugin orchestrator** for data collection modules written in `python` v2 or v3 (both are supported). |
30
+| [slabinfo.plugin](https://github.com/netdata/netdata/blob/master/collectors/slabinfo.plugin/README.md) | `C` | linux | collects kernel internal cache objects (SLAB) metrics. |
31
32
Plugin orchestrators may also be described as **modular plugins**. They are modular since they accept custom made modules to be included. Writing modules for these plugins is easier than accessing the native Netdata API directly. You will find modules already available for each orchestrator under the directory of the particular modular plugin (e.g. under python.d.plugin for the python orchestrator).
33
Each of these modular plugins has each own methods for defining modules. Please check the examples and their documentation.
@@ -154,18 +154,18 @@ every 5 seconds.
154
There are a few environment variables that are set by `netdata` and are
155
available for the plugin to use.
156
157
-|variable|description|
158
-|:------:|:----------|
159
-|`NETDATA_USER_CONFIG_DIR`|The directory where all Netdata-related user configuration should be stored. If the plugin requires custom user configuration, this is the place the user has saved it (normally under `/etc/netdata`).|
160
-|`NETDATA_STOCK_CONFIG_DIR`|The directory where all Netdata -related stock configuration should be stored. If the plugin is shipped with configuration files, this is the place they can be found (normally under `/usr/lib/netdata/conf.d`).|
161
-|`NETDATA_PLUGINS_DIR`|The directory where all Netdata plugins are stored.|
162
-|`NETDATA_USER_PLUGINS_DIRS`|The list of directories where custom plugins are stored.|
163
-|`NETDATA_WEB_DIR`|The directory where the web files of Netdata are saved.|
164
-|`NETDATA_CACHE_DIR`|The directory where the cache files of Netdata are stored. Use this directory if the plugin requires a place to store data. A new directory should be created for the plugin for this purpose, inside this directory.|
165
-|`NETDATA_LOG_DIR`|The directory where the log files are stored. By default the `stderr` output of the plugin will be saved in the `error.log` file of Netdata.|
166
-|`NETDATA_HOST_PREFIX`|This is used in environments where system directories like `/sys` and `/proc` have to be accessed at a different path.|
167
-|`NETDATA_DEBUG_FLAGS`|This is a number (probably in hex starting with `0x`), that enables certain Netdata debugging features. Check **\[[Tracing Options]]** for more information.|
168
-|`NETDATA_UPDATE_EVERY`|The minimum number of seconds between chart refreshes. This is like the **internal clock** of Netdata (it is user configurable, defaulting to `1`). There is no meaning for a plugin to update its values more frequently than this number of seconds.|
157
+| variable | description |
158
+|:---------------------------:|:-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
159
+| `NETDATA_USER_CONFIG_DIR` | The directory where all Netdata-related user configuration should be stored. If the plugin requires custom user configuration, this is the place the user has saved it (normally under `/etc/netdata`). |
160
+| `NETDATA_STOCK_CONFIG_DIR` | The directory where all Netdata -related stock configuration should be stored. If the plugin is shipped with configuration files, this is the place they can be found (normally under `/usr/lib/netdata/conf.d`). |
161
+| `NETDATA_PLUGINS_DIR` | The directory where all Netdata plugins are stored. |
162
+| `NETDATA_USER_PLUGINS_DIRS` | The list of directories where custom plugins are stored. |
163
+| `NETDATA_WEB_DIR` | The directory where the web files of Netdata are saved. |
164
+| `NETDATA_CACHE_DIR` | The directory where the cache files of Netdata are stored. Use this directory if the plugin requires a place to store data. A new directory should be created for the plugin for this purpose, inside this directory. |
165
+| `NETDATA_LOG_DIR` | The directory where the log files are stored. By default the `stderr` output of the plugin will be saved in the `error.log` file of Netdata. |
166
+| `NETDATA_HOST_PREFIX` | This is used in environments where system directories like `/sys` and `/proc` have to be accessed at a different path. |
167
+| `NETDATA_DEBUG_FLAGS` | This is a number (probably in hex starting with `0x`), that enables certain Netdata debugging features. Check **\[[Tracing Options]]** for more information. |
168
+| `NETDATA_UPDATE_EVERY` | The minimum number of seconds between chart refreshes. This is like the **internal clock** of Netdata (it is user configurable, defaulting to `1`). There is no meaning for a plugin to update its values more frequently than this number of seconds. |
169
170
### The output of the plugin
171
@@ -298,7 +298,7 @@ the template is:
298
299
the context is giving the template of the chart. For example, if multiple charts present the same information for a different family, they should have the same `context`
300
301
- this is used for looking up rendering information for the chart (colors, sizes, informational texts) and also apply alarms to it
301
+ this is used for looking up rendering information for the chart (colors, sizes, informational texts) and also apply alerts to it
302
303
- `charttype`
304
@@ -388,12 +388,12 @@ the template is:
388
389
> VARIABLE [SCOPE] name = value
390
391
-`VARIABLE` defines a variable that can be used in alarms. This is to used for setting constants (like the max connections a server may accept).
391
+`VARIABLE` defines a variable that can be used in alerts. This is to used for setting constants (like the max connections a server may accept).
392
393
Variables support 2 scopes:
394
395
- `GLOBAL` or `HOST` to define the variable at the host level.
396
-- `LOCAL` or `CHART` to define the variable at the chart level. Use chart-local variables when the same variable may exist for different charts (i.e. Netdata monitors 2 mysql servers, and you need to set the `max_connections` each server accepts). Using chart-local variables is the ideal to build alarm templates.
396
+- `LOCAL` or `CHART` to define the variable at the chart level. Use chart-local variables when the same variable may exist for different charts (i.e. Netdata monitors 2 mysql servers, and you need to set the `max_connections` each server accepts). Using chart-local variables is the ideal to build alert templates.
397
398
The position of the `VARIABLE` line, sets its default scope (in case you do not specify a scope). So, defining a `VARIABLE` before any `CHART`, or between `END` and `BEGIN` (outside any chart), sets `GLOBAL` scope, while defining a `VARIABLE` just after a `CHART` or a `DIMENSION`, or within the `BEGIN` - `END` block of a chart, sets `LOCAL` scope.
399
collectors/proc.plugin/README.md
+3
-3
@@ -398,11 +398,11 @@ You can set the following values for each configuration option:
398
399
#### Wireless configuration
400
401
-#### alarms
401
+#### alerts
402
403
-There are several alarms defined in `health.d/net.conf`.
403
+There are several alerts defined in `health.d/net.conf`.
404
405
-The tricky ones are `inbound packets dropped` and `inbound packets dropped ratio`. They have quite a strict policy so that they warn users about possible issues. These alarms can be annoying for some network configurations. It is especially true for some bonding configurations if an interface is a child or a bonding interface itself. If it is expected to have a certain number of drops on an interface for a certain network configuration, a separate alarm with different triggering thresholds can be created or the existing one can be disabled for this specific interface. It can be done with the help of the [families](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md#alarm-line-families) line in the alarm configuration. For example, if you want to disable the `inbound packets dropped` alarm for `eth0`, set `families: !eth0 *` in the alarm definition for `template: inbound_packets_dropped`.
405
+The tricky ones are `inbound packets dropped` and `inbound packets dropped ratio`. They have quite a strict policy so that they warn users about possible issues. These alerts can be annoying for some network configurations. It is especially true for some bonding configurations if an interface is a child or a bonding interface itself. If it is expected to have a certain number of drops on an interface for a certain network configuration, a separate alert with different triggering thresholds can be created or the existing one can be disabled for this specific interface. It can be done with the help of the [families](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md#alert-line-families) line in the alert configuration. For example, if you want to disable the `inbound packets dropped` alert for `eth0`, set `families: !eth0 *` in the alert definition for `template: inbound_packets_dropped`.
406
407
#### configuration
408
collectors/statsd.plugin/README.md
+5
-5
@@ -36,7 +36,7 @@ Netdata ships with a few synthetic chart definitions to automatically present ap
36
more uniform way. These synthetic charts are configuration files (you can create your own) that re-arrange
37
statsd metrics into a more meaningful way.
38
39
-On synthetic charts, we can have alarms as with any metric and chart.
39
+On synthetic charts, we can have alerts as with any metric and chart.
40
41
- [K6 load testing tool](https://k6.io)
42
- **Description:** k6 is a developer-centric, free and open-source load testing tool built for making performance testing a productive and enjoyable experience.
@@ -348,11 +348,11 @@ Using the above configuration `myapp` should get its own section on the dashboar
348
- `gaps when not collected = yes|no`, enables or disables gaps on the charts of the application in case that no metrics are collected.
349
- `memory mode` sets the memory mode for all charts of the application. The default is the global default for Netdata (not the global default for StatsD private charts). We suggest not to use this (we have commented it out in the example) and let your app use the global default for Netdata, which is our dbengine.
350
351
-- `history` sets the size of the round robin database for this application. The default is the global default for Netdata (not the global default for StatsD private charts). This is only relevant if you use `memory mode = save`. Read more on our [metrics storage(]/docs/store/change-metrics-storage.md) doc.
351
+- `history` sets the size of the round-robin database for this application. The default is the global default for Netdata (not the global default for StatsD private charts). This is only relevant if you use `memory mode = save`. Read more on our [metrics storage(]/docs/store/change-metrics-storage.md) doc.
352
353
`[dictionary]` defines name-value associations. These are used to renaming metrics, when added to synthetic charts. Metric names are also defined at each `dimension` line. However, using the dictionary dimension names can be declared globally, for each app and is the only way to rename dimensions when using patterns. Of course the dictionary can be empty or missing.
354
355
-Then, add any number of charts. Each chart should start with `[id]`. The chart will be called `app_name.id`. `family` controls the submenu on the dashboard. `context` controls the alarm templates. `priority` controls the ordering of the charts on the dashboard. The rest of the settings are informational.
355
+Then, add any number of charts. Each chart should start with `[id]`. The chart will be called `app_name.id`. `family` controls the submenu on the dashboard. `context` controls the alert templates. `priority` controls the ordering of the charts on the dashboard. The rest of the settings are informational.
356
357
Add any number of metrics to a chart, using `dimension` lines. These lines accept 5 space separated parameters:
358
@@ -361,7 +361,7 @@ Add any number of metrics to a chart, using `dimension` lines. These lines accep
361
3. an optional selector (type) of the value to shown (see below)
362
4. an optional multiplier
363
5. an optional divider
364
-6. optional flags, space separated and enclosed in quotes. All the external plugins `DIMENSION` flags can be used. Currently the only usable flag is `hidden`, to add the dimension, but not show it on the dashboard. This is usually needed to have the values available for percentage calculation, or use them in alarms.
364
+6. optional flags, space separated and enclosed in quotes. All the external plugins `DIMENSION` flags can be used. Currently, the only usable flag is `hidden`, to add the dimension, but not show it on the dashboard. This is usually needed to have the values available for percentage calculation, or use them in alerts.
365
366
So, the format is this:
367
@@ -439,7 +439,7 @@ Use the dictionary in 2 ways:
439
1. set `dimension = myapp.metric1 ''` and have at the dictionary `myapp.metric1 = metric1 name`
440
2. set `dimension = myapp.metric1 'm1'` and have at the dictionary `m1 = metric1 name`
441
442
-In both cases, the dimension will be added with ID `myapp.metric1` and will be named `metric1 name`. So, in alarms use either of the 2 as `${myapp.metric1}` or `${metric1 name}`.
442
+In both cases, the dimension will be added with ID `myapp.metric1` and will be named `metric1 name`. So, in alerts use either of the 2 as `${myapp.metric1}` or `${metric1 name}`.
443
444
> keep in mind that if you add multiple times the same StatsD metric to a chart, Netdata will append `TYPE` to the dimension ID, so `myapp.metric1` will be added as `myapp.metric1_last` or `myapp.metric1_events`, etc. If you add multiple times the same metric with the same `TYPE` to a chart, Netdata will also append an incremental counter to the dimension ID, i.e. `myapp.metric1_last1`, `myapp.metric1_last2`, etc.
445
daemon/config/README.md
+65
-65
@@ -72,40 +72,40 @@ Please note that your data history will be lost if you have modified `history` p
72
73
### [global] section options
74
75
-| setting | default | info |
76
-|:-------------------------------------:|:-------------:|:---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
77
-| process scheduling policy | `keep` | See [Netdata process scheduling policy](https://github.com/netdata/netdata/blob/master/daemon/README.md#netdata-process-scheduling-policy) |
78
-| OOM score | `0` | |
79
-| glibc malloc arena max for plugins | `1` | See [Virtual memory](https://github.com/netdata/netdata/blob/master/daemon/README.md#virtual-memory). |
80
-| glibc malloc arena max for Netdata | `1` | See [Virtual memory](https://github.com/netdata/netdata/blob/master/daemon/README.md#virtual-memory). |
81
-| hostname | auto-detected | The hostname of the computer running Netdata. |
82
-| host access prefix | empty | This is used in docker environments where /proc, /sys, etc have to be accessed via another path. You may also have to set SYS_PTRACE capability on the docker for this work. Check [issue 43](https://github.com/netdata/netdata/issues/43). |
83
-| timezone | auto-detected | The timezone retrieved from the environment variable |
84
-| run as user | `netdata` | The user Netdata will run as. |
85
-| pthread stack size | auto-detected | |
75
+| setting | default | info |
76
+|:----------------------------------:|:-------------:|:---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
77
+| process scheduling policy | `keep` | See [Netdata process scheduling policy](https://github.com/netdata/netdata/blob/master/daemon/README.md#netdata-process-scheduling-policy) |
78
+| OOM score | `0` | |
79
+| glibc malloc arena max for plugins | `1` | See [Virtual memory](https://github.com/netdata/netdata/blob/master/daemon/README.md#virtual-memory). |
80
+| glibc malloc arena max for Netdata | `1` | See [Virtual memory](https://github.com/netdata/netdata/blob/master/daemon/README.md#virtual-memory). |
81
+| hostname | auto-detected | The hostname of the computer running Netdata. |
82
+| host access prefix | empty | This is used in docker environments where /proc, /sys, etc have to be accessed via another path. You may also have to set SYS_PTRACE capability on the docker for this work. Check [issue 43](https://github.com/netdata/netdata/issues/43). |
83
+| timezone | auto-detected | The timezone retrieved from the environment variable |
84
+| run as user | `netdata` | The user Netdata will run as. |
85
+| pthread stack size | auto-detected | |
86
87
### [db] section options
88
89
-| setting | default | info |
90
-|:---------------------------------------------:|:----------:|:------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
89
+| setting | default | info |
90
+|:---------------------------------------------:|:----------:|:---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
91
| mode | `dbengine` | `dbengine`: The default for long-term metrics storage with efficient RAM and disk usage. Can be extended with `dbengine page cache size MB` and `dbengine disk space MB`. <br />`save`: Netdata will save its round robin database on exit and load it on startup. <br />`map`: Cache files will be updated in real-time. Not ideal for systems with high load or slow disks (check `man mmap`). <br />`ram`: The round-robin database will be temporary and it will be lost when Netdata exits. <br />`alloc`: Similar to `ram`, but can significantly reduce memory usage, when combined with a low retention and does not support KSM. <br />`none`: Disables the database at this host, and disables health monitoring entirely, as that requires a database of metrics. Not to be used together with streaming. |
92
-| retention | `3600` | Used with `mode = save/map/ram/alloc`, not the default `mode = dbengine`. This number reflects the number of entries the `netdata` daemon will by default keep in memory for each chart dimension. Check [Memory Requirements](https://github.com/netdata/netdata/blob/master/database/README.md) for more information. |
93
-| storage tiers | `1` | The number of storage tiers you want to have in your dbengine. Check the tiering mechanism in the [dbengine's reference](https://github.com/netdata/netdata/blob/master/database/engine/README.md#tiering). You can have up to 5 tiers of data (including the _Tier 0_). This number ranges between 1 and 5. |
94
-| dbengine page cache size MB | `32` | Determines the amount of RAM in MiB that is dedicated to caching for _Tier 0_ Netdata metric values. |
95
-| dbengine tier **`N`** page cache size MB | `32` | Determines the amount of RAM in MiB that is dedicated for caching Netdata metric values of the **`N`** tier. <br /> `N belongs to [1..4]` ||
96
- | dbengine disk space MB | `256` | Determines the amount of disk space in MiB that is dedicated to storing _Tier 0_ Netdata metric values and all related metadata describing them. This option is available **only for legacy configuration** (`Agent v1.23.2 and prior`). |
97
-| dbengine multihost disk space MB | `256` | Same functionality as `dbengine disk space MB`, but includes support for storing metrics streamed to a parent node by its children. Can be used in single-node environments as well. This setting is only for _Tier 0_ metrics. |
98
-| dbengine tier **`N`** multihost disk space MB | `256` | Same functionality as `dbengine multihost disk space MB`, but stores metrics of the **`N`** tier (both parent node and its children). Can be used in single-node environments as well. <br /> `N belongs to [1..4]` |
99
-| update every | `1` | The frequency in seconds, for data collection. For more information see the [performance guide](https://github.com/netdata/netdata/blob/master/docs/guides/configure/performance.md). These metrics stored as _Tier 0_ data. Explore the tiering mechanism in the [dbengine's reference](https://github.com/netdata/netdata/blob/master/database/engine/README.md#tiering). |
100
-| dbengine tier **`N`** update every iterations | `60` | The down sampling value of each tier from the previous one. For each Tier, the greater by one Tier has N (equal to 60 by default) less data points of any metric it collects. This setting can take values from `2` up to `255`. <br /> `N belongs to [1..4]` |
101
-| dbengine tier **`N`** back fill | `New` | Specifies the strategy of recreating missing data on each Tier from the exact lower Tier. <br /> `New`: Sees the latest point on each Tier and save new points to it only if the exact lower Tier has available points for it's observation window (`dbengine tier N update every iterations` window). <br /> `none`: No back filling is applied. <br /> `N belongs to [1..4]` |
102
-| memory deduplication (ksm) | `yes` | When set to `yes`, Netdata will offer its in-memory round robin database and the dbengine page cache to kernel same page merging (KSM) for deduplication. For more information check [Memory Deduplication - Kernel Same Page Merging - KSM](https://github.com/netdata/netdata/blob/master/database/README.md#ksm) |
103
-| cleanup obsolete charts after secs | `3600` | See [monitoring ephemeral containers](https://github.com/netdata/netdata/blob/master/collectors/cgroups.plugin/README.md#monitoring-ephemeral-containers), also sets the timeout for cleaning up obsolete dimensions |
104
-| gap when lost iterations above | `1` | |
105
-| cleanup orphan hosts after secs | `3600` | How long to wait until automatically removing from the DB a remote Netdata host (child) that is no longer sending data. |
106
-| delete obsolete charts files | `yes` | See [monitoring ephemeral containers](https://github.com/netdata/netdata/blob/master/collectors/cgroups.plugin/README.md#monitoring-ephemeral-containers), also affects the deletion of files for obsolete dimensions |
107
-| delete orphan hosts files | `yes` | Set to `no` to disable non-responsive host removal. |
108
-| enable zero metrics | `no` | Set to `yes` to show charts when all their metrics are zero. |
92
+| retention | `3600` | Used with `mode = save/map/ram/alloc`, not the default `mode = dbengine`. This number reflects the number of entries the `netdata` daemon will by default keep in memory for each chart dimension. Check [Memory Requirements](https://github.com/netdata/netdata/blob/master/database/README.md) for more information. |
93
+| storage tiers | `1` | The number of storage tiers you want to have in your dbengine. Check the tiering mechanism in the [dbengine's reference](https://github.com/netdata/netdata/blob/master/database/engine/README.md#tiering). You can have up to 5 tiers of data (including the _Tier 0_). This number ranges between 1 and 5. |
94
+| dbengine page cache size MB | `32` | Determines the amount of RAM in MiB that is dedicated to caching for _Tier 0_ Netdata metric values. |
95
+| dbengine tier **`N`** page cache size MB | `32` | Determines the amount of RAM in MiB that is dedicated for caching Netdata metric values of the **`N`** tier. <br /> `N belongs to [1..4]` |
96
+| dbengine disk space MB | `256` | Determines the amount of disk space in MiB that is dedicated to storing _Tier 0_ Netdata metric values and all related metadata describing them. This option is available **only for legacy configuration** (`Agent v1.23.2 and prior`). |
97
+| dbengine multihost disk space MB | `256` | Same functionality as `dbengine disk space MB`, but includes support for storing metrics streamed to a parent node by its children. Can be used in single-node environments as well. This setting is only for _Tier 0_ metrics. |
98
+| dbengine tier **`N`** multihost disk space MB | `256` | Same functionality as `dbengine multihost disk space MB`, but stores metrics of the **`N`** tier (both parent node and its children). Can be used in single-node environments as well. <br /> `N belongs to [1..4]` |
99
+| update every | `1` | The frequency in seconds, for data collection. For more information see the [performance guide](https://github.com/netdata/netdata/blob/master/docs/guides/configure/performance.md). These metrics stored as _Tier 0_ data. Explore the tiering mechanism in the [dbengine's reference](https://github.com/netdata/netdata/blob/master/database/engine/README.md#tiering). |
100
+| dbengine tier **`N`** update every iterations | `60` | The down sampling value of each tier from the previous one. For each Tier, the greater by one Tier has N (equal to 60 by default) less data points of any metric it collects. This setting can take values from `2` up to `255`. <br /> `N belongs to [1..4]` |
101
+| dbengine tier **`N`** back fill | `New` | Specifies the strategy of recreating missing data on each Tier from the exact lower Tier. <br /> `New`: Sees the latest point on each Tier and save new points to it only if the exact lower Tier has available points for it's observation window (`dbengine tier N update every iterations` window). <br /> `none`: No back filling is applied. <br /> `N belongs to [1..4]` |
102
+| memory deduplication (ksm) | `yes` | When set to `yes`, Netdata will offer its in-memory round robin database and the dbengine page cache to kernel same page merging (KSM) for deduplication. For more information check [Memory Deduplication - Kernel Same Page Merging - KSM](https://github.com/netdata/netdata/blob/master/database/README.md#ksm) |
103
+| cleanup obsolete charts after secs | `3600` | See [monitoring ephemeral containers](https://github.com/netdata/netdata/blob/master/collectors/cgroups.plugin/README.md#monitoring-ephemeral-containers), also sets the timeout for cleaning up obsolete dimensions |
104
+| gap when lost iterations above | `1` | |
105
+| cleanup orphan hosts after secs | `3600` | How long to wait until automatically removing from the DB a remote Netdata host (child) that is no longer sending data. |
106
+| delete obsolete charts files | `yes` | See [monitoring ephemeral containers](https://github.com/netdata/netdata/blob/master/collectors/cgroups.plugin/README.md#monitoring-ephemeral-containers), also affects the deletion of files for obsolete dimensions |
107
+| delete orphan hosts files | `yes` | Set to `no` to disable non-responsive host removal. |
108
+| enable zero metrics | `no` | Set to `yes` to show charts when all their metrics are zero. |
109
110
> ### Info
111
>
@@ -113,32 +113,32 @@ Please note that your data history will be lost if you have modified `history` p
113
114
### [directories] section options
115
116
-| setting | default | info |
117
-|:-------------------:|:------------------------------------------------------------------:|:----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
118
-| config | `/etc/netdata` | The directory configuration files are kept. |
119
-| stock config | `/usr/lib/netdata/conf.d` | |
120
-| log | `/var/log/netdata` | The directory in which the [log files](https://github.com/netdata/netdata/blob/master/daemon/README.md#log-files) are kept. |
121
-| web | `/usr/share/netdata/web` | The directory the web static files are kept. |
122
-| cache | `/var/cache/netdata` | The directory the memory database will be stored if and when Netdata exits. Netdata will re-read the database when it will start again, to continue from the same point. |
123
-| lib | `/var/lib/netdata` | Contains the alarm log and the Netdata instance GUID. |
124
-| home | `/var/cache/netdata` | Contains the db files for the collected metrics. |
125
-| lock | `/var/lib/netdata/lock` | Contains the data collectors lock files. |
126
-| plugins | `"/usr/libexec/netdata/plugins.d" "/etc/netdata/custom-plugins.d"` | The directory plugin programs are kept. This setting supports multiple directories, space separated. If any directory path contains spaces, enclose it in single or double quotes. |
127
-| health config | `/etc/netdata/health.d` | The directory containing the user alarm configuration files, to override the stock configurations |
128
-| stock health config | `/usr/lib/netdata/conf.d/health.d` | Contains the stock alarm configuration files for each collector |
129
-| registry | `/opt/netdata/var/lib/netdata/registry` | Contains the [registry](https://github.com/netdata/netdata/blob/master/registry/README.md) database and GUID that uniquely identifies each Netdata Agent |
116
+| setting | default | info |
117
+|:-------------------:|:------------------------------------------------------------------:|:-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
118
+| config | `/etc/netdata` | The directory configuration files are kept. |
119
+| stock config | `/usr/lib/netdata/conf.d` | |
120
+| log | `/var/log/netdata` | The directory in which the [log files](https://github.com/netdata/netdata/blob/master/daemon/README.md#log-files) are kept. |
121
+| web | `/usr/share/netdata/web` | The directory the web static files are kept. |
122
+| cache | `/var/cache/netdata` | The directory the memory database will be stored if and when Netdata exits. Netdata will re-read the database when it will start again, to continue from the same point. |
123
+| lib | `/var/lib/netdata` | Contains the alert log and the Netdata instance GUID. |
124
+| home | `/var/cache/netdata` | Contains the db files for the collected metrics. |
125
+| lock | `/var/lib/netdata/lock` | Contains the data collectors lock files. |
126
+| plugins | `"/usr/libexec/netdata/plugins.d" "/etc/netdata/custom-plugins.d"` | The directory plugin programs are kept. This setting supports multiple directories, space separated. If any directory path contains spaces, enclose it in single or double quotes. |
127
+| health config | `/etc/netdata/health.d` | The directory containing the user alert configuration files, to override the stock configurations |
128
+| stock health config | `/usr/lib/netdata/conf.d/health.d` | Contains the stock alert configuration files for each collector |
129
+| registry | `/opt/netdata/var/lib/netdata/registry` | Contains the [registry](https://github.com/netdata/netdata/blob/master/registry/README.md) database and GUID that uniquely identifies each Netdata Agent |
130
131
### [logs] section options
132
133
-| setting | default | info |
134
-|:----------------------------------:|:-----------------------------:|:-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
133
+| setting | default | info |
134
+|:----------------------------------:|:-----------------------------:|:---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
135
| debug flags | `0x0000000000000000` | Bitmap of debug options to enable. For more information check [Tracing Options](https://github.com/netdata/netdata/blob/master/daemon/README.md#debugging). |
136
| debug | `/var/log/netdata/debug.log` | The filename to save debug information. This file will not be created if debugging is not enabled. You can also set it to `syslog` to send the debug messages to syslog, or `none` to disable this log. For more information check [Tracing Options](https://github.com/netdata/netdata/blob/master/daemon/README.md#debugging). |
137
-| error | `/var/log/netdata/error.log` | The filename to save error messages for Netdata daemon and all plugins (`stderr` is sent here for all Netdata programs, including the plugins). You can also set it to `syslog` to send the errors to syslog, or `none` to disable this log. |
138
-| access | `/var/log/netdata/access.log` | The filename to save the log of web clients accessing Netdata charts. You can also set it to `syslog` to send the access log to syslog, or `none` to disable this log. |
139
-| facility | `daemon` | A facility keyword is used to specify the type of system that is logging the message. |
140
-| errors flood protection period | `1200` | Length of period (in sec) during which the number of errors should not exceed the `errors to trigger flood protection`. |
141
-| errors to trigger flood protection | `200` | Number of errors written to the log in `errors flood protection period` sec before flood protection is activated. |
137
+| error | `/var/log/netdata/error.log` | The filename to save error messages for Netdata daemon and all plugins (`stderr` is sent here for all Netdata programs, including the plugins). You can also set it to `syslog` to send the errors to syslog, or `none` to disable this log. |
138
+| access | `/var/log/netdata/access.log` | The filename to save the log of web clients accessing Netdata charts. You can also set it to `syslog` to send the access log to syslog, or `none` to disable this log. |
139
+| facility | `daemon` | A facility keyword is used to specify the type of system that is logging the message. |
140
+| errors flood protection period | `1200` | Length of period (in sec) during which the number of errors should not exceed the `errors to trigger flood protection`. |
141
+| errors to trigger flood protection | `200` | Number of errors written to the log in `errors flood protection period` sec before flood protection is activated. |
142
143
### [environment variables] section options
144
@@ -163,20 +163,20 @@ Please note that your data history will be lost if you have modified `history` p
163
164
This section controls the general behavior of the health monitoring capabilities of Netdata.
165
166
-Specific alarms are configured in per-collector config files under the `health.d` directory. For more info, see [health
166
+Specific alerts are configured in per-collector config files under the `health.d` directory. For more info, see [health
167
monitoring](https://github.com/netdata/netdata/blob/master/health/README.md).
168
169
-[Alarm notifications](https://github.com/netdata/netdata/blob/master/health/notifications/README.md) are configured in `health_alarm_notify.conf`.
169
+[Alert notifications](https://github.com/netdata/netdata/blob/master/health/notifications/README.md) are configured in `health_alarm_notify.conf`.
170
171
-| setting | default | info |
172
-|:----------------------------------------------:|:------------------------------------------------:|:-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
173
-| enabled | `yes` | Set to `no` to disable all alarms and notifications |
174
-| in memory max health log entries | 1000 | Size of the alarm history held in RAM |
175
-| script to execute on alarm | `/usr/libexec/netdata/plugins.d/alarm-notify.sh` | The script that sends alarm notifications. Note that in versions before 1.16, the plugins.d directory may be installed in a different location in certain OSs (e.g. under `/usr/lib/netdata`). |
176
-| run at least every seconds | `10` | Controls how often all alarm conditions should be evaluated. |
177
-| postpone alarms during hibernation for seconds | `60` | Prevents false alarms. May need to be increased if you get alarms during hibernation. |
178
-| health log history | `432000` | Specifies the history of alarm events (in seconds) kept in the agent's sqlite database. |
179
-| enabled alarms | * | Defines which alarms to load from both user and stock directories. This is a [simple pattern](https://github.com/netdata/netdata/blob/master/libnetdata/simple_pattern/README.md) list of alarm or template names. Can be used to disable specific alarms. For example, `enabled alarms = !oom_kill *` will load all alarms except `oom_kill`. |
171
+| setting | default | info |
172
+|:----------------------------------------------:|:------------------------------------------------:|:------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
173
+| enabled | `yes` | Set to `no` to disable all alerts and notifications |
174
+| in memory max health log entries | 1000 | Size of the alert history held in RAM |
175
+| script to execute on alarm | `/usr/libexec/netdata/plugins.d/alarm-notify.sh` | The script that sends alert notifications. Note that in versions before 1.16, the plugins.d directory may be installed in a different location in certain OSs (e.g. under `/usr/lib/netdata`). |
176
+| run at least every seconds | `10` | Controls how often all alert conditions should be evaluated. |
177
+| postpone alarms during hibernation for seconds | `60` | Prevents false alerts. May need to be increased if you get alerts during hibernation. |
178
+| health log history | `432000` | Specifies the history of alert events (in seconds) kept in the agent's sqlite database. |
179
+| enabled alarms | * | Defines which alerts to load from both user and stock directories. This is a [simple pattern](https://github.com/netdata/netdata/blob/master/libnetdata/simple_pattern/README.md) list of alert or template names. Can be used to disable specific alerts. For example, `enabled alarms = !oom_kill *` will load all alerts except `oom_kill`. |
180
181
### [web] section options
182
@@ -222,10 +222,10 @@ for all internal Netdata plugins.
222
223
External plugins will have only 2 options at `netdata.conf`:
224
225
-| setting | default | info |
226
-|:---------------:|:--------------------------------------------:|:------------------------------------------------------------------------------------------------------------------------------------------------------|
225
+| setting | default | info |
226
+|:---------------:|:--------------------------------------------:|:----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
227
| update every | the value of `[global].update every` setting | The frequency in seconds the plugin should collect values. For more information check the [performance guide](https://github.com/netdata/netdata/blob/master/docs/guides/configure/performance.md). |
228
-| command options | - | Additional command line options to pass to the plugin. | |
228
+| command options | - | Additional command line options to pass to the plugin. |
229
230
External plugins that need additional configuration may support a dedicated file in `/etc/netdata`. Check their
231
documentation.
docs/category-overview-pages/accessing-netdata-dashboards.md
+3
-3
@@ -7,7 +7,7 @@ A user accessing the Netdata dashboard **from the Cloud** will always be present
7
A user accessing the Netdata dashboard **from the Agent** will, by default, be presented with the latest Netdata dashboard version (the same as Netdata Cloud) except in the following scenarios:
8
* Agent doesn't have Internet access, and is unable to get the latest Netdata dashboards, as a result it falls back to the Netdata dashboard version that
9
was shipped with the agent.
10
-* Users have defined, e.g. through URL bookmark, that they wants to see the previous version of the dashboard (accessible `http://NODE:19999/v1`, replacing `NODE` with the IP address or hostname of your Agent).
10
+* Users have defined, e.g. through URL bookmark, that they want to see the previous version of the dashboard (accessible `http://NODE:19999/v1`, replacing `NODE` with the IP address or hostname of your Agent).
11
12
## Main sections
13
@@ -16,12 +16,12 @@ The Netdata dashboard consists of the following main sections:
16
* [Infrastructure Overview](https://github.com/netdata/netdata/blob/master/docs/visualize/overview-infrastructure.md)
17
* [Nodes view](https://github.com/netdata/netdata/blob/master/docs/cloud/visualize/nodes.md)
18
* [Custom dashboards](https://learn.netdata.cloud/docs/visualizations/custom-dashboards)
19
-* [Alerts](https://github.com/netdata/netdata/blob/master/docs/monitor/view-active-alarms.md)
19
+* [Alerts](https://github.com/netdata/netdata/blob/master/docs/monitor/view-active-alerts.md)
20
* [Anomaly Advisor](https://github.com/netdata/netdata/blob/master/docs/cloud/insights/anomaly-advisor.md)
21
* [Functions](https://github.com/netdata/netdata/blob/master/docs/cloud/netdata-functions.md)
22
* [Events feed](https://github.com/netdata/netdata/blob/master/docs/cloud/insights/events-feed.md)
23
24
-> ⚠️ Some sections of the dashboard, when accessed through the agent, may require the user to be signed-in to Netdata Cloud or having the Agent claimed to Netdata Cloud for their full functionality. Examples include saving visualization settings on charts or custom dashboards, claiming the node to Netdata Cloud, or executing functions on an Agent.
24
+> ⚠️ Some sections of the dashboard, when accessed through the agent, may require the user to be signed in to Netdata Cloud or having the Agent claimed to Netdata Cloud for their full functionality. Examples include saving visualization settings on charts or custom dashboards, claiming the node to Netdata Cloud, or executing functions on an Agent.
25
26
27
Documentation for previous Agent dashboard can still be found [here](https://github.com/netdata/netdata/blob/master/web/gui/README.md).
\ No newline at end of file
docs/category-overview-pages/deployment-strategies.md
+1
-1
@@ -265,4 +265,4 @@ We also suggest that you:
265
266
3. [Use host labels](https://github.com/netdata/netdata/blob/master/docs/guides/using-host-labels.md)
267
268
- To organize systems, metrics, and alarms.
268
+ To organize systems, metrics, and alerts.
docs/cloud/alerts-notifications/add-webhook-notification-configuration.md
+20
-20
@@ -42,23 +42,23 @@ Netdata webhook integration service will send alert notifications to the destina
42
43
The notification content sent to the destination service will be a JSON object having these properties:
44
45
-| field | type | description |
46
-| :-- | :-- | :-- |
47
-| message | string | A summary message of the alert. |
48
-| alarm | string | The alarm the notification is about. |
49
-| info | string | Additional info related with the alert. |
50
-| chart | string | The chart associated with the alert. |
51
-| context | string | The chart context. |
52
-| space | string | The space where the node that raised the alert is assigned. |
53
-| rooms | object[object(string,string)] | Object with list of rooms names and urls where the node belongs to. |
54
-| family | string | Context family. |
55
-| class | string | Classification of the alert, e.g. "Error". |
56
-| severity | string | Alert severity, can be one of "warning", "critical" or "clear". |
57
-| date | string | Date of the alert in ISO8601 format. |
58
-| duration | string | Duration the alert has been raised. |
59
-| additional_active_critical_alerts | integer | Number of additional critical alerts currently existing on the same node. |
60
-| additional_active_warning_alerts | integer | Number of additional warning alerts currently existing on the same node. |
61
-| alarm_url | string | Netdata Cloud URL for this alarm. |
45
+| field | type | description |
46
+|:----------------------------------|:------------------------------|:--------------------------------------------------------------------------|
47
+| message | string | A summary message of the alert. |
48
+| alarm | string | The alert the notification is about. |
49
+| info | string | Additional info related with the alert. |
50
+| chart | string | The chart associated with the alert. |
51
+| context | string | The chart context. |
52
+| space | string | The space where the node that raised the alert is assigned. |
53
+| rooms | object[object(string,string)] | Object with list of rooms names and urls where the node belongs to. |
54
+| family | string | Context family. |
55
+| class | string | Classification of the alert, e.g. "Error". |
56
+| severity | string | Alert severity, can be one of "warning", "critical" or "clear". |
57
+| date | string | Date of the alert in ISO8601 format. |
58
+| duration | string | Duration the alert has been raised. |
59
+| additional_active_critical_alerts | integer | Number of additional critical alerts currently existing on the same node. |
60
+| additional_active_warning_alerts | integer | Number of additional warning alerts currently existing on the same node. |
61
+| alarm_url | string | Netdata Cloud URL for this alert. |
62
63
### Extra headers
64
@@ -66,9 +66,9 @@ When setting up a webhook integration, the user can specify a set of headers to
66
67
By default, the following headers will be sent in the HTTP request
68
69
-| **Header** | **Value** |
70
-|:-------------------------------:|-----------------------------|
71
-| Content-Type | application/json |
69
+| **Header** | **Value** |
70
+|:------------:|------------------|
71
+| Content-Type | application/json |
72
73
### Authentication mechanisms
74
docs/cloud/alerts-notifications/notifications.md
+13
-13
@@ -8,7 +8,7 @@ you or your team.
8
9
Having this information centralized helps you:
10
* Have a clear view of the health across your infrastructure, seeing all alerts in one place.
11
-* Easily [setup your alert notification process](https://github.com/netdata/netdata/blob/master/docs/cloud/alerts-notifications/manage-notification-methods.md):
11
+* Easily [set up your alert notification process](https://github.com/netdata/netdata/blob/master/docs/cloud/alerts-notifications/manage-notification-methods.md):
12
methods to use and where to use them, filtering rules, etc.
13
* Quickly troubleshoot using [Metric Correlations](https://github.com/netdata/netdata/blob/master/docs/cloud/insights/metric-correlations.md)
14
or [Anomaly Advisor](https://github.com/netdata/netdata/blob/master/docs/cloud/insights/anomaly-advisor.md)
@@ -104,8 +104,8 @@ if the node should be silenced for the entire space or just for specific rooms (
104
105
### Scope definition for Alerts
106
* **Alert name:** silencing a specific alert name silences all alert state transitions for that specific alert.
107
-* **Alert context:** silencing a specific alert context will silence all alert state transitions for alerts targeting that chart context, for more details check [alert configuration docs](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md#alarm-line-on).
108
-* **Alert role:** silencing a specific alert role will silence all the alert state transitions for alerts that are configured to be specific role recipients, for more details check [alert configuration docs](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md#alarm-line-to).
107
+* **Alert context:** silencing a specific alert context will silence all alert state transitions for alerts targeting that chart context, for more details check [alert configuration docs](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md#alert-line-on).
108
+* **Alert role:** silencing a specific alert role will silence all the alert state transitions for alerts that are configured to be specific role recipients, for more details check [alert configuration docs](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md#alert-line-to).
109
110
Beside the above two main entities there are another two important settings that you can define on a silencing rule:
111
* Who does the rule affect? **All user** in the space or **Myself**
@@ -124,24 +124,24 @@ the local Agent dashboard at `http://NODE:19999`.
124
125
## Anatomy of an alert notification
126
127
-Email alarm notifications show the following information:
127
+Email alert notifications show the following information:
128
129
- The Space's name
130
- The node's name
131
-- Alarm status: critical, warning, cleared
132
-- Previous alarm status
133
-- Time at which the alarm triggered
134
-- Chart context that triggered the alarm
135
-- Name and information about the triggered alarm
136
-- Alarm value
131
+- Alert status: critical, warning, cleared
132
+- Previous alert status
133
+- Time at which the alert triggered
134
+- Chart context that triggered the alert
135
+- Name and information about the triggered alert
136
+- Alert value
137
- Total number of warning and critical alerts on that node
138
-- Threshold for triggering the given alarm state
138
+- Threshold for triggering the given alert state
139
- Calculation or database lookups that Netdata uses to compute the value
140
-- Source of the alarm, including which file you can edit to configure this alarm on an individual node
140
+- Source of the alert, including which file you can edit to configure this alert on an individual node
141
142
Email notifications also feature a **Go to Node** button, which takes you directly to the offending chart for that node
143
within Cloud's embedded dashboards.
144
145
Here's an example email notification for the `ram_available` chart, which is in a critical state:
146
147
-
147
+
docs/cloud/cheatsheet.md
+17
-17
@@ -99,13 +99,13 @@ modules:
99
sudo ./edit-config go.d/mysql.conf
100
```
101
102
-### Alarms & notifications
102
+### Alerts & notifications
103
104
-<!-- #### Add a new alarm
104
+<!-- #### Add a new alert
105
106
```
107
-sudo touch health.d/example-alarm.conf
108
-sudo ./edit-config health.d/example-alarm.conf
107
+sudo touch health.d/example-alert.conf
108
+sudo ./edit-config health.d/example-alert.conf
109
``` -->
110
After any change, reload the Netdata health configuration:
111
@@ -115,23 +115,23 @@ netdatacli reload-health
115
killall -USR2 netdata
116
```
117
118
-#### Configure a specific alarm
118
+#### Configure a specific alert
119
120
```bash
121
-sudo ./edit-config health.d/example-alarm.conf
121
+sudo ./edit-config health.d/example-alert.conf
122
```
123
124
-#### Silence a specific alarm
124
+#### Silence a specific alert
125
126
```bash
127
-sudo ./edit-config health.d/example-alarm.conf
127
+sudo ./edit-config health.d/example-alert.conf
128
```
129
130
```
131
to: silent
132
```
133
134
-<!-- #### Disable alarms and notifications
134
+<!-- #### Disable alerts and notifications
135
136
```conf
137
[health]
@@ -142,14 +142,14 @@ sudo ./edit-config health.d/example-alarm.conf
142
143
### Manage the daemon
144
145
-| Intent | Action |
146
-| :-------------------------- | --------------------------------------------------------------------: |
147
-| Start Netdata | `$ sudo service netdata start` |
148
-| Stop Netdata | `$ sudo service netdata stop` |
149
-| Restart Netdata | `$ sudo service netdata restart` |
150
-| Reload health configuration | `$ sudo netdatacli reload-health` `$ killall -USR2 netdata` |
151
-| View error logs | `less /var/log/netdata/error.log` |
152
-| View collectors logs | `less /var/log/netdata/collector.log` |
145
+| Intent | Action |
146
+|:----------------------------|------------------------------------------------------------:|
147
+| Start Netdata | `$ sudo service netdata start` |
148
+| Stop Netdata | `$ sudo service netdata stop` |
149
+| Restart Netdata | `$ sudo service netdata restart` |
150
+| Reload health configuration | `$ sudo netdatacli reload-health` `$ killall -USR2 netdata` |
151
+| View error logs | `less /var/log/netdata/error.log` |
152
+| View collectors logs | `less /var/log/netdata/collector.log` |
153
154
#### Change the port Netdata listens to (example, set it to port 39999)
155
docs/cloud/manage/sign-in.md
+3
-3
@@ -23,7 +23,7 @@ device, and sign in.
23
24
### Don't have a Netdata Cloud account yet?
25
26
-If you don't have a Netdata Cloud account yet you won't need to worry about it. During the sign in process we will create one for you and make the process seamless to you.
26
+If you don't already have a Netdata Cloud account, you don't need to worry about this. During the sign-in process we will create one for you and make the process seamless to you.
27
28
After your account is created and you sign in to Netdata, you first are asked to agree to Netdata Cloud's [Privacy
29
Policy](https://www.netdata.cloud/privacy/) and [Terms of Use](https://www.netdata.cloud/terms/). Once you agree with these you are directed
@@ -40,14 +40,14 @@ If you don't see the email, try the following:
40
- Check your spam folder.
41
- In Gmail, check the **Updates** category.
42
- Check [Netdata Cloud status](https://status.netdata.cloud) for ongoing issues with our infrastructure.
43
-- Request another sign in email via the [sign in page](https://app.netdata.cloud/sign-in?cloudRoute=spaces?utm_source=docs&utm_content=sign_in_button_troubleshooting_section).
43
+- Request another sign in email via the [sign-in page](https://app.netdata.cloud/sign-in?cloudRoute=spaces?utm_source=docs&utm_content=sign_in_button_troubleshooting_section).
44
45
You may also want to add `no-reply@netdata.cloud` to your address book or contacts list, especially if you're using
46
a public email service, such as Gmail. You may also want to whitelist/allowlist either the specific email or the entire
47
`netdata.cloud` domain.
48
49
In some cases, temporary issues with your mail server or email account may result in your email address being added to a Bounce list by Sendgrid.
50
-If you are added to that list, no Netdata cloud email can reach you, including alarm notifications. Let us know in Discord that you have trouble receiving
50
+If you are added to that list, no Netdata cloud email can reach you, including alert notifications. Let us know in Discord that you have trouble receiving
51
any email from us and someone will ask you to provide your email address privately, so we can check if you are on the Bounce list.
52
53
## Google and GitHub OAuth
docs/cloud/visualize/node-filter.md
+5
-9
@@ -4,15 +4,11 @@ The node filter allows you to quickly filter the nodes visualized in a War Room'
4
5
Inside the filter, the nodes get categorized into three groups:
6
7
-- Live nodes
8
- Nodes that are currently online, collecting and streaming metrics to Cloud.
9
- - Live nodes display raised [Alert](https://github.com/netdata/netdata/blob/master/docs/monitor/view-active-alarms.md) counters, [Machine Learning](https://github.com/netdata/netdata/blob/master/ml/README.md) availability, and [Functions](https://github.com/netdata/netdata/blob/master/docs/cloud/netdata-functions.md) availability
10
-- Stale nodes
11
- Nodes that are offline and not streaming metrics to Cloud. Only historical data can be presented from a parent node.
12
- - For these nodes you can only see their ML status, as they are not online to provide more information
13
-- Offline nodes
14
- Nodes that are offline, not streaming metrics to Cloud and not available in any parent node.
15
- Offline nodes are automatically deleted after 30 days and can also be deleted manually.
7
+| Group | Description |
8
+|---------|-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
9
+| Live | Nodes that are currently online, collecting and streaming metrics to Cloud. Live nodes display raised [Alert](https://github.com/netdata/netdata/blob/master/docs/monitor/view-active-alerts.md) counters, [Machine Learning](https://github.com/netdata/netdata/blob/master/ml/README.md) availability, and [Functions](https://github.com/netdata/netdata/blob/master/docs/cloud/netdata-functions.md) availability |
10
+| Stale | Nodes that are offline and not streaming metrics to Cloud. Only historical data can be presented from a parent node. For these nodes you can only see their ML status, as they are not online to provide more information |
11
+| Offline | Nodes that are offline, not streaming metrics to Cloud and not available in any parent node. Offline nodes are automatically deleted after 30 days and can also be deleted manually. |
12
13
By using the search bar, you can narrow down to specific nodes based on their name.
14
docs/cloud/visualize/nodes.md
+1
-1
@@ -7,7 +7,7 @@ to any node's dashboard for troubleshooting performance issues or anomalies usin
7
Cloud](https://user-images.githubusercontent.com/1153921/119035218-2eebb700-b964-11eb-8b74-4ec2df0e457c.png)
8
9
Each War Room's Nodes tab is populated based on the nodes you added to that specific War Room. Each node occupies a
10
-single row, first featuring that node's alarm status (yellow for warnings, red for critical alarms) and operating
10
+single row, first featuring that node's alert status (yellow for warnings, red for critical alerts) and operating
11
system, some essential information about the node, followed by columns of user-defined key metrics represented in
12
real-time charts.
13
docs/collect/container-metrics.md
+2
-2
@@ -71,13 +71,13 @@ _entirely for free_. These methods work together to help you troubleshoot perfor
71
your k8s infrastructure.
72
73
- A [Helm chart](https://github.com/netdata/helmchart), which bootstraps a Netdata Agent pod on every node in your
74
- cluster, plus an additional parent pod for storing metrics and managing alarm notifications.
74
+ cluster, plus an additional parent pod for storing metrics and managing alert notifications.
75
- A [service discovery plugin](https://github.com/netdata/agent-service-discovery), which discovers and creates
76
configuration files for [compatible
77
applications](https://github.com/netdata/helmchart#service-discovery-and-supported-services) and any endpoints
78
covered by our [generic Prometheus
79
collector](https://github.com/netdata/go.d.plugin/blob/master/modules/prometheus/README.md). With these
80
- configuration files, Netdata collects metrics from any compatible applications as they run _inside_ of a pod.
80
+ configuration files, Netdata collects metrics from any compatible applications as they run _inside_ a pod.
81
Service discovery happens without manual intervention as pods are created, destroyed, or moved between nodes.
82
- A [Kubelet collector](https://github.com/netdata/go.d.plugin/blob/master/modules/k8s_kubelet/README.md), which runs
83
on each node in a k8s cluster to monitor the number of pods/containers, the volume of operations on each container,
docs/configure/common-changes.md
+22
-23
@@ -64,45 +64,45 @@ of
64
To disable specific collectors, open `go.d.conf`, `python.d.conf` or `charts.d.conf` and find the line
65
for that specific module. Uncomment the line and change its value to `no`.
66
67
-## Modify alarms and notifications
67
+## Modify alerts and notifications
68
69
Netdata's health monitoring watchdog uses hundreds of preconfigured health entities, with intelligent thresholds, to
70
-generate warning and critical alarms for most production systems and their applications without configuration. However,
71
-each alarm and notification method is completely customizable.
70
+generate warning and critical alerts for most production systems and their applications without configuration. However,
71
+each alert and notification method is completely customizable.
72
73
-### Add a new alarm
73
+### Add a new alert
74
75
-To create a new alarm configuration file, initiate an empty file, with a filename that ends in `.conf`, in the
76
-`health.d/` directory. The Netdata Agent loads any valid alarm configuration file ending in `.conf` in that directory.
77
-Next, edit the new file with `edit-config`. For example, with a file called `example-alarm.conf`.
75
+To create a new alert configuration file, initiate an empty file, with a filename that ends in `.conf`, in the
76
+`health.d/` directory. The Netdata Agent loads any valid alert configuration file ending in `.conf` in that directory.
77
+Next, edit the new file with `edit-config`. For example, with a file called `example-alert.conf`.
78
79
```bash
80
-sudo touch health.d/example-alarm.conf
81
-sudo ./edit-config health.d/example-alarm.conf
80
+sudo touch health.d/example-alert.conf
81
+sudo ./edit-config health.d/example-alert.conf
82
```
83
84
-Or, append your new alarm to an existing file by editing a relevant existing file in the `health.d/` directory.
84
+Or, append your new alert to an existing file by editing a relevant existing file in the `health.d/` directory.
85
86
-Read more about [configuring alarms](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md) to
86
+Read more about [configuring alerts](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md) to
87
get started, and see
88
the [health monitoring reference](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md) for a full listing
89
of options available in health entities.
90
91
-### Configure a specific alarm
91
+### Configure a specific alert
92
93
-Tweak existing alarms by editing files in the `health.d/` directory. For example, edit `health.d/cpu.conf` to change how
93
+Tweak existing alerts by editing files in the `health.d/` directory. For example, edit `health.d/cpu.conf` to change how
94
the Agent responds to anomalies related to CPU utilization.
95
96
To see which configuration file you need to edit to configure a specific
97
-alarm, [view your active alarms](https://github.com/netdata/netdata/blob/master/docs/monitor/view-active-alarms.md) in
97
+alert, [view your active alerts](https://github.com/netdata/netdata/blob/master/docs/monitor/view-active-alerts.md) in
98
Netdata Cloud or the local Agent dashboard and look for the **source** line. For example, it might
99
read `source 4@/usr/lib/netdata/conf.d/health.d/cpu.conf`.
100
101
-Because the source path contains `health.d/cpu.conf`, run `sudo edit-config health.d/cpu.conf` to configure that alarm.
101
+Because the source path contains `health.d/cpu.conf`, run `sudo edit-config health.d/cpu.conf` to configure that alert.
102
103
-### Disable a specific alarm
103
+### Disable a specific alert
104
105
-Open the configuration file for that alarm and set the `to` line to `silent`.
105
+Open the configuration file for that alert and set the `to` line to `silent`.
106
107
```conf
108
template: disk_fill_rate
@@ -113,14 +113,13 @@ template: disk_fill_rate
113
to: silent
114
```
115
116
-### Turn of all alarms and notifications
116
+### Turn of all alerts and notifications
117
118
Set `enabled` to `no` in
119
-the [`[health]` section](https://github.com/netdata/netdata/blob/master/daemon/config/README.md#health-section-options)
120
-section of
121
-`netdata.conf`.
119
+the [`[health]`](https://github.com/netdata/netdata/blob/master/daemon/config/README.md#health-section-options)
120
+section of `netdata.conf`.
121
123
-### Enable alarm notifications
122
+### Enable alert notifications
123
124
Open `health_alarm_notify.conf` for editing. First, read the [enabling
125
notifications](https://github.com/netdata/netdata/blob/master/docs/monitor/enable-notifications.md#netdata-agent) doc
@@ -156,5 +155,5 @@ The following restrictions apply to host label names:
155
- Names only accept alphabet letters, numbers, dots, and dashes.
156
157
The policy for values is more flexible, but you can not use exclamation marks (`!`), whitespaces (` `), single quotes
159
-(`'`), double quotes (`"`), or asterisks (`*`), because they are used to compare label values in health alarms and
158
+(`'`), double quotes (`"`), or asterisks (`*`), because they are used to compare label values in health alerts and
159
templates.
docs/configure/nodes.md
+1
-1
@@ -42,7 +42,7 @@ exist.
42
**Application** charts from [`apps.plugin`](https://github.com/netdata/netdata/blob/master/collectors/apps.plugin/README.md) or
43
[`ebpf.plugin`](https://github.com/netdata/netdata/blob/master/collectors/ebpf.plugin/README.md).
44
- `health.d/` is a directory that contains [health configuration files](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md).
45
-- `health_alarm_notify.conf` enables and configures [alarm notifications](https://github.com/netdata/netdata/blob/master/docs/monitor/enable-notifications.md).
45
+- `health_alarm_notify.conf` enables and configures [alert notifications](https://github.com/netdata/netdata/blob/master/docs/monitor/enable-notifications.md).
46
- `statsd.d/` is a directory for configuring Netdata's [statsd collector](https://github.com/netdata/netdata/blob/master/collectors/statsd.plugin/README.md).
47
- `stream.conf` configures [parent-child streaming](https://github.com/netdata/netdata/blob/master/streaming/README.md) between separate nodes running the Agent.
48
- `.environment` is a hidden file that describes the environment in which the Netdata Agent is installed, including the
docs/contributing/style-guide.md
+9
-9
@@ -103,8 +103,8 @@ the sentence is action. In passive voice, the subject is acted upon. A famous ex
103
104
| | |
105
|-----------------|-------------------------------------------------------------------------------------------|
106
-| Not recommended | When an alarm is triggered by a metric, a notification is sent by Netdata. |
107
-| **Recommended** | When a metric triggers an alarm, Netdata sends a notification to your preferred endpoint. |
106
+| Not recommended | When an alert is triggered by a metric, a notification is sent by Netdata. |
107
+| **Recommended** | When a metric triggers an alert, Netdata sends a notification to your preferred endpoint. |
108
109
### Second person
110
@@ -470,7 +470,7 @@ The following tables describe the standard spelling, capitalization, and usage o
470
| Term | Definition |
471
|-----------------------------|-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
472
| **claimed node** | A node that you've proved ownership of by completing the [connecting to Cloud process](https://github.com/netdata/netdata/blob/master/claim/README.md). The claimed node will then appear in your Space and any War Rooms you added it to. |
473
-| **Netdata** | The company behind the open-source Netdata Agent and the Netdata Cloud web application. Never use _netdata_ or _NetData_. <br /><br />In general, focus on the user's goals, actions, and solutions rather than what the company provides. For example, write _Learn more about enabling alarm notifications on your preferred platforms_ instead of _Netdata sends alarm notifications to your preferred platforms_. |
473
+| **Netdata** | The company behind the open-source Netdata Agent and the Netdata Cloud web application. Never use _netdata_ or _NetData_. <br /><br />In general, focus on the user's goals, actions, and solutions rather than what the company provides. For example, write _Learn more about enabling alert notifications on your preferred platforms_ instead of _Netdata sends alert notifications to your preferred platforms_. |
474
| **Netdata Agent** | The free and open source [monitoring agent](https://github.com/netdata/netdata) that you can install on all of your distributed systems, whether they're physical, virtual, containerized, ephemeral, and more. The Agent monitors systems running Linux, Docker, Kubernetes, macOS, FreeBSD, and more, and collects metrics from hundreds of popular services and applications. |
475
| **Netdata Cloud** | The web application hosted at [https://app.netdata.cloud](https://app.netdata.cloud) that helps you monitor an entire infrastructure of distributed systems in real time. <br /><br />Never use _Cloud_ without the preceding _Netdata_ to avoid ambiguity. |
476
| **Netdata community forum** | The Discourse-powered forum for feature requests, Netdata Cloud technical support, and conversations about Netdata's monitoring and troubleshooting products. |
@@ -478,12 +478,12 @@ The following tables describe the standard spelling, capitalization, and usage o
478
| **Space** | The highest level container within Netdata Cloud for a user to organize their team members and nodes within their infrastructure. A Space likely represents an entire organization or a large team. <br /><br />_Space_ is always capitalized. |
479
| **unreachable node** | A connected node with a disrupted [Agent-Cloud link](https://github.com/netdata/netdata/blob/master/aclk/README.md). Unreachable could mean the node no longer exists or is experiencing network connectivity issues with Cloud. |
480
| **visited node** | A node which has had its Agent dashboard directly visited by a user. A list of these is maintained on a per-user basis. |
481
-| **War Room** | A smaller grouping of nodes where users can view key metrics in real-time and monitor the health of many nodes with their alarm status. War Rooms can be used to organize nodes in any way that makes sense for your infrastructure, such as by a service, purpose, physical location, and more. <br /><br />_War Room_ is always capitalized. |
481
+| **War Room** | A smaller grouping of nodes where users can view key metrics in real-time and monitor the health of many nodes with their alert status. War Rooms can be used to organize nodes in any way that makes sense for your infrastructure, such as by a service, purpose, physical location, and more. <br /><br />_War Room_ is always capitalized. |
482
483
### Other technical terms
484
485
-| Term | Definition |
486
-|-----------------------------|---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
487
-| **filesystem** | Use instead of _file system_. |
488
-| **preconfigured** | The concept that many of Netdata's features come with sane defaults that users don't need to configure to find immediate value. |
489
-| **real time**/**real-time** | Use _real time_ as a noun phrase, most often with _in_: _Netdata collects metrics in real time_. Use _real-time_ as an adjective: _Netdata collects real-time metrics from hundreds of supported applications and services. |
485
+| Term | Definition |
486
+|-----------------------------|-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
487
+| **filesystem** | Use instead of _file system_. |
488
+| **preconfigured** | The concept that many of Netdata's features come with sane defaults that users don't need to configure to find immediate value. |
489
+| **real time**/**real-time** | Use _real time_ as a noun phrase, most often with _in_: _Netdata collects metrics in real time_. Use _real-time_ as an adjective: _Netdata collects real-time metrics from hundreds of supported applications and services. |
docs/dashboard/dimensions-contexts-families.md
+4
-4
@@ -5,7 +5,7 @@ they have a lot of underlying complexity. To meaningfully organize charts out of
5
your nodes, Netdata uses the concepts of **dimensions**, **contexts**, and **families**.
6
7
Understanding how these work will help you more easily navigate the dashboard,
8
-[write new alarms](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md), or play around
8
+[write new alerts](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md), or play around
9
with the [API](https://github.com/netdata/netdata/blob/master/web/api/README.md).
10
11
## Dimension
@@ -42,8 +42,8 @@ whereas anything after the `.` is specified either by the chart's developer or b
42
43
By default, a chart's type affects where it fits in the menu, while its family creates submenus.
44
45
-Netdata also relies on contexts for [alarm configuration](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md) (the [`on`
46
-line](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md#alarm-line-on)).
45
+Netdata also relies on contexts for [alert configuration](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md) (the [`on`
46
+line](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md#alert-line-on)).
47
48
## Family
49
@@ -62,7 +62,7 @@ Given the four example contexts, and two families of `sda` and `sdb`, Netdata wi
62
names:
63
64
| Context | `sda` family | `sdb` family |
65
-| :------------- | ------------------ | ------------------ |
65
+|:---------------|--------------------|--------------------|
66
| `disk.io` | `disk_io.sda` | `disk_io.sdb` |
67
| `disk.ops` | `disk_ops.sda` | `disk_ops.sdb` |
68
| `disk.backlog` | `disk_backlog.sda` | `disk_backlog.sdb` |
docs/dashboard/import-export-print-snapshot.md
+2
-2
@@ -18,8 +18,8 @@ Netdata can export snapshots of the contents of your dashboard at a given time,
18
node running Netdata. Or, you can create a print-ready version of your dashboard to save to PDF or actually print to
19
paper.
20
21
-Snapshots can be incredibly useful for diagnosing anomalies after they've already happened. Let's say Netdata triggered a warning alarm while you were asleep. In the morning, you can [select the
22
-timeframe](https://github.com/netdata/netdata/blob/master/docs/dashboard/visualization-date-and-time-controls.md) when the alarm triggered, export a snapshot, and send it to a
21
+Snapshots can be incredibly useful for diagnosing anomalies after they've already happened. Let's say Netdata triggered a warning alert while you were asleep. In the morning, you can [select the
22
+timeframe](https://github.com/netdata/netdata/blob/master/docs/dashboard/visualization-date-and-time-controls.md) when the alert triggered, export a snapshot, and send it to a
23
24
colleague for further analysis.
25
docs/getting-started/introduction.md
+6
-6
@@ -17,7 +17,7 @@ Netdata is:
17
- **One-line deployment** for Linux distributions, plus support for Kubernetes/Docker infrastructures.
18
- **Zero configuration and maintenance** required to collect thousands of metrics, every second, from the underlying
19
OS and running applications.
20
-- **Prebuilt charts and alarms** alert you to common anomalies and performance issues without manual configuration.
20
+- **Prebuilt charts and alerts** alert you to common anomalies and performance issues without manual configuration.
21
- **Distributed storage** to simplify the cost and complexity of storing metrics data from any number of nodes.
22
23
### Powerful and scalable
@@ -48,7 +48,7 @@ Netdata offers many benefits over the existing monitoring landscape, whether the
48
open-source tools.
49
50
| Netdata | Others (open-source and commercial) |
51
-| :-------------------------------------------------------------- | :--------------------------------------------------------------- |
51
+|:----------------------------------------------------------------|:-----------------------------------------------------------------|
52
| **High resolution metrics** (1s granularity) | Low resolution metrics (10s granularity at best) |
53
| Collects **thousands of metrics per node** | Collects just a few metrics |
54
| Fast UI optimized for **anomaly detection** | UI is good for just an abstract view |
@@ -64,7 +64,7 @@ Netdata works with tons of applications, notifications platforms, and other time
64
- **300+ system, container, and application endpoints**: Collectors autodetect metrics from default endpoints and
65
immediately visualize them into meaningful charts designed for troubleshooting. See [everything we
66
support](https://github.com/netdata/netdata/blob/master/collectors/COLLECTORS.md).
67
-- **20+ notification platforms**: Netdata's health watchdog sends warning and critical alarms to your [favorite
67
+- **20+ notification platforms**: Netdata's health watchdog sends warning and critical alerts to your [favorite
68
platform](https://github.com/netdata/netdata/blob/master/docs/monitor/enable-notifications.md) to inform you of anomalies just seconds
69
after they affect your node.
70
- **30+ external time-series databases**: Export resampled metrics as they're collected to other [local- and
@@ -96,9 +96,9 @@ You can install Netdata on most Linux distributions (Ubuntu, Debian, CentOS, and
96
97
### Netdata Cloud
98
99
-Netdata Cloud is a web application that gives you real-time visibility for your entire infrastructure. With Netdata Cloud, you can view key metrics, insightful charts, and active alarms from all your nodes in a single web interface. When an anomaly strikes, seamlessly navigate to any node to troubleshoot and discover the root cause with the familiar Netdata dashboard.
99
+Netdata Cloud is a web application that gives you real-time visibility for your entire infrastructure. With Netdata Cloud, you can view key metrics, insightful charts, and active alerts from all your nodes in a single web interface. When an anomaly strikes, seamlessly navigate to any node to troubleshoot and discover the root cause with the familiar Netdata dashboard.
100
101
-Netdata Cloud is free! You can add an entire infrastructure of nodes, invite all your colleagues, and visualize any number of metrics, charts, and alarms entirely for free.
101
+Netdata Cloud is free! You can add an entire infrastructure of nodes, invite all your colleagues, and visualize any number of metrics, charts, and alerts entirely for free.
102
103
While Netdata Cloud offers a centralized method of monitoring your Agents, your metrics data is not stored or centralized in any way. Metrics data remains with your nodes and is only streamed to your browser, through Cloud, when you're viewing the Netdata Cloud interface.
104
@@ -189,5 +189,5 @@ _When people first hear about a new product, they frequently ask if it is any go
189
[remarked](https://news.ycombinator.com/item?id=3067434):_
190
191
> Note to self: Starting immediately, all raganwald projects will have a “Is it any good?” section in the readme, and
192
-> the answer shall be “yes.".
192
+> the answer shall be "yes.".
193
*******************************************************************************
docs/glossary.md
+2
-2
@@ -33,7 +33,7 @@ Use the alphabatized list below to find the answer to your single-term questions
33
34
- [**Child**](https://github.com/netdata/netdata/blob/master/docs/metrics-storage-management/enable-streaming.md#streaming-basics): A node, running Netdata, that streams metric data to one or more parent.
35
36
-- [**Cloud** or **Netdata Cloud**](https://github.com/netdata/netdata/blob/master/docs/quickstart/infrastructure.md): Netdata Cloud is a web application that gives you real-time visibility for your entire infrastructure. With Netdata Cloud, you can view key metrics, insightful charts, and active alarms from all your nodes in a single web interface.
36
+- [**Cloud** or **Netdata Cloud**](https://github.com/netdata/netdata/blob/master/docs/quickstart/infrastructure.md): Netdata Cloud is a web application that gives you real-time visibility for your entire infrastructure. With Netdata Cloud, you can view key metrics, insightful charts, and active alerts from all your nodes in a single web interface.
37
38
- [**Collector**](https://github.com/netdata/netdata/blob/master/collectors/README.md#collector-architecture-and-terminology): A catch-all term for any Netdata process that gathers metrics from an endpoint.
39
@@ -114,7 +114,7 @@ metrics, troubleshoot complex performance problems, and make data interoperable
114
115
- [**Netdata Agent** or **Agent**](https://github.com/netdata/netdata/blob/master/packaging/installer/README.md): Netdata's distributed monitoring Agent collects thousands of metrics from systems, hardware, and applications with zero configuration. It runs permanently on all your physical/virtual servers, containers, cloud deployments, and edge/IoT devices.
116
117
-- [**Netdata Cloud** or **Cloud**](https://github.com/netdata/netdata/blob/master/docs/quickstart/infrastructure.md): Netdata Cloud is a web application that gives you real-time visibility for your entire infrastructure. With Netdata Cloud, you can view key metrics, insightful charts, and active alarms from all your nodes in a single web interface.
117
+- [**Netdata Cloud** or **Cloud**](https://github.com/netdata/netdata/blob/master/docs/quickstart/infrastructure.md): Netdata Cloud is a web application that gives you real-time visibility for your entire infrastructure. With Netdata Cloud, you can view key metrics, insightful charts, and active alerts from all your nodes in a single web interface.
118
119
- [**Netdata Functions** or **Functions**](https://github.com/netdata/netdata/blob/master/docs/cloud/netdata-functions.md): Routines exposed by a collector on the Netdata Agent that can bring additional information to support troubleshooting or trigger some action to happen on the node itself.
120
docs/guides/collect-apache-nginx-web-logs.md
+4
-4
@@ -94,13 +94,13 @@ We do have [extensive
94
documentation](https://github.com/netdata/go.d.plugin/blob/master/modules/weblog/README.md#custom-log-format) on how
95
to build custom parsing for Nginx and Apache logs.
96
97
-## Tweak web log collector alarms
97
+## Tweak web log collector alerts
98
99
-Over time, we've created some default alarms for web log monitoring. These alarms are designed to work only when your
99
+Over time, we've created some default alerts for web log monitoring. These alerts are designed to work only when your
100
web server is receiving more than 120 requests per minute. Otherwise, there's simply not enough data to make conclusions
101
about what is "too few" or "too many."
102
103
-- [web log alarms](https://raw.githubusercontent.com/netdata/netdata/master/health/health.d/web_log.conf).
103
+- [web log alerts](https://raw.githubusercontent.com/netdata/netdata/master/health/health.d/web_log.conf).
104
105
You can also edit this file directly with `edit-config`:
106
@@ -108,5 +108,5 @@ You can also edit this file directly with `edit-config`:
108
./edit-config health.d/weblog.conf
109
```
110
111
-For more information about editing the defaults or writing new alarm entities, see our
111
+For more information about editing the defaults or writing new alert entities, see our
112
[health monitoring documentation](https://github.com/netdata/netdata/blob/master/health/README.md).
docs/guides/monitor-cockroachdb.md
+4
-4
@@ -28,7 +28,7 @@ Let's dive in and walk through the process of monitoring CockroachDB metrics wit
28
- [What's in this guide](#whats-in-this-guide)
29
- [Configure the CockroachDB collector](#configure-the-cockroachdb-collector)
30
- [Manual setup for a local CockroachDB database](#manual-setup-for-a-local-cockroachdb-database)
31
- - [Tweak CockroachDB alarms](#tweak-cockroachdb-alarms)
31
+ - [Tweak CockroachDB alerts](#tweak-cockroachdb-alerts)
32
33
## Configure the CockroachDB collector
34
@@ -102,9 +102,9 @@ Netdata to see your new charts.
102
<figcaption>Charts showing a node failure during a simulated test</figcaption>
103
</figure>
104
105
-## Tweak CockroachDB alarms
105
+## Tweak CockroachDB alerts
106
107
-This release also includes eight pre-configured alarms for live nodes, such as whether the node is live, storage
107
+This release also includes eight pre-configured alerts for live nodes, such as whether the node is live, storage
108
capacity, issues with replication, and the number of SQL connections/statements. See [health.d/cockroachdb.conf on
109
GitHub](https://raw.githubusercontent.com/netdata/netdata/master/health/health.d/cockroachdb.conf) for details.
110
@@ -115,4 +115,4 @@ cd /etc/netdata/ # Replace with your Netdata configuration directory, if not /et
115
./edit-config health.d/cockroachdb.conf # You may need to use `sudo` for write privileges
116
```
117
118
-For more information about editing the defaults or writing new alarm entities, see our documentation on [configuring health alarms](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md).
118
+For more information about editing the defaults or writing new alert entities, see our documentation on [configuring health alerts](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md).
docs/guides/monitor-hadoop-cluster.md
+5
-5
@@ -173,13 +173,13 @@ sudo systemctl restart netdata
173
Upon restart, Netdata should recognize your HDFS/Zookeeper servers, enable the HDFS and Zookeeper modules, and begin
174
showing real-time metrics for both in your Netdata dashboard. 🎉
175
176
-## Configuring HDFS and Zookeeper alarms
176
+## Configuring HDFS and Zookeeper alerts
177
178
-The Netdata community helped us create sane defaults for alarms related to both HDFS and Zookeeper. You may want to
178
+The Netdata community helped us create sane defaults for alerts related to both HDFS and Zookeeper. You may want to
179
investigate these to ensure they work well with your Hadoop implementation.
180
181
-- [HDFS alarms](https://raw.githubusercontent.com/netdata/netdata/master/health/health.d/hdfs.conf)
182
-- [Zookeeper alarms](https://raw.githubusercontent.com/netdata/netdata/master/health/health.d/zookeeper.conf)
181
+- [HDFS alerts](https://raw.githubusercontent.com/netdata/netdata/master/health/health.d/hdfs.conf)
182
+- [Zookeeper alerts](https://raw.githubusercontent.com/netdata/netdata/master/health/health.d/zookeeper.conf)
183
184
You can also access/edit these files directly with `edit-config`:
185
@@ -188,5 +188,5 @@ sudo /etc/netdata/edit-config health.d/hdfs.conf
188
sudo /etc/netdata/edit-config health.d/zookeeper.conf
189
```
190
191
-For more information about editing the defaults or writing new alarm entities, see our
191
+For more information about editing the defaults or writing new alert entities, see our
192
[health monitoring documentation](https://github.com/netdata/netdata/blob/master/health/README.md).
docs/guides/monitor/anomaly-detection.md
+4
-4
@@ -53,13 +53,13 @@ Pressing the anomalies icon (next to the information icon in the chart header) w
53
54
## Anomaly Rate Based Alerts
55
56
-It is possible to use the `anomaly-bit` when defining traditional Alerts within netdata. The `anomaly-bit` is just another `options` parameter that can be passed as part of an [alarm line lookup](https://github.com/netdata/netdata/blob/master/docs/configure/start-stop-restart.md#alarm-line-lookup).
56
+It is possible to use the `anomaly-bit` when defining traditional Alerts within netdata. The `anomaly-bit` is just another `options` parameter that can be passed as part of an [alert line lookup](https://github.com/netdata/netdata/blob/master/docs/configure/start-stop-restart.md#alert-line-lookup).
57
58
You can see some example ML based alert configurations below:
59
60
-- [Anomaly rate based CPU dimensions alarm](https://github.com/netdata/netdata/blob/master/docs/configure/start-stop-restart.md#example-8---anomaly-rate-based-cpu-dimensions-alarm)
61
-- [Anomaly rate based CPU chart alarm](https://github.com/netdata/netdata/blob/master/docs/configure/start-stop-restart.md#example-9---anomaly-rate-based-cpu-chart-alarm)
62
-- [Anomaly rate based node level alarm](https://github.com/netdata/netdata/blob/master/docs/configure/start-stop-restart.md#example-10---anomaly-rate-based-node-level-alarm)
60
+- [Anomaly rate based CPU dimensions alert](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md#example-8---anomaly-rate-based-cpu-dimensions-alert)
61
+- [Anomaly rate based CPU chart alert](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md#example-9---anomaly-rate-based-cpu-chart-alert)
62
+- [Anomaly rate based node level alert](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md#example-10---anomaly-rate-based-node-level-alert)
63
- More examples in the [`/health/health.d/ml.conf`](https://github.com/netdata/netdata/blob/master/health/health.d/ml.conf) file that ships with the agent.
64
65
## Learn More
docs/guides/monitor/lamp-stack.md
+7
-7
@@ -34,7 +34,7 @@ of required setup.
34
In this tutorial, you'll set up robust LAMP stack monitoring with Netdata in just a few minutes. When you're done,
35
you'll have one dashboard to monitor every part of your web application, including each essential LAMP stack service.
36
37
-This dashboard updates every second with new metrics, and pairs those metrics up with preconfigured alarms to keep you
37
+This dashboard updates every second with new metrics, and pairs those metrics up with preconfigured alerts to keep you
38
informed of any errors or odd behavior.
39
40
## What you need to get started
@@ -192,18 +192,18 @@ Here's a quick reference for what charts you might want to focus on after settin
192
| Active Connections (`mysql_local.connections_active`) | MySQL monitoring | If the `active` dimension nears the `limit`, your MySQL database will bottleneck responses. |
193
| Performance (phpfpm_local.performance) | PHP monitoring | The `slow requests` dimension lets you know if any requests exceed the configured `request_slowlog_timeout`. If so, users might be having a less-than-ideal experience. |
194
195
-## Get alarms for LAMP stack errors
195
+## Get alerts for LAMP stack errors
196
197
-The Netdata Agent comes with hundreds of pre-configured alarms to help you keep tabs on your system, including 19 alarms
197
+The Netdata Agent comes with hundreds of pre-configured alerts to help you keep tabs on your system, including 19 alerts
198
designed for smarter LAMP stack monitoring.
199
200
-Click the 🔔 icon in the top navigation to [see active alarms](https://github.com/netdata/netdata/blob/master/docs/monitor/view-active-alarms.md). The **Active** tabs
201
-shows any alarms currently triggered, while the **All** tab displays a list of _every_ pre-configured alarm. The
200
+Click the 🔔 icon in the top navigation to [see active alerts](https://github.com/netdata/netdata/blob/master/docs/monitor/view-active-alerts.md). The **Active** tabs
201
+shows any alerts currently triggered, while the **All** tab displays a list of _every_ pre-configured alert. The
202
203
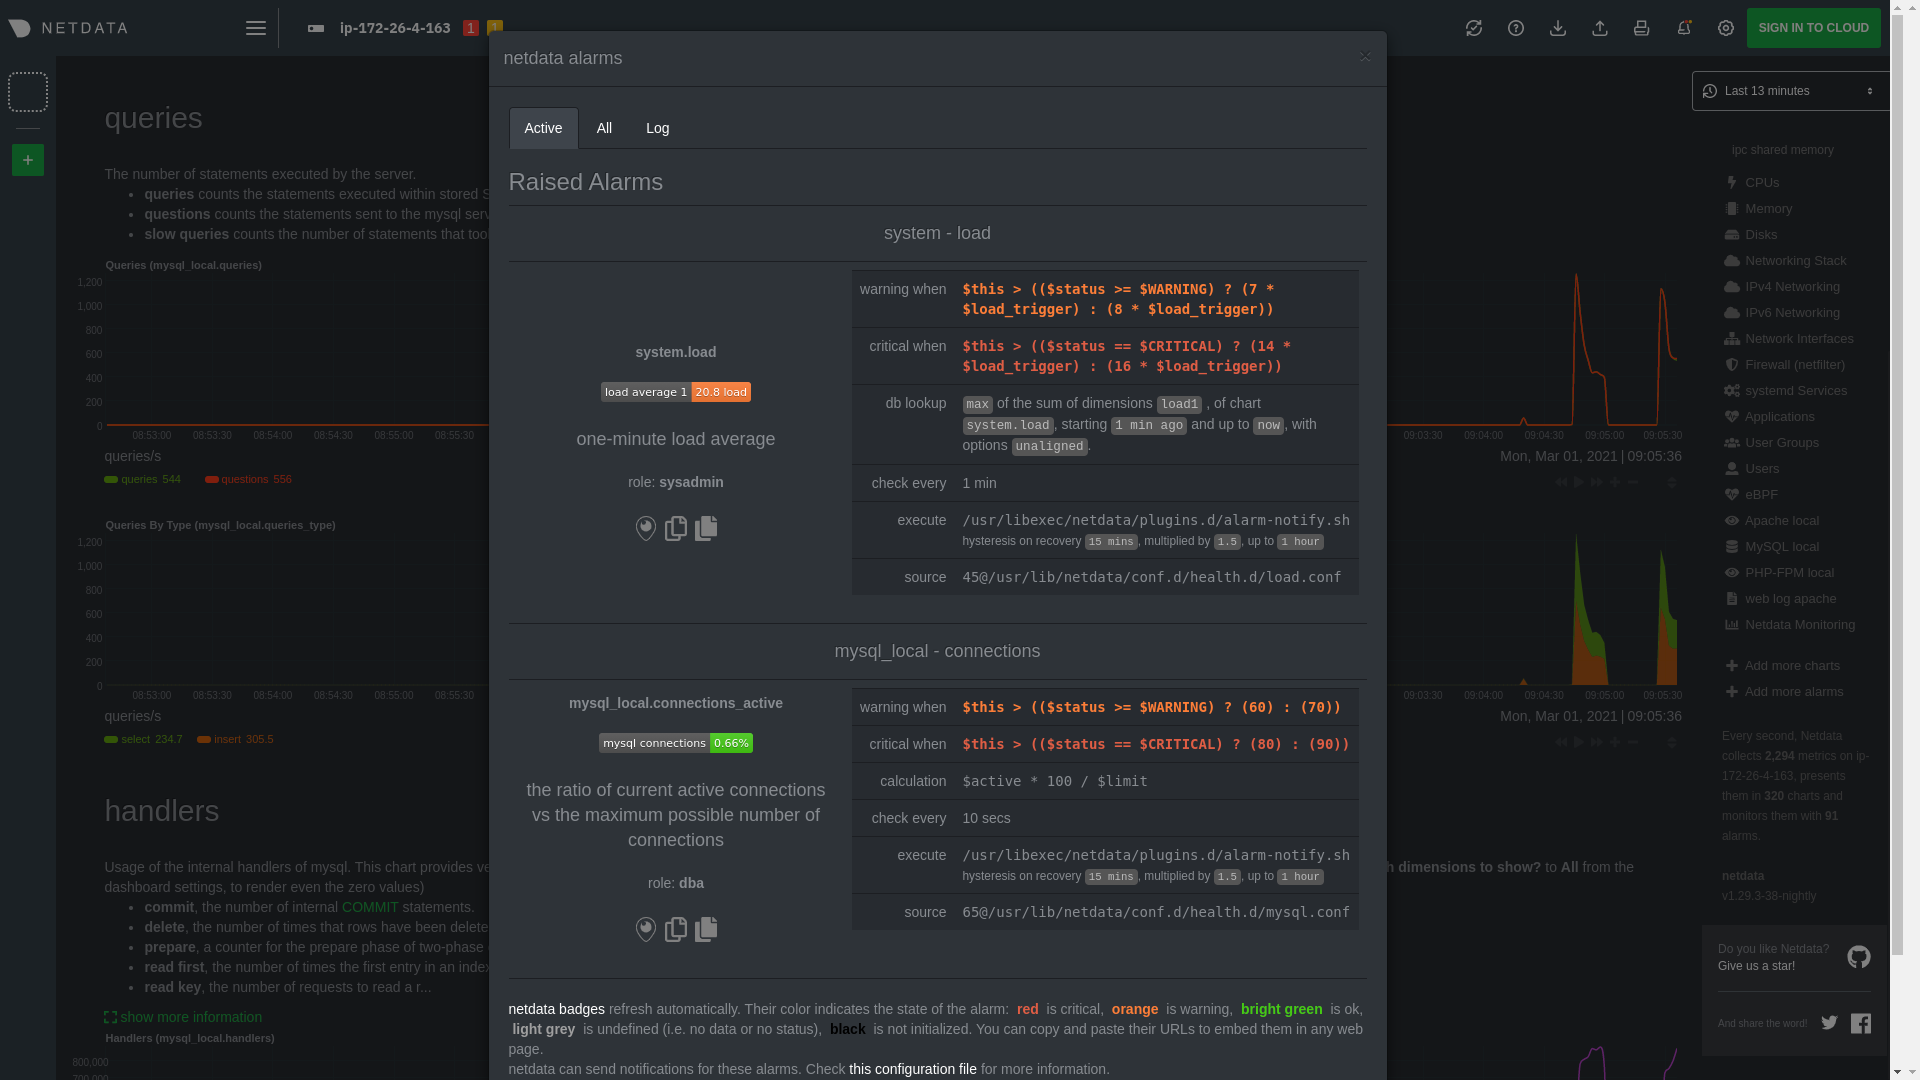
204
+alerts](https://user-images.githubusercontent.com/1153921/109524120-5883f900-7a6d-11eb-830e-0e7baaa28163.png)
205
206
-[Tweak alarms](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md) based on your infrastructure monitoring needs, and to see these alarms
206
+[Tweak alerts](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md) based on your infrastructure monitoring needs, and to see these alerts
207
in other places, like your inbox or a Slack channel, [enable a notification
208
method](https://github.com/netdata/netdata/blob/master/docs/monitor/enable-notifications.md).
209
docs/guides/python-collector.md
+2
-2
@@ -16,7 +16,7 @@ Golang is more performant, easier to maintain, and simpler for users since it do
16
execute. Python plugins require Python on the machine to be executed. Netdata uses Go as the platform of choice for
17
production-grade collectors.
18
19
-We generally do not accept contributions of Python modules to the Github project netdata/netdata. If you write a Python collector and
19
+We generally do not accept contributions of Python modules to the GitHub project netdata/netdata. If you write a Python collector and
20
want to make it available for other users, you should create the pull request in https://github.com/netdata/community.
21
22
## What you need to get started
@@ -540,7 +540,7 @@ At minimum, to be buildable and testable, the PR needs to include:
540
- A makefile for the plugin at `collectors/python.d.plugin/<module_dir>/Makefile.inc`. Check an existing plugin for what this should look like.
541
- A line in `collectors/python.d.plugin/Makefile.am` including the above-mentioned makefile. Place it with the other plugin includes (please keep the includes sorted alphabetically).
542
- Optionally, chart information in `web/gui/dashboard_info.js`. This generally involves specifying a name and icon for the section, and may include descriptions for the section or individual charts.
543
-- Optionally, some default alarm configurations for your collector in `health/health.d/<module_name>.conf` and a line adding `<module_name>.conf` in `health/Makefile.am`.
543
+- Optionally, some default alert configurations for your collector in `health/health.d/<module_name>.conf` and a line adding `<module_name>.conf` in `health/Makefile.am`.
544
545
## Framework class reference
546
docs/guides/using-host-labels.md
+4
-4
@@ -41,7 +41,7 @@ To define your windows server as a virtual node you need to:
41
42
Host labels can be extremely useful when:
43
44
-- You need alarms that adapt to the system's purpose
44
+- You need alerts that adapt to the system's purpose
45
- You need properly-labeled metrics archiving so you can sort, correlate, and mash-up your data to your heart's content.
46
- You need to keep tabs on ephemeral Docker containers in a Kubernetes cluster.
47
@@ -149,7 +149,7 @@ exporting. Speaking of which...
149
### Host labels in alerts
150
151
You can use host labels to logically organize your systems by their type, purpose, or location, and then apply specific
152
-alarms to them.
152
+alerts to them.
153
154
For example, let's use configuration example from earlier:
155
@@ -178,7 +178,7 @@ Or, by using one of the automatic labels, for only webserver systems running a s
178
host labels: _os_name = Debian*
179
```
180
181
-In a streaming configuration where a parent node is triggering alarms for its child nodes, you could create health
181
+In a streaming configuration where a parent node is triggering alerts for its child nodes, you could create health
182
entities that apply only to child nodes:
183
184
```yaml
@@ -192,7 +192,7 @@ Or when ephemeral Docker nodes are involved:
192
```
193
194
Of course, there are many more possibilities for intuitively organizing your systems with host labels. See the [health
195
-documentation](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md#alarm-line-host-labels) for more details, and then get creative!
195
+documentation](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md#alert-line-host-labels) for more details, and then get creative!
196
197
### Host labels in metrics exporting
198
docs/metrics-storage-management/enable-streaming.md
+5
-5
@@ -5,7 +5,7 @@ replicate metrics data across multiple nodes, or centralize all your metrics dat
5
(TSDB).
6
7
When one node streams metrics to another, the node receiving metrics can visualize them on the dashboard, run health checks to
8
-[trigger alarms](https://github.com/netdata/netdata/blob/master/docs/monitor/view-active-alarms.md) and
8
+[trigger alerts](https://github.com/netdata/netdata/blob/master/docs/monitor/view-active-alerts.md) and
9
[send notifications](https://github.com/netdata/netdata/blob/master/docs/monitor/enable-notifications.md), and
10
[export](https://github.com/netdata/netdata/blob/master/docs/export/external-databases.md) all metrics to an external TSDB. When Netdata streams metrics to another
11
Netdata, the receiving one is able to perform everything a Netdata instance is capable of.
@@ -48,16 +48,16 @@ Here are a few example streaming configurations:
48
- **Headless collector**:
49
- Child `A`, _without_ a database or web dashboard, streams metrics to parent `B`.
50
- `A` metrics are only available via the local Agent dashboard for `B`.
51
- - `B` generates alarms for `A`.
51
+ - `B` generates alerts for `A`.
52
- **Replication**:
53
- Child `A`, _with_ a database and web dashboard, streams metrics to parent `B`.
54
- `A` metrics are available on both local Agent dashboards, and can be stored with the same or different metrics
55
retention policies.
56
- - Both `A` and `B` generate alarms.
56
+ - Both `A` and `B` generate alerts.
57
- **Proxy**:
58
- Child `A`, _with or without_ a database, sends metrics to proxy `C`, also _with or without_ a database. `C` sends
59
metrics to parent `B`.
60
- - Any node with a database can generate alarms.
60
+ - Any node with a database can generate alerts.
61
62
63
@@ -102,7 +102,7 @@ parent node, and both nodes retain metrics in their own databases.
102
To configure replication, you need two nodes, each running Netdata. First you'll first enable streaming on your parent
103
node, then enable streaming on your child node. When you're finished, you'll be able to see the child node's metrics in
104
the parent node's dashboard, quickly switch between the two dashboards, and be able to serve
105
-[alarm notifications](https://github.com/netdata/netdata/blob/master/docs/monitor/enable-notifications.md) from either or both nodes.
105
+[alert notifications](https://github.com/netdata/netdata/blob/master/docs/monitor/enable-notifications.md) from either or both nodes.
106
107
### Enable streaming on the parent node
108
docs/monitor/enable-notifications.md
+1
-1
@@ -1,6 +1,6 @@
1
<!--
2
title: "Alert notifications"
3
-description: "Send Netdata alarms from a centralized place with Netdata Cloud, or configure nodes individually, to enable incident response and faster resolution."
3
+description: "Send Netdata alerts from a centralized place with Netdata Cloud, or configure nodes individually, to enable incident response and faster resolution."
4
custom_edit_url: "https://github.com/netdata/netdata/edit/master/docs/monitor/enable-notifications.md"
5
sidebar_label: "Notify"
6
learn_status: "Published"
docs/monitor/view-active-alerts.md
renamed
+11
-11
@@ -43,28 +43,28 @@ At the bottom of the panel you can click the green button "View dedicated alert
43
<!--
44
## Local Netdata Agent dashboard
45
46
-Find the alarms icon 
48
-in the top navigation to bring up a modal that shows currently raised alarms, all running alarms, and the alarms log.
49
-Here is an example of a raised `system.cpu` alarm, followed by the full list and alarm log:
48
+in the top navigation to bring up a modal that shows currently raised alerts, all running alerts, and the alerts log.
49
+Here is an example of a raised `system.cpu` alert, followed by the full list and alert log:
50
51
-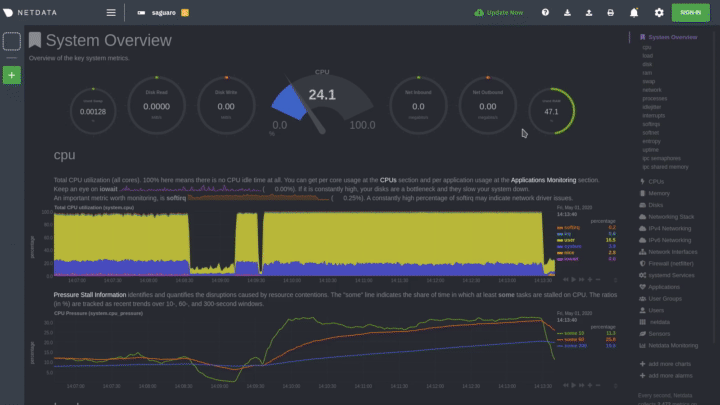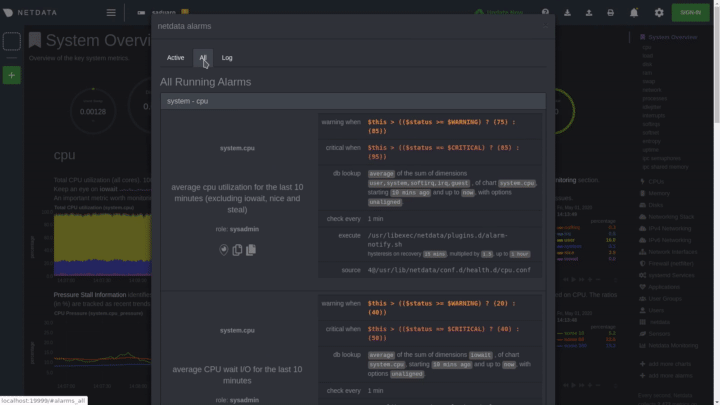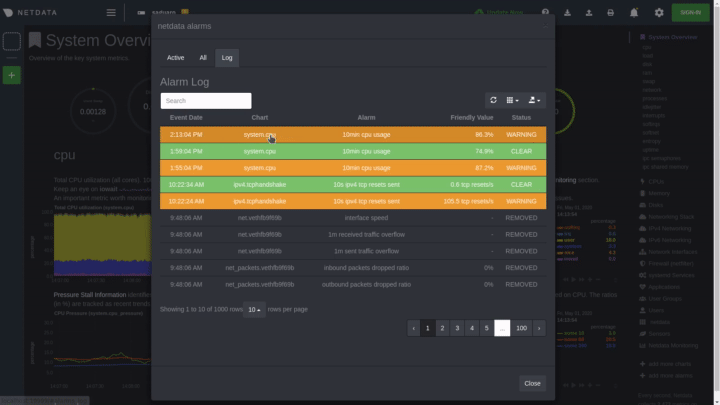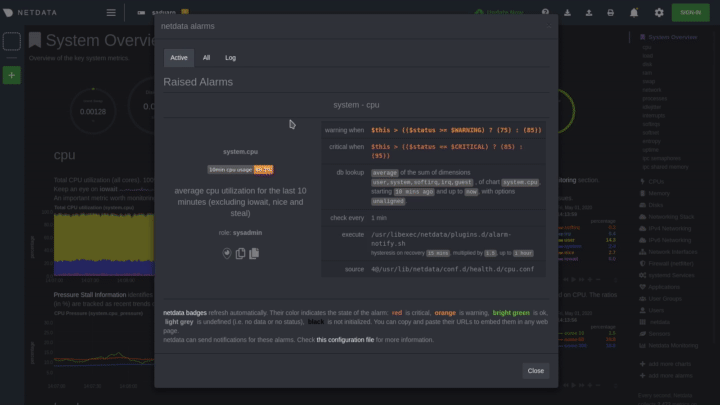
53
54
-And a static screenshot of the raised CPU alarm:
54
+And a static screenshot of the raised CPU alert:
55
56
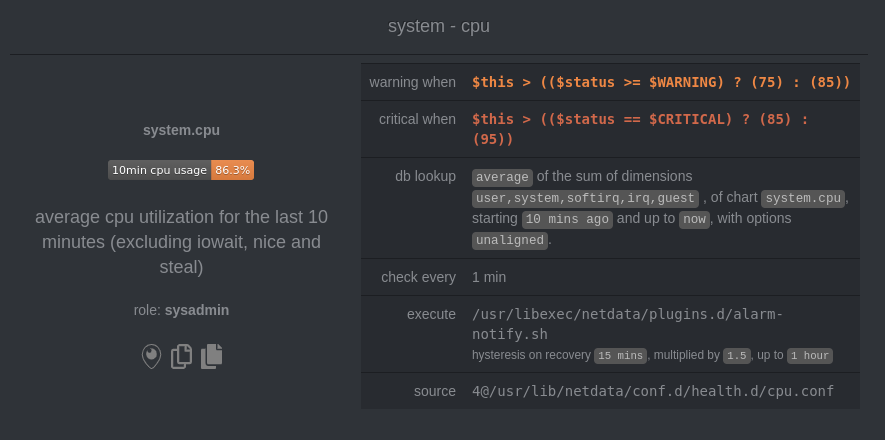
57
+alert](https://user-images.githubusercontent.com/1153921/80842330-2dfbb200-8bb6-11ea-8147-3cd366eb0f37.png)
58
59
-The alarm itself is named **system - cpu**, and its context is `system.cpu`. Beneath that is an auto-updating badge that
60
-shows the latest value of the chart that triggered the alarm.
59
+The alert itself is named **system - cpu**, and its context is `system.cpu`. Beneath that is an auto-updating badge that
60
+shows the latest value of the chart that triggered the alert.
61
62
With the three icons beneath that and the **role** designation, you can:
63
64
-1. Scroll to the chart associated with this raised alarm.
64
+1. Scroll to the chart associated with this raised alert.
65
2. Copy a link to the badge to your clipboard.
66
3. Copy the code to embed the badge onto another web page using an `<embed>` element.
67
68
-The table on the right-hand side displays information about the health entity that triggered the alarm, which you can
69
-use as a reference to [configure alarms](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md).
68
+The table on the right-hand side displays information about the health entity that triggered the alert, which you can
69
+use as a reference to [configure alerts](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md).
70
-->
docs/quickstart/infrastructure.md
+6
-6
@@ -3,7 +3,7 @@ import { RiExternalLinkLine } from 'react-icons/ri'
3
4
# Monitor your infrastructure
5
6
-Learn how to view key metrics, insightful charts, and active alarms from all your nodes, with Netdata Cloud's real-time infrastructure monitoring.
6
+Learn how to view key metrics, insightful charts, and active alerts from all your nodes, with Netdata Cloud's real-time infrastructure monitoring.
7
8
[Netdata Cloud](https://app.netdata.cloud) provides scalable infrastructure monitoring for any number of distributed
9
nodes running the Netdata Agent. A node is any system in your infrastructure that you want to monitor, whether it's a
@@ -20,7 +20,7 @@ between them, you can monitor your infrastructure using customizable, interactiv
20
number of distributed nodes.
21
22
In this quickstart guide, you'll learn the basics of using Netdata Cloud to monitor an infrastructure with dashboards,
23
-composite charts, and alarm viewing. You'll then learn about the most critical ways to configure the Agent on each of
23
+composite charts, and alert viewing. You'll then learn about the most critical ways to configure the Agent on each of
24
your nodes to maximize the value you get from Netdata.
25
26
This quickstart assumes you've [installed Netdata](https://github.com/netdata/netdata/edit/master/packaging/installer/README.md)
@@ -73,13 +73,13 @@ These tabs can be separated into "static", meaning they are by default presented
73
74
- The second and most important tab is the [Overview tab](https://github.com/netdata/netdata/blob/master/docs/cloud/visualize/overview.md#overview-and-single-node-view) which uses composite charts to display real-time metrics from every available node in a given War Room.
75
76
-- The [Nodes tab](https://github.com/netdata/netdata/blob/master/docs/cloud/visualize/nodes.md) gives you the ability to see the status (offline or online), host details, alarm status and also a short overview of some key metrics from all your nodes at a glance.
76
+- The [Nodes tab](https://github.com/netdata/netdata/blob/master/docs/cloud/visualize/nodes.md) gives you the ability to see the status (offline or online), host details, alert status and also a short overview of some key metrics from all your nodes at a glance.
77
78
- [Kubernetes tab](https://github.com/netdata/netdata/blob/master/docs/cloud/visualize/kubernetes.md) is a logical grouping of charts regarding your Kubernetes clusters. It contains a subset of the charts available in the **Overview tab**.
79
80
- The [Dashboards tab](https://github.com/netdata/netdata/blob/master/docs/cloud/visualize/dashboards.md) gives you the ability to have tailored made views of specific/targeted interfaces for your infrastructure using any number of charts from any number of nodes.
81
82
-- The [Alerts tab](https://github.com/netdata/netdata/blob/master/docs/monitor/view-active-alarms.md) provides you with an overview for all the active alerts you receive for the nodes in this War Room, you can also see all the alerts that are configured to be triggered in any given moment.
82
+- The [Alerts tab](https://github.com/netdata/netdata/blob/master/docs/monitor/view-active-alerts.md) provides you with an overview for all the active alerts you receive for the nodes in this War Room, you can also see all the alerts that are configured to be triggered in any given moment.
83
84
- The [Anomalies tab](https://github.com/netdata/netdata/blob/master/docs/cloud/insights/anomaly-advisor.md) is dedicated to the Anomaly Advisor tool.
85
@@ -181,7 +181,7 @@ collect from across your infrastructure with Netdata.
181
<Box
182
title="Alerts and notifications">
183
<BoxList>
184
- <BoxListItemRegexLink to="[](https://github.com/netdata/netdata/blob/master/docs/monitor/view-active-alarms.md#netdata-cloud)" title="View active alerts" />
184
+ <BoxListItemRegexLink to="[](https://github.com/netdata/netdata/blob/master/docs/monitor/view-active-alerts.md#netdata-cloud)" title="View active alerts" />
185
<BoxListItemRegexLink to="[](https://github.com/netdata/netdata/blob/master/docs/cloud/alerts-notifications/notifications.md)" title="Alert notifications" />
186
</BoxList>
187
</Box>
@@ -212,7 +212,7 @@ collect from across your infrastructure with Netdata.
212
- [Kubernetes](https://github.com/netdata/netdata/blob/master/docs/cloud/visualize/kubernetes.md)
213
- [Create new dashboards](https://github.com/netdata/netdata/blob/master/docs/cloud/visualize/dashboards.md)
214
- Alerts and notifications
215
- - [View active alerts](https://github.com/netdata/netdata/blob/master/docs/monitor/view-active-alarms.md#netdata-cloud)
215
+ - [View active alerts](https://github.com/netdata/netdata/blob/master/docs/monitor/view-active-alerts.md#netdata-cloud)
216
- [Alert notifications](https://github.com/netdata/netdata/blob/master/docs/cloud/alerts-notifications/notifications.md)
217
- Troubleshooting with Netdata Cloud
218
- [Metric Correlations](https://github.com/netdata/netdata/blob/master/docs/cloud/insights/metric-correlations.md)
docs/store/distributed-data-architecture.md
+2
-2
@@ -68,8 +68,8 @@ When you use the database engine to store your metrics, you can always perform a
68
69
Netdata Cloud does not store metric values.
70
71
-To enable certain features, such as [viewing active alarms](https://github.com/netdata/netdata/blob/master/docs/monitor/view-active-alarms.md)
71
+To enable certain features, such as [viewing active alerts](https://github.com/netdata/netdata/blob/master/docs/monitor/view-active-alerts.md)
72
or [filtering by hostname](https://github.com/netdata/netdata/blob/master/docs/cloud/visualize/node-filter.md), Netdata Cloud does
73
-store configured alarms, their status, and a list of active collectors.
73
+store configured alerts, their status, and a list of active collectors.
74
75
Netdata does not and never will sell your personal data or data about your deployment.
exporting/README.md
+2
-2
@@ -314,9 +314,9 @@ and performance of the exporting engine itself:
314
315

316
317
-## Exporting engine alarms
317
+## Exporting engine alerts
318
319
-Netdata adds 3 alarms:
319
+Netdata adds 3 alerts:
320
321
1. `exporting_last_buffering`, number of seconds since the last successful buffering of exported data
322
2. `exporting_metrics_sent`, percentage of metrics sent to the external database server
exporting/prometheus/README.md
+1
-1
@@ -24,7 +24,7 @@ Each chart in Netdata has several properties (common to all its metrics):
24
- `chart_name` - a more human friendly name for `chart_id`, also unique.
25
26
- `context` - this is the template of the chart. All disk I/O charts have the same context, all mysql requests charts
27
- have the same context, etc. This is used for alarm templates to match all the charts they should be attached to.
27
+ have the same context, etc. This is used for alert templates to match all the charts they should be attached to.
28
29
- `family` groups a set of charts together. It is used as the submenu of the dashboard.
30
health/README.md
+3
-3
@@ -2,10 +2,10 @@
2
3
The Netdata Agent is a health watchdog for the health and performance of your systems, services, and applications. We've
4
worked closely with our community of DevOps engineers, SREs, and developers to define hundreds of production-ready
5
-alarms that work without any configuration.
5
+alerts that work without any configuration.
6
7
-The Agent's health monitoring system is also dynamic and fully customizable. You can write entirely new alarms, tune the
8
-community-configured alarms for every app/service [the Agent collects metrics from](https://github.com/netdata/netdata/blob/master/collectors/COLLECTORS.md), or
7
+The Agent's health monitoring system is also dynamic and fully customizable. You can write entirely new alerts, tune the
8
+community-configured alerts for every app/service [the Agent collects metrics from](https://github.com/netdata/netdata/blob/master/collectors/COLLECTORS.md), or
9
silence anything you're not interested in. You can even power complex lookups by running statistical algorithms against
10
your metrics.
11
health/REFERENCE.md
+214
-215
@@ -1,15 +1,15 @@
1
# Configure alerts
2
3
-Netdata's health watchdog is highly configurable, with support for dynamic thresholds, hysteresis, alarm templates, and
4
-more. You can tweak any of the existing alarms based on your infrastructure's topology or specific monitoring needs, or
3
+Netdata's health watchdog is highly configurable, with support for dynamic thresholds, hysteresis, alert templates, and
4
+more. You can tweak any of the existing alerts based on your infrastructure's topology or specific monitoring needs, or
5
create new entities.
6
7
-You can use health alarms in conjunction with any of Netdata's [collectors](https://github.com/netdata/netdata/blob/master/collectors/README.md) (see
7
+You can use health alerts in conjunction with any of Netdata's [collectors](https://github.com/netdata/netdata/blob/master/collectors/README.md) (see
8
the [supported collector list](https://github.com/netdata/netdata/blob/master/collectors/COLLECTORS.md)) to monitor the health of your systems, containers, and
9
applications in real time.
10
11
-While you can see active alarms both on the local dashboard and Netdata Cloud, all health alarms are configured _per
12
-node_ via individual Netdata Agents. If you want to deploy a new alarm across your
11
+While you can see active alerts both on the local dashboard and Netdata Cloud, all health alerts are configured _per
12
+node_ via individual Netdata Agents. If you want to deploy a new alert across your
13
[infrastructure](https://github.com/netdata/netdata/blob/master/docs/quickstart/infrastructure.md), you must configure each node with the same health configuration
14
files.
15
@@ -55,7 +55,7 @@ template: 10min_cpu_usage
55
to: sysadmin
56
```
57
58
-To tune this alarm to trigger warning and critical alarms at a lower CPU utilization, change the `warn` and `crit` lines
58
+To tune this alert to trigger warning and critical alerts at a lower CPU utilization, change the `warn` and `crit` lines
59
to the values of your choosing. For example:
60
61
```yaml
@@ -79,7 +79,7 @@ In the `netdata.conf` `[health]` section, set `enabled` to `no`, and restart the
79
80
In the `netdata.conf` `[health]` section, set `enabled alarms` to a
81
[simple pattern](https://github.com/netdata/netdata/edit/master/libnetdata/simple_pattern/README.md) that
82
-excludes one or more alerts. e.g. `enabled alarms = !oom_kill *` will load all alarms except `oom_kill`.
82
+excludes one or more alerts. e.g. `enabled alarms = !oom_kill *` will load all alerts except `oom_kill`.
83
84
You can also [edit the file where the alert is defined](#edit-individual-alerts), comment out its definition,
85
and [reload Netdata's health configuration](#reload-health-configuration).
@@ -112,7 +112,7 @@ or restarting the agent.
112
113
## Write a new health entity
114
115
-While tuning existing alarms may work in some cases, you may need to write entirely new health entities based on how
115
+While tuning existing alerts may work in some cases, you may need to write entirely new health entities based on how
116
your systems, containers, and applications work.
117
118
Read the [health entity reference](#health-entity-reference) for a full listing of the format,
@@ -128,8 +128,8 @@ sudo touch health.d/ram-usage.conf
128
sudo ./edit-config health.d/ram-usage.conf
129
```
130
131
-For example, here is a health entity that triggers a warning alarm when a node's RAM usage rises above 80%, and a
132
-critical alarm above 90%:
131
+For example, here is a health entity that triggers a warning alert when a node's RAM usage rises above 80%, and a
132
+critical alert above 90%:
133
134
```yaml
135
alarm: ram_usage
@@ -151,7 +151,7 @@ Let's look into each of the lines to see how they create a working health entity
151
152
- `on`: Which chart the entity listens to.
153
154
-- `lookup`: Which metrics the alarm monitors, the duration of time to monitor, and how to process the metrics into a
154
+- `lookup`: Which metrics the alert monitors, the duration of time to monitor, and how to process the metrics into a
155
usable format.
156
- `average`: Calculate the average of all the metrics collected.
157
- `-1m`: Use metrics from 1 minute ago until now to calculate that average.
@@ -160,13 +160,13 @@ Let's look into each of the lines to see how they create a working health entity
160
161
- `units`: Use percentages rather than absolute units.
162
163
-- `every`: How often to perform the `lookup` calculation to decide whether or not to trigger this alarm.
163
+- `every`: How often to perform the `lookup` calculation to decide whether to trigger this alert.
164
165
-- `warn`/`crit`: The value at which Netdata should trigger a warning or critical alarm. This example uses simple
165
+- `warn`/`crit`: The value at which Netdata should trigger a warning or critical alert. This example uses simple
166
syntax, but most pre-configured health entities use
167
[hysteresis](#special-use-of-the-conditional-operator) to avoid superfluous notifications.
168
169
-- `info`: A description of the alarm, which will appear in the dashboard and notifications.
169
+- `info`: A description of the alert, which will appear in the dashboard and notifications.
170
171
In human-readable format:
172
@@ -174,8 +174,8 @@ In human-readable format:
174
> metrics from the **used** dimension and calculates the **average** of all those metrics in a **percentage** format,
175
> using a **% unit**. The entity performs this lookup **every minute**.
176
>
177
-> If the average RAM usage percentage over the last 1 minute is **more than 80%**, the entity triggers a warning alarm.
178
-> If the usage is **more than 90%**, the entity triggers a critical alarm.
177
+> If the average RAM usage percentage over the last 1 minute is **more than 80%**, the entity triggers a warning alert.
178
+> If the usage is **more than 90%**, the entity triggers a critical alert.
179
180
When you finish writing this new health entity, [reload Netdata's health configuration](#reload-health-configuration) to
181
see it live on the local dashboard or Netdata Cloud.
@@ -188,20 +188,20 @@ without restarting all of Netdata, run `netdatacli reload-health` or `killall -U
188
## Health entity reference
189
190
The following reference contains information about the syntax and options of _health entities_, which Netdata attaches
191
-to charts in order to trigger alarms.
191
+to charts in order to trigger alerts.
192
193
### Entity types
194
195
There are two entity types: **alarms** and **templates**. They have the same format and feature set—the only difference
196
is their label.
197
198
-**Alarms** are attached to specific charts and use the `alarm` label.
198
+**Alerts** are attached to specific charts and use the `alarm` label.
199
200
**Templates** define rules that apply to all charts of a specific context, and use the `template` label. Templates help
201
you apply one entity to all disks, all network interfaces, all MySQL databases, and so on.
202
203
-Alarms have higher precedence and will override templates. If an alarm and template entity have the same name and attach
204
-to the same chart, Netdata will use the alarm.
203
+Alerts have higher precedence and will override templates.
204
+If the `alert` and `template` entities have the same name and are attached to the same chart, Netdata will use `alarm`.
205
206
### Entity format
207
@@ -219,39 +219,39 @@ Netdata parses the following lines. Beneath the table is an in-depth explanation
219
This comes in handy if your `info` line consists of several sentences.
220
221
| line | required | functionality |
222
-| --------------------------------------------------- | --------------- | ------------------------------------------------------------------------------------- |
223
-| [`alarm`/`template`](#alarm-line-alarm-or-template) | yes | Name of the alarm/template. |
224
-| [`on`](#alarm-line-on) | yes | The chart this alarm should attach to. |
225
-| [`class`](#alarm-line-class) | no | The general alarm classification. |
226
-| [`type`](#alarm-line-type) | no | What area of the system the alarm monitors. |
227
-| [`component`](#alarm-line-component) | no | Specific component of the type of the alarm. |
228
-| [`os`](#alarm-line-os) | no | Which operating systems to run this chart. |
229
-| [`hosts`](#alarm-line-hosts) | no | Which hostnames will run this alarm. |
230
-| [`plugin`](#alarm-line-plugin) | no | Restrict an alarm or template to only a certain plugin. |
231
-| [`module`](#alarm-line-module) | no | Restrict an alarm or template to only a certain module. |
232
-| [`charts`](#alarm-line-charts) | no | Restrict an alarm or template to only certain charts. |
233
-| [`families`](#alarm-line-families) | no | Restrict a template to only certain families. |
234
-| [`lookup`](#alarm-line-lookup) | yes | The database lookup to find and process metrics for the chart specified through `on`. |
235
-| [`calc`](#alarm-line-calc) | yes (see above) | A calculation to apply to the value found via `lookup` or another variable. |
236
-| [`every`](#alarm-line-every) | no | The frequency of the alarm. |
237
-| [`green`/`red`](#alarm-lines-green-and-red) | no | Set the green and red thresholds of a chart. |
238
-| [`warn`/`crit`](#alarm-lines-warn-and-crit) | yes (see above) | Expressions evaluating to true or false, and when true, will trigger the alarm. |
239
-| [`to`](#alarm-line-to) | no | A list of roles to send notifications to. |
240
-| [`exec`](#alarm-line-exec) | no | The script to execute when the alarm changes status. |
241
-| [`delay`](#alarm-line-delay) | no | Optional hysteresis settings to prevent floods of notifications. |
242
-| [`repeat`](#alarm-line-repeat) | no | The interval for sending notifications when an alarm is in WARNING or CRITICAL mode. |
243
-| [`options`](#alarm-line-options) | no | Add an option to not clear alarms. |
244
-| [`host labels`](#alarm-line-host-labels) | no | Restrict an alarm or template to a list of matching labels present on a host. |
245
-| [`chart labels`](#alarm-line-chart-labels) | no | Restrict an alarm or template to a list of matching labels present on a host. |
246
-| [`info`](#alarm-line-info) | no | A brief description of the alarm. |
222
+|-----------------------------------------------------|-----------------|---------------------------------------------------------------------------------------|
223
+| [`alarm`/`template`](#alert-line-alarm-or-template) | yes | Name of the alert/template. |
224
+| [`on`](#alert-line-on) | yes | The chart this alert should attach to. |
225
+| [`class`](#alert-line-class) | no | The general alert classification. |
226
+| [`type`](#alert-line-type) | no | What area of the system the alert monitors. |
227
+| [`component`](#alert-line-component) | no | Specific component of the type of the alert. |
228
+| [`os`](#alert-line-os) | no | Which operating systems to run this chart. |
229
+| [`hosts`](#alert-line-hosts) | no | Which hostnames will run this alert. |
230
+| [`plugin`](#alert-line-plugin) | no | Restrict an alert or template to only a certain plugin. |
231
+| [`module`](#alert-line-module) | no | Restrict an alert or template to only a certain module. |
232
+| [`charts`](#alert-line-charts) | no | Restrict an alert or template to only certain charts. |
233
+| [`families`](#alert-line-families) | no | Restrict a template to only certain families. |
234
+| [`lookup`](#alert-line-lookup) | yes | The database lookup to find and process metrics for the chart specified through `on`. |
235
+| [`calc`](#alert-line-calc) | yes (see above) | A calculation to apply to the value found via `lookup` or another variable. |
236
+| [`every`](#alert-line-every) | no | The frequency of the alert. |
237
+| [`green`/`red`](#alert-lines-green-and-red) | no | Set the green and red thresholds of a chart. |
238
+| [`warn`/`crit`](#alert-lines-warn-and-crit) | yes (see above) | Expressions evaluating to true or false, and when true, will trigger the alert. |
239
+| [`to`](#alert-line-to) | no | A list of roles to send notifications to. |
240
+| [`exec`](#alert-line-exec) | no | The script to execute when the alert changes status. |
241
+| [`delay`](#alert-line-delay) | no | Optional hysteresis settings to prevent floods of notifications. |
242
+| [`repeat`](#alert-line-repeat) | no | The interval for sending notifications when an alert is in WARNING or CRITICAL mode. |
243
+| [`options`](#alert-line-options) | no | Add an option to not clear alerts. |
244
+| [`host labels`](#alert-line-host-labels) | no | Restrict an alert or template to a list of matching labels present on a host. |
245
+| [`chart labels`](#alert-line-chart-labels) | no | Restrict an alert or template to a list of matching labels present on a host. |
246
+| [`info`](#alert-line-info) | no | A brief description of the alert. |
247
248
The `alarm` or `template` line must be the first line of any entity.
249
250
-#### Alarm line `alarm` or `template`
250
+#### Alert line `alarm` or `template`
251
252
-This line starts an alarm or template based on the [entity type](#entity-types) you're interested in creating.
252
+This line starts an alert or template based on the [entity type](#entity-types) you're interested in creating.
253
254
-**Alarm:**
254
+**Alert:**
255
256
```yaml
257
alarm: NAME
@@ -266,11 +266,11 @@ template: NAME
266
`NAME` can be any alpha character, with `.` (period) and `_` (underscore) as the only allowed symbols, but the names
267
cannot be `chart name`, `dimension name`, `family name`, or `chart variables names`.
268
269
-#### Alarm line `on`
269
+#### Alert line `on`
270
271
-This line defines the chart this alarm should attach to.
271
+This line defines the chart this alert should attach to.
272
273
-**Alarms:**
273
+**Alerts:**
274
275
```yaml
276
on: CHART
@@ -297,40 +297,40 @@ shows a disk I/O chart, the tooltip reads: `proc:/proc/diskstats, disk.io`.
297
298
You're interested in what comes after the comma: `disk.io`. That's the name of the chart's context.
299
300
-If you create a template using the `disk.io` context, it will apply an alarm to every disk available on your system.
300
+If you create a template using the `disk.io` context, it will apply an alert to every disk available on your system.
301
302
-#### Alarm line `class`
302
+#### Alert line `class`
303
304
-This indicates the type of error (or general problem area) that the alarm or template applies to. For example, `Latency` can be used for alarms that trigger on latency issues on network interfaces, web servers, or database systems. Example:
304
+This indicates the type of error (or general problem area) that the alert or template applies to. For example, `Latency` can be used for alerts that trigger on latency issues on network interfaces, web servers, or database systems. Example:
305
306
```yaml
307
class: Latency
308
```
309
310
<details>
311
-<summary>Netdata's stock alarms use the following `class` attributes by default:</summary>
311
+<summary>Netdata's stock alerts use the following `class` attributes by default:</summary>
312
313
-| Class |
314
-| ----------------|
315
-| Errors |
316
-| Latency |
317
-| Utilization |
318
-| Workload |
313
+| Class |
314
+|-------------|
315
+| Errors |
316
+| Latency |
317
+| Utilization |
318
+| Workload |
319
320
</details>
321
322
-`class` will default to `Unknown` if the line is missing from the alarm configuration.
322
+`class` will default to `Unknown` if the line is missing from the alert configuration.
323
324
-#### Alarm line `type`
324
+#### Alert line `type`
325
326
-Type can be used to indicate the broader area of the system that the alarm applies to. For example, under the general `Database` type, you can group together alarms that operate on various database systems, like `MySQL`, `CockroachDB`, `CouchDB` etc. Example:
326
+Type can be used to indicate the broader area of the system that the alert applies to. For example, under the general `Database` type, you can group together alerts that operate on various database systems, like `MySQL`, `CockroachDB`, `CouchDB` etc. Example:
327
328
```yaml
329
type: Database
330
```
331
332
<details>
333
-<summary>Netdata's stock alarms use the following `type` attributes by default, but feel free to adjust for your own requirements.</summary>
333
+<summary>Netdata's stock alerts use the following `type` attributes by default, but feel free to adjust for your own requirements.</summary>
334
335
| Type | Description |
336
|-----------------|------------------------------------------------------------------------------------------------|
@@ -352,7 +352,7 @@ type: Database
352
| Power Supply | Alerts from power supply related services (e.g. apcupsd) |
353
| Search engine | Alerts for search services (e.g. elasticsearch) |
354
| Storage | Class for alerts dealing with storage services (storage devices typically live under `System`) |
355
-| System | General system alarms (e.g. cpu, network, etc.) |
355
+| System | General system alerts (e.g. cpu, network, etc.) |
356
| Virtual Machine | Virtual Machine software |
357
| Web Proxy | Web proxy software (e.g. squid) |
358
| Web Server | Web server software (e.g. Apache, ngnix, etc.) |
@@ -360,11 +360,11 @@ type: Database
360
361
</details>
362
363
-If an alarm configuration is missing the `type` line, its value will default to `Unknown`.
363
+If an alert configuration is missing the `type` line, its value will default to `Unknown`.
364
365
-#### Alarm line `component`
365
+#### Alert line `component`
366
367
-Component can be used to narrow down what the previous `type` value specifies for each alarm or template. Continuing from the previous example, `component` might include `MySQL`, `CockroachDB`, `MongoDB`, all under the same `Database` type. Example:
367
+Component can be used to narrow down what the previous `type` value specifies for each alert or template. Continuing from the previous example, `component` might include `MySQL`, `CockroachDB`, `MongoDB`, all under the same `Database` type. Example:
368
369
```yaml
370
component: MySQL
@@ -372,9 +372,9 @@ component: MySQL
372
373
As with the `class` and `type` line, if `component` is missing from the configuration, its value will default to `Unknown`.
374
375
-#### Alarm line `os`
375
+#### Alert line `os`
376
377
-The alarm or template will be used only if the operating system of the host matches this list specified in `os`. The
377
+The alert or template will be used only if the operating system of the host matches this list specified in `os`. The
378
value is a space-separated list.
379
380
The following example enables the entity on Linux, FreeBSD, and macOS, but no other operating systems.
@@ -383,9 +383,9 @@ The following example enables the entity on Linux, FreeBSD, and macOS, but no ot
383
os: linux freebsd macos
384
```
385
386
-#### Alarm line `hosts`
386
+#### Alert line `hosts`
387
388
-The alarm or template will be used only if the hostname of the host matches this space-separated list.
388
+The alert or template will be used only if the hostname of the host matches this space-separated list.
389
390
The following example will load on systems with the hostnames `server` and `server2`, and any system with hostnames that
391
begin with `database`. It _will not load_ on the host `redis3`, but will load on any _other_ systems with hostnames that
@@ -395,47 +395,47 @@ begin with `redis`.
395
hosts: server1 server2 database* !redis3 redis*
396
```
397
398
-#### Alarm line `plugin`
398
+#### Alert line `plugin`
399
400
-The `plugin` line filters which plugin within the context this alarm should apply to. The value is a space-separated
400
+The `plugin` line filters which plugin within the context this alert should apply to. The value is a space-separated
401
list of [simple patterns](https://github.com/netdata/netdata/blob/master/libnetdata/simple_pattern/README.md). For example,
402
-you can create a filter for an alarm that applies specifically to `python.d.plugin`:
402
+you can create a filter for an alert that applies specifically to `python.d.plugin`:
403
404
```yaml
405
plugin: python.d.plugin
406
```
407
408
The `plugin` line is best used with other options like `module`. When used alone, the `plugin` line creates a very
409
-inclusive filter that is unlikely to be of much use in production. See [`module`](#alarm-line-module) for a
409
+inclusive filter that is unlikely to be of much use in production. See [`module`](#alert-line-module) for a
410
comprehensive example using both.
411
412
-#### Alarm line `module`
412
+#### Alert line `module`
413
414
-The `module` line filters which module within the context this alarm should apply to. The value is a space-separated
414
+The `module` line filters which module within the context this alert should apply to. The value is a space-separated
415
list of [simple patterns](https://github.com/netdata/netdata/blob/master/libnetdata/simple_pattern/README.md). For
416
-example, you can create an alarm that applies only on the `isc_dhcpd` module started by `python.d.plugin`:
416
+example, you can create an alert that applies only on the `isc_dhcpd` module started by `python.d.plugin`:
417
418
```yaml
419
plugin: python.d.plugin
420
module: isc_dhcpd
421
```
422
423
-#### Alarm line `charts`
423
+#### Alert line `charts`
424
425
-The `charts` line filters which chart this alarm should apply to. It is only available on entities using the
426
-[`template`](#alarm-line-alarm-or-template) line.
425
+The `charts` line filters which chart this alert should apply to. It is only available on entities using the
426
+[`template`](#alert-line-alarm-or-template) line.
427
The value is a space-separated list of [simple patterns](https://github.com/netdata/netdata/blob/master/libnetdata/simple_pattern/README.md). For
428
-example, a template that applies to `disk.svctm` (Average Service Time) context, but excludes the disk `sdb` from alarms:
428
+example, a template that applies to `disk.svctm` (Average Service Time) context, but excludes the disk `sdb` from alerts:
429
430
```yaml
431
-template: disk_svctm_alarm
431
+template: disk_svctm_alert
432
on: disk.svctm
433
charts: !*sdb* *
434
```
435
436
-#### Alarm line `families`
436
+#### Alert line `families`
437
438
-The `families` line, used only alongside templates, filters which families within the context this alarm should apply
438
+The `families` line, used only alongside templates, filters which families within the context this alert should apply
439
to. The value is a space-separated list.
440
441
The value is a space-separate list of simple patterns. See our [simple patterns docs](https://github.com/netdata/netdata/blob/master/libnetdata/simple_pattern/README.md) for
@@ -448,9 +448,9 @@ families: sda sdb
448
```
449
450
Please note that the use of the `families` filter is planned to be deprecated in upcoming Netdata releases.
451
-Please use [`chart labels`](#alarm-line-chart-labels) instead.
451
+Please use [`chart labels`](#alert-line-chart-labels) instead.
452
453
-#### Alarm line `lookup`
453
+#### Alert line `lookup`
454
455
This line makes a database lookup to find a value. This result of this lookup is available as `$this`.
456
@@ -485,17 +485,17 @@ The full [database query API](https://github.com/netdata/netdata/blob/master/web
485
`,` or `|` instead of spaces)_ and the `match-ids` and `match-names` options affect the searches
486
for dimensions.
487
488
-- `foreach DIMENSIONS` is optional and works only with [templates](#alarm-line-alarm-or-template), will always be the last parameter, and uses the same `,`/`|`
488
+- `foreach DIMENSIONS` is optional and works only with [templates](#alert-line-alarm-or-template), will always be the last parameter, and uses the same `,`/`|`
489
rules as the `of` parameter. Each dimension you specify in `foreach` will use the same rule
490
- to trigger an alarm. If you set both `of` and `foreach`, Netdata will ignore the `of` parameter
490
+ to trigger an alert. If you set both `of` and `foreach`, Netdata will ignore the `of` parameter
491
and replace it with one of the dimensions you gave to `foreach`. This option allows you to
492
- [use dimension templates to create dynamic alarms](#use-dimension-templates-to-create-dynamic-alarms).
492
+ [use dimension templates to create dynamic alerts](#use-dimension-templates-to-create-dynamic-alerts).
493
494
The result of the lookup will be available as `$this` and `$NAME` in expressions.
495
The timestamps of the timeframe evaluated by the database lookup is available as variables
496
`$after` and `$before` (both are unix timestamps).
497
498
-#### Alarm line `calc`
498
+#### Alert line `calc`
499
500
A `calc` is designed to apply some calculation to the values or variables available to the entity. The result of the
501
calculation will be made available at the `$this` variable, overwriting the value from your `lookup`, to use in warning
@@ -512,9 +512,9 @@ The `calc` line uses [expressions](#expressions) for its syntax.
512
calc: EXPRESSION
513
```
514
515
-#### Alarm line `every`
515
+#### Alert line `every`
516
517
-Sets the update frequency of this alarm. This is the same to the `every DURATION` given
517
+Sets the update frequency of this alert. This is the same to the `every DURATION` given
518
in the `lookup` lines.
519
520
Format:
@@ -525,11 +525,11 @@ every: DURATION
525
526
`DURATION` accepts `s` for seconds, `m` is minutes, `h` for hours, `d` for days.
527
528
-#### Alarm lines `green` and `red`
528
+#### Alert lines `green` and `red`
529
530
Set the green and red thresholds of a chart. Both are available as `$green` and `$red` in expressions. If multiple
531
-alarms define different thresholds, the ones defined by the first alarm will be used. These will eventually visualized
532
-on the dashboard, so only one set of them is allowed. If you need multiple sets of them in different alarms, use
531
+alerts define different thresholds, the ones defined by the first alert will be used. Eventually it will be visualized
532
+on the dashboard, so only one set of them is allowed If you need multiple sets of them in different alerts, use
533
absolute numbers instead of `$red` and `$green`.
534
535
Format:
@@ -539,9 +539,9 @@ green: NUMBER
539
red: NUMBER
540
```
541
542
-#### Alarm lines `warn` and `crit`
542
+#### Alert lines `warn` and `crit`
543
544
-Define the expression that triggers either a warning or critical alarm. These are optional, and should evaluate to
544
+Define the expression that triggers either a warning or critical alert. These are optional, and should evaluate to
545
either true or false (or zero/non-zero).
546
547
The format uses Netdata's [expressions syntax](#expressions).
@@ -551,9 +551,9 @@ warn: EXPRESSION
551
crit: EXPRESSION
552
```
553
554
-#### Alarm line `to`
554
+#### Alert line `to`
555
556
-This will be the first parameter of the script to be executed when the alarm switches status. Its meaning is left up to
556
+This will be the first script parameter that will be executed when the alert changes its status. Its meaning is left up to
557
the `exec` script.
558
559
The default `exec` script, `alarm-notify.sh`, uses this field as a space separated list of roles, which are then
@@ -565,9 +565,9 @@ Format:
565
to: ROLE1 ROLE2 ROLE3 ...
566
```
567
568
-#### Alarm line `exec`
568
+#### Alert line `exec`
569
570
-The script that will be executed when the alarm changes status.
570
+Script to be executed when the alert status changes.
571
572
Format:
573
@@ -578,10 +578,10 @@ exec: SCRIPT
578
The default `SCRIPT` is Netdata's `alarm-notify.sh`, which supports all the notifications methods Netdata supports,
579
including custom hooks.
580
581
-#### Alarm line `delay`
581
+#### Alert line `delay`
582
583
This is used to provide optional hysteresis settings for the notifications, to defend against notification floods. These
584
-settings do not affect the actual alarm - only the time the `exec` script is executed.
584
+settings do not affect the actual alert - only the time the `exec` script is executed.
585
586
Format:
587
@@ -589,45 +589,45 @@ Format:
589
delay: [[[up U] [down D] multiplier M] max X]
590
```
591
592
-- `up U` defines the delay to be applied to a notification for an alarm that raised its status
592
+- `up U` defines the delay to be applied to a notification for an alert that raised its status
593
(i.e. CLEAR to WARNING, CLEAR to CRITICAL, WARNING to CRITICAL). For example, `up 10s`, the
594
notification for this event will be sent 10 seconds after the actual event. This is used in
595
- hope the alarm will get back to its previous state within the duration given. The default `U`
595
+ hope the alert will get back to its previous state within the duration given. The default `U`
596
is zero.
597
598
-- `down D` defines the delay to be applied to a notification for an alarm that moves to lower
598
+- `down D` defines the delay to be applied to a notification for an alert that moves to lower
599
state (i.e. CRITICAL to WARNING, CRITICAL to CLEAR, WARNING to CLEAR). For example, `down 1m`
600
will delay the notification by 1 minute. This is used to prevent notifications for flapping
601
- alarms. The default `D` is zero.
601
+ alerts. The default `D` is zero.
602
603
-- `multiplier M` multiplies `U` and `D` when an alarm changes state, while a notification is
603
+- `multiplier M` multiplies `U` and `D` when an alert changes state, while a notification is
604
delayed. The default multiplier is `1.0`.
605
606
-- `max X` defines the maximum absolute notification delay an alarm may get. The default `X`
606
+- `max X` defines the maximum absolute notification delay an alert may get. The default `X`
607
is `max(U * M, D * M)` (i.e. the max duration of `U` or `D` multiplied once with `M`).
608
609
Example:
610
611
`delay: up 10s down 15m multiplier 2 max 1h`
612
613
- The time is `00:00:00` and the status of the alarm is CLEAR.
613
+ The time is `00:00:00` and the status of the alert is CLEAR.
614
615
| time of event | new status | delay | notification will be sent | why |
616
- | ------------- | ---------- | --- | ------------------------- | --- |
616
+ |---------------|------------|---------------------|---------------------------|-------------------------------------------------------------------------------|
617
| 00:00:01 | WARNING | `up 10s` | 00:00:11 | first state switch |
618
- | 00:00:05 | CLEAR | `down 15m x2` | 00:30:05 | the alarm changes state while a notification is delayed, so it was multiplied |
618
+ | 00:00:05 | CLEAR | `down 15m x2` | 00:30:05 | the alert changes state while a notification is delayed, so it was multiplied |
619
| 00:00:06 | WARNING | `up 10s x2 x2` | 00:00:26 | multiplied twice |
620
| 00:00:07 | CLEAR | `down 15m x2 x2 x2` | 00:45:07 | multiplied 3 times. |
621
622
So:
623
624
- - `U` and `D` are multiplied by `M` every time the alarm changes state (any state, not just
624
+ - `U` and `D` are multiplied by `M` every time the alert changes state (any state, not just
625
their matching one) and a delay is in place.
626
- - All are reset to their defaults when the alarm switches state without a delay in place.
626
+ - All are reset to their defaults when the alert switches state without a delay in place.
627
628
-#### Alarm line `repeat`
628
+#### Alert line `repeat`
629
630
-Defines the interval between repeating notifications for the alarms in CRITICAL or WARNING mode. This will override the
630
+Defines the interval between repeating notifications for the alerts in CRITICAL or WARNING mode. This will override the
631
default interval settings inherited from health settings in `netdata.conf`. The default settings for repeating
632
notifications are `default repeat warning = DURATION` and `default repeat critical = DURATION` which can be found in
633
health stock configuration, when one of these interval is bigger than 0, Netdata will activate the repeat notification
@@ -639,14 +639,14 @@ Format:
639
repeat: [off] [warning DURATION] [critical DURATION]
640
```
641
642
-- `off`: Turns off the repeating feature for the current alarm. This is effective when the default repeat settings has
642
+- `off`: Turns off the repeating feature for the current alert. This is effective when the default repeat settings has
643
been enabled in health configuration.
644
-- `warning DURATION`: Defines the interval when the alarm is in WARNING state. Use `0s` to turn off the repeating
644
+- `warning DURATION`: Defines the interval when the alert is in WARNING state. Use `0s` to turn off the repeating
645
notification for WARNING mode.
646
-- `critical DURATION`: Defines the interval when the alarm is in CRITICAL state. Use `0s` to turn off the repeating
646
+- `critical DURATION`: Defines the interval when the alert is in CRITICAL state. Use `0s` to turn off the repeating
647
notification for CRITICAL mode.
648
649
-#### Alarm line `options`
649
+#### Alert line `options`
650
651
The only possible value for the `options` line is
652
@@ -654,16 +654,16 @@ The only possible value for the `options` line is
654
options: no-clear-notification
655
```
656
657
-For some alarms we need compare two time-frames, to detect anomalies. For example, `health.d/httpcheck.conf` has an
658
-alarm template called `web_service_slow` that compares the average http call response time over the last 3 minutes,
659
-compared to the average over the last hour. It triggers a warning alarm when the average of the last 3 minutes is twice
660
-the average of the last hour. In such cases, it is easy to trigger the alarm, but difficult to tell when the alarm is
657
+For some alerts we need compare two time-frames, to detect anomalies. For example, `health.d/httpcheck.conf` has an
658
+alert template called `web_service_slow` that compares the average http call response time over the last 3 minutes,
659
+compared to the average over the last hour. It triggers a warning alert when the average of the last 3 minutes is twice
660
+the average of the last hour. In such cases, it is easy to trigger the alert, but difficult to tell when the alert is
661
cleared. As time passes, the newest window moves into the older, so the average response time of the last hour will keep
662
-increasing. Eventually, the comparison will find the averages in the two time-frames close enough to clear the alarm.
663
-However, the issue was not resolved, it's just a matter of the newer data "polluting" the old. For such alarms, it's a
662
+increasing. Eventually, the comparison will find the averages in the two time-frames close enough to clear the alert.
663
+However, the issue was not resolved, it's just a matter of the newer data "polluting" the old. For such alerts, it's a
664
good idea to tell Netdata to not clear the notification, by using the `no-clear-notification` option.
665
666
-#### Alarm line `host labels`
666
+#### Alert line `host labels`
667
668
Defines the list of labels present on a host. See our [host labels guide](https://github.com/netdata/netdata/blob/master/docs/guides/using-host-labels.md) for
669
an explanation of host labels and how to implement them.
@@ -684,14 +684,14 @@ And more labels in `netdata.conf` for workstations:
684
room = workstation
685
```
686
687
-By defining labels inside of `netdata.conf`, you can now apply labels to alarms. For example, you can add the following
688
-line to any alarms you'd like to apply to hosts that have the label `room = server`.
687
+By defining labels inside of `netdata.conf`, you can now apply labels to alerts. For example, you can add the following
688
+line to any alerts you'd like to apply to hosts that have the label `room = server`.
689
690
```yaml
691
host labels: room = server
692
```
693
694
-The `host labels` is a space-separated list that accepts simple patterns. For example, you can create an alarm
694
+The `host labels` is a space-separated list that accepts simple patterns. For example, you can create an alert
695
that will be applied to all hosts installed in the last decade with the following line:
696
697
```yaml
@@ -700,9 +700,9 @@ host labels: installed = 201*
700
701
See our [simple patterns docs](https://github.com/netdata/netdata/blob/master/libnetdata/simple_pattern/README.md) for more examples.
702
703
-#### Alarm line `chart labels`
703
+#### Alert line `chart labels`
704
705
-Similar to host labels, the `chart labels` key can be used to filter if an alarm will load or not for a specific chart, based on
705
+Similar to host labels, the `chart labels` key can be used to filter if an alert will load or not for a specific chart, based on
706
whether these chart labels match or not.
707
708
The list of chart labels present on each chart can be obtained from http://localhost:19999/api/v1/charts?all
@@ -729,10 +729,10 @@ is specified that does not exist in the chart, the chart won't be matched.
729
730
See our [simple patterns docs](https://github.com/netdata/netdata/blob/master/libnetdata/simple_pattern/README.md) for more examples.
731
732
-#### Alarm line `info`
732
+#### Alert line `info`
733
734
-The info field can contain a small piece of text describing the alarm or template. This will be rendered in
735
-notifications and UI elements whenever the specific alarm is in focus. An example for the `ram_available` alarm is:
734
+The info field can contain a small piece of text describing the alert or template. This will be rendered in
735
+notifications and UI elements whenever the specific alert is in focus. An example for the `ram_available` alert is:
736
737
```yaml
738
info: percentage of estimated amount of RAM available for userspace processes, without causing swapping
@@ -741,10 +741,10 @@ info: percentage of estimated amount of RAM available for userspace processes, w
741
info fields can contain special variables in their text that will be replaced during run-time to provide more specific
742
alert information. Current variables supported are:
743
744
-| variable | description |
745
-| ---------| ----------- |
746
-| ${family} | Will be replaced by the family instance for the alert (e.g. eth0) |
747
-| ${label:LABEL_NAME} | The variable will be replaced with the value of the label |
744
+| variable | description |
745
+|---------------------|-------------------------------------------------------------------|
746
+| ${family} | Will be replaced by the family instance for the alert (e.g. eth0) |
747
+| ${label:LABEL_NAME} | The variable will be replaced with the value of the label |
748
749
For example, an info field like the following:
750
@@ -771,7 +771,7 @@ Will become:
771
info: average ratio of HTTP responses with unexpected status over the last 5 minutes for the site https://netdata.cloud/
772
```
773
774
-> Please note that variable names are case sensitive.
774
+> Please note that variable names are case-sensitive.
775
776
## Expressions
777
@@ -797,10 +797,10 @@ Expressions can have variables. Variables start with `$`. Check below for more i
797
There are two special values you can use:
798
799
- `nan`, for example `$this != nan` will check if the variable `this` is available. A variable can be `nan` if the
800
- database lookup failed. All calculations (i.e. addition, multiplication, etc) with a `nan` result in a `nan`.
800
+ database lookup failed. All calculations (i.e. addition, multiplication, etc.) with a `nan` result in a `nan`.
801
802
- `inf`, for example `$this != inf` will check if `this` is not infinite. A value or variable can be set to infinite
803
- if divided by zero. All calculations (i.e. addition, multiplication, etc) with a `inf` result in a `inf`.
803
+ if divided by zero. All calculations (i.e. addition, multiplication, etc.) with a `inf` result in a `inf`.
804
805
### Special use of the conditional operator
806
@@ -809,7 +809,7 @@ A common (but not necessarily obvious) use of the conditional evaluation operato
809
avoid bogus messages resulting from small variations in the value when it is varying regularly but staying close to the
810
threshold value, without needing to delay sending messages at all.
811
812
-An example of such usage from the default CPU usage alarms bundled with Netdata is:
812
+An example of such usage from the default CPU usage alerts bundled with Netdata is:
813
814
```yaml
815
warn: $this > (($status >= $WARNING) ? (75) : (85))
@@ -818,9 +818,9 @@ crit: $this > (($status == $CRITICAL) ? (85) : (95))
818
819
The above say:
820
821
-- If the alarm is currently a warning, then the threshold for being considered a warning is 75, otherwise it's 85.
821
+- If the alert is currently a warning, then the threshold for being considered a warning is 75, otherwise it's 85.
822
823
-- If the alarm is currently critical, then the threshold for being considered critical is 85, otherwise it's 95.
823
+- If the alert is currently critical, then the threshold for being considered critical is 85, otherwise it's 95.
824
825
Which in turn, results in the following behavior:
826
@@ -846,26 +846,25 @@ registry](https://registry.my-netdata.io/api/v1/alarm_variables?chart=system.cpu
846
847
Netdata supports 3 internal indexes for variables that will be used in health monitoring.
848
849
-<details markdown="1"><summary>The variables below can be used in both chart alarms and context templates.</summary>
849
+<details markdown="1"><summary>The variables below can be used in both chart alerts and context templates.</summary>
850
851
Although the `alarm_variables` link shows you variables for a particular chart, the same variables can also be used in
852
templates for charts belonging to a given [context](https://github.com/netdata/netdata/blob/master/web/README.md#contexts). The reason is that all charts of a given
853
context are essentially identical, with the only difference being the [family](https://github.com/netdata/netdata/blob/master/web/README.md#families) that
854
identifies a particular hardware or software instance. Charts and templates do not apply to specific families anyway,
855
-unless if you explicitly limit an alarm with the [alarm line `families`](#alarm-line-families).
855
+unless if you explicitly limit an alert with the [alert line `families`](#alert-line-families).
856
857
</details>
858
859
- **chart local variables**. All the dimensions of the chart are exposed as local variables. The value of `$this` for
860
- the other configured alarms of the chart also appears, under the name of each configured alarm.
860
+ the other configured alerts of the chart also appears, under the name of each configured alert.
861
862
Charts also define a few special variables:
863
864
- `$last_collected_t` is the unix timestamp of the last data collection
865
- `$collected_total_raw` is the sum of all the dimensions (their last collected values)
866
- `$update_every` is the update frequency of the chart
867
- - `$green` and `$red` the threshold defined in alarms (these are per chart - the charts
868
- inherits them from the the first alarm that defined them)
867
+ - `$green` and `$red` the threshold defined in alerts (these are per chart - the charts inherits them from the first alert that defined them)
868
869
Chart dimensions define their last calculated (i.e. interpolated) value, exactly as
870
shown on the charts, but also a variable with their name and suffix `_raw` that resolves
@@ -877,35 +876,35 @@ unless if you explicitly limit an alarm with the [alarm line `families`](#alarm-
876
charts, have `family = eth0`. This index includes all local variables, but if there are
877
overlapping variables, only the first are exposed.
878
880
-- **host variables**. All the dimensions of all charts, including all alarms, in fullname.
879
+- **host variables**. All the dimensions of all charts, including all alerts, in fullname.
880
Fullname is `CHART.VARIABLE`, where `CHART` is either the chart id or the chart name (both
881
are supported).
882
883
- **special variables\*** are:
884
886
- - `$this`, which is resolved to the value of the current alarm.
885
+ - `$this`, which is resolved to the value of the current alert.
886
888
- - `$status`, which is resolved to the current status of the alarm (the current = the last
887
+ - `$status`, which is resolved to the current status of the alert (the current = the last
888
status, i.e. before the current database lookup and the evaluation of the `calc` line).
889
This values can be compared with `$REMOVED`, `$UNINITIALIZED`, `$UNDEFINED`, `$CLEAR`,
891
- `$WARNING`, `$CRITICAL`. These values are incremental, ie. `$status > $CLEAR` works as
890
+ `$WARNING`, `$CRITICAL`. These values are incremental, e.g. `$status > $CLEAR` works as
891
expected.
892
893
- `$now`, which is resolved to current unix timestamp.
894
896
-## Alarm statuses
895
+## Alert statuses
896
898
-Alarms can have the following statuses:
897
+Alerts can have the following statuses:
898
900
-- `REMOVED` - the alarm has been deleted (this happens when a SIGUSR2 is sent to Netdata
899
+- `REMOVED` - the alert has been deleted (this happens when a SIGUSR2 is sent to Netdata
900
to reload health configuration)
901
903
-- `UNINITIALIZED` - the alarm is not initialized yet
902
+- `UNINITIALIZED` - the alert is not initialized yet
903
905
-- `UNDEFINED` - the alarm failed to be calculated (i.e. the database lookup failed,
906
- a division by zero occurred, etc)
904
+- `UNDEFINED` - the alert failed to be calculated (i.e. the database lookup failed,
905
+ a division by zero occurred, etc.)
906
908
-- `CLEAR` - the alarm is not armed / raised (i.e. is OK)
907
+- `CLEAR` - the alert is not armed / raised (i.e. is OK)
908
909
- `WARNING` - the warning expression resulted in true or non-zero
910
@@ -913,9 +912,9 @@ Alarms can have the following statuses:
912
913
The external script will be called for all status changes.
914
916
-## Example alarms
915
+## Example alerts
916
918
-Check the `health/health.d/` directory for all alarms shipped with Netdata.
917
+Check the `health/health.d/` directory for all alerts shipped with Netdata.
918
919
Here are a few examples:
920
@@ -962,16 +961,16 @@ The above applies the **template** to all charts that have `context = apache.req
961
every: 10s
962
```
963
965
-The alarm will be evaluated every 10 seconds.
964
+The alert will be evaluated every 10 seconds.
965
966
```yaml
967
warn: $this > ( 5 * $update_every)
968
crit: $this > (10 * $update_every)
969
```
970
972
-If these result in non-zero or true, they trigger the alarm.
971
+If these result in non-zero or true, they trigger the alert.
972
974
-- `$this` refers to the value of this alarm (i.e. the result of the `calc` line.
973
+- `$this` refers to the value of this alert (e.g. the result of the `calc` line).
974
We could also use `$apache_last_collected_secs`.
975
976
`$update_every` is the update frequency of the chart, in seconds.
@@ -997,8 +996,8 @@ template: disk_full_percent
996
997
So, the `calc` line finds the percentage of used space. `$this` resolves to this percentage.
998
1000
-This is a repeating alarm and if the alarm becomes CRITICAL it repeats the notifications every 10 seconds. It also
1001
-repeats notifications every 2 minutes if the alarm goes into WARNING mode.
999
+This is a repeating alert and if the alert becomes CRITICAL it repeats the notifications every 10 seconds. It also
1000
+repeats notifications every 2 minutes if the alert goes into WARNING mode.
1001
1002
### Example 3 - disk fill rate
1003
@@ -1018,7 +1017,7 @@ Calculate the disk fill rate:
1017
1018
In the `calc` line: `$this` is the result of the `lookup` line (i.e. the free space 30 minutes
1019
ago) and `$avail` is the current disk free space. So the `calc` line will either have a positive
1021
-number of GB/second if the disk if filling up, or a negative number of GB/second if the disk is
1020
+number of GB/second if the disk is filling up, or a negative number of GB/second if the disk is
1021
freeing up space.
1022
1023
There is no `warn` or `crit` lines here. So, this template will just do the calculation and
@@ -1039,7 +1038,7 @@ The `calc` line estimates the time in hours, we will run out of disk space. Of c
1038
positive values are interesting for this check, so the warning and critical conditions check
1039
for positive values and that we have enough free space for 48 and 24 hours respectively.
1040
1042
-Once this alarm triggers we will receive an email like this:
1041
+Once this alert triggers we will receive an email like this:
1042
1043

1044
@@ -1057,11 +1056,11 @@ template: 30min_packet_drops
1056
1057
The `lookup` line will calculate the sum of the all dropped packets in the last 30 minutes.
1058
1060
-The `crit` line will issue a critical alarm if even a single packet has been dropped.
1059
+The `crit` line will issue a critical alert if even a single packet has been dropped.
1060
1061
Note that the drops chart does not exist if a network interface has never dropped a single packet.
1063
-When Netdata detects a dropped packet, it will add the chart and it will automatically attach this
1064
-alarm to it.
1062
+When Netdata detects a dropped packet, it will add the chart, and it will automatically attach this
1063
+alert to it.
1064
1065
### Example 5 - CPU usage
1066
@@ -1079,7 +1078,7 @@ template: cpu_template
1078
```
1079
1080
The `lookup` line will calculate the average CPU usage from system and user over the last minute. Because we have
1082
-the foreach in the `lookup` line, Netdata will create two independent alarms called `cpu_template_system`
1081
+the foreach in the `lookup` line, Netdata will create two independent alerts called `cpu_template_system`
1082
and `dim_template_user` that will have all the other parameters shared among them.
1083
1084
### Example 6 - CPU usage
@@ -1098,11 +1097,11 @@ template: cpu_template
1097
```
1098
1099
The `lookup` line will calculate the average of CPU usage from system and user over the last minute. In this case
1101
-Netdata will create alarms for all dimensions of the chart.
1100
+Netdata will create alerts for all dimensions of the chart.
1101
1103
-### Example 7 - Z-Score based alarm
1102
+### Example 7 - Z-Score based alert
1103
1105
-Derive a "[Z Score](https://en.wikipedia.org/wiki/Standard_score)" based alarm on `user` dimension of the `system.cpu` chart:
1104
+Derive a "[Z Score](https://en.wikipedia.org/wiki/Standard_score)" based alert on `user` dimension of the `system.cpu` chart:
1105
1106
```yaml
1107
alarm: cpu_user_mean
@@ -1124,9 +1123,9 @@ lookup: mean -10s of user
1123
crit: $this < -3 or $this > 3
1124
```
1125
1127
-Since [`z = (x - mean) / stddev`](https://en.wikipedia.org/wiki/Standard_score) we create two input alarms, one for `mean` and one for `stddev` and then use them both as inputs in our final `cpu_user_zscore` alarm.
1126
+Since [`z = (x - mean) / stddev`](https://en.wikipedia.org/wiki/Standard_score) we create two input alerts, one for `mean` and one for `stddev` and then use them both as inputs in our final `cpu_user_zscore` alert.
1127
1129
-### Example 8 - [Anomaly rate](https://github.com/netdata/netdata/blob/master/ml/README.md#anomaly-rate) based CPU dimensions alarm
1128
+### Example 8 - [Anomaly rate](https://github.com/netdata/netdata/blob/master/ml/README.md#anomaly-rate) based CPU dimensions alert
1129
1130
Warning if 5 minute rolling [anomaly rate](https://github.com/netdata/netdata/blob/master/ml/README.md#anomaly-rate) for any CPU dimension is above 5%, critical if it goes above 20%:
1131
@@ -1145,9 +1144,9 @@ template: ml_5min_cpu_dims
1144
```
1145
1146
The `lookup` line will calculate the average anomaly rate of each `system.cpu` dimension over the last 5 minues. In this case
1148
-Netdata will create alarms for all dimensions of the chart.
1147
+Netdata will create alerts for all dimensions of the chart.
1148
1150
-### Example 9 - [Anomaly rate](https://github.com/netdata/netdata/blob/master/ml/README.md#anomaly-rate) based CPU chart alarm
1149
+### Example 9 - [Anomaly rate](https://github.com/netdata/netdata/blob/master/ml/README.md#anomaly-rate) based CPU chart alert
1150
1151
Warning if 5 minute rolling [anomaly rate](https://github.com/netdata/netdata/blob/master/ml/README.md#anomaly-rate) averaged across all CPU dimensions is above 5%, critical if it goes above 20%:
1152
@@ -1166,9 +1165,9 @@ template: ml_5min_cpu_chart
1165
```
1166
1167
The `lookup` line will calculate the average anomaly rate across all `system.cpu` dimensions over the last 5 minues. In this case
1169
-Netdata will create one alarm for the chart.
1168
+Netdata will create one alert for the chart.
1169
1171
-### Example 10 - [Anomaly rate](https://github.com/netdata/netdata/blob/master/ml/README.md#anomaly-rate) based node level alarm
1170
+### Example 10 - [Anomaly rate](https://github.com/netdata/netdata/blob/master/ml/README.md#anomaly-rate) based node level alert
1171
1172
Warning if 5 minute rolling [anomaly rate](https://github.com/netdata/netdata/blob/master/ml/README.md#anomaly-rate) averaged across all ML enabled dimensions is above 5%, critical if it goes above 20%:
1173
@@ -1188,10 +1187,10 @@ template: ml_5min_node
1187
1188
The `lookup` line will use the `anomaly_rate` dimension of the `anomaly_detection.anomaly_rate` ML chart to calculate the average [node level anomaly rate](https://github.com/netdata/netdata/blob/master/ml/README.md#node-anomaly-rate) over the last 5 minues.
1189
1191
-## Use dimension templates to create dynamic alarms
1190
+## Use dimension templates to create dynamic alerts
1191
1193
-In v1.18 of Netdata, we introduced **dimension templates** for alarms, which simplifies the process of
1194
-writing [alarm entities](#health-entity-reference) for
1192
+In v1.18 of Netdata, we introduced **dimension templates** for alerts, which simplifies the process of
1193
+writing [alert entities](#health-entity-reference) for
1194
charts with many dimensions.
1195
1196
Dimension templates can condense many individual entities into one—no more copy-pasting one entity and changing the
@@ -1199,21 +1198,21 @@ Dimension templates can condense many individual entities into one—no more cop
1198
1199
### The fundamentals of `foreach`
1200
1202
-> **Note**: works only with [templates](#alarm-line-alarm-or-template).
1201
+> **Note**: works only with [templates](#alert-line-alarm-or-template).
1202
1203
Our dimension templates update creates a new `foreach` parameter to the
1205
-existing [`lookup` line](#alarm-line-lookup). This
1204
+existing [`lookup` line](#alert-line-lookup). This
1205
is where the magic happens.
1206
1208
-You use the `foreach` parameter to specify which dimensions you want to monitor with this single alarm. You can separate
1207
+You use the `foreach` parameter to specify which dimensions you want to monitor with this single alert. You can separate
1208
them with a comma (`,`) or a pipe (`|`). You can also use
1209
a [Netdata simple pattern](https://github.com/netdata/netdata/blob/master/libnetdata/simple_pattern/README.md) to create
1211
-many alarms with a regex-like syntax.
1210
+many alerts with a regex-like syntax.
1211
1212
The `foreach` parameter _has_ to be the last parameter in your `lookup` line, and if you have both `of` and `foreach` in
1213
the same `lookup` line, Netdata will ignore the `of` parameter and use `foreach` instead.
1214
1216
-Let's get into some examples so you can see how the new parameter works.
1215
+Let's get into some examples, so you can see how the new parameter works.
1216
1217
> ⚠️ The following entities are examples to showcase the functionality and syntax of dimension templates. They are not
1218
> meant to be run as-is on production systems.
@@ -1246,7 +1245,7 @@ lookup: average -10m of nice
1245
crit: $this > 80
1246
```
1247
1249
-With dimension templates, you can condense these into a single template. Take note of the `alarm` and `lookup` lines.
1248
+With dimension templates, you can condense these into a single template. Take note of the `lookup` line.
1249
1250
```yaml
1251
template: cpu_template
@@ -1262,27 +1261,27 @@ and `_` being the only allowed symbols.
1261
1262
The `lookup` line has changed from `of` to `foreach`, and we're now passing three dimensions.
1263
1265
-In this example, Netdata will create three alarms with the names `cpu_template_system`, `cpu_template_user`, and
1266
-`cpu_template_nice`. Every minute, each alarm will use the same database query to calculate the average CPU usage for
1267
-the `system`, `user`, and `nice` dimensions over the last 10 minutes and send out alarms if necessary.
1264
+In this example, Netdata will create three alerts with the names `cpu_template_system`, `cpu_template_user`, and
1265
+`cpu_template_nice`. Every minute, each alert will use the same database query to calculate the average CPU usage for
1266
+the `system`, `user`, and `nice` dimensions over the last 10 minutes and send out alerts if necessary.
1267
1269
-You can find these three alarms active by clicking on the **Alarms** button in the top navigation, and then clicking on
1268
+You can find these three alerts active by clicking on the **Alerts** button in the top navigation, and then clicking on
1269
the **All** tab and scrolling to the **system - cpu** collapsible section.
1270
1272
-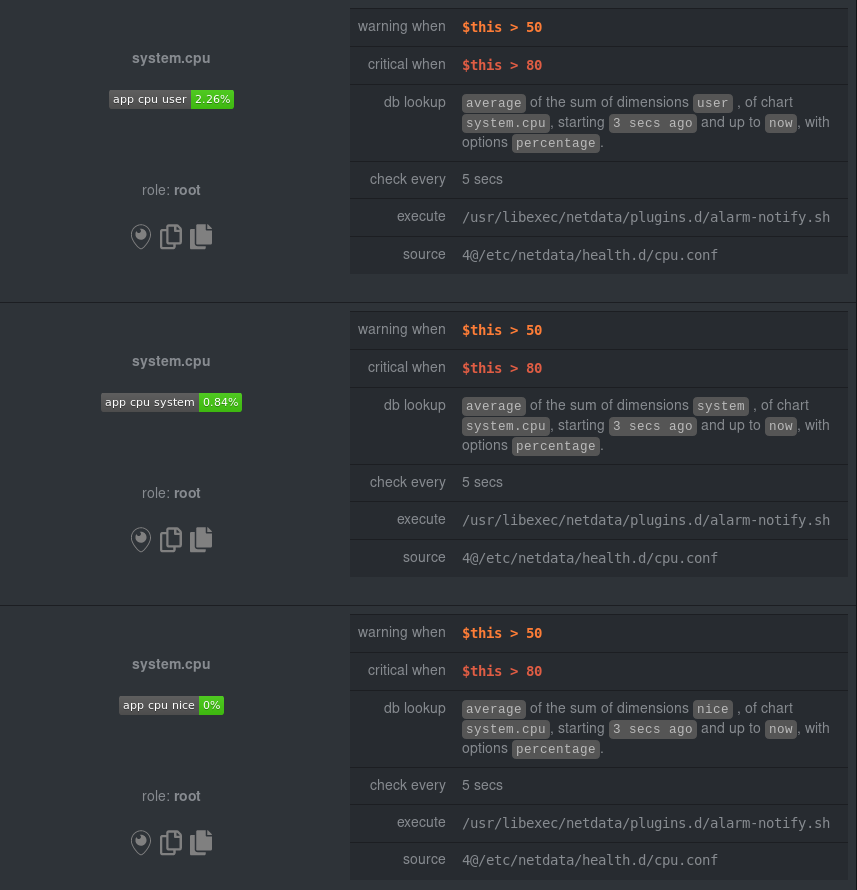
1271
+
1272
1274
-Let's look at some other examples of how `foreach` works so you can best apply it in your configurations.
1273
+Let's look at some other examples of how `foreach` works, so you can best apply it in your configurations.
1274
1275
### Using a Netdata simple pattern in `foreach`
1276
1278
-In the last example, we used `foreach system,user,nice` to create three distinct alarms using dimension templates. But
1279
-what if you want to quickly create alarms for _all_ the dimensions of a given chart?
1277
+In the last example, we used `foreach system,user,nice` to create three distinct alerts using dimension templates. But
1278
+what if you want to quickly create alerts for _all_ the dimensions of a given chart?
1279
1280
Use a [simple pattern](https://github.com/netdata/netdata/blob/master/libnetdata/simple_pattern/README.md)! One example of a simple pattern is a single wildcard
1281
(`*`).
1282
1283
Instead of monitoring system CPU usage, let's monitor per-application CPU usage using the `apps.cpu` chart. Passing a
1285
-wildcard as the simple pattern tells Netdata to create a separate alarm for _every_ process on your system:
1284
+wildcard as the simple pattern tells Netdata to create a separate alert for _every_ process on your system:
1285
1286
```yaml
1287
alarm: app_cpu
@@ -1293,21 +1292,21 @@ lookup: average -10m percentage foreach *
1292
crit: $this > 80
1293
```
1294
1296
-This entity will now create alarms for every dimension in the `apps.cpu` chart. Given that most `apps.cpu` charts have
1295
+This entity will now create alerts for every dimension in the `apps.cpu` chart. Given that most `apps.cpu` charts have
1296
10 or more dimensions, using the wildcard ensures you catch every CPU-hogging process.
1297
1298
To learn more about how to use simple patterns with dimension templates, see
1299
our [simple patterns documentation](https://github.com/netdata/netdata/blob/master/libnetdata/simple_pattern/README.md).
1300
1302
-### Using `foreach` with alarm templates
1301
+### Using `foreach` with alert templates
1302
1303
Dimension templates also work
1305
-with [alarm templates](#alarm-line-alarm-or-template).
1306
-Alarm templates help you create alarms for all the charts with a given context—for example, all the cores of your
1304
+with [alert templates](#alert-line-alarm-or-template).
1305
+Alert templates help you create alerts for all the charts with a given context—for example, all the cores of your
1306
system's CPU.
1307
1309
-By combining the two, you can create dozens of individual alarms with a single template entity. Here's how you would
1310
-create alarms for the `system`, `user`, and `nice` dimensions for every chart in the `cpu.cpu` context—or, in other
1308
+By combining the two, you can create dozens of individual alerts with a single template entity. Here's how you would
1309
+create alerts for the `system`, `user`, and `nice` dimensions for every chart in the `cpu.cpu` context—or, in other
1310
words, every CPU core.
1311
1312
```yaml
@@ -1319,7 +1318,7 @@ template: cpu_template
1318
crit: $this > 80
1319
```
1320
1322
-On a system with a 6-core, 12-thread Ryzen 5 1600 CPU, this one entity creates alarms on the following charts and
1321
+On a system with a 6-core, 12-thread Ryzen 5 1600 CPU, this one entity creates alerts on the following charts and
1322
dimensions:
1323
1324
- `cpu.cpu0`
@@ -1344,11 +1343,11 @@ dimensions:
1343
- `cpu_template_system`
1344
- `cpu_template_nice`
1345
1347
-And how just a few of those dimension template-generated alarms look like in the Netdata dashboard.
1346
+And how just a few of those dimension template-generated alerts look like in the Netdata dashboard.
1347
1349
-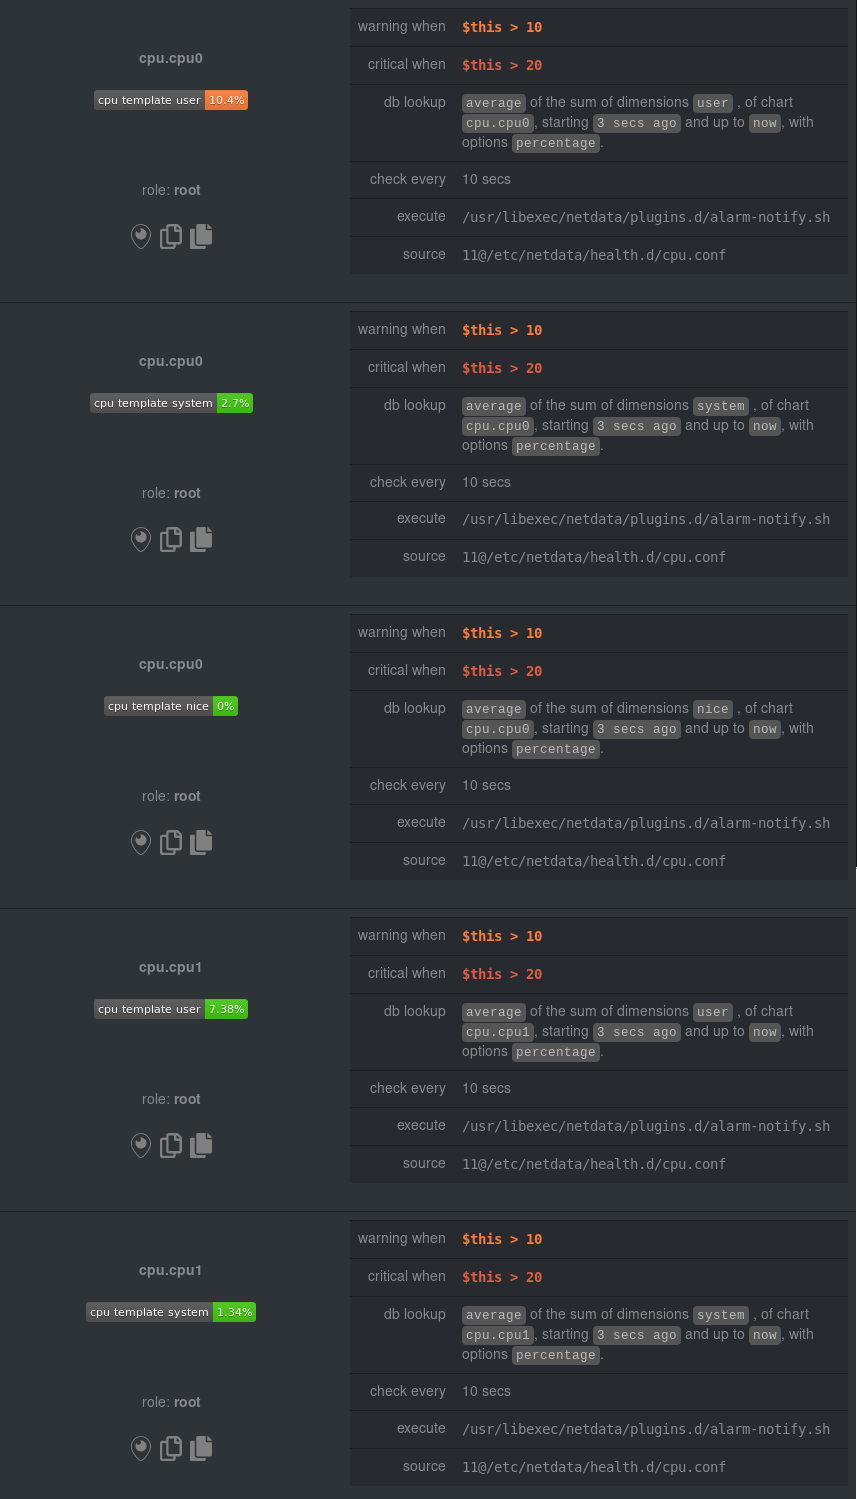
1348
+
1349
1351
-All in all, this single entity creates 36 individual alarms. Much easier than writing 36 separate entities in your
1350
+All in all, this single entity creates 36 individual alerts. Much easier than writing 36 separate entities in your
1351
health configuration files!
1352
1353
## Troubleshooting
@@ -1366,7 +1365,7 @@ output in debug.log.
1365
You can find the context of charts by looking up the chart in either `http://NODE:19999/netdata.conf` or
1366
`http://NODE:19999/api/v1/charts`, replacing `NODE` with the IP address or hostname for your Agent dashboard.
1367
1369
-You can find how Netdata interpreted the expressions by examining the alarm at
1368
+You can find how Netdata interpreted the expressions by examining the alert at
1369
`http://NODE:19999/api/v1/alarms?all`. For each expression, Netdata will return the expression as given in its
1370
config file, and the same expression with additional parentheses added to indicate the evaluation flow of the
1371
expression.
health/notifications/README.md
+10
-10
@@ -58,7 +58,7 @@ You can send the notification to multiple recipients by separating the emails wi
58
# RECIPIENTS PER ROLE
59
60
# -----------------------------------------------------------------------------
61
-# generic system alarms
61
+# generic system alerts
62
# CPU, disks, network interfaces, entropy, etc
63
64
role_recipients_email[sysadmin]="someone@exaple.com someoneelse@example.com"
@@ -106,10 +106,10 @@ sudo su -s /bin/bash netdata
106
# enable debugging info on the console
107
export NETDATA_ALARM_NOTIFY_DEBUG=1
108
109
-# send test alarms to sysadmin
109
+# send test alerts to sysadmin
110
/usr/libexec/netdata/plugins.d/alarm-notify.sh test
111
112
-# send test alarms to any role
112
+# send test alerts to any role
113
/usr/libexec/netdata/plugins.d/alarm-notify.sh test "ROLE"
114
```
115
@@ -129,17 +129,17 @@ If you are [running your own registry](https://github.com/netdata/netdata/blob/m
129
130
When you define recipients per role for notification methods, you can append `|critical` to limit the notifications that are sent.
131
132
-In the following examples, the first recipient receives all the alarms, while the second one receives only notifications for alarms that have at some point become critical.
133
-The second user may still receive warning and clear notifications, but only for the event that previously caused a critical alarm.
132
+In the following examples, the first recipient receives all the alerts, while the second one receives only notifications for alerts that have at some point become critical.
133
+The second user may still receive warning and clear notifications, but only for the event that previously caused a critical alert.
134
135
```conf
136
email : "user1@example.com user2@example.com|critical"
137
pushover : "2987343...9437837 8756278...2362736|critical"
138
telegram : "111827421 112746832|critical"
139
- slack : "alarms disasters|critical"
140
- alerta : "alarms disasters|critical"
141
- flock : "alarms disasters|critical"
142
- discord : "alarms disasters|critical"
139
+ slack : "alerts disasters|critical"
140
+ alerta : "alerts disasters|critical"
141
+ flock : "alerts disasters|critical"
142
+ discord : "alerts disasters|critical"
143
twilio : "+15555555555 +17777777777|critical"
144
messagebird: "+15555555555 +17777777777|critical"
145
kavenegar : "09155555555 09177777777|critical"
@@ -148,7 +148,7 @@ The second user may still receive warning and clear notifications, but only for
148
```
149
150
If a per role recipient is set to an empty string, the default recipient of the given
151
-notification method (email, pushover, telegram, slack, alerta, etc) will be used.
151
+notification method (email, pushover, telegram, slack, alerta, etc.) will be used.
152
153
To disable a notification, use the recipient called: disabled
154
This works for all notification methods (including the default recipients).
health/notifications/awssns/README.md
+15
-15
@@ -63,14 +63,14 @@ Edit `health_alarm_notify.conf`, changes to this file do not require restarting
63
| `${alarm}` | Like "name = value units" |
64
| `${status_message}` | Like "needs attention", "recovered", "is critical" |
65
| `${severity}` | Like "Escalated to CRITICAL", "Recovered from WARNING" |
66
- | `${raised_for}` | Like "(alarm was raised for 10 minutes)" |
66
+ | `${raised_for}` | Like "(alert was raised for 10 minutes)" |
67
| `${host}` | The host generated this event |
68
| `${url_host}` | Same as ${host} but URL encoded |
69
| `${unique_id}` | The unique id of this event |
70
- | `${alarm_id}` | The unique id of the alarm that generated this event |
71
- | `${event_id}` | The incremental id of the event, for this alarm id |
70
+ | `${alarm_id}` | The unique id of the alert that generated this event |
71
+ | `${event_id}` | The incremental id of the event, for this alert id |
72
| `${when}` | The timestamp this event occurred |
73
- | `${name}` | The name of the alarm, as given in netdata health.d entries |
73
+ | `${name}` | The name of the alert, as given in netdata health.d entries |
74
| `${url_name}` | Same as ${name} but URL encoded |
75
| `${chart}` | The name of the chart (type.id) |
76
| `${url_chart}` | Same as ${chart} but URL encoded |
@@ -78,27 +78,27 @@ Edit `health_alarm_notify.conf`, changes to this file do not require restarting
78
| `${url_family}` | Same as ${family} but URL encoded |
79
| `${status}` | The current status : REMOVED, UNINITIALIZED, UNDEFINED, CLEAR, WARNING, CRITICAL |
80
| `${old_status}` | The previous status: REMOVED, UNINITIALIZED, UNDEFINED, CLEAR, WARNING, CRITICAL |
81
- | `${value}` | The current value of the alarm |
82
- | `${old_value}` | The previous value of the alarm |
83
- | `${src}` | The line number and file the alarm has been configured |
84
- | `${duration}` | The duration in seconds of the previous alarm state |
81
+ | `${value}` | The current value of the alert |
82
+ | `${old_value}` | The previous value of the alert |
83
+ | `${src}` | The line number and file the alert has been configured |
84
+ | `${duration}` | The duration in seconds of the previous alert state |
85
| `${duration_txt}` | Same as ${duration} for humans |
86
| `${non_clear_duration}` | The total duration in seconds this is/was non-clear |
87
| `${non_clear_duration_txt}` | Same as ${non_clear_duration} for humans |
88
| `${units}` | The units of the value |
89
- | `${info}` | A short description of the alarm |
89
+ | `${info}` | A short description of the alert |
90
| `${value_string}` | Friendly value (with units) |
91
| `${old_value_string}` | Friendly old value (with units) |
92
- | `${image}` | The URL of an image to represent the status of the alarm |
93
- | `${color}` | A color in AABBCC format for the alarm |
92
+ | `${image}` | The URL of an image to represent the status of the alert |
93
+ | `${color}` | A color in AABBCC format for the alert |
94
| `${goto_url}` | The URL the user can click to see the netdata dashboard |
95
- | `${calc_expression}` | The expression evaluated to provide the value for the alarm |
95
+ | `${calc_expression}` | The expression evaluated to provide the value for the alert |
96
| `${calc_param_values}` | The value of the variables in the evaluated expression |
97
- | `${total_warnings}` | The total number of alarms in WARNING state on the host |
98
- | `${total_critical}` | The total number of alarms in CRITICAL state on the host |
97
+ | `${total_warnings}` | The total number of alerts in WARNING state on the host |
98
+ | `${total_critical}` | The total number of alerts in CRITICAL state on the host |
99
100
3. Set `DEFAULT_RECIPIENT_AWSSNS` to the Topic ARN you noted down upon creating the Topic.
101
- All roles will default to this variable if left unconfigured.
101
+ All roles will default to this variable if it is not configured.
102
103
You can then have different recipient Topics per **role**, by editing `DEFAULT_RECIPIENT_AWSSNS` with the Topic ARN you want, in the following entries at the bottom of the same file:
104
health/notifications/custom/README.md
+16
-16
@@ -39,7 +39,7 @@ Edit `health_alarm_notify.conf`, changes to this file do not require restarting
39
# limit it to 160 characters and encode it for use in a URL
40
urlencode "${msg:0:160}" >/dev/null; msg="${REPLY}"
41
42
- # a space separated list of the recipients to send alarms to
42
+ # a space separated list of the recipients to send alerts to
43
to="${1}"
44
45
for phone in ${to}; do
@@ -67,14 +67,14 @@ Edit `health_alarm_notify.conf`, changes to this file do not require restarting
67
| `${alarm}` | Like "name = value units" |
68
| `${status_message}` | Like "needs attention", "recovered", "is critical" |
69
| `${severity}` | Like "Escalated to CRITICAL", "Recovered from WARNING" |
70
- | `${raised_for}` | Like "(alarm was raised for 10 minutes)" |
70
+ | `${raised_for}` | Like "(alert was raised for 10 minutes)" |
71
| `${host}` | The host generated this event |
72
| `${url_host}` | Same as ${host} but URL encoded |
73
| `${unique_id}` | The unique id of this event |
74
- | `${alarm_id}` | The unique id of the alarm that generated this event |
75
- | `${event_id}` | The incremental id of the event, for this alarm id |
74
+ | `${alarm_id}` | The unique id of the alert that generated this event |
75
+ | `${event_id}` | The incremental id of the event, for this alert id |
76
| `${when}` | The timestamp this event occurred |
77
- | `${name}` | The name of the alarm, as given in netdata health.d entries |
77
+ | `${name}` | The name of the alert, as given in netdata health.d entries |
78
| `${url_name}` | Same as ${name} but URL encoded |
79
| `${chart}` | The name of the chart (type.id) |
80
| `${url_chart}` | Same as ${chart} but URL encoded |
@@ -82,24 +82,24 @@ Edit `health_alarm_notify.conf`, changes to this file do not require restarting
82
| `${url_family}` | Same as ${family} but URL encoded |
83
| `${status}` | The current status : REMOVED, UNINITIALIZED, UNDEFINED, CLEAR, WARNING, CRITICAL |
84
| `${old_status}` | The previous status: REMOVED, UNINITIALIZED, UNDEFINED, CLEAR, WARNING, CRITICAL |
85
- | `${value}` | The current value of the alarm |
86
- | `${old_value}` | The previous value of the alarm |
87
- | `${src}` | The line number and file the alarm has been configured |
88
- | `${duration}` | The duration in seconds of the previous alarm state |
85
+ | `${value}` | The current value of the alert |
86
+ | `${old_value}` | The previous value of the alert |
87
+ | `${src}` | The line number and file the alert has been configured |
88
+ | `${duration}` | The duration in seconds of the previous alert state |
89
| `${duration_txt}` | Same as ${duration} for humans |
90
| `${non_clear_duration}` | The total duration in seconds this is/was non-clear |
91
| `${non_clear_duration_txt}` | Same as ${non_clear_duration} for humans |
92
| `${units}` | The units of the value |
93
- | `${info}` | A short description of the alarm |
93
+ | `${info}` | A short description of the alert |
94
| `${value_string}` | Friendly value (with units) |
95
| `${old_value_string}` | Friendly old value (with units) |
96
- | `${image}` | The URL of an image to represent the status of the alarm |
97
- | `${color}` | A color in AABBCC format for the alarm |
96
+ | `${image}` | The URL of an image to represent the status of the alert |
97
+ | `${color}` | A color in AABBCC format for the alert |
98
| `${goto_url}` | The URL the user can click to see the netdata dashboard |
99
- | `${calc_expression}` | The expression evaluated to provide the value for the alarm |
99
+ | `${calc_expression}` | The expression evaluated to provide the value for the alert |
100
| `${calc_param_values}` | The value of the variables in the evaluated expression |
101
- | `${total_warnings}` | The total number of alarms in WARNING state on the host |
102
- | `${total_critical}` | The total number of alarms in CRITICAL state on the host |
101
+ | `${total_warnings}` | The total number of alerts in WARNING state on the host |
102
+ | `${total_critical}` | The total number of alerts in CRITICAL state on the host |
103
104
You can then have different `${to}` variables per **role**, by editing `DEFAULT_RECIPIENT_CUSTOM` with the variable you want, in the following entries at the bottom of the same file:
105
@@ -129,7 +129,7 @@ custom_sender() {
129
# limit it to 160 characters and encode it for use in a URL
130
urlencode "${msg:0:160}" >/dev/null; msg="${REPLY}"
131
132
- # a space separated list of the recipients to send alarms to
132
+ # a space separated list of the recipients to send alerts to
133
to="${1}"
134
135
for phone in ${to}; do
health/notifications/dynatrace/README.md
+2
-2
@@ -21,7 +21,7 @@ You will need:
21
- An API Space. This is the URL part of the page you have access in order to generate the API Token.
22
For example, the URL for a generated API token might look like: `https://monitor.illumineit.com/e/2a93fe0e-4cd5-469a-9d0d-1a064235cfce/#settings/integration/apikeys;gf=all` In that case, the Space is `2a93fe0e-4cd5-469a-9d0d-1a064235cfce`.
23
- A Server Tag. To generate one on your Dynatrace Server, go to **Settings** --> **Tags** --> **Manually applied tags** and create the Tag.
24
- The Netdata alarm is sent as a Dynatrace Event to be correlated with all those hosts tagged with this Tag you have created.
24
+ The Netdata alert is sent as a Dynatrace Event to be correlated with all those hosts tagged with this Tag you have created.
25
- terminal access to the Agent you wish to configure
26
27
## Configure Netdata to send alert notifications to Dynatrace
@@ -42,7 +42,7 @@ Edit `health_alarm_notify.conf`:
42
3. Set `DYNATRACE_TOKEN` to your Dynatrace API authentication token
43
4. Set `DYNATRACE_SPACE` to the API Space, it is the URL part of the page you have access in order to generate the API Token. For example, the URL for a generated API token might look like: `https://monitor.illumineit.com/e/2a93fe0e-4cd5-469a-9d0d-1a064235cfce/#settings/integration/apikeys;gf=all` In that case, the Space is `2a93fe0e-4cd5-469a-9d0d-1a064235cfce`.
44
5. Set `DYNATRACE_TAG_VALUE` to your Dynatrace Server Tag.
45
-6. `DYNATRACE_ANNOTATION_TYPE` can be left to its default value `Netdata Alarm`, but you can change it to better fit your needs.
45
+6. `DYNATRACE_ANNOTATION_TYPE` can be left to its default value `Netdata Alert`, but you can change it to better fit your needs.
46
7. Set `DYNATRACE_EVENT` to the Dynatrace `eventType` you want, possible values are:
47
`AVAILABILITY_EVENT`, `CUSTOM_ALERT`, `CUSTOM_ANNOTATION`, `CUSTOM_CONFIGURATION`, `CUSTOM_DEPLOYMENT`, `CUSTOM_INFO`, `ERROR_EVENT`, `MARKED_FOR_TERMINATION`, `PERFORMANCE_EVENT`, `RESOURCE_CONTENTION_EVENT`. You can read more [here](https://www.dynatrace.com/support/help/dynatrace-api/environment-api/events-v2/post-event#request-body-objects)
48
health/notifications/email/README.md
+1
-1
@@ -47,7 +47,7 @@ Edit `health_alarm_notify.conf`, changes to this file do not require restarting
47
48
2. Set `SEND_EMAIL` to `YES`.
49
3. Set `DEFAULT_RECIPIENT_EMAIL` to the email address you want the email to be sent by default.
50
- You can define multiple email addresses like this: `alarms@example.com systems@example.com`.
50
+ You can define multiple email addresses like this: `alerts@example.com systems@example.com`.
51
All roles will default to this variable if left unconfigured.
52
4. There are also other optional configuration entries that can be found in the same section of the file.
53
health/notifications/flock/README.md
+1
-1
@@ -58,7 +58,7 @@ An example of a working configuration would be:
58
59
SEND_FLOCK="YES"
60
FLOCK_WEBHOOK_URL="https://api.flock.com/hooks/sendMessage/XXXXXXXXXXXXXXXXXXXXXXXXXXXXXXX"
61
-DEFAULT_RECIPIENT_FLOCK="alarms"
61
+DEFAULT_RECIPIENT_FLOCK="alerts"
62
```
63
64
## Test the notification method
health/notifications/gotify/README.md
+1
-1
@@ -10,7 +10,7 @@ Learn how to send alerts to your Gotify instance using Netdata's Agent alert not
10
11
This is what you will get:
12
13
-<img src="https://user-images.githubusercontent.com/103264516/162509205-1e88e5d9-96b6-4f7f-9426-182776158128.png" alt="Example alarm notifications in Gotify" width="70%"></img>
13
+<img src="https://user-images.githubusercontent.com/103264516/162509205-1e88e5d9-96b6-4f7f-9426-182776158128.png" alt="Example alert notifications in Gotify" width="70%"></img>
14
15
## Prerequisites
16
health/notifications/hangouts/README.md
+5
-5
@@ -12,7 +12,7 @@ learn_autogeneration_metadata: "{'part_of_cloud': False, 'part_of_agent': True}"
12
# Google Hangouts agent alert notifications
13
14
[Google Hangouts](https://hangouts.google.com/) is a cross-platform messaging app developed by Google. You can configure
15
-Netdata to send alarm notifications to a Hangouts room in order to stay aware of possible health or performance issues
15
+Netdata to send alert notifications to a Hangouts room in order to stay aware of possible health or performance issues
16
on your nodes. Here's an example of the notification in action:
17
18
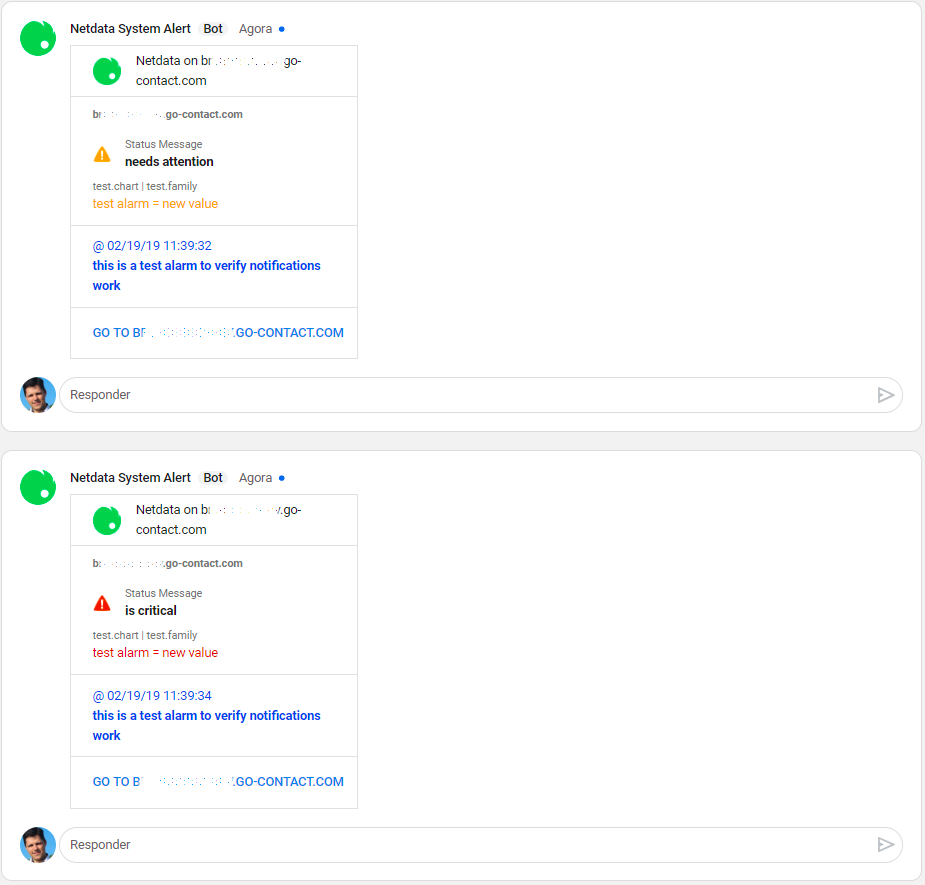
@@ -30,7 +30,7 @@ Set the webhook URIs and room names in `health_alarm_notify.conf`. To edit it on
30
31
## Threads (optional)
32
33
-Instead to receive alarms on different threads, Netdata allows you to concentrate them inside an unique thread when you
33
+Instead, to receive alerts on different threads, Netdata allows you to concentrate them inside a unique thread when you
34
set the variable `HANGOUTS_WEBHOOK_THREAD[NAME]`.
35
36
```
@@ -49,11 +49,11 @@ HANGOUTS_WEBHOOK_URI[development]="https://chat.googleapis.com/v1/spaces/AAAAYYY
49
# if a DEFAULT_RECIPIENT_HANGOUTS are not configured,
50
# notifications wouldn't be send to hangouts rooms.
51
# DEFAULT_RECIPIENT_HANGOUTS="systems development|critical"
52
-DEFAULT_RECIPIENT_HANGOUTS="sysadmin devops alarms|critical"
52
+DEFAULT_RECIPIENT_HANGOUTS="sysadmin devops alerts|critical"
53
```
54
55
-You can define multiple rooms like this: `sysadmin devops alarms|critical`.
55
+You can define multiple rooms like this: `sysadmin devops alerts|critical`.
56
57
-The keywords `sysadmin`, `devops`, and `alarms` are Hangouts rooms.
57
+The keywords `sysadmin`, `devops`, and `alerts` are Hangouts rooms.
58
59
health/notifications/irc/README.md
+5
-5
@@ -49,13 +49,13 @@ Edit `health_alarm_notify.conf`, changes to this file do not require restarting
49
50
2. Set `SEND_IRC` to `YES`
51
3. Set `DEFAULT_RECIPIENT_IRC` to one or more channels to post the messages to.
52
- You can define multiple channels like this: `#alarms #systems`.
53
- All roles will default to this variable if left unconfigured.
52
+ You can define multiple channels like this: `#alerts #systems`.
53
+ All roles will default to this variable if it is not configured.
54
4. Set `IRC_NETWORK` to the IRC network which your preferred channels belong to.
55
5. Set `IRC_PORT` to the IRC port to which a connection will occur.
56
6. Set `IRC_NICKNAME` to the IRC nickname which is required to send the notification.
57
It must not be an already registered name as the connection's `MODE` is defined as a `guest`.
58
-7. Set `IRC_REALNAME` to the IRC realname which is required in order to make he connection.
58
+7. Set `IRC_REALNAME` to the IRC realname which is required in order to make the connection.
59
60
You can then have different channels per **role**, by editing `DEFAULT_RECIPIENT_IRC` with the channel you want, in the following entries at the bottom of the same file:
61
@@ -77,9 +77,9 @@ An example of a working configuration would be:
77
# irc notification options
78
#
79
SEND_IRC="YES"
80
-DEFAULT_RECIPIENT_IRC="#system-alarms"
80
+DEFAULT_RECIPIENT_IRC="#system-alerts"
81
IRC_NETWORK="irc.freenode.net"
82
-IRC_NICKNAME="netdata-alarm-user"
82
+IRC_NICKNAME="netdata-alert-user"
83
IRC_REALNAME="netdata-user"
84
```
85
health/notifications/matrix/README.md
+1
-1
@@ -12,7 +12,7 @@ You will need:
12
13
- The url of the homeserver (`https://homeserver:port`).
14
- Credentials for connecting to the homeserver, in the form of a valid access token for your account (or for a dedicated notification account). These tokens usually don't expire.
15
-- The room ids that you want to sent the notification to.
15
+- The room ids that you want to send the notification to.
16
17
## Configure Netdata to send alert notifications to Matrix
18
health/notifications/ntfy/README.md
+2
-2
@@ -10,7 +10,7 @@ Learn how to send alerts to an ntfy server using Netdata's Agent alert notificat
10
11
This is what you will get:
12
13
-<img src="https://user-images.githubusercontent.com/5953192/230661442-a180abe2-c8bd-496e-88be-9038e62fb4f7.png" alt="Example alarm notifications in Ntfy" width="60%"></img>
13
+<img src="https://user-images.githubusercontent.com/5953192/230661442-a180abe2-c8bd-496e-88be-9038e62fb4f7.png" alt="Example alert notifications in Ntfy" width="60%"></img>
14
15
## Prerequisites
16
@@ -37,7 +37,7 @@ Edit `health_alarm_notify.conf`, changes to this file do not require restarting
37
2. Set `DEFAULT_RECIPIENT_NTFY` to the URL formed by the server-topic combination you want the alert notifications to be sent to. Unless you are hosting your own server, the server should always be set to [https://ntfy.sh](https://ntfy.sh)
38
39
You can define multiple recipient URLs like this: `https://SERVER1/TOPIC1 https://SERVER2/TOPIC2`
40
- All roles will default to this variable if left unconfigured.
40
+ All roles will default to this variable if it is not configured.
41
42
> ### Warning
43
> All topics published on https://ntfy.sh are public, so anyone can subscribe to them and follow your notifications. To avoid that, ensure the topic is unique enough using a long, randomly generated ID, like in the following examples.
health/notifications/opsgenie/README.md
+2
-3
@@ -7,11 +7,10 @@ Learn how to send notifications to Opsgenie using Netdata's Agent alert notifica
7
> This file assumes you have read the [Introduction to Agent alert notifications](https://github.com/netdata/netdata/blob/master/health/notifications/README.md), detailing how the Netdata Agent's alert notification method works.
8
9
[Opsgenie](https://www.atlassian.com/software/opsgenie) is an alerting and incident response tool.
10
-It is designed to group and filter alarms, build custom routing rules for on-call teams, and correlate deployments and commits to incidents.
10
+It is designed to group and filter alerts, build custom routing rules for on-call teams, and correlate deployments and commits to incidents.
11
12
This is what you will get:
13
-
13
+
14
15
## Prerequisites
16
health/notifications/rocketchat/README.md
+2
-2
@@ -34,7 +34,7 @@ Edit `health_alarm_notify.conf`, changes to this file do not require restarting
34
2. Set `ROCKETCHAT_WEBHOOK_URL` to your webhook URL.
35
3. Set `DEFAULT_RECIPIENT_ROCKETCHAT` to the channel you want the alert notifications to be sent to.
36
You can define multiple channels like this: `alerts systems`.
37
- All roles will default to this variable if left unconfigured.
37
+ All roles will default to this variable if it is not configured.
38
39
You can then have different channels per **role**, by editing `DEFAULT_RECIPIENT_ROCKETCHAT` with the channel you want, in the following entries at the bottom of the same file:
40
@@ -57,7 +57,7 @@ An example of a working configuration would be:
57
58
SEND_ROCKETCHAT="YES"
59
ROCKETCHAT_WEBHOOK_URL="<your_incoming_webhook_url>"
60
-DEFAULT_RECIPIENT_ROCKETCHAT="monitoring_alarms"
60
+DEFAULT_RECIPIENT_ROCKETCHAT="monitoring_alerts"
61
```
62
63
## Test the notification method
health/notifications/slack/README.md
+2
-2
@@ -36,7 +36,7 @@ Edit `health_alarm_notify.conf`, changes to this file do not require restarting
36
2. Set `SLACK_WEBHOOK_URL` to your Slack app's webhook URL.
37
3. Set `DEFAULT_RECIPIENT_SLACK` to the Slack channel your Slack app is set to send messages to.
38
The syntax for channels is `#channel` or `channel`.
39
- All roles will default to this variable if left unconfigured.
39
+ All roles will default to this variable if it is not configured.
40
41
An example of a working configuration would be:
42
@@ -46,7 +46,7 @@ An example of a working configuration would be:
46
47
SEND_SLACK="YES"
48
SLACK_WEBHOOK_URL="https://hooks.slack.com/services/XXXXXXXX/XXXXXXXX/XXXXXXXXXXXXXXXXXXXXXXXXXXXXXXX"
49
-DEFAULT_RECIPIENT_SLACK="#alarms"
49
+DEFAULT_RECIPIENT_SLACK="#alerts"
50
```
51
52
## Test the notification method
health/notifications/stackpulse/README.md
+17
-17
@@ -15,7 +15,7 @@ learn_autogeneration_metadata: "{'part_of_cloud': False, 'part_of_agent': True}"
15
It helps SREs, DevOps Engineers and Software Developers reduce toil and alert fatigue while improving reliability of
16
software services by managing, analyzing and automating incident response activities.
17
18
-Sending Netdata alarm notifications to StackPulse allows you to create smart automated response workflows
18
+Sending Netdata alert notifications to StackPulse allows you to create smart automated response workflows
19
(StackPulse playbooks) that will help you drive down your MTTD and MTTR by performing any of the following:
20
21
- Enriching the incident with data from multiple sources
@@ -44,41 +44,41 @@ STACKPULSE_WEBHOOK="https://hooks.stackpulse.io/v1/webhooks/YOUR_UNIQUE_ID"
44
```
45
46
4. Now restart Netdata using `sudo systemctl restart netdata`, or the [appropriate
47
- method](https://github.com/netdata/netdata/blob/master/docs/configure/start-stop-restart.md) for your system. When your node creates an alarm, you can see the
47
+ method](https://github.com/netdata/netdata/blob/master/docs/configure/start-stop-restart.md) for your system. When your node creates an alert, you can see the
48
associated notification on your StackPulse Administration Portal
49
50
-## React to alarms with playbooks
50
+## React to alerts with playbooks
51
52
StackPulse allow users to create `Playbooks` giving additional information about events that happen in specific
53
-scenarios. For example, you could create a Playbook that responds to a "low disk space" alarm by compressing and
53
+scenarios. For example, you could create a Playbook that responds to a "low disk space" alert by compressing and
54
cleaning up storage partitions with dynamic data.
55
56

57
58
-
60
-### Create Playbooks for Netdata alarms
58
+
59
+
60
+### Create Playbooks for Netdata alerts
61
62
To create a Playbook, you need to access the StackPulse Administration Portal. After the initial setup, you need to
63
access the **TRIGGER** tab to define the scenarios used to trigger the event. The following variables are available:
64
65
- `Hostname`: The host that generated the event.
66
- `Chart`: The name of the chart.
67
-- `OldValue` : The previous value of the alarm.
68
-- `Value`: The current value of the alarm.
67
+- `OldValue` : The previous value of the alert.
68
+- `Value`: The current value of the alert.
69
- `Units` : The units of the value.
70
- `OldStatus` : The previous status: REMOVED, UNINITIALIZED, UNDEFINED, CLEAR, WARNING, CRITICAL.
71
-- `State`: The current alarm status, the acceptable values are the same of `OldStatus`.
72
-- `Alarm` : The name of the alarm, as given in Netdata's health.d entries.
71
+- `State`: The current alert status, the acceptable values are the same of `OldStatus`.
72
+- `Alarm` : The name of the alert, as given in Netdata's health.d entries.
73
- `Date` : The timestamp this event occurred.
74
-- `Duration` : The duration in seconds of the previous alarm state.
74
+- `Duration` : The duration in seconds of the previous alert state.
75
- `NonClearDuration` : The total duration in seconds this is/was non-clear.
76
-- `Description` : A short description of the alarm copied from the alarm definition.
77
-- `CalcExpression` : The expression that was evaluated to trigger the alarm.
76
+- `Description` : A short description of the alert copied from the alert definition.
77
+- `CalcExpression` : The expression that was evaluated to trigger the alert.
78
- `CalcParamValues` : The values of the parameters in the expression, at the time of the evaluation.
79
-- `TotalWarnings` : Total number of alarms in WARNING state.
80
-- `TotalCritical` : Total number of alarms in CRITICAL state.
81
-- `ID` : The unique id of the alarm that generated this event.
79
+- `TotalWarnings` : Total number of alerts in WARNING state.
80
+- `TotalCritical` : Total number of alerts in CRITICAL state.
81
+- `ID` : The unique id of the alert that generated this event.
82
83
For more details how to create a scenario, take a look at the [StackPulse documentation](https://docs.stackpulse.io).
84
ml/README.md
+1
-1
@@ -267,7 +267,7 @@ The anomaly rate across all dimensions of a node.
267
268
- We would love to hear any feedback relating to this functionality, please email us at analytics-ml-team@netdata.cloud or come join us in the [🤖-ml-powered-monitoring](https://discord.gg/4eRSEUpJnc) channel of the Netdata discord.
269
- We are working on additional UI/UX based features that build on these core components to make them as useful as possible out of the box.
270
-- Although not yet a core focus of this work, users could leverage the `anomaly_detection` chart dimensions and/or `anomaly-bit` options in defining alarms based on ML driven anomaly detection models.
270
+- Although not yet a core focus of this work, users could leverage the `anomaly_detection` chart dimensions and/or `anomaly-bit` options in defining alerts based on ML driven anomaly detection models.
271
- [This presentation](https://docs.google.com/presentation/d/18zkCvU3nKP-Bw_nQZuXTEa4PIVM6wppH3VUnAauq-RU/edit?usp=sharing) walks through some of the main concepts covered above in a more informal way.
272
- After restart Netdata will wait until `minimum num samples to train` observations of data are available before starting training and prediction.
273
- Netdata uses [dlib](https://github.com/davisking/dlib) under the hood for its core ML features.
packaging/installer/README.md
+3
-3
@@ -51,10 +51,10 @@ learn more about [how data collectors work](https://github.com/netdata/netdata/b
51
collector](https://github.com/netdata/netdata/blob/master/collectors/COLLECTORS.md) for metrics you need, [configure the collector](https://github.com/netdata/netdata/blob/master/collectors/REFERENCE.md)
52
or read about its requirements to configure your endpoint to publish metrics in the correct format and endpoint.
53
54
-#### Alarms & notifications
54
+#### Alerts & notifications
55
56
-Netdata comes with hundreds of preconfigured alarms, designed by our monitoring gurus in parallel with our open-source
57
-community, but you may want to [edit alarms](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md) or
56
+Netdata comes with hundreds of preconfigured alerts, designed by our monitoring gurus in parallel with our open-source
57
+community, but you may want to [edit alerts](https://github.com/netdata/netdata/blob/master/health/REFERENCE.md) or
58
[enable notifications](https://github.com/netdata/netdata/blob/master/docs/monitor/enable-notifications.md) to customize your Netdata experience.
59
60
#### Make your deployment production ready
packaging/installer/methods/kubernetes.md
+1
-1
@@ -5,7 +5,7 @@ import TabItem from '@theme/TabItem';
5
6
This document details how to install Netdata on an existing Kubernetes (k8s) cluster, and connect it to Netdata Cloud. Read our [Kubernetes visualizations](https://github.com/netdata/netdata/blob/master/docs/cloud/visualize/kubernetes.md) documentation, to see what you will get.
7
8
-The [Netdata Helm chart](https://github.com/netdata/helmchart/blob/master/charts/netdata/README.md) installs one `parent` pod for storing metrics and managing alarm notifications, plus an additional
8
+The [Netdata Helm chart](https://github.com/netdata/helmchart/blob/master/charts/netdata/README.md) installs one `parent` pod for storing metrics and managing alert notifications, plus an additional
9
`child` pod for every node in the cluster, responsible for collecting metrics from the node, Kubernetes control planes,
10
pods/containers, and [supported application-specific
11
metrics](https://github.com/netdata/helmchart#service-discovery-and-supported-services).
packaging/installer/methods/manual.md
+2
-2
@@ -94,8 +94,8 @@ Netdata plugins and various aspects of Netdata can be enabled or benefit when th
94
95
| package |description|
96
|:-----:|-----------|
97
-| `bash`|for shell plugins and **alarm notifications**|
98
-| `curl`|for shell plugins and **alarm notifications**|
97
+| `bash`|for shell plugins and **alert notifications**|
98
+| `curl`|for shell plugins and **alert notifications**|
99
| `iproute` or `iproute2`|for monitoring **Linux traffic QoS**<br/>use `iproute2` if `iproute` reports as not available or obsolete|
100
| `python`|for most of the external plugins|
101
| `python-yaml`|used for monitoring **beanstalkd**|
streaming/README.md
+50
-50
@@ -30,36 +30,36 @@ node**. This file is automatically generated by Netdata the first time it is sta
30
31
#### `[stream]` section
32
33
-| Setting | Default | Description |
34
-| :---------------------------------------------- | :------------------------ | :-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
35
-| `enabled` | `no` | Whether this node streams metrics to any parent. Change to `yes` to enable streaming. |
36
-| [`destination`](#destination) | ` ` | A space-separated list of parent nodes to attempt to stream to, with the first available parent receiving metrics, using the following format: `[PROTOCOL:]HOST[%INTERFACE][:PORT][:SSL]`. [Read more →](#destination) |
37
-| `ssl skip certificate verification` | `yes` | If you want to accept self-signed or expired certificates, set to `yes` and uncomment. |
38
-| `CApath` | `/etc/ssl/certs/` | The directory where known certificates are found. Defaults to OpenSSL's default path. |
39
-| `CAfile` | `/etc/ssl/certs/cert.pem` | Add a parent node certificate to the list of known certificates in `CAPath`. |
40
-| `api key` | ` ` | The `API_KEY` to use as the child node. |
41
-| `timeout seconds` | `60` | The timeout to connect and send metrics to a parent. |
42
-| `default port` | `19999` | The port to use if `destination` does not specify one. |
43
-| [`send charts matching`](#send-charts-matching) | `*` | A space-separated list of [Netdata simple patterns](https://github.com/netdata/netdata/blob/master/libnetdata/simple_pattern/README.md) to filter which charts are streamed. [Read more →](#send-charts-matching) |
44
-| `buffer size bytes` | `10485760` | The size of the buffer to use when sending metrics. The default `10485760` equals a buffer of 10MB, which is good for 60 seconds of data. Increase this if you expect latencies higher than that. The buffer is flushed on reconnect. |
45
-| `reconnect delay seconds` | `5` | How long to wait until retrying to connect to the parent node. |
46
-| `initial clock resync iterations` | `60` | Sync the clock of charts for how many seconds when starting. |
33
+| Setting | Default | Description |
34
+|-------------------------------------------------|---------------------------|---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
35
+| `enabled` | `no` | Whether this node streams metrics to any parent. Change to `yes` to enable streaming. |
36
+| [`destination`](#destination) | | A space-separated list of parent nodes to attempt to stream to, with the first available parent receiving metrics, using the following format: `[PROTOCOL:]HOST[%INTERFACE][:PORT][:SSL]`. [Read more →](#destination) |
37
+| `ssl skip certificate verification` | `yes` | If you want to accept self-signed or expired certificates, set to `yes` and uncomment. |
38
+| `CApath` | `/etc/ssl/certs/` | The directory where known certificates are found. Defaults to OpenSSL's default path. |
39
+| `CAfile` | `/etc/ssl/certs/cert.pem` | Add a parent node certificate to the list of known certificates in `CAPath`. |
40
+| `api key` | | The `API_KEY` to use as the child node. |
41
+| `timeout seconds` | `60` | The timeout to connect and send metrics to a parent. |
42
+| `default port` | `19999` | The port to use if `destination` does not specify one. |
43
+| [`send charts matching`](#send-charts-matching) | `*` | A space-separated list of [Netdata simple patterns](https://github.com/netdata/netdata/blob/master/libnetdata/simple_pattern/README.md) to filter which charts are streamed. [Read more →](#send-charts-matching) |
44
+| `buffer size bytes` | `10485760` | The size of the buffer to use when sending metrics. The default `10485760` equals a buffer of 10MB, which is good for 60 seconds of data. Increase this if you expect latencies higher than that. The buffer is flushed on reconnect. |
45
+| `reconnect delay seconds` | `5` | How long to wait until retrying to connect to the parent node. |
46
+| `initial clock resync iterations` | `60` | Sync the clock of charts for how many seconds when starting. |
47
48
### `[API_KEY]` and `[MACHINE_GUID]` sections
49
50
-| Setting | Default | Description |
51
-| :---------------------------------------------- | :------------------------ | :-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
52
-| `enabled` | `no` | Whether this API KEY enabled or disabled. |
53
-| [`allow from`](#allow-from) | `*` | A space-separated list of [Netdata simple patterns](https://github.com/netdata/netdata/blob/master/libnetdata/simple_pattern/README.md) matching the IPs of nodes that will stream metrics using this API key. [Read more →](#allow-from) |
54
-| `default history` | `3600` | The default amount of child metrics history to retain when using the `save`, `map`, or `ram` memory modes. |
55
-| [`default memory mode`](#default-memory-mode) | `ram` | The [database](https://github.com/netdata/netdata/blob/master/database/README.md) to use for all nodes using this `API_KEY`. Valid settings are `dbengine`, `map`, `save`, `ram`, or `none`. [Read more →](#default-memory-mode) |
56
-| `health enabled by default` | `auto` | Whether alarms and notifications should be enabled for nodes using this `API_KEY`. `auto` enables alarms when the child is connected. `yes` enables alarms always, and `no` disables alarms. |
57
-| `default postpone alarms on connect seconds` | `60` | Postpone alarms and notifications for a period of time after the child connects. |
58
-| `default health log history` | `432000` | History of health log events (in seconds) kept in the database. |
59
-| `default proxy enabled` | ` ` | Route metrics through a proxy. |
60
-| `default proxy destination` | ` ` | Space-separated list of `IP:PORT` for proxies. |
61
-| `default proxy api key` | ` ` | The `API_KEY` of the proxy. |
62
-| `default send charts matching` | `*` | See [`send charts matching`](#send-charts-matching). |
50
+| Setting | Default | Description |
51
+|-----------------------------------------------|----------|------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
52
+| `enabled` | `no` | Whether this API KEY enabled or disabled. |
53
+| [`allow from`](#allow-from) | `*` | A space-separated list of [Netdata simple patterns](https://github.com/netdata/netdata/blob/master/libnetdata/simple_pattern/README.md) matching the IPs of nodes that will stream metrics using this API key. [Read more →](#allow-from) |
54
+| `default history` | `3600` | The default amount of child metrics history to retain when using the `save`, `map`, or `ram` memory modes. |
55
+| [`default memory mode`](#default-memory-mode) | `ram` | The [database](https://github.com/netdata/netdata/blob/master/database/README.md) to use for all nodes using this `API_KEY`. Valid settings are `dbengine`, `map`, `save`, `ram`, or `none`. [Read more →](#default-memory-mode) |
56
+| `health enabled by default` | `auto` | Whether alerts and notifications should be enabled for nodes using this `API_KEY`. `auto` enables alerts when the child is connected. `yes` enables alerts always, and `no` disables alerts. |
57
+| `default postpone alarms on connect seconds` | `60` | Postpone alerts and notifications for a period of time after the child connects. |
58
+| `default health log history` | `432000` | History of health log events (in seconds) kept in the database. |
59
+| `default proxy enabled` | | Route metrics through a proxy. |
60
+| `default proxy destination` | | Space-separated list of `IP:PORT` for proxies. |
61
+| `default proxy api key` | | The `API_KEY` of the proxy. |
62
+| `default send charts matching` | `*` | See [`send charts matching`](#send-charts-matching). |
63
64
#### `destination`
65
@@ -145,24 +145,24 @@ cache size` and `dbengine multihost disk space` settings in the `[global]` secti
145
146
### `netdata.conf`
147
148
-| Setting | Default | Description |
149
-| :----------------------------------------- | :---------------- | :--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
150
-| **`[global]` section** | | |
151
-| `memory mode` | `dbengine` | Determines the [database type](https://github.com/netdata/netdata/blob/master/database/README.md) to be used on that node. Other options settings include `none`, `ram`, `save`, and `map`. `none` disables the database at this host. This also disables alarms and notifications, as those can't run without a database. |
152
-| **`[web]` section** | | |
148
+| Setting | Default | Description |
149
+|--------------------------------------------|-------------------|----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
150
+| `[global]` section | | |
151
+| `memory mode` | `dbengine` | Determines the [database type](https://github.com/netdata/netdata/blob/master/database/README.md) to be used on that node. Other options settings include `none`, `ram`, `save`, and `map`. `none` disables the database at this host. This also disables alerts and notifications, as those can't run without a database. |
152
+| `[web]` section | | |
153
| `mode` | `static-threaded` | Determines the [web server](https://github.com/netdata/netdata/blob/master/web/server/README.md) type. The other option is `none`, which disables the dashboard, API, and registry. |
154
-| `accept a streaming request every seconds` | `0` | Set a limit on how often a parent node accepts streaming requests from child nodes. `0` equals no limit. If this is set, you may see `... too busy to accept new streaming request. Will be allowed in X secs` in Netdata's `error.log`. |
154
+| `accept a streaming request every seconds` | `0` | Set a limit on how often a parent node accepts streaming requests from child nodes. `0` equals no limit. If this is set, you may see `... too busy to accept new streaming request. Will be allowed in X secs` in Netdata's `error.log`. |
155
156
### Basic use cases
157
158
This is an overview of how the main options can be combined:
159
160
-| target|memory<br/>mode|web<br/>mode|stream<br/>enabled|exporting|alarms|dashboard|
161
-|------|:-------------:|:----------:|:----------------:|:-----:|:----:|:-------:|
162
-| headless collector|`none`|`none`|`yes`|only for `data source = as collected`|not possible|no|
163
-| headless proxy|`none`|not `none`|`yes`|only for `data source = as collected`|not possible|no|
164
-| proxy with db|not `none`|not `none`|`yes`|possible|possible|yes|
165
-| central netdata|not `none`|not `none`|`no`|possible|possible|yes|
160
+| target | memory<br/>mode | web<br/>mode | stream<br/>enabled | exporting | alerts | dashboard |
161
+|--------------------|:---------------:|:------------:|:------------------:|:-------------------------------------:|:------------:|:---------:|
162
+| headless collector | `none` | `none` | `yes` | only for `data source = as collected` | not possible | no |
163
+| headless proxy | `none` | not `none` | `yes` | only for `data source = as collected` | not possible | no |
164
+| proxy with db | not `none` | not `none` | `yes` | possible | possible | yes |
165
+| central netdata | not `none` | not `none` | `no` | possible | possible | yes |
166
167
### Per-child settings
168
@@ -170,7 +170,7 @@ While the `[API_KEY]` section applies settings for any child node using that key
170
with the `[MACHINE_GUID]` section.
171
172
For example, the metrics streamed from only the child node with `MACHINE_GUID` are saved in memory, not using the
173
-default `dbengine` as specified by the `API_KEY`, and alarms are disabled.
173
+default `dbengine` as specified by the `API_KEY`, and alerts are disabled.
174
175
```conf
176
[API_KEY]
@@ -261,12 +261,12 @@ To enable stream compression:
261
```
262
263
264
-| Parent | Stream compression | Child |
265
-|----------------------|--------------------|----------------------|
266
-| Supported & Enabled | compressed | Supported & Enabled |
267
-| (Supported & Disabled)/Not supported | uncompressed | Supported & Enabled |
268
-| Supported & Enabled | uncompressed | (Supported & Disabled)/Not supported |
269
-| (Supported & Disabled)/Not supported | uncompressed | (Supported & Disabled)/Not supported |
264
+| Parent | Stream compression | Child |
265
+|--------------------------------------|--------------------|--------------------------------------|
266
+| Supported & Enabled | compressed | Supported & Enabled |
267
+| (Supported & Disabled)/Not supported | uncompressed | Supported & Enabled |
268
+| Supported & Enabled | uncompressed | (Supported & Disabled)/Not supported |
269
+| (Supported & Disabled)/Not supported | uncompressed | (Supported & Disabled)/Not supported |
270
271
In case of parents with multiple children you can select which streams will be compressed by using the same configuration under the `[API_KEY]`, `[MACHINE_GUID]` section.
272
@@ -383,7 +383,7 @@ following configurations:
383
parameter (default is no).
384
385
| Parent TLS enabled | Parent port SSL | Child TLS | Child SSL Ver. | Behavior |
386
-| :----------------- | :--------------- | :-------- | :------------- | :--------------------------------------------------------------------------------------------------------------------------------------- |
386
+|:-------------------|:-----------------|:----------|:---------------|:-----------------------------------------------------------------------------------------------------------------------------------------|
387
| No | - | No | no | Legacy behavior. The parent-child stream is unencrypted. |
388
| Yes | force | No | no | The parent rejects the child connection. |
389
| Yes | -/optional | No | no | The parent-child stream is unencrypted (expected situation for legacy child nodes and newer parent nodes) |
@@ -396,7 +396,7 @@ A proxy is a node that receives metrics from a child, then streams them onward t
396
configure it as a receiving and a sending Netdata at the same time.
397
398
Netdata proxies may or may not maintain a database for the metrics passing through them. When they maintain a database,
399
-they can also run health checks (alarms and notifications) for the remote host that is streaming the metrics.
399
+they can also run health checks (alerts and notifications) for the remote host that is streaming the metrics.
400
401
In the following example, the proxy receives metrics from a child node using the `API_KEY` of
402
`66666666-7777-8888-9999-000000000000`, then stores metrics using `dbengine`. It then uses the `API_KEY` of
@@ -431,7 +431,7 @@ On the parent, set the following in `stream.conf`:
431
# do not save child metrics on disk
432
default memory = ram
433
434
- # alarms checks, only while the child is connected
434
+ # alerts checks, only while the child is connected
435
health enabled by default = auto
436
```
437
@@ -449,7 +449,7 @@ On the child nodes, set the following in `stream.conf`:
449
api key = 11111111-2222-3333-4444-555555555555
450
```
451
452
-In addition, edit `netdata.conf` on each child node to disable the database and alarms.
452
+In addition, edit `netdata.conf` on each child node to disable the database and alerts.
453
454
```bash
455
[global]
web/api/badges/README.md
+3
-3
@@ -77,11 +77,11 @@ Here is what you can put for `options` (these are standard Netdata API options):
77
78
- `alarm=NAME`
79
80
- Render the current value and status of an alarm linked to the chart. This option can be ignored if the badge to be generated is not related to an alarm.
80
+ Render the current value and status of an alert linked to the chart. This option can be ignored if the badge to be generated is not related to an alert.
81
82
- The current value of the alarm will be rendered. The color of the badge will indicate the status of the alarm.
82
+ The current value of the alert will be rendered. The color of the badge will indicate the status of the alert.
83
84
- For alarm badges, **both `chart` and `alarm` parameters are required**.
84
+ For alert badges, **both `chart` and `alarm` parameters are required**.
85
86
- `dimensions=DIMENSION1|DIMENSION2|...`
87
web/api/exporters/shell/README.md
+2
-2
@@ -40,12 +40,12 @@ NETDATA_SYSTEM_CPU_VISIBLETOTAL=5
40
echo ${NETDATA_SYSTEM_CPU_VISIBLETOTAL}
41
5
42
43
-# what about alarms?
43
+# what about alerts?
44
set | grep "^NETDATA_ALARM_SYSTEM_SWAP_"
45
NETDATA_ALARM_SYSTEM_SWAP_USED_SWAP_STATUS=CLEAR
46
NETDATA_ALARM_SYSTEM_SWAP_USED_SWAP_VALUE=51
47
48
-# let's get the current status of the alarm 'used swap'
48
+# let's get the current status of the alert 'used swap'
49
echo ${NETDATA_ALARM_SYSTEM_SWAP_USED_SWAP_STATUS}
50
CLEAR
51
web/api/health/README.md
+33
-33
@@ -12,23 +12,23 @@ learn_rel_path: "Developers/Web/Api"
12
13
## Health Read API
14
15
-### Enabled Alarms
15
+### Enabled Alerts
16
17
-Netdata enables alarms on demand, i.e. when the chart they should be linked to starts collecting data. So, although many
18
-more alarms are configured, only the useful ones are enabled.
17
+Netdata enables alerts on demand, i.e. when the chart they should be linked to starts collecting data. So, although many
18
+more alerts are configured, only the useful ones are enabled.
19
20
-To get the list of all enabled alarms, open your browser and navigate to `http://NODE:19999/api/v1/alarms?all`,
20
+To get the list of all enabled alerts, open your browser and navigate to `http://NODE:19999/api/v1/alarms?all`,
21
replacing `NODE` with the IP address or hostname for your Agent dashboard.
22
23
-### Raised Alarms
23
+### Raised Alerts
24
25
-This API call will return the alarms currently in WARNING or CRITICAL state.
25
+This API call will return the alerts currently in WARNING or CRITICAL state.
26
27
`http://NODE:19999/api/v1/alarms`
28
29
### Event Log
30
31
-The size of the alarm log is configured in `netdata.conf`. There are 2 settings: the event history kept in the DB (in seconds), and the in memory size of the alarm log.
31
+The size of the alert log is configured in `netdata.conf`. There are 2 settings: the event history kept in the DB (in seconds), and the in memory size of the alert log.
32
33
```
34
[health]
@@ -36,32 +36,32 @@ The size of the alarm log is configured in `netdata.conf`. There are 2 settings:
36
health log history = 432000
37
```
38
39
-The API call retrieves all entries of the alarm log:
39
+The API call retrieves all entries of the alert log:
40
41
`http://NODE:19999/api/v1/alarm_log`
42
43
-### Alarm Log Incremental Updates
43
+### Alert Log Incremental Updates
44
45
`http://NODE:19999/api/v1/alarm_log?after=UNIQUEID`
46
47
-The above returns all the events in the alarm log that occurred after UNIQUEID (you poll it once without `after=`, remember the last UNIQUEID of the returned set, which you give back to get incrementally the next events).
47
+The above returns all the events in the alert log that occurred after UNIQUEID (you poll it once without `after=`, remember the last UNIQUEID of the returned set, which you give back to get incrementally the next events).
48
49
-### Alarm badges
49
+### Alert badges
50
51
-The following will return an SVG badge of the alarm named `NAME`, attached to the chart named `CHART`.
51
+The following will return an SVG badge of the alert named `NAME`, attached to the chart named `CHART`.
52
53
`http://NODE:19999/api/v1/badge.svg?alarm=NAME&chart=CHART`
54
55
## Health Management API
56
57
-Netdata v1.12 and beyond provides a command API to control health checks and notifications at runtime. The feature is especially useful for maintenance periods, during which you receive meaningless alarms.
57
+Netdata v1.12 and beyond provides a command API to control health checks and notifications at runtime. The feature is especially useful for maintenance periods, during which you receive meaningless alerts.
58
From Netdata v1.16.0 and beyond, the configuration controlled via the API commands is [persisted across Netdata restarts](#persistence).
59
60
Specifically, the API allows you to:
61
62
-- Disable health checks completely. Alarm conditions will not be evaluated at all and no entries will be added to the alarm log.
63
-- Silence alarm notifications. Alarm conditions will be evaluated, the alarms will appear in the log and the Netdata UI will show the alarms as active, but no notifications will be sent.
64
-- Disable or Silence specific alarms that match selectors on alarm/template name, chart, context, host and family.
62
+- Disable health checks completely. Alert conditions will not be evaluated at all and no entries will be added to the alert log.
63
+- Silence alert notifications. Alert conditions will be evaluated, the alerts will appear in the log and the Netdata UI will show the alerts as active, but no notifications will be sent.
64
+- Disable or Silence specific alerts that match selectors on alert/template name, chart, context, host and family.
65
66
The API is available by default, but it is protected by an `api authorization token` that is stored in the file you will see in the following entry of `http://NODE:19999/netdata.conf`:
67
@@ -81,7 +81,7 @@ By default access to the health management API is only allowed from `localhost`.
81
The command `RESET` just returns Netdata to the default operation, with all health checks and notifications enabled.
82
If you've configured and entered your token correctly, you should see the plain text response `All health checks and notifications are enabled`.
83
84
-### Disable or silence all alarms
84
+### Disable or silence all alerts
85
86
If all you need is temporarily disable all health checks, then you issue the following before your maintenance period starts:
87
@@ -89,14 +89,14 @@ If all you need is temporarily disable all health checks, then you issue the fol
89
curl "http://NODE:19999/api/v1/manage/health?cmd=DISABLE ALL" -H "X-Auth-Token: Mytoken"
90
```
91
92
-The effect of disabling health checks is that the alarm criteria are not evaluated at all and nothing is written in the alarm log.
92
+The effect of disabling health checks is that the alert criteria are not evaluated at all and nothing is written in the alert log.
93
If you want the health checks to be running but to not receive any notifications during your maintenance period, you can instead use this:
94
95
```sh
96
curl "http://NODE:19999/api/v1/manage/health?cmd=SILENCE ALL" -H "X-Auth-Token: Mytoken"
97
```
98
99
-Alarms may then still be raised and logged in Netdata, so you'll be able to see them via the UI.
99
+Alerts may then still be raised and logged in Netdata, so you'll be able to see them via the UI.
100
101
Regardless of the option you choose, at the end of your maintenance period you revert to the normal state via the RESET command.
102
@@ -104,25 +104,25 @@ Regardless of the option you choose, at the end of your maintenance period you r
104
curl "http://NODE:19999/api/v1/manage/health?cmd=RESET" -H "X-Auth-Token: Mytoken"
105
```
106
107
-### Disable or silence specific alarms
107
+### Disable or silence specific alerts
108
109
-If you do not wish to disable/silence all alarms, then the `DISABLE ALL` and `SILENCE ALL` commands can't be used.
110
-Instead, the following commands expect that one or more alarm selectors will be added, so that only alarms that match the selectors are disabled or silenced.
109
+If you do not wish to disable/silence all alerts, then the `DISABLE ALL` and `SILENCE ALL` commands can't be used.
110
+Instead, the following commands expect that one or more alert selectors will be added, so that only alerts that match the selectors are disabled or silenced.
111
112
- `DISABLE` : Set the mode to disable health checks.
113
- `SILENCE` : Set the mode to silence notifications.
114
115
-You will normally put one of these commands in the same request with your first alarm selector, but it's possible to issue them separately as well.
115
+You will normally put one of these commands in the same request with your first alert selector, but it's possible to issue them separately as well.
116
You will get a warning in the response, if a selector was added without a SILENCE/DISABLE command, or vice versa.
117
118
-Each request can specify a single alarm `selector`, with one or more `selection criteria`.
119
-A single alarm will match a `selector` if all selection criteria match the alarm.
118
+Each request can specify a single alert `selector`, with one or more `selection criteria`.
119
+A single alert will match a `selector` if all selection criteria match the alert.
120
You can add as many selectors as you like.
121
-In essence, the rule is: IF (alarm matches all the criteria in selector1 OR all the criteria in selector2 OR ...) THEN apply the DISABLE or SILENCE command.
121
+In essence, the rule is: IF (alert matches all the criteria in selector1 OR all the criteria in selector2 OR ...) THEN apply the DISABLE or SILENCE command.
122
123
To clear all selectors and reset the mode to default, use the `RESET` command.
124
125
-The following example silences notifications for all the alarms with context=load:
125
+The following example silences notifications for all the alerts with context=load:
126
127
```
128
curl "http://NODE:19999/api/v1/manage/health?cmd=SILENCE&context=load" -H "X-Auth-Token: Mytoken"
@@ -138,9 +138,9 @@ The accepted keys for the `selection criteria` are the following:
138
- `chart` : Chart ids/names, as shown on the dashboard. These will match the `on` entry of a configured `alarm`.
139
- `context` : Chart context, as shown on the dashboard. These will match the `on` entry of a configured `template`.
140
- `hosts` : The hostnames that will need to match.
141
-- `families` : The alarm families.
141
+- `families` : The alert families.
142
143
-You can add any of the selection criteria you need on the request, to ensure that only the alarms you are interested in are matched and disabled/silenced. e.g. there is no reason to add `hosts: *`, if you want the criteria to be applied to alarms for all hosts.
143
+You can add any of the selection criteria you need on the request, to ensure that only the alerts you are interested in are matched and disabled/silenced. e.g. there is no reason to add `hosts: *`, if you want the criteria to be applied to alerts for all hosts.
144
145
Example 1: Disable all health checks for context = `random`
146
@@ -148,13 +148,13 @@ Example 1: Disable all health checks for context = `random`
148
http://NODE:19999/api/v1/manage/health?cmd=DISABLE&context=random
149
```
150
151
-Example 2: Silence all alarms and templates with name starting with `out_of` on host `myhost`
151
+Example 2: Silence all alerts and templates with name starting with `out_of` on host `myhost`
152
153
```
154
http://NODE:19999/api/v1/manage/health?cmd=SILENCE&alarm=out_of*&hosts=myhost
155
```
156
157
-Example 2.2: Add one more selector, to also silence alarms for cpu1 and cpu2
157
+Example 2.2: Add one more selector, to also silence alerts for cpu1 and cpu2
158
159
```
160
http://NODE:19999/api/v1/manage/health?families=cpu1 cpu2
@@ -168,7 +168,7 @@ The command `LIST` was added in Netdata v1.16.0 and returns a JSON with the curr
168
curl "http://NODE:19999/api/v1/manage/health?cmd=LIST" -H "X-Auth-Token: Mytoken"
169
```
170
171
-As an example, the following response shows that we have two silencers configured, one for an alarm called `samplealarm` and one for alarms with context `random` on host `myhost`
171
+As an example, the following response shows that we have two silencers configured, one for an alert called `samplealert` and one for alerts with context `random` on host `myhost`
172
173
```
174
json
@@ -177,7 +177,7 @@ json
177
"type": "SILENCE",
178
"silencers": [
179
{
180
- "alarm": "samplealarm"
180
+ "alarm": "samplealert"
181
},
182
{
183
"context": "random",
web/api/queries/average/README.md
+2
-2
@@ -21,10 +21,10 @@ average = sum(numbers) / count(numbers)
21
22
## how to use
23
24
-Use it in alarms like this:
24
+Use it in alerts like this:
25
26
```
27
- alarm: my_alarm
27
+ alarm: my_alert
28
on: my_chart
29
lookup: average -1m unaligned of my_dimension
30
warn: $this > 1000
web/api/queries/countif/README.md
+1
-1
@@ -31,7 +31,7 @@ The target number and the desired condition can be set using the `group_options`
31
32
## how to use
33
34
-This query cannot be used in alarms.
34
+This query cannot be used in alerts.
35
36
`countif` changes the units of charts. The result of the calculation is always from zero to 1, expressing the percentage of database points that matched the condition.
37
web/api/queries/des/README.md
+2
-2
@@ -46,10 +46,10 @@ You can change the fixed value `15` by setting in `netdata.conf`:
46
47
## how to use
48
49
-Use it in alarms like this:
49
+Use it in alerts like this:
50
51
```
52
- alarm: my_alarm
52
+ alarm: my_alert
53
on: my_chart
54
lookup: des -1m unaligned of my_dimension
55
warn: $this > 1000
web/api/queries/incremental_sum/README.md
+2
-2
@@ -15,10 +15,10 @@ The result may be positive (rising) or negative (falling) depending on the first
15
16
## how to use
17
18
-Use it in alarms like this:
18
+Use it in alerts like this:
19
20
```
21
- alarm: my_alarm
21
+ alarm: my_alert
22
on: my_chart
23
lookup: incremental_sum -1m unaligned of my_dimension
24
warn: $this > 1000
web/api/queries/max/README.md
+2
-2
@@ -13,10 +13,10 @@ This module finds the max value in the time-frame given.
13
14
## how to use
15
16
-Use it in alarms like this:
16
+Use it in alerts like this:
17
18
```
19
- alarm: my_alarm
19
+ alarm: my_alert
20
on: my_chart
21
lookup: max -1m unaligned of my_dimension
22
warn: $this > 1000
web/api/queries/median/README.md
+2
-2
@@ -33,10 +33,10 @@ The function `trimmed-median` is an alias for `trimmed-median5`.
33
34
## how to use
35
36
-Use it in alarms like this:
36
+Use it in alerts like this:
37
38
```
39
- alarm: my_alarm
39
+ alarm: my_alert
40
on: my_chart
41
lookup: median -1m unaligned of my_dimension
42
warn: $this > 1000
web/api/queries/min/README.md
+2
-2
@@ -13,10 +13,10 @@ This module finds the min value in the time-frame given.
13
14
## how to use
15
16
-Use it in alarms like this:
16
+Use it in alerts like this:
17
18
```
19
- alarm: my_alarm
19
+ alarm: my_alert
20
on: my_chart
21
lookup: min -1m unaligned of my_dimension
22
warn: $this > 1000
web/api/queries/percentile/README.md
+2
-2
@@ -33,10 +33,10 @@ Any percentile may be requested using the `group_options` query parameter.
33
34
## how to use
35
36
-Use it in alarms like this:
36
+Use it in alerts like this:
37
38
```
39
- alarm: my_alarm
39
+ alarm: my_alert
40
on: my_chart
41
lookup: percentile95 -1m unaligned of my_dimension
42
warn: $this > 1000
web/api/queries/ses/README.md
+2
-2
@@ -34,10 +34,10 @@ You can change the fixed value `15` by setting in `netdata.conf`:
34
35
## how to use
36
37
-Use it in alarms like this:
37
+Use it in alerts like this:
38
39
```
40
- alarm: my_alarm
40
+ alarm: my_alert
41
on: my_chart
42
lookup: ses -1m unaligned of my_dimension
43
warn: $this > 1000
web/api/queries/stddev/README.md
+6
-6
@@ -18,10 +18,10 @@ out over a wider range of values.
18
19
## how to use
20
21
-Use it in alarms like this:
21
+Use it in alerts like this:
22
23
```
24
- alarm: my_alarm
24
+ alarm: my_alert
25
on: my_chart
26
lookup: stddev -1m unaligned of my_dimension
27
warn: $this > 1000
@@ -61,16 +61,16 @@ and its standard deviation is 100 (meaning that it variates from 900 to 1100), t
61
62
This is an easy way to check the % variation, without using absolute values.
63
64
-For example, you may trigger an alarm if your web server requests/sec `cv` is above 20 (`%`)
64
+For example, you may trigger an alert if your web server requests/sec `cv` is above 20 (`%`)
65
over the last minute. So if your web server was serving 1000 reqs/sec over the last minute,
66
-it will trigger the alarm if had spikes below 800/sec or above 1200/sec.
66
+it will trigger the alert if had spikes below 800/sec or above 1200/sec.
67
68
## how to use
69
70
-Use it in alarms like this:
70
+Use it in alerts like this:
71
72
```
73
- alarm: my_alarm
73
+ alarm: my_alert
74
on: my_chart
75
lookup: cv -1m unaligned of my_dimension
76
units: %
web/api/queries/trimmed_mean/README.md
+2
-2
@@ -31,10 +31,10 @@ Any percentage may be requested using the `group_options` query parameter.
31
32
## how to use
33
34
-Use it in alarms like this:
34
+Use it in alerts like this:
35
36
```
37
- alarm: my_alarm
37
+ alarm: my_alert
38
on: my_chart
39
lookup: trimmed-mean5 -1m unaligned of my_dimension
40
warn: $this > 1000
web/gui/confluence/README.md
+3
-3
@@ -73,7 +73,7 @@ like this (type `{html` for the html box to appear - you need the confluence htm
73
74
### Add a few badges
75
76
-Then, go to your Netdata and copy an alarm badge (the `<embed>` version of it):
76
+Then, go to your Netdata and copy an alert badge (the `<embed>` version of it):
77
78
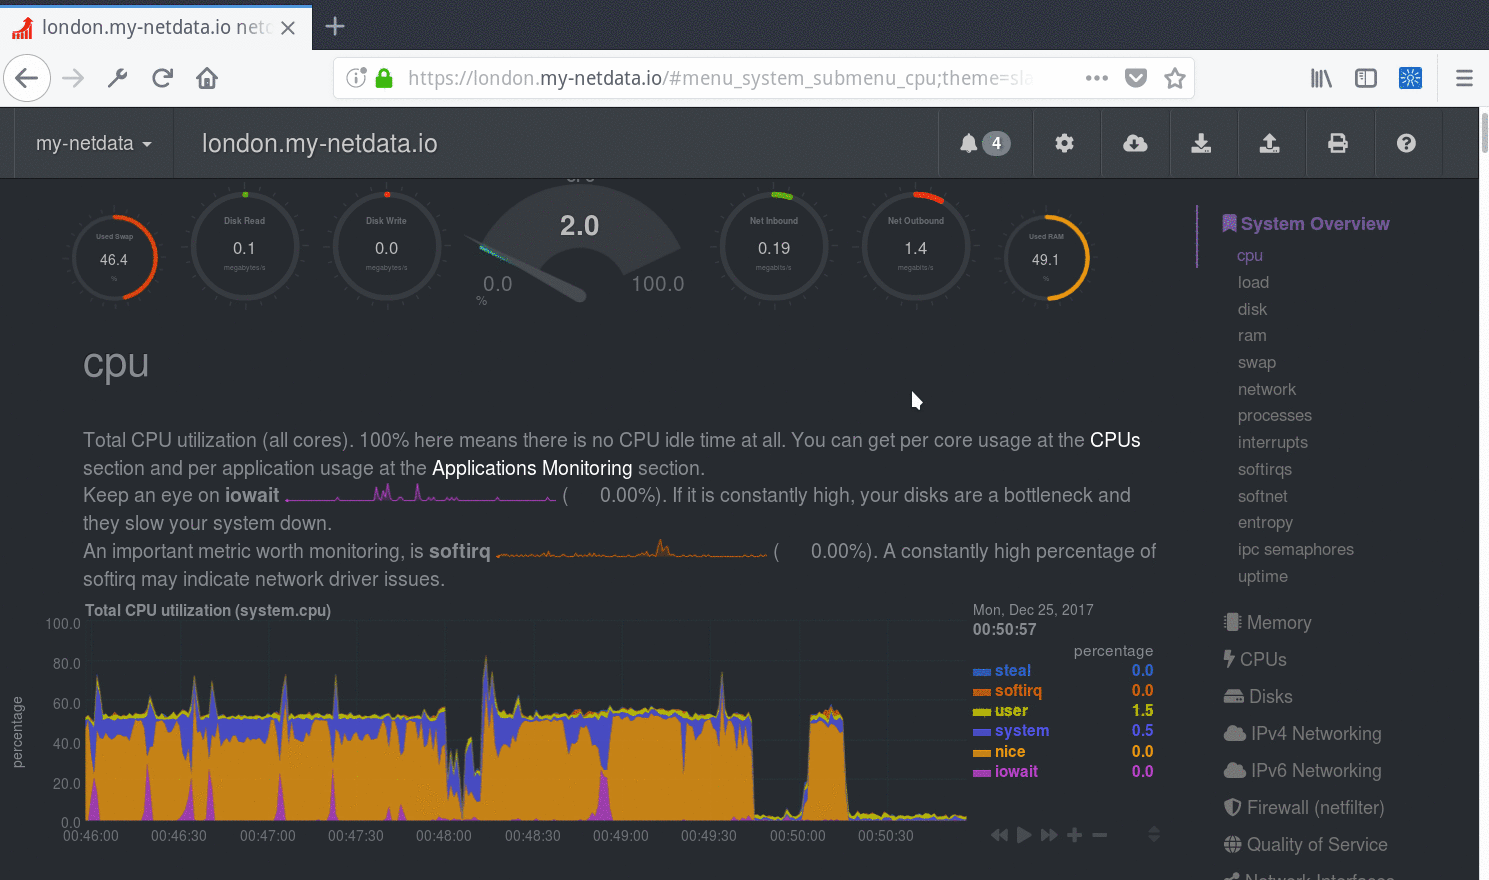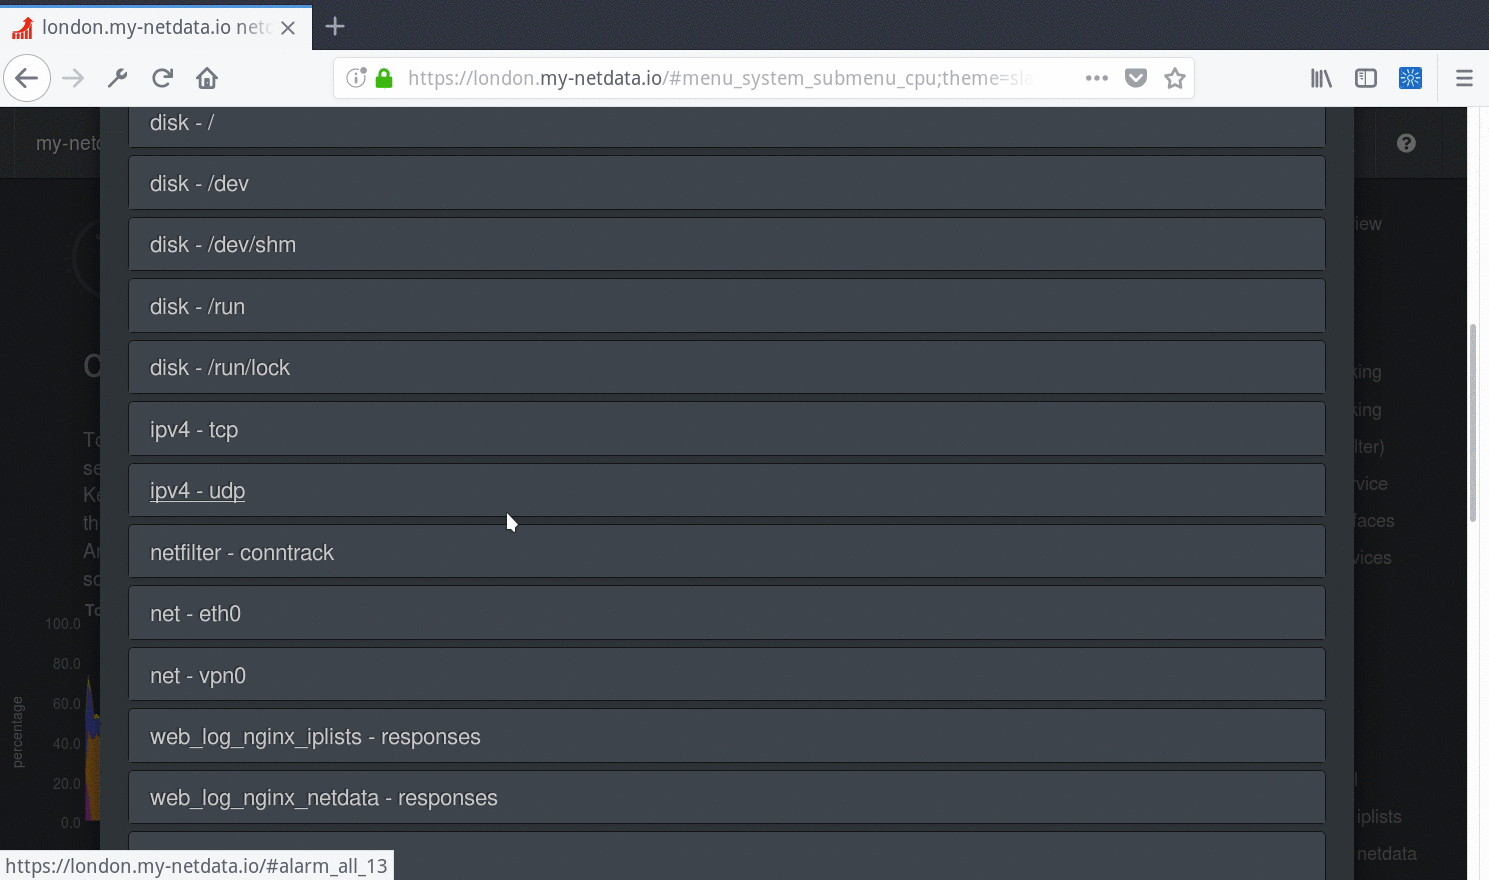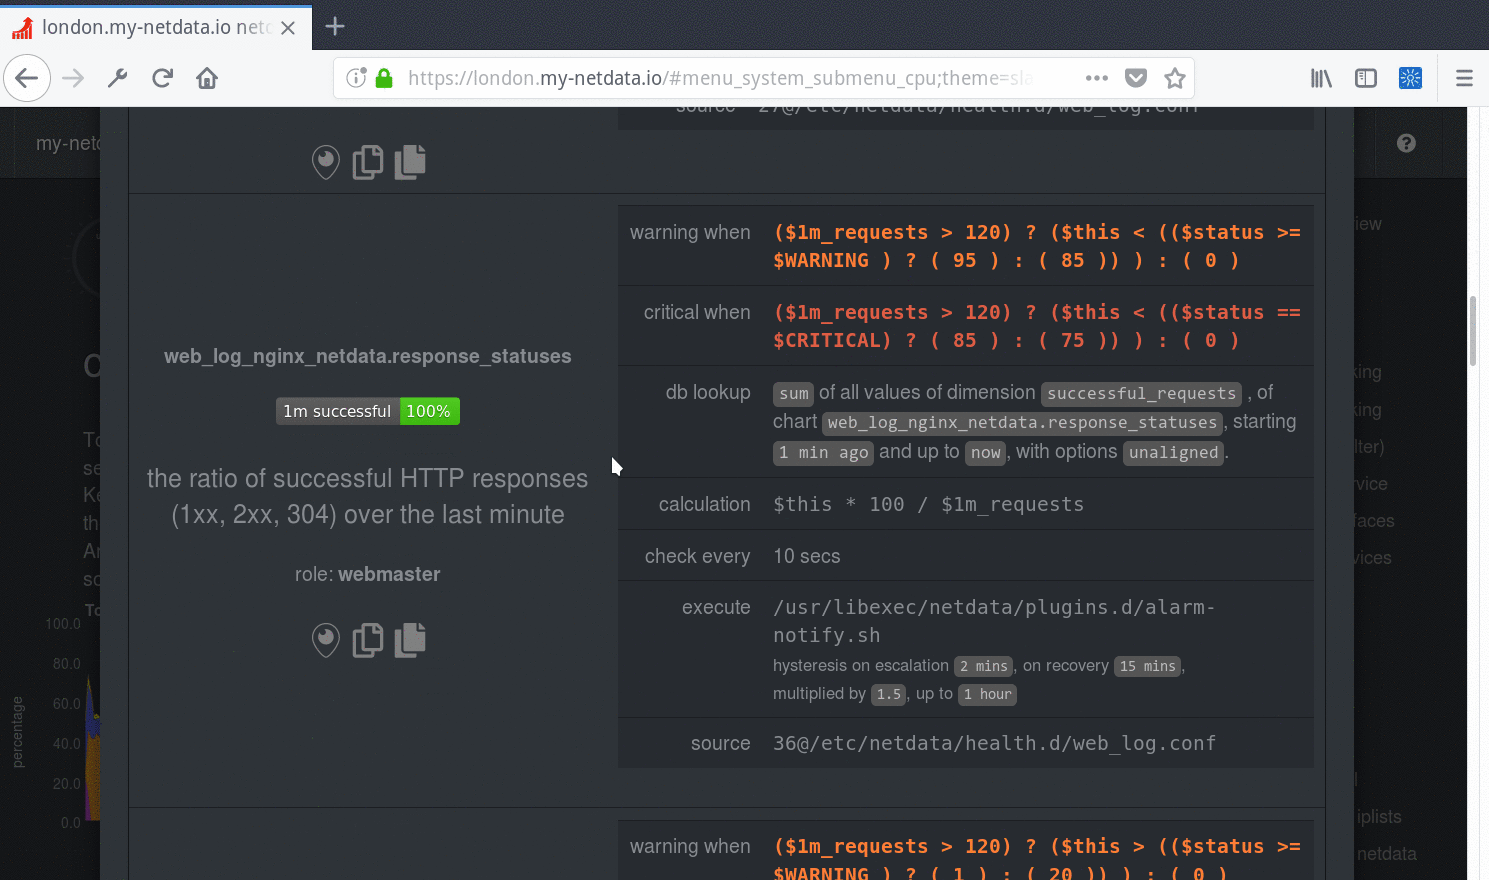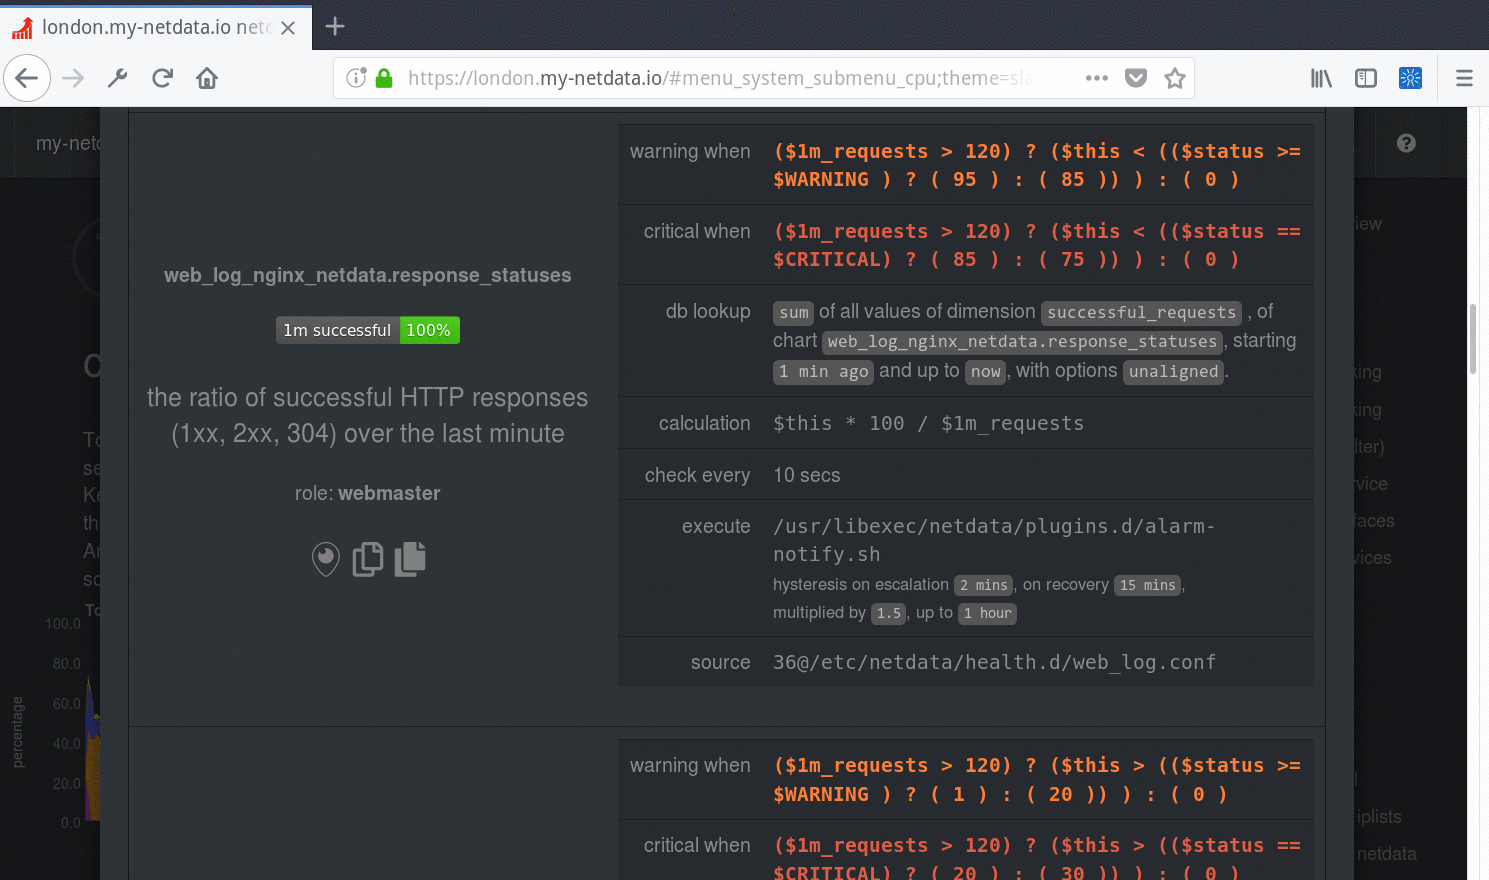
79
@@ -85,10 +85,10 @@ Hit **update** and you will get this:
85
86

87
88
-This badge is now auto-refreshing. It will update itself based on the update frequency of the alarm.
88
+This badge is now auto-refreshing. It will update itself based on the update frequency of the alert.
89
90
> Keep in mind you can add badges with custom Netdata queries too. Netdata automatically creates badges for all the
91
-> alarms, but every chart, every dimension on every chart, can be used for a badge. And Netdata badges are quite
91
+> alerts, but every chart, every dimension on every chart, can be used for a badge. And Netdata badges are quite
92
> powerful! Check [Creating Badges](https://github.com/netdata/netdata/blob/master/web/api/badges/README.md) for more information on badges.
93
94
So, let's create a table and add this badge for both our web servers: