Health: Proposed restructuring of health documentation (#7329)
* Squashed commits for PR * Addressing comments from Chris and Thiago * Changed sidebar title * Fixes for Vlad
Joel Hans committed
Dec 3, 2019 at 07:34 UTC
e5478fac6c84081686fcfae1d9766a964ea5068f
10 files changed
+984
-717
collectors/proc.plugin/README.md
+1
-1
@@ -300,7 +300,7 @@ By default Netdata will enable monitoring metrics only when they are not zero. I
300
301
There are several alarms defined in `health.d/net.conf`.
302
303
-The tricky ones are `inbound packets dropped` and `inbound packets dropped ratio`. They have quite a strict policy so that they warn users about possible issues. These alarms can be annoying for some network configurations. It is especially true for some bonding configurations if an interface is a slave or a bonding interface itself. If it is expected to have a certain number of drops on an interface for a certain network configuration, a separate alarm with different triggering thresholds can be created or the existing one can be disabled for this specific interface. It can be done with the help of the [families](../../health/#alarm-line-families) line in the alarm configuration. For example, if you want to disable the `inbound packets dropped` alarm for `eth0`, set `families: !eth0 *` in the alarm definition for `template: inbound_packets_dropped`.
303
+The tricky ones are `inbound packets dropped` and `inbound packets dropped ratio`. They have quite a strict policy so that they warn users about possible issues. These alarms can be annoying for some network configurations. It is especially true for some bonding configurations if an interface is a slave or a bonding interface itself. If it is expected to have a certain number of drops on an interface for a certain network configuration, a separate alarm with different triggering thresholds can be created or the existing one can be disabled for this specific interface. It can be done with the help of the [families](../../health/REFERENCE.md#alarm-line-families) line in the alarm configuration. For example, if you want to disable the `inbound packets dropped` alarm for `eth0`, set `families: !eth0 *` in the alarm definition for `template: inbound_packets_dropped`.
304
305
#### configuration
306
docs/generator/buildyaml.sh
+5
-1
@@ -256,7 +256,11 @@ navpart 3 collectors/slabinfo.plugin
256
echo -ne " - 'docs/Third-Party-Plugins.md'
257
"
258
259
-navpart 1 health README "Alarms and notifications"
259
+navpart 1 health README "Health monitoring and alerts"
260
+echo -ne " - 'health/QUICKSTART.md'
261
+ - 'health/REFERENCE.md'
262
+"
263
+navpart 2 health/tutorials "" "Tutorials" 2
264
navpart 2 health/notifications "" "" 1
265
navpart 2 health/notifications "" "Supported notifications" 2 excludefirstlevel
266
docs/getting-started.md
+3
-1
@@ -154,7 +154,9 @@ Find the `SEND_EMAIL="YES"` line and change it to `SEND_EMAIL="NO"`.
154
155
**What's next?**:
156
157
-- Write your own health alarm using the [examples](../health/README.md#examples).
157
+- Follow the [health quickstart](../health/QUICKSTART.md) to locate and edit existing health entities, and then create
158
+ your own.
159
+- See all the alarm options via the [health configuration reference](../health/REFERENCE.md).
160
- Add a new notification method, like [Slack](../health/notifications/slack/).
161
162
## Change how long Netdata stores metrics
health/QUICKSTART.md
new
+129
@@ -0,0 +1,129 @@
1
+# Health quickstart
2
+
3
+In this getting started guide, you'll learn the basics of editing health configuration files. With this knowledge, you
4
+will be able to customize how and when Netdata triggers alarms based on the health and performance of your system or
5
+infrastructure.
6
+
7
+To learn about more advanced health configurations, visit the [health reference guide](REFERENCE.md).
8
+
9
+## What's in this getting started guide
10
+
11
+- [Locate health configuration files](#locate-health-configuration-files)
12
+- [Edit existing health configuration files](#edit-existing-health-configuration-files)
13
+- [Write a new health entity](#write-a-new-health-entity)
14
+- [Reload health configuration](#reload-health-configuration)
15
+
16
+## Locate health configuration files
17
+
18
+By default, Netdata will put health configuration files in `/usr/lib/netdata/conf.d/health.d`.
19
+
20
+However, you can double-check the location of these files by navigating to `http://HOST:19999/netdata.conf` in your
21
+browser and looking for the `stock health configuration directory` option. The value here will show the correct path for
22
+your installation.
23
+
24
+```conf
25
+[health]
26
+ ...
27
+ # stock health configuration directory = /usr/lib/netdata/conf.d/health.d
28
+```
29
+
30
+Navigate to the health configuration directory to see all the available files.
31
+
32
+```bash
33
+cd /usr/lib/netdata/conf.d/health.d/
34
+ls
35
+adaptec_raid.conf entropy.conf memory.conf squid.conf
36
+am2320.conf fping.conf mongodb.conf stiebeleltron.conf
37
+apache.conf fronius.conf mysql.conf swap.conf
38
+...
39
+```
40
+
41
+## Edit existing health configuration files
42
+
43
+You should use `edit-config` to edit Netdata's health configuration files.
44
+
45
+For example, to edit the `cpu.conf` health configuration file, you would run:
46
+
47
+```bash
48
+cd /etc/netdata/ # Replace with your Netdata configuration directory, if not /etc/netdata/
49
+./edit-config health.d/cpu.conf
50
+```
51
+
52
+> You may need to use `sudo` or another method of elevating your privileges.
53
+
54
+`edit-config` will open a text editor for you to make your changes. Once you've saved and closed the editor,
55
+`edit-config` will copy your edited file into `/etc/netdata/health.d/`, and it will now override the default in
56
+`/usr/lib/netdata/conf.d/health.d/`.
57
+
58
+Each health configuration file contains one or more health entities, which always begin with an `alarm:` or `template:`
59
+line. You can edit these entities based on your needs. To make any changes live, be sure to [reload your health
60
+configuration](#reload-health-configuration).
61
+
62
+## Write a new health entity
63
+
64
+While tuning existing alarms may work in some cases, you may need to write entirely new health entities based on how
65
+your systems and applications work.
66
+
67
+To write a new health entity, let's create a new file inside of the `health.d/` directory. We'll name our file
68
+`example.conf` for now.
69
+
70
+```bash
71
+./edit-config health.d/example.conf
72
+```
73
+
74
+As an example, let's build a health entity that triggers an alarm your system's RAM usage goes above 80%. Copy and paste
75
+the following into the editor:
76
+
77
+```yaml
78
+ alarm: ram_usage
79
+ on: system.ram
80
+lookup: average -1m percentage of used
81
+ units: %
82
+ every: 1m
83
+ warn: $this > 80
84
+ crit: $this > 90
85
+ info: The percentage of RAM used by the system.
86
+```
87
+
88
+Let's look into each of the lines to see how they create a working health entity.
89
+
90
+- `alarm`: The name for your new entity. The name can be anything, but the only symbols allowed are `.` and `_`.
91
+- `on`: Which chart the entity listens to.
92
+- `lookup`: Which metrics the alarm monitors, the duration of time to monitor, and how to process the metrics into a
93
+ usable format.
94
+ - `average`: Calculate the average of all the metrics collected.
95
+ - `-1m`: Use metrics from 1 minute ago until now to calculate that average.
96
+ - `percentage`: Clarify that we're calculating a percentage of RAM usage.
97
+ - `of used`: Specify which dimension (`used`) on the `system.ram` chart you want to monitor with this entity.
98
+- `units`: Use percentages rather than absolute units.
99
+- `every`: How often to perform the `lookup` calculation to decide whether or not to trigger this alarm.
100
+- `warn`/`crit`: The value at which Netdata should trigger a warning or critical alarm.
101
+- `info`: A description of the alarm, which will appear in the dashboard and notifications.
102
+
103
+Let's put all these lines into a human-readable format.
104
+
105
+This health entity, named **ram_usage**, watches at the **system.ram** chart. It looks up the last **1 minute** of
106
+metrics from the **used** dimension and calculates the **average** of all those metrics in a **percentage** format,
107
+using a **% unit**. The entity performs this lookup **every minute**. If the average RAM usage percentage over the last
108
+1 minute is **more than 80%**, the entity triggers a warning alarm. If the usage is **more than 90%**, the entity
109
+triggers a critical alarm.
110
+
111
+Now that you've written a new health entity, you need to reload it to see it live on the dashboard.
112
+
113
+## Reload health configuration
114
+
115
+To make any changes to your health configuration live, you must reload Netdata's health monitoring system. To do that
116
+without restarting all of Netdata, run the following:
117
+
118
+```bash
119
+killall -USR2 netdata
120
+```
121
+
122
+## What's next?
123
+
124
+To learn about all of Netdata's health configuration options, view the [reference guide](REFERENCE.md).
125
+
126
+Or, get guided insights into specific health configurations with our [health tutorials](README.md#tutorials).
127
+
128
+Finally, move on to Netdata's [notification system](notifications/README.md) to learn more about how Netdata can let you
129
+know when the health of your systems or apps goes awry.
health/README.md
+26
-707
@@ -1,726 +1,45 @@
1
# Health monitoring
2
3
-Each Netdata node runs an independent thread evaluating health monitoring checks.
4
-This thread has lock free access to the database, so that it can operate as a watchdog.
3
+With Netdata, you can monitor the health and performance of your systems and applications. You start with hundreds of
4
+alarms that have been pre-configured by the Netdata community, but you can write new alarms, tune existing ones, or
5
+silence any that you're not interested in.
6
6
-Health checks (alarms) are attached to Netdata charts, allowing Netdata to automatically
7
-activate an alarm as soon as a chart is created. This is very important for
8
-netdata, since many charts are dynamically created during runtime (for example, the
9
-chart tracking network interface packet drops, is automatically created on the first
10
-packet dropped).
7
+Netdata creates charts dynamically, and runs an independent thread to constantly evaluate them, which means Netdata
8
+operates like a health watchdog for your services and applications.
9
12
-Netdata also supports alarm **templates**, so that an alarm can be attached to all the charts of the same context (i.e. all network interfaces, or all disks, or all mysql servers, etc.).
10
+You can even run statistical algorithms against the metrics you've collected to power complex lookups. Your imagination,
11
+and the needs of your infrastructure, are your only limits.
12
14
-Each alarm can execute a single query to the database using statistical algorithms against past data,
15
-but alarms can be combined. So, if you need 2 queries in the database, you can combine
16
-2 alarms together (both will run a query to the database, and the results can be combined).
13
+**Take the next steps with health monitoring:**
14
18
-Each alarm has unlimited access to all the metrics collected. So, a single alarm can
19
-use expressions combining the latest value of any number of metrics.
15
+<DocsSteps>
16
21
-## Health configuration reference
17
+[<FiPlay /> Quickstart](QUICKSTART.md)
18
23
-Stock Netdata health configuration is in `/usr/lib/netdata/conf.d/health.d`.
24
-These files can be overwritten by copying them and editing them in `/etc/netdata/health.d`
25
-(run `/etc/netdata/edit-config` to edit them).
19
+[<FiCode /> Configuration reference](REFERENCE.md)
20
27
-In `/etc/netdata/health.d` you can also put any number of files (in any number of sub-directories)
28
-with a suffix `.conf` to have them processed by Netdata.
21
+[<FiBook /> Tutorials](#tutorials)
22
30
-Health configuration can be reloaded at any time, without restarting Netdata.
31
-Just send Netdata the SIGUSR2 signal, like this:
23
+</DocsSteps>
24
33
-```sh
34
-killall -USR2 netdata
35
-```
25
+## Tutorials
26
37
-### Entities in the health files
27
+Every infrastructure is different, so we're not interested in mandating how you should configure Netdata's health
28
+monitoring features. Instead, these tutorials should give you the details you need to tweak alarms to your heart's
29
+content.
30
39
-There are 2 entities:
31
+<DocsTutorials>
32
+<div>
33
41
-1. **alarms**, which are attached to specific charts, and
34
+### Health entities
35
43
-2. **templates**, which define rules that should be applied to all charts having a
44
- specific `context`. You can use this feature to apply **alarms** to all disks,
45
- all network interfaces, all mysql databases, all nginx web servers, etc.
36
+[Stopping notifications for individual alarms](tutorials/stop-notifications-alarms.md)
37
47
-Both of these entities have exactly the same format and feature set.
48
-The only difference is the label `alarm` or `template`.
38
+[Use dimension templates to create dynamic alarms](tutorials/dimension-templates.md)
39
50
-Netdata supports overriding **templates** with **alarms**.
51
-For example, when a template is defined for a set of charts, an alarm with exactly the
52
-same name attached to the same chart the template matches, will have higher precedence
53
-(i.e. Netdata will use the alarm on this chart and prevent the template from being applied
54
-to it).
40
+</div>
41
+</DocsTutorials>
42
56
-### The format
43
+## Related features
44
58
-The following lines are parsed.
59
-
60
-#### Alarm line `alarm` or `template`
61
-
62
-This line starts an alarm or alarm template.
63
-
64
-```
65
-alarm: NAME
66
-```
67
-
68
-or
69
-
70
-```
71
-template: NAME
72
-```
73
-
74
-This line has to be first on each alarm or template.
75
-`NAME` is anything you would like to name it (the only symbols allowed are `.` and `_`).
76
-
77
----
78
-
79
-#### Alarm line `on`
80
-
81
-This line defines the data the alarm should be attached to.
82
-
83
-For alarms:
84
-
85
-```
86
-on: CHART
87
-```
88
-
89
-For `CHART` you can use a chart `id` or `name` of the chart, as shown on the dashboard.
90
-
91
-For alarm templates:
92
-
93
-```
94
-on: CONTEXT
95
-```
96
-
97
-`CONTEXT` is the template of a chart. For example the charts `mysql_local.net` and
98
-`mysql_server2.net` have the same context: `mysql.net`. So, you can use this to apply
99
-alarms to all `mysql.net` charts.
100
-
101
-To find the `CONTEXT` of a chart hover over its date, above the legend. A tooltip will
102
-appear with this format `plugin:nodule, context`. For example, the bandwidth chart of
103
-a network interface says:
104
-
105
-```
106
-proc:/proc/dev/dev, net.net
107
-```
108
-
109
-So, `plugin = proc`, `module = /proc/net/dev` and `context = net.net`.
110
-
111
----
112
-
113
-#### Alarm line `os`
114
-
115
-This alarm or template will be used only if the O/S of the host loading it, matches this
116
-pattern list. The value is a space separated list of simple patterns (use `*` as wildcard,
117
-prefix with `!` for a negative match, order is important).
118
-
119
-```
120
-os: linux freebsd macos
121
-```
122
-
123
----
124
-
125
-#### Alarm line `hosts`
126
-
127
-This alarm or template will be used only if the hostname of the host loading it, matches
128
-this pattern list. The value is a space separated list of simple patterns (use `*` as wildcard,
129
-prefix with `!` for a negative match, order is important).
130
-
131
-```
132
-hosts: server1 server2 database* !redis3 redis*
133
-```
134
-
135
-The above says: use this alarm on all hosts named `server1`, `server2`, `database*`, and
136
-all `redis*` except `redis3`.
137
-
138
-This is useful when you centralize metrics from multiple hosts, to one Netdata.
139
-
140
----
141
-
142
-#### Alarm line `families`
143
-
144
-This line is only used in alarm templates. It filters the charts. So, if you need to create
145
-an alarm template for a few of a kind of chart (a few of your disks, or a few of your network
146
-interfaces, or a few your mysql servers, etc), you can create an alarm template that would
147
-normally be applied to all of them, and filter them by [family](../web/README.md#families).
148
-
149
-The format is:
150
-
151
-```
152
-families: SIMPLE PATTERN LIST
153
-```
154
-
155
-The simple pattern syntax and operation is explained in [simple patterns](../libnetdata/simple_pattern/).
156
-
157
----
158
-
159
-#### Alarm line `lookup`
160
-
161
-This line makes a database lookup to find a value. This result of this lookup is available as `$this`.
162
-
163
-The format is:
164
-
165
-```
166
-lookup: METHOD AFTER [at BEFORE] [every DURATION] [OPTIONS] [of DIMENSIONS] [foreach DIMENSIONS]
167
-```
168
-
169
-Everything is the same with [badges](../web/api/badges/). In short:
170
-
171
-- `METHOD` is one of `average`, `min`, `max`, `sum`, `incremental-sum`.
172
- This is required.
173
-
174
-- `AFTER` is a relative number of seconds, but it also accepts a single letter for changing
175
- the units, like `-1s` = 1 second in the past, `-1m` = 1 minute in the past, `-1h` = 1 hour
176
- in the past, `-1d` = 1 day in the past. You need a negative number (i.e. how far in the past
177
- to look for the value). **This is required**.
178
-
179
-- `at BEFORE` is by default 0 and is not required. Using this you can define the end of the
180
- lookup. So data will be evaluated between `AFTER` and `BEFORE`.
181
-
182
-- `every DURATION` sets the updated frequency of the lookup (supports single letter units as
183
- above too).
184
-
185
-- `OPTIONS` is a space separated list of `percentage`, `absolute`, `min2max`, `unaligned`,
186
- `match-ids`, `match-names`. Check the badges documentation for more info.
187
-
188
-- `of DIMENSIONS` is optional and has to be the last parameter. Dimensions have to be separated
189
- by `,` or `|`. The space characters found in dimensions will be kept as-is (a few dimensions
190
- have spaces in their names). This accepts Netdata simple patterns and the `match-ids` and
191
- `match-names` options affect the searches for dimensions.
192
-
193
-- `foreach DIMENSIONS` is optional, will always be the last parameter, and uses the same `,`/`|`
194
- rules as the `of` parameter. Each dimension you specify in `foreach` will use the same rule
195
- to trigger an alarm. If you set both `of` and `foreach`, Netdata will ignore the `of` parameter
196
- and replace it with one of the dimensions you gave to `foreach`.
197
-
198
-The result of the lookup will be available as `$this` and `$NAME` in expressions.
199
-The timestamps of the timeframe evaluated by the database lookup is available as variables
200
-`$after` and `$before` (both are unix timestamps).
201
-
202
----
203
-
204
-#### Alarm line `calc`
205
-
206
-This expression is evaluated just after the `lookup` (if any). Its purpose is to apply some
207
-calculation before using the value looked up from the db.
208
-
209
-You can also have an expression without a lookup, using other variables that are available.
210
-
211
-The result of the calculation will be available as `$this` in warning and critical expressions
212
-(overwriting the `lookup` one).
213
-
214
-Format:
215
-
216
-```
217
-calc: EXPRESSION
218
-```
219
-
220
-Check [Expressions](#expressions) for more information.
221
-
222
----
223
-
224
-#### Alarm line `every`
225
-
226
-Sets the update frequency of this alarm. This is the same to the `every DURATION` given
227
-in the `lookup` lines.
228
-
229
-Format:
230
-
231
-```
232
-every: DURATION
233
-```
234
-
235
-`DURATION` accepts `s` for seconds, `m` is minutes, `h` for hours, `d` for days.
236
-
237
----
238
-
239
-#### Alarm lines `green` and `red`
240
-
241
-Set the green and red thresholds of a chart. Both are available as `$green` and `$red` in
242
-expressions. If multiple alarms define different thresholds, the ones defined by the first
243
-alarm will be used. These will eventually visualized on the dashboard, so only one set of
244
-them is allowed. If you need multiple sets of them in different alarms, use absolute numbers
245
-instead of `$red` and `$green`.
246
-
247
-Format:
248
-
249
-```
250
-green: NUMBER
251
-red: NUMBER
252
-```
253
-
254
----
255
-
256
-#### Alarm lines `warn` and `crit`
257
-
258
-These expressions should evaluate to true or false (alternatively non-zero or zero).
259
-They trigger the alarm. Both are optional.
260
-
261
-Format:
262
-
263
-```
264
-warn: EXPRESSION
265
-crit: EXPRESSION
266
-```
267
-
268
-Check [Expressions](#expressions) for more information.
269
-
270
----
271
-
272
-#### Alarm line `to`
273
-
274
-This will be the first parameter of the script to be executed when the alarm switches status.
275
-Its meaning is left up to the `exec` script.
276
-
277
-The default `exec` script, `alarm-notify.sh`, uses this field as a space separated list of roles,
278
-which are then consulted to find the exact recipients per notification method.
279
-
280
-Format:
281
-
282
-```
283
-to: ROLE1 ROLE2 ROLE3 ...
284
-```
285
-
286
----
287
-
288
-#### Alarm line `exec`
289
-
290
-The script that will be executed when the alarm changes status.
291
-
292
-Format:
293
-
294
-```
295
-exec: SCRIPT
296
-```
297
-
298
-The default `SCRIPT` is Netdata's `alarm-notify.sh`, which supports all the notifications
299
-methods Netdata supports, including custom hooks.
300
-
301
----
302
-
303
-#### Alarm line `delay`
304
-
305
-This is used to provide optional hysteresis settings for the notifications, to defend
306
-against notification floods. These settings do not affect the actual alarm - only the time
307
-the `exec` script is executed.
308
-
309
-Format:
310
-
311
-```
312
-delay: [[[up U] [down D] multiplier M] max X]
313
-```
314
-
315
-- `up U` defines the delay to be applied to a notification for an alarm that raised its status
316
- (i.e. CLEAR to WARNING, CLEAR to CRITICAL, WARNING to CRITICAL). For example, `up 10s`, the
317
- notification for this event will be sent 10 seconds after the actual event. This is used in
318
- hope the alarm will get back to its previous state within the duration given. The default `U`
319
- is zero.
320
-
321
-- `down D` defines the delay to be applied to a notification for an alarm that moves to lower
322
- state (i.e. CRITICAL to WARNING, CRITICAL to CLEAR, WARNING to CLEAR). For example, `down 1m`
323
- will delay the notification by 1 minute. This is used to prevent notifications for flapping
324
- alarms. The default `D` is zero.
325
-
326
-- `mutliplier M` multiplies `U` and `D` when an alarm changes state, while a notification is
327
- delayed. The default multiplier is `1.0`.
328
-
329
-- `max X` defines the maximum absolute notification delay an alarm may get. The default `X`
330
- is `max(U * M, D * M)` (i.e. the max duration of `U` or `D` multiplied once with `M`).
331
-
332
- Example:
333
-
334
- `delay: up 10s down 15m multiplier 2 max 1h`
335
-
336
- The time is `00:00:00` and the status of the alarm is CLEAR.
337
-
338
- | time of event | new status | delay | notification will be sent|why|
339
- |-------------|----------|:---:|-------------------------|---|
340
- | 00:00:01 | WARNING | `up 10s` | 00:00:11|first state switch|
341
- | 00:00:05 | CLEAR | `down 15m x2` | 00:30:05|the alarm changes state while a notification is delayed, so it was multiplied|
342
- | 00:00:06 | WARNING | `up 10s x2 x2` | 00:00:26|multiplied twice|
343
- | 00:00:07 | CLEAR | `down 15m x2 x2 x2` | 00:45:07|multiplied 3 times.|
344
-
345
- So:
346
-
347
- - `U` and `D` are multiplied by `M` every time the alarm changes state (any state, not just
348
- their matching one) and a delay is in place.
349
- - All are reset to their defaults when the alarm switches state without a delay in place.
350
-
351
----
352
-
353
-#### Alarm line `repeat`
354
-
355
-Defines the interval between repeating notifications for the alarms in CRITICAL or WARNING mode. This will override the default interval settings inherited from health settings in `netdata.conf`. The default settings for repeating notifications are `default repeat warning = DURATION` and `default repeat critical = DURATION` which can be found in health stock configuration, when one of these interval is bigger than 0, Netdata will activate the repeat notification for `CRITICAL`, `CLEAR` and `WARNING` messages.
356
-`
357
-
358
-Format:
359
-
360
-```
361
-repeat: [off] [warning DURATION] [critical DURATION]
362
-```
363
-
364
-- `off`: Turns off the repeating feature for the current alarm. This is effective when the default repeat settings has been enabled in health configuration.
365
-- `warning DURATION`: Defines the interval when the alarm is in WARNING state. Use `0s` to turn off the repeating notification for WARNING mode.
366
-- `critical DURATION`: Defines the interval when the alarm is in CRITICAL state. Use `0s` to turn off the repeating notification for CRITICAL mode.
367
-
368
----
369
-
370
-#### Alarm line `option`
371
-
372
-The only possible value for the `option` line is
373
-
374
-```
375
-option: no-clear-notification
376
-```
377
-
378
-For some alarms we need compare two time-frames, to detect anomalies. For example, `health.d/httpcheck.conf` has an alarm template called `web_service_slow` that compares the average http call response time over the last 3 minutes, compared to the average over the last hour. It triggers a warning alarm when the average of the last 3 minutes is twice the average of the last hour. In such cases, it is easy to trigger the alarm, but difficult to tell when the alarm is cleared. As time passes, the newest window moves into the older, so the average response time of the last hour will keep increasing. Eventually, the comparison will find the averages in the two time-frames close enough to clear the alarm. However, the issue was not resolved, it's just a matter of the newer data "polluting" the old. For such alarms, it's a good idea to tell Netdata to not clear the notification, by using the `no-clear-notification` option.
379
-
380
----
381
-
382
-### Expressions
383
-
384
-Netdata has an internal [infix expression parser](../libnetdata/eval).
385
-This parses expressions and creates an internal structure that allows fast execution of them.
386
-
387
-These operators are supported `+`, `-`, `*`, `/`, `<`, `<=`, `<>`, `!=`, `>`, `>=`, `&&`, `||`,
388
-`!`, `AND`, `OR`, `NOT`. Boolean operators result in either `1` (true) or `0` (false).
389
-
390
-The conditional evaluation operator `?` is supported too. Using this operator IF-THEN-ELSE conditional statements can be specified. The format is: `(condition) ? (true expression) :(false expression)`. So, Netdata will first evaluate the `condition` and based on the result will either evaluate `true expression` or `false expression`.
391
-
392
-Example: `($this > 0) ? ($avail * 2) : ($used / 2)`.
393
-
394
-Nested such expressions are also supported (i.e. `true expression` and `false expression` can contain conditional evaluations).
395
-
396
-Expressions also support the `abs()` function.
397
-
398
-Expressions can have variables. Variables start with `$`. Check below for more information.
399
-
400
-There are two special values you can use:
401
-
402
-- `nan`, for example `$this != nan` will check if the variable `this` is available. A variable can be `nan` if the database lookup failed. All calculations (i.e. addition, multiplication, etc) with a `nan` result in a `nan`.
403
-
404
-- `inf`, for example `$this != inf` will check if `this` is not infinite. A value or variable can be infinite if divided by zero. All calculations (i.e. addition, multiplication, etc) with a `inf` result in a `inf`.
405
-
406
----
407
-
408
-### Special use of the conditional operator
409
-
410
-A common (but not necessarily obvious) use of the conditional evaluation operator is
411
-to provide [hysteresis](https://en.wikipedia.org/wiki/Hysteresis) around the critical
412
-or warning thresholds. This usage helps to avoid bogus messages resulting from small
413
-variations in the value when it is varying regularly but staying close to the threshold
414
-value, without needing to delay sending messages at all.
415
-
416
-An example of such usage from the default CPU usage alarms bundled with Netdata is:
417
-
418
-```
419
-warn: $this > (($status >= $WARNING) ? (75) : (85))
420
-crit: $this > (($status == $CRITICAL) ? (85) : (95))
421
-```
422
-
423
-The above say:
424
-
425
-- If the alarm is currently a warning, then the threshold for being considered a warning
426
- is 75, otherwise it's 85.
427
-
428
-- If the alarm is currently critical, then the threshold for being considered critical
429
- is 85, otherwise it's 95.
430
-
431
-Which in turn, results in the following behavior:
432
-
433
-- While the value is rising, it will trigger a warning when it exceeds 85, and a critical
434
- alert when it exceeds 95.
435
-
436
-- While the value is falling, it will return to a warning state when it goes below 85,
437
- and a normal state when it goes below 75.
438
-
439
-- If the value is constantly varying between 80 and 90, then it will trigger a warning the
440
- first time it goes above 85, but will remain a warning until it goes below 75 (or goes above 85).
441
-
442
-- If the value is constantly varying between 90 and 100, then it will trigger a critical alert
443
- the first time it goes above 95, but will remain a critical alert goes below 85 (at which
444
- point it will return to being a warning).
445
-
446
----
447
-
448
-### Variables
449
-
450
-You can find all the variables that can be used for a given chart, using
451
-`http://your.netdata.ip:19999/api/v1/alarm_variables?chart=CHART_NAME`
452
-Example: [variables for the `system.cpu` chart of the registry](https://registry.my-netdata.io/api/v1/alarm_variables?chart=system.cpu).
453
-
454
-_Hint: If you don't know how to find the CHART_NAME, you can read about it [here](../web/README.md#charts)._
455
-
456
-Netdata supports 3 internal indexes for variables that will be used in health monitoring.
457
-
458
-<details markdown="1"><summary>The variables below can be used in both chart alarms and context templates.</summary>
459
-
460
-Although the `alarm_variables` link shows you variables for a particular chart, the same variables can also be used in templates for charts belonging to a given [context](../web/README.md#contexts). The reason is that all charts of a given context are essentially identical, with the only difference being the [family](../web/README.md#families) that identifies a particular hardware or software instance. Charts and templates do not apply to specific families anyway, unless if you explicitly limit an alarm with the [alarm line `families`](#alarm-line-families).
461
-</details>
462
-
463
-- **chart local variables**. All the dimensions of the chart are exposed as local variables. The value of $this for the other configured alarms of the chart also appears, under the name of each configured alarm.
464
-
465
- Charts also define a few special variables:
466
-
467
- - `$last_collected_t` is the unix timestamp of the last data collection
468
- - `$collected_total_raw` is the sum of all the dimensions (their last collected values)
469
- - `$update_every` is the update frequency of the chart
470
- - `$green` and `$red` the threshold defined in alarms (these are per chart - the charts
471
- inherits them from the the first alarm that defined them)
472
-
473
- Chart dimensions define their last calculated (i.e. interpolated) value, exactly as
474
- shown on the charts, but also a variable with their name and suffix `_raw` that resolves
475
- to the last collected value - as collected and another with suffix `_last_collected_t`
476
- that resolves to unix timestamp the dimension was last collected (there may be dimensions
477
- that fail to be collected while others continue normally).
478
-
479
-- **family variables**. Families are used to group charts together. For example all `eth0`
480
- charts, have `family = eth0`. This index includes all local variables, but if there are
481
- overlapping variables, only the first are exposed.
482
-
483
-- **host variables**. All the dimensions of all charts, including all alarms, in fullname.
484
- Fullname is `CHART.VARIABLE`, where `CHART` is either the chart id or the chart name (both
485
- are supported).
486
-
487
-- **special variables\*** are:
488
-
489
- - `$this`, which is resolved to the value of the current alarm.
490
-
491
- - `$status`, which is resolved to the current status of the alarm (the current = the last
492
- status, i.e. before the current database lookup and the evaluation of the `calc` line).
493
- This values can be compared with `$REMOVED`, `$UNINITIALIZED`, `$UNDEFINED`, `$CLEAR`,
494
- `$WARNING`, `$CRITICAL`. These values are incremental, ie. `$status > $CLEAR` works as
495
- expected.
496
-
497
- - `$now`, which is resolved to current unix timestamp.
498
-
499
-## Alarm Statuses
500
-
501
-Alarms can have the following statuses:
502
-
503
-- `REMOVED` - the alarm has been deleted (this happens when a SIGUSR2 is sent to Netdata
504
- to reload health configuration)
505
-
506
-- `UNINITIALIZED` - the alarm is not initialized yet
507
-
508
-- `UNDEFINED` - the alarm failed to be calculated (i.e. the database lookup failed,
509
- a division by zero occurred, etc)
510
-
511
-- `CLEAR` - the alarm is not armed / raised (i.e. is OK)
512
-
513
-- `WARNING` - the warning expression resulted in true or non-zero
514
-
515
-- `CRITICAL` - the critical expression resulted in true or non-zero
516
-
517
-The external script will be called for all status changes.
518
-
519
-## Examples
520
-
521
-Check the `health/health.d/` directory for all alarms shipped with Netdata.
522
-
523
-Here are a few examples:
524
-
525
-### Example 1
526
-
527
-A simple check if an apache server is alive:
528
-
529
-```
530
-template: apache_last_collected_secs
531
- on: apache.requests
532
- calc: $now - $last_collected_t
533
- every: 10s
534
- warn: $this > ( 5 * $update_every)
535
- crit: $this > (10 * $update_every)
536
-```
537
-
538
-The above checks that Netdata is able to collect data from apache. In detail:
539
-
540
-```
541
-template: apache_last_collected_secs
542
-```
543
-
544
-The above defines a **template** named `apache_last_collected_secs`.
545
-The name is important since `$apache_last_collected_secs` resolves to the `calc` line.
546
-So, try to give something descriptive.
547
-
548
-```
549
- on: apache.requests
550
-```
551
-
552
-The above applies the **template** to all charts that have `context = apache.requests`
553
-(i.e. all your apache servers).
554
-
555
-```
556
- calc: $now - $last_collected_t
557
-```
558
-
559
-- `$now` is a standard variable that resolves to the current timestamp.
560
-
561
-- `$last_collected_t` is the last data collection timestamp of the chart.
562
- So this calculation gives the number of seconds passed since the last data collection.
563
-
564
-```
565
- every: 10s
566
-```
567
-
568
-The alarm will be evaluated every 10 seconds.
569
-
570
-```
571
- warn: $this > ( 5 * $update_every)
572
- crit: $this > (10 * $update_every)
573
-```
574
-
575
-If these result in non-zero or true, they trigger the alarm.
576
-
577
-- `$this` refers to the value of this alarm (i.e. the result of the `calc` line.
578
- We could also use `$apache_last_collected_secs`.
579
-
580
-`$update_every` is the update frequency of the chart, in seconds.
581
-
582
-So, the warning condition checks if we have not collected data from apache for 5
583
-iterations and the critical condition checks for 10 iterations.
584
-
585
-### Example 2
586
-
587
-Check if any of the disks is critically low on disk space:
588
-
589
-```
590
-template: disk_full_percent
591
- on: disk.space
592
- calc: $used * 100 / ($avail + $used)
593
- every: 1m
594
- warn: $this > 80
595
- crit: $this > 95
596
- repeat: warning 120s critical 10s
597
-```
598
-
599
-`$used` and `$avail` are the `used` and `avail` chart dimensions as shown on the dashboard.
600
-
601
-So, the `calc` line finds the percentage of used space. `$this` resolves to this percentage.
602
-
603
-This is a repeating alarm and if the alarm becomes CRITICAL it repeats the notifications every 10 seconds. It also repeats notifications every 2 minutes if the alarm goes into WARNING mode.
604
-
605
-### Example 3
606
-
607
-Predict if any disk will run out of space in the near future.
608
-
609
-We do this in 2 steps:
610
-
611
-Calculate the disk fill rate:
612
-
613
-```
614
- template: disk_fill_rate
615
- on: disk.space
616
- lookup: max -1s at -30m unaligned of avail
617
- calc: ($this - $avail) / (30 * 60)
618
- every: 15s
619
-```
620
-
621
-In the `calc` line: `$this` is the result of the `lookup` line (i.e. the free space 30 minutes
622
-ago) and `$avail` is the current disk free space. So the `calc` line will either have a positive
623
-number of GB/second if the disk if filling up, or a negative number of GB/second if the disk is
624
-freeing up space.
625
-
626
-There is no `warn` or `crit` lines here. So, this template will just do the calculation and
627
-nothing more.
628
-
629
-Predict the hours after which the disk will run out of space:
630
-
631
-```
632
- template: disk_full_after_hours
633
- on: disk.space
634
- calc: $avail / $disk_fill_rate / 3600
635
- every: 10s
636
- warn: $this > 0 and $this < 48
637
- crit: $this > 0 and $this < 24
638
-```
639
-
640
-The `calc` line estimates the time in hours, we will run out of disk space. Of course, only
641
-positive values are interesting for this check, so the warning and critical conditions check
642
-for positive values and that we have enough free space for 48 and 24 hours respectively.
643
-
644
-Once this alarm triggers we will receive an email like this:
645
-
646
-
647
-
648
-### Example 4
649
-
650
-Check if any network interface is dropping packets:
651
-
652
-```
653
-template: 30min_packet_drops
654
- on: net.drops
655
- lookup: sum -30m unaligned absolute
656
- every: 10s
657
- crit: $this > 0
658
-```
659
-
660
-The `lookup` line will calculate the sum of the all dropped packets in the last 30 minutes.
661
-
662
-The `crit` line will issue a critical alarm if even a single packet has been dropped.
663
-
664
-Note that the drops chart does not exist if a network interface has never dropped a single packet.
665
-When Netdata detects a dropped packet, it will add the chart and it will automatically attach this
666
-alarm to it.
667
-
668
-### Example 5
669
-
670
-Check if user or system dimension is using more than 50% of cpu:
671
-
672
-```
673
- alarm: dim_template
674
- on: system.cpu
675
- os: linux
676
-lookup: average -3s percentage foreach system,user
677
- units: %
678
- every: 10s
679
- warn: $this > 50
680
- crit: $this > 80
681
-```
682
-
683
-The `lookup` line will calculate the average CPU usage from system and user in the last 3 seconds. Because we have
684
-the foreach in the `lookup` line, Netdata will create two independent alarms called `dim_template_system`
685
-and `dim_template_user` that will have all the other parameters shared among them.
686
-
687
-### Example 6
688
-
689
-Check if all dimensions are using more than 50% of cpu:
690
-
691
-```
692
- alarm: dim_template
693
- on: system.cpu
694
- os: linux
695
-lookup: average -3s percentage foreach *
696
- units: %
697
- every: 10s
698
- warn: $this > 50
699
- crit: $this > 80
700
-```
701
-
702
-The `lookup` line will calculate the average of CPU usage from system and user in the last 3 seconds. In this case
703
-Netdata will create alarms for all dimensions of the chart.
704
-
705
-## Troubleshooting
706
-
707
-You can compile Netdata with [debugging](../daemon#debugging) and then set in `netdata.conf`:
708
-
709
-```
710
-[global]
711
- debug flags = 0x0000000000800000
712
-```
713
-
714
-Then check your `/var/log/netdata/debug.log`. It will show you how it works.
715
-Important: this will generate a lot of output in debug.log.
716
-
717
-You can find the context of charts by looking up the chart in either
718
-`http://your.netdata:19999/netdata.conf` or `http://your.netdata:19999/api/v1/charts`.
719
-
720
-You can find how Netdata interpreted the expressions by examining the alarm at `http://your.netdata:19999/api/v1/alarms?all`. For each expression, Netdata will return the expression as given in its config file, and the same expression with additional parentheses added to indicate the evaluation flow of the expression.
721
-
722
-## Disabling health checks or silencing notifications at runtime
723
-
724
-It's currently not possible to schedule notifications from within the alarm template. For those scenarios where you need to temporary disable notifications (for instance when running backups triggers a disk alert) you can disable or silence notifications are runtime. The health checks can be controlled at runtime via the [health management api](../web/api/health/#health-management-api).
725
-
726
-[](<>)
45
+**[Health notifications](notifications/README.md)**: Get notified about Netdata's alarms via your favorite platform(s).
health/REFERENCE.md
new
+724
@@ -0,0 +1,724 @@
1
+# Health configuration reference
2
+
3
+Welcome to the health configuration reference.
4
+
5
+This guide contains information about editing health configuration files to tweak existing alarms or create new health
6
+entities that are customized to the needs of your infrastructure.
7
+
8
+To learn the basics of locating and editing health configuration files, see the [health quickstart](QUICKSTART.md).
9
+
10
+## What's in this reference guide
11
+
12
+- [Health entity reference](#health-entity-reference)
13
+ - [Entity types](#entity-types)
14
+ - [Entity format](#entity-format)
15
+- [Expressions](#expressions)
16
+ - [Special use of the conditional operator](#special-use-of-the-conditional-operator)
17
+- [Variables](#variables)
18
+- [Alarm statuses](#alarm-statuses)
19
+- [Example alarms](#example-alarms)
20
+- [Troubleshooting](#troubleshooting)
21
+- [Disabling health checks or silencing notifications at runtime](#disabling-health-checks-or-silencing-notifications-at-runtime)
22
+
23
+## Health entity reference
24
+
25
+The following reference contains information about the syntax and options of _health entities_, which Netdata attaches
26
+to charts in order to trigger alarms.
27
+
28
+Entities are written into `.conf` files, inside of the `health.d/` directory, using YAML formatting.
29
+
30
+### Entity types
31
+
32
+There are two entity types: **alarms** and **templates**. They have the same format and feature set—the only difference
33
+is their label.
34
+
35
+**Alarms** are attached to specific charts and use the `alarm` label.
36
+
37
+**Templates** define rules that apply to all charts of a specific context, and use the `template` label. Templates help
38
+you apply one entity to all disks, all network interfaces, all MySQL databases, and so on.
39
+
40
+Alarms have higher precedence and will override templates. If an alarm and template entity have the same name and attach
41
+to the same chart, Netdata will use the alarm.
42
+
43
+### Entity format
44
+
45
+Netdata parses the following lines. Beneath the table is an in-depth explanation of each line's purpose and syntax.
46
+
47
+- The `on` and `lookup` lines are **always required**.
48
+- Each entity **must** have one of the following lines: `calc`, `warn`, or `crit`.
49
+- The `alarm` or `template` line must be the first line of any entity.
50
+- A few lines use space-separated lists to define how the entity behaves. You can use `*` as a wildcard or prefix with
51
+ `!` for a negative match. Order is important, too! See our [simple patterns docs](../libnetdata/simple_pattern/) for
52
+ more examples.
53
+
54
+| line | required | functionality |
55
+| --------------------------------------------------- | --------------- | ------------------------------------------------------------------------------------- |
56
+| [`alarm`/`template`](#alarm-line-alarm-or-template) | yes | Name of the alarm/template. |
57
+| [`on`](#alarm-line-on) | yes | The chart this alarm should attach to. |
58
+| [`os`](#alarm-line-os) | no | Which operating systems to run this chart. |
59
+| [`hosts`](#alarm-line-hosts) | no | Which hostnames will run this alarm. |
60
+| [`families`](#alarm-line-families) | no | Restrict a template to only certain families. |
61
+| [`lookup`](#alarm-line-lookup) | yes | The database lookup to find and process metrics for the chart specified through `on`. |
62
+| [`calc`](#alarm-line-calc) | yes (see above) | A calculation to apply to the value found via `lookup` or another variable. |
63
+| [`every`](#alarm-line-every) | no | The frequency of the alarm. |
64
+| [`green`/`red`](#alarm-lines-green-and-red) | no | Set the green and red thresholds of a chart. |
65
+| [`warn`/`crit`](#alarm-lines-warn-and-crit) | yes (see above) | Expressions evaluating to true or false, and when true, will trigger the alarm. |
66
+| [`to`](#alarm-line-to) | no | A list of roles to send notifications to. |
67
+| [`exec`](#alarm-line-exec) | no | The script to execute when the alarm changes status. |
68
+| [`delay`](#alarm-line-delay) | no | Optional hysteresis settings to prevent floods of notifications. |
69
+| [`repeat`](#alarm-line-repeat) | no | The interval for sending notifications when an alarm is in WARNING or CRITICAL mode. |
70
+| [`option`](#alarm-line-option) | no | Add an option to not clear alarms. |
71
+
72
+The `alarm` or `template` line must be the first line of any entity.
73
+
74
+#### Alarm line `alarm` or `template`
75
+
76
+This line starts an alarm or template based on the [entity type](#entity-types) you're interested in creating.
77
+
78
+**Alarm:**
79
+
80
+```yaml
81
+alarm: NAME
82
+```
83
+
84
+**Template:**
85
+
86
+```yaml
87
+template: NAME
88
+```
89
+
90
+`NAME` can be anything, with `.` (period) and `_` (underscore) as the only allowed symbols.
91
+
92
+#### Alarm line `on`
93
+
94
+This line defines the chart this alarm should attach to.
95
+
96
+**Alarms:**
97
+
98
+```yaml
99
+on: CHART
100
+```
101
+
102
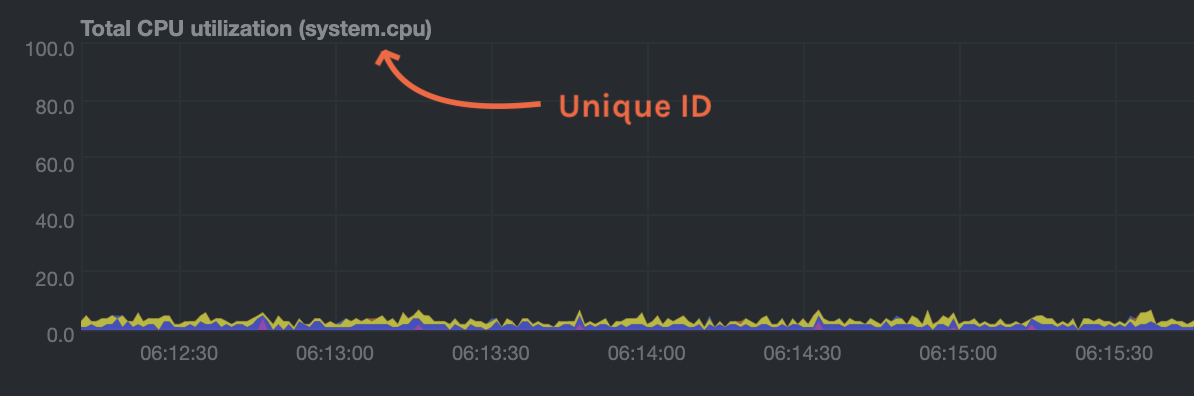
+The value `CHART` should be the unique ID or name of the chart you're interested in, as shown on the dashboard. In the
103
+image below, the unique ID is `system.cpu`.
104
+
105
+
107
+
108
+**Template:**
109
+
110
+```yaml
111
+on: CONTEXT
112
+```
113
+
114
+The value `CONTEXT` should be the context you want this template to attach to.
115
+
116
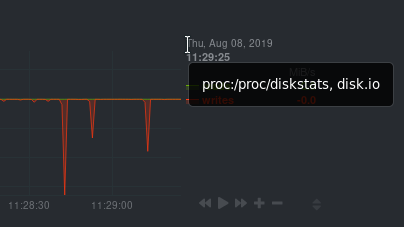
+Need to find the context? Hover over the date on any given chart and look at the tooltip. In the image below, which
117
+shows a disk I/O chart, the tooltip reads: `proc:/proc/diskstats, disk.io`.
118
+
119
+
120
+
121
+You're interested in what comes after the comma: `disk.io`. That's the name of the chart's context.
122
+
123
+If you create a template using the `disk.io` context, it will apply an alarm to every disk available on your system.
124
+
125
+#### Alarm line `os`
126
+
127
+The alarm or template will be used only if the operating system of the host matches this list specified in `os`. The
128
+value is a space-separated list.
129
+
130
+The following example enables the entity on Linux, FreeBSD, and MacOS, but no other operating systems.
131
+
132
+```yaml
133
+os: linux freebsd macos
134
+```
135
+
136
+#### Alarm line `hosts`
137
+
138
+The alarm or template will be used only if the hostname of the host matches this space-separated list.
139
+
140
+The following example will load on systems with the hostnames `server` and `server2`, and any system with hostnames that
141
+begin with `database`. It _will not load_ on the host `redis3`, but will load on any _other_ systems with hostnames that
142
+begin with `redis`.
143
+
144
+```yaml
145
+hosts: server1 server2 database* !redis3 redis*
146
+```
147
+
148
+#### Alarm line `families`
149
+
150
+The `families` line, used only alongside templates, filters which families within the context this alarm should apply
151
+to. The value is a space-separated list.
152
+
153
+The value is a space-separate list of simple patterns. See our [simple patterns docs](../libnetdata/simple_pattern/) for
154
+some examples.
155
+
156
+For example, you can create a template on the `disk.io` context, but filter it to only the `sda` and `sdb` families:
157
+
158
+```yaml
159
+families: sda sdb
160
+```
161
+
162
+#### Alarm line `lookup`
163
+
164
+This line makes a database lookup to find a value. This result of this lookup is available as `$this`.
165
+
166
+The format is:
167
+
168
+```yaml
169
+lookup: METHOD AFTER [at BEFORE] [every DURATION] [OPTIONS] [of DIMENSIONS] [foreach DIMENSIONS]
170
+```
171
+
172
+Everything is the same with [badges](../web/api/badges/). In short:
173
+
174
+- `METHOD` is one of `average`, `min`, `max`, `sum`, `incremental-sum`.
175
+ This is required.
176
+
177
+- `AFTER` is a relative number of seconds, but it also accepts a single letter for changing
178
+ the units, like `-1s` = 1 second in the past, `-1m` = 1 minute in the past, `-1h` = 1 hour
179
+ in the past, `-1d` = 1 day in the past. You need a negative number (i.e. how far in the past
180
+ to look for the value). **This is required**.
181
+
182
+- `at BEFORE` is by default 0 and is not required. Using this you can define the end of the
183
+ lookup. So data will be evaluated between `AFTER` and `BEFORE`.
184
+
185
+- `every DURATION` sets the updated frequency of the lookup (supports single letter units as
186
+ above too).
187
+
188
+- `OPTIONS` is a space separated list of `percentage`, `absolute`, `min2max`, `unaligned`,
189
+ `match-ids`, `match-names`. Check the badges documentation for more info.
190
+
191
+- `of DIMENSIONS` is optional and has to be the last parameter. Dimensions have to be separated
192
+ by `,` or `|`. The space characters found in dimensions will be kept as-is (a few dimensions
193
+ have spaces in their names). This accepts Netdata simple patterns and the `match-ids` and
194
+ `match-names` options affect the searches for dimensions.
195
+
196
+- `foreach DIMENSIONS` is optional, will always be the last parameter, and uses the same `,`/`|`
197
+ rules as the `of` parameter. Each dimension you specify in `foreach` will use the same rule
198
+ to trigger an alarm. If you set both `of` and `foreach`, Netdata will ignore the `of` parameter
199
+ and replace it with one of the dimensions you gave to `foreach`.
200
+
201
+The result of the lookup will be available as `$this` and `$NAME` in expressions.
202
+The timestamps of the timeframe evaluated by the database lookup is available as variables
203
+`$after` and `$before` (both are unix timestamps).
204
+
205
+#### Alarm line `calc`
206
+
207
+A `calc` is designed to apply some calculation to the values or variables available to the entity. The result of the
208
+calculation will be made available at the `$this` variable, overwriting the value from your `lookup`, to use in warning
209
+and critical expressions.
210
+
211
+When paired with `lookup`, `calc` will perform the calculation just after `lookup` has retreived a value from Netdata's
212
+database.
213
+
214
+You can use `calc` without `lookup` if you are using [other available variables](#variables).
215
+
216
+The `calc` line uses [expressions](#expressions) for its syntax.
217
+
218
+```yaml
219
+calc: EXPRESSION
220
+```
221
+
222
+#### Alarm line `every`
223
+
224
+Sets the update frequency of this alarm. This is the same to the `every DURATION` given
225
+in the `lookup` lines.
226
+
227
+Format:
228
+
229
+```yaml
230
+every: DURATION
231
+```
232
+
233
+`DURATION` accepts `s` for seconds, `m` is minutes, `h` for hours, `d` for days.
234
+
235
+#### Alarm lines `green` and `red`
236
+
237
+Set the green and red thresholds of a chart. Both are available as `$green` and `$red` in expressions. If multiple
238
+alarms define different thresholds, the ones defined by the first alarm will be used. These will eventually visualized
239
+on the dashboard, so only one set of them is allowed. If you need multiple sets of them in different alarms, use
240
+absolute numbers instead of `$red` and `$green`.
241
+
242
+Format:
243
+
244
+```yaml
245
+green: NUMBER
246
+red: NUMBER
247
+```
248
+
249
+#### Alarm lines `warn` and `crit`
250
+
251
+Define the expression that triggers either a warning or critical alarm. These are optional, and should evaluate to
252
+either true or false (or zero/non-zero).
253
+
254
+The format uses Netdata's [expressions syntax](#expressions).
255
+
256
+```yaml
257
+warn: EXPRESSION
258
+crit: EXPRESSION
259
+```
260
+
261
+#### Alarm line `to`
262
+
263
+This will be the first parameter of the script to be executed when the alarm switches status. Its meaning is left up to
264
+the `exec` script.
265
+
266
+The default `exec` script, `alarm-notify.sh`, uses this field as a space separated list of roles, which are then
267
+consulted to find the exact recipients per notification method.
268
+
269
+Format:
270
+
271
+```yaml
272
+to: ROLE1 ROLE2 ROLE3 ...
273
+```
274
+
275
+#### Alarm line `exec`
276
+
277
+The script that will be executed when the alarm changes status.
278
+
279
+Format:
280
+
281
+```yaml
282
+exec: SCRIPT
283
+```
284
+
285
+The default `SCRIPT` is Netdata's `alarm-notify.sh`, which supports all the notifications methods Netdata supports,
286
+including custom hooks.
287
+
288
+#### Alarm line `delay`
289
+
290
+This is used to provide optional hysteresis settings for the notifications, to defend against notification floods. These
291
+settings do not affect the actual alarm - only the time the `exec` script is executed.
292
+
293
+Format:
294
+
295
+```yaml
296
+delay: [[[up U] [down D] multiplier M] max X]
297
+```
298
+
299
+- `up U` defines the delay to be applied to a notification for an alarm that raised its status
300
+ (i.e. CLEAR to WARNING, CLEAR to CRITICAL, WARNING to CRITICAL). For example, `up 10s`, the
301
+ notification for this event will be sent 10 seconds after the actual event. This is used in
302
+ hope the alarm will get back to its previous state within the duration given. The default `U`
303
+ is zero.
304
+
305
+- `down D` defines the delay to be applied to a notification for an alarm that moves to lower
306
+ state (i.e. CRITICAL to WARNING, CRITICAL to CLEAR, WARNING to CLEAR). For example, `down 1m`
307
+ will delay the notification by 1 minute. This is used to prevent notifications for flapping
308
+ alarms. The default `D` is zero.
309
+
310
+- `mutliplier M` multiplies `U` and `D` when an alarm changes state, while a notification is
311
+ delayed. The default multiplier is `1.0`.
312
+
313
+- `max X` defines the maximum absolute notification delay an alarm may get. The default `X`
314
+ is `max(U * M, D * M)` (i.e. the max duration of `U` or `D` multiplied once with `M`).
315
+
316
+ Example:
317
+
318
+ `delay: up 10s down 15m multiplier 2 max 1h`
319
+
320
+ The time is `00:00:00` and the status of the alarm is CLEAR.
321
+
322
+ | time of event | new status | delay | notification will be sent | why |
323
+ | ------------- | ---------- | --- | ------------------------- | --- |
324
+ | 00:00:01 | WARNING | `up 10s` | 00:00:11 | first state switch |
325
+ | 00:00:05 | CLEAR | `down 15m x2` | 00:30:05 | the alarm changes state while a notification is delayed, so it was multiplied |
326
+ | 00:00:06 | WARNING | `up 10s x2 x2` | 00:00:26 | multiplied twice |
327
+ | 00:00:07 | CLEAR | `down 15m x2 x2 x2` | 00:45:07 | multiplied 3 times. |
328
+
329
+ So:
330
+
331
+ - `U` and `D` are multiplied by `M` every time the alarm changes state (any state, not just
332
+ their matching one) and a delay is in place.
333
+ - All are reset to their defaults when the alarm switches state without a delay in place.
334
+
335
+#### Alarm line `repeat`
336
+
337
+Defines the interval between repeating notifications for the alarms in CRITICAL or WARNING mode. This will override the
338
+default interval settings inherited from health settings in `netdata.conf`. The default settings for repeating
339
+notifications are `default repeat warning = DURATION` and `default repeat critical = DURATION` which can be found in
340
+health stock configuration, when one of these interval is bigger than 0, Netdata will activate the repeat notification
341
+for `CRITICAL`, `CLEAR` and `WARNING` messages.
342
+
343
+Format:
344
+
345
+```yaml
346
+repeat: [off] [warning DURATION] [critical DURATION]
347
+```
348
+
349
+- `off`: Turns off the repeating feature for the current alarm. This is effective when the default repeat settings has
350
+ been enabled in health configuration.
351
+- `warning DURATION`: Defines the interval when the alarm is in WARNING state. Use `0s` to turn off the repeating
352
+ notification for WARNING mode.
353
+- `critical DURATION`: Defines the interval when the alarm is in CRITICAL state. Use `0s` to turn off the repeating
354
+ notification for CRITICAL mode.
355
+
356
+#### Alarm line `option`
357
+
358
+The only possible value for the `option` line is
359
+
360
+```yaml
361
+option: no-clear-notification
362
+```
363
+
364
+For some alarms we need compare two time-frames, to detect anomalies. For example, `health.d/httpcheck.conf` has an
365
+alarm template called `web_service_slow` that compares the average http call response time over the last 3 minutes,
366
+compared to the average over the last hour. It triggers a warning alarm when the average of the last 3 minutes is twice
367
+the average of the last hour. In such cases, it is easy to trigger the alarm, but difficult to tell when the alarm is
368
+cleared. As time passes, the newest window moves into the older, so the average response time of the last hour will keep
369
+increasing. Eventually, the comparison will find the averages in the two time-frames close enough to clear the alarm.
370
+However, the issue was not resolved, it's just a matter of the newer data "polluting" the old. For such alarms, it's a
371
+good idea to tell Netdata to not clear the notification, by using the `no-clear-notification` option.
372
+
373
+## Expressions
374
+
375
+Netdata has an internal [infix expression parser](../libnetdata/eval). This parses expressions and creates an internal
376
+structure that allows fast execution of them.
377
+
378
+These operators are supported `+`, `-`, `*`, `/`, `<`, `<=`, `<>`, `!=`, `>`, `>=`, `&&`, `||`, `!`, `AND`, `OR`, `NOT`.
379
+Boolean operators result in either `1` (true) or `0` (false).
380
+
381
+The conditional evaluation operator `?` is supported too. Using this operator IF-THEN-ELSE conditional statements can be
382
+specified. The format is: `(condition) ? (true expression) : (false expression)`. So, Netdata will first evaluate the
383
+`condition` and based on the result will either evaluate `true expression` or `false expression`.
384
+
385
+Example: `($this > 0) ? ($avail * 2) : ($used / 2)`.
386
+
387
+Nested such expressions are also supported (i.e. `true expression` and `false expression` can contain conditional
388
+evaluations).
389
+
390
+Expressions also support the `abs()` function.
391
+
392
+Expressions can have variables. Variables start with `$`. Check below for more information.
393
+
394
+There are two special values you can use:
395
+
396
+- `nan`, for example `$this != nan` will check if the variable `this` is available. A variable can be `nan` if the
397
+ database lookup failed. All calculations (i.e. addition, multiplication, etc) with a `nan` result in a `nan`.
398
+
399
+- `inf`, for example `$this != inf` will check if `this` is not infinite. A value or variable can be set to infinite
400
+ if divided by zero. All calculations (i.e. addition, multiplication, etc) with a `inf` result in a `inf`.
401
+
402
+### Special use of the conditional operator
403
+
404
+A common (but not necessarily obvious) use of the conditional evaluation operator is to provide
405
+[hysteresis](https://en.wikipedia.org/wiki/Hysteresis) around the critical or warning thresholds. This usage helps to
406
+avoid bogus messages resulting from small variations in the value when it is varying regularly but staying close to the
407
+threshold value, without needing to delay sending messages at all.
408
+
409
+An example of such usage from the default CPU usage alarms bundled with Netdata is:
410
+
411
+```yaml
412
+warn: $this > (($status >= $WARNING) ? (75) : (85))
413
+crit: $this > (($status == $CRITICAL) ? (85) : (95))
414
+```
415
+
416
+The above say:
417
+
418
+- If the alarm is currently a warning, then the threshold for being considered a warning is 75, otherwise it's 85.
419
+
420
+- If the alarm is currently critical, then the threshold for being considered critical is 85, otherwise it's 95.
421
+
422
+Which in turn, results in the following behavior:
423
+
424
+- While the value is rising, it will trigger a warning when it exceeds 85, and a critical alert when it exceeds 95.
425
+
426
+- While the value is falling, it will return to a warning state when it goes below 85, and a normal state when it goes
427
+ below 75.
428
+
429
+- If the value is constantly varying between 80 and 90, then it will trigger a warning the first time it goes above
430
+ 85, but will remain a warning until it goes below 75 (or goes above 85).
431
+
432
+- If the value is constantly varying between 90 and 100, then it will trigger a critical alert the first time it goes
433
+ above 95, but will remain a critical alert goes below 85 (at which point it will return to being a warning).
434
+
435
+## Variables
436
+
437
+You can find all the variables that can be used for a given chart, using
438
+`http://your.netdata.ip:19999/api/v1/alarm_variables?chart=CHART_NAME` Example: [variables for the `system.cpu` chart of
439
+the registry](https://registry.my-netdata.io/api/v1/alarm_variables?chart=system.cpu).
440
+
441
+> If you don't know how to find the CHART_NAME, you can read about it [here](../web/README.md#charts).
442
+
443
+Netdata supports 3 internal indexes for variables that will be used in health monitoring.
444
+
445
+<details markdown="1"><summary>The variables below can be used in both chart alarms and context templates.</summary>
446
+
447
+Although the `alarm_variables` link shows you variables for a particular chart, the same variables can also be used in
448
+templates for charts belonging to a given [context](../web/README.md#contexts). The reason is that all charts of a given
449
+context are essentially identical, with the only difference being the [family](../web/README.md#families) that
450
+identifies a particular hardware or software instance. Charts and templates do not apply to specific families anyway,
451
+unless if you explicitly limit an alarm with the [alarm line `families`](#alarm-line-families).
452
+
453
+</details>
454
+
455
+- **chart local variables**. All the dimensions of the chart are exposed as local variables. The value of `$this` for
456
+ the other configured alarms of the chart also appears, under the name of each configured alarm.
457
+
458
+ Charts also define a few special variables:
459
+
460
+ - `$last_collected_t` is the unix timestamp of the last data collection
461
+ - `$collected_total_raw` is the sum of all the dimensions (their last collected values)
462
+ - `$update_every` is the update frequency of the chart
463
+ - `$green` and `$red` the threshold defined in alarms (these are per chart - the charts
464
+ inherits them from the the first alarm that defined them)
465
+
466
+ Chart dimensions define their last calculated (i.e. interpolated) value, exactly as
467
+ shown on the charts, but also a variable with their name and suffix `_raw` that resolves
468
+ to the last collected value - as collected and another with suffix `_last_collected_t`
469
+ that resolves to unix timestamp the dimension was last collected (there may be dimensions
470
+ that fail to be collected while others continue normally).
471
+
472
+- **family variables**. Families are used to group charts together. For example all `eth0`
473
+ charts, have `family = eth0`. This index includes all local variables, but if there are
474
+ overlapping variables, only the first are exposed.
475
+
476
+- **host variables**. All the dimensions of all charts, including all alarms, in fullname.
477
+ Fullname is `CHART.VARIABLE`, where `CHART` is either the chart id or the chart name (both
478
+ are supported).
479
+
480
+- **special variables\*** are:
481
+
482
+ - `$this`, which is resolved to the value of the current alarm.
483
+
484
+ - `$status`, which is resolved to the current status of the alarm (the current = the last
485
+ status, i.e. before the current database lookup and the evaluation of the `calc` line).
486
+ This values can be compared with `$REMOVED`, `$UNINITIALIZED`, `$UNDEFINED`, `$CLEAR`,
487
+ `$WARNING`, `$CRITICAL`. These values are incremental, ie. `$status > $CLEAR` works as
488
+ expected.
489
+
490
+ - `$now`, which is resolved to current unix timestamp.
491
+
492
+## Alarm statuses
493
+
494
+Alarms can have the following statuses:
495
+
496
+- `REMOVED` - the alarm has been deleted (this happens when a SIGUSR2 is sent to Netdata
497
+ to reload health configuration)
498
+
499
+- `UNINITIALIZED` - the alarm is not initialized yet
500
+
501
+- `UNDEFINED` - the alarm failed to be calculated (i.e. the database lookup failed,
502
+ a division by zero occurred, etc)
503
+
504
+- `CLEAR` - the alarm is not armed / raised (i.e. is OK)
505
+
506
+- `WARNING` - the warning expression resulted in true or non-zero
507
+
508
+- `CRITICAL` - the critical expression resulted in true or non-zero
509
+
510
+The external script will be called for all status changes.
511
+
512
+## Example alarms
513
+
514
+Check the `health/health.d/` directory for all alarms shipped with Netdata.
515
+
516
+Here are a few examples:
517
+
518
+### Example 1
519
+
520
+A simple check if an apache server is alive:
521
+
522
+```yaml
523
+template: apache_last_collected_secs
524
+ on: apache.requests
525
+ calc: $now - $last_collected_t
526
+ every: 10s
527
+ warn: $this > ( 5 * $update_every)
528
+ crit: $this > (10 * $update_every)
529
+```
530
+
531
+The above checks that Netdata is able to collect data from apache. In detail:
532
+
533
+```yaml
534
+template: apache_last_collected_secs
535
+```
536
+
537
+The above defines a **template** named `apache_last_collected_secs`.
538
+The name is important since `$apache_last_collected_secs` resolves to the `calc` line.
539
+So, try to give something descriptive.
540
+
541
+```yaml
542
+ on: apache.requests
543
+```
544
+
545
+The above applies the **template** to all charts that have `context = apache.requests`
546
+(i.e. all your apache servers).
547
+
548
+```yaml
549
+ calc: $now - $last_collected_t
550
+```
551
+
552
+- `$now` is a standard variable that resolves to the current timestamp.
553
+
554
+- `$last_collected_t` is the last data collection timestamp of the chart.
555
+ So this calculation gives the number of seconds passed since the last data collection.
556
+
557
+```yaml
558
+ every: 10s
559
+```
560
+
561
+The alarm will be evaluated every 10 seconds.
562
+
563
+```yaml
564
+ warn: $this > ( 5 * $update_every)
565
+ crit: $this > (10 * $update_every)
566
+```
567
+
568
+If these result in non-zero or true, they trigger the alarm.
569
+
570
+- `$this` refers to the value of this alarm (i.e. the result of the `calc` line.
571
+ We could also use `$apache_last_collected_secs`.
572
+
573
+`$update_every` is the update frequency of the chart, in seconds.
574
+
575
+So, the warning condition checks if we have not collected data from apache for 5
576
+iterations and the critical condition checks for 10 iterations.
577
+
578
+### Example 2
579
+
580
+Check if any of the disks is critically low on disk space:
581
+
582
+```yaml
583
+template: disk_full_percent
584
+ on: disk.space
585
+ calc: $used * 100 / ($avail + $used)
586
+ every: 1m
587
+ warn: $this > 80
588
+ crit: $this > 95
589
+ repeat: warning 120s critical 10s
590
+```
591
+
592
+`$used` and `$avail` are the `used` and `avail` chart dimensions as shown on the dashboard.
593
+
594
+So, the `calc` line finds the percentage of used space. `$this` resolves to this percentage.
595
+
596
+This is a repeating alarm and if the alarm becomes CRITICAL it repeats the notifications every 10 seconds. It also
597
+repeats notifications every 2 minutes if the alarm goes into WARNING mode.
598
+
599
+### Example 3
600
+
601
+Predict if any disk will run out of space in the near future.
602
+
603
+We do this in 2 steps:
604
+
605
+Calculate the disk fill rate:
606
+
607
+```yaml
608
+ template: disk_fill_rate
609
+ on: disk.space
610
+ lookup: max -1s at -30m unaligned of avail
611
+ calc: ($this - $avail) / (30 * 60)
612
+ every: 15s
613
+```
614
+
615
+In the `calc` line: `$this` is the result of the `lookup` line (i.e. the free space 30 minutes
616
+ago) and `$avail` is the current disk free space. So the `calc` line will either have a positive
617
+number of GB/second if the disk if filling up, or a negative number of GB/second if the disk is
618
+freeing up space.
619
+
620
+There is no `warn` or `crit` lines here. So, this template will just do the calculation and
621
+nothing more.
622
+
623
+Predict the hours after which the disk will run out of space:
624
+
625
+```yaml
626
+ template: disk_full_after_hours
627
+ on: disk.space
628
+ calc: $avail / $disk_fill_rate / 3600
629
+ every: 10s
630
+ warn: $this > 0 and $this < 48
631
+ crit: $this > 0 and $this < 24
632
+```
633
+
634
+The `calc` line estimates the time in hours, we will run out of disk space. Of course, only
635
+positive values are interesting for this check, so the warning and critical conditions check
636
+for positive values and that we have enough free space for 48 and 24 hours respectively.
637
+
638
+Once this alarm triggers we will receive an email like this:
639
+
640
+
641
+
642
+### Example 4
643
+
644
+Check if any network interface is dropping packets:
645
+
646
+```yaml
647
+template: 30min_packet_drops
648
+ on: net.drops
649
+ lookup: sum -30m unaligned absolute
650
+ every: 10s
651
+ crit: $this > 0
652
+```
653
+
654
+The `lookup` line will calculate the sum of the all dropped packets in the last 30 minutes.
655
+
656
+The `crit` line will issue a critical alarm if even a single packet has been dropped.
657
+
658
+Note that the drops chart does not exist if a network interface has never dropped a single packet.
659
+When Netdata detects a dropped packet, it will add the chart and it will automatically attach this
660
+alarm to it.
661
+
662
+### Example 5
663
+
664
+Check if user or system dimension is using more than 50% of cpu:
665
+
666
+```yaml
667
+ alarm: dim_template
668
+ on: system.cpu
669
+ os: linux
670
+lookup: average -3s percentage foreach system,user
671
+ units: %
672
+ every: 10s
673
+ warn: $this > 50
674
+ crit: $this > 80
675
+```
676
+
677
+The `lookup` line will calculate the average CPU usage from system and user in the last 3 seconds. Because we have
678
+the foreach in the `lookup` line, Netdata will create two independent alarms called `dim_template_system`
679
+and `dim_template_user` that will have all the other parameters shared among them.
680
+
681
+### Example 6
682
+
683
+Check if all dimensions are using more than 50% of cpu:
684
+
685
+```yaml
686
+ alarm: dim_template
687
+ on: system.cpu
688
+ os: linux
689
+lookup: average -3s percentage foreach *
690
+ units: %
691
+ every: 10s
692
+ warn: $this > 50
693
+ crit: $this > 80
694
+```
695
+
696
+The `lookup` line will calculate the average of CPU usage from system and user in the last 3 seconds. In this case
697
+Netdata will create alarms for all dimensions of the chart.
698
+
699
+## Troubleshooting
700
+
701
+You can compile Netdata with [debugging](../daemon/README.md#debugging) and then set in `netdata.conf`:
702
+
703
+```yaml
704
+[global]
705
+ debug flags = 0x0000000000800000
706
+```
707
+
708
+Then check your `/var/log/netdata/debug.log`. It will show you how it works.
709
+Important: this will generate a lot of output in debug.log.
710
+
711
+You can find the context of charts by looking up the chart in either
712
+`http://your.netdata:19999/netdata.conf` or `http://your.netdata:19999/api/v1/charts`.
713
+
714
+You can find how Netdata interpreted the expressions by examining the alarm at
715
+`http://your.netdata:19999/api/v1/alarms?all`. For each expression, Netdata will return the expression as given in its
716
+config file, and the same expression with additional parentheses added to indicate the evaluation flow of the
717
+expression.
718
+
719
+## Disabling health checks or silencing notifications at runtime
720
+
721
+It's currently not possible to schedule notifications from within the alarm template. For those scenarios where you need
722
+to temporary disable notifications (for instance when running backups triggers a disk alert) you can disable or silence
723
+notifications are runtime. The health checks can be controlled at runtime via the [health management
724
+api](../web/api/health/).
health/tutorials/dimension-templates.md
renamed
+5
-5
@@ -4,19 +4,19 @@ Your ability to monitor the health of your systems and applications relies on yo
4
the best set of alarms for your particular needs.
5
6
In v1.18 of Netdata, we introduced **dimension templates** for alarms, which simplifies the process of writing [alarm
7
-entities](../../health/README.md#entities-in-the-health-files) for charts with many dimensions.
7
+entities](../REFERENCE.md#health-entity-reference) for charts with many dimensions.
8
9
Dimension templates can condense many individual entities into one—no more copy-pasting one entity and changing the
10
`alarm`/`template` and `lookup` lines for each dimension you'd like to monitor.
11
12
They are, however, an advanced health monitoring feature. For more basic instructions on creating your first alarm,
13
-check out our [health monitoring documentation](../../health/), which also includes
14
-[examples](../../health/README.md#examples).
13
+check out our [health monitoring documentation](../README.md), which also includes
14
+[examples](../REFERENCE.md#example-alarms).
15
16
## The fundamentals of `foreach`
17
18
Our dimension templates update creates a new `foreach` parameter to the existing [`lookup`
19
-line](../../health/README.md#alarm-line-lookup). This is where the magic happens.
19
+line](../REFERENCE.md#alarm-line-lookup). This is where the magic happens.
20
21
You use the `foreach` parameter to specify which dimensions you want to monitor with this single alarm. You can separate
22
them with a comma (`,`) or a pipe (`|`). You can also use a [Netdata simple pattern](../../libnetdata/simple_pattern/README.md)
@@ -113,7 +113,7 @@ documentation](../../libnetdata/simple_pattern/README.md).
113
114
## Using `foreach` with alarm templates
115
116
-Dimension templates also work with [alarm templates](../../health/README.md#entities-in-the-health-files). Alarm
116
+Dimension templates also work with [alarm templates](../REFERENCE.md#alarm-line-alarm-or-template). Alarm
117
templates help you create alarms for all the charts with a given context—for example, all the cores of your system's
118
CPU.
119
health/tutorials/stop-notifications-alarms.md
new
+85
@@ -0,0 +1,85 @@
1
+# Stop notifications for individual alarms
2
+
3
+In this short tutorial, you'll learn how to how to stop notifications for individual alarms in Netdata's health
4
+monitoring system. We also refer to this process as _silencing_ the alarm.
5
+
6
+Why silence alarms? We designed Netdata's pre-configured alarms for production systems, so they might not be
7
+relevant if you run Netdata on your laptop or a small virtual server. If they're not helpful, they can be a distraction
8
+to real issues with health and performance.
9
+
10
+Silencing individual alarms is an excellent solution for situations where you're not interested in seeing a specific
11
+alarm but don't want to disable a [notification system](../notifications/README.md) entirely.
12
+
13
+## Find the alarm configuration file
14
+
15
+To silence an alarm, you need to know where to find its configuration file.
16
+
17
+Let's use the `system.cpu` chart as an example. It's the first chart you'll see on most Netdata dashboards.
18
+
19
+To figure out which file you need to edit, open up Netdata's dashboard and, click the **Alarms** button at the top
20
+of the dashboard, followed by clicking on the **All** tab.
21
+
22
+In this example, we're looking for the `system - cpu` entity, which, when opened, looks like this:
23
+
24
+
26
+
27
+In the `source` row, you see that this chart is getting its configuration from
28
+`4@/usr/lib/netdata/conf.d/health.d/cpu.conf`. The relevant part of begins at `health.d`: `health.d/cpu.conf`. That's
29
+the file you need to edit if you want to silence this alarm.
30
+
31
+For more information about locating health configuration files on your system, see the [health
32
+quickstart](../QUICKSTART.md#locate-health-configuration-files).
33
+
34
+## Edit the file to enable silencing
35
+
36
+To edit `health.d/cpu.conf`, use `edit-config` from inside of your Netdata configuration directory.
37
+
38
+```bash
39
+cd /etc/netdata/ # Replace with your Netdata configuration directory, if not /etc/netdata/
40
+./edit-config health.d/cpu.conf
41
+```
42
+
43
+> You may need to use `sudo` or another method of elevating your privileges.
44
+
45
+The beginning of the file looks like this:
46
+
47
+```yaml
48
+template: 10min_cpu_usage
49
+ on: system.cpu
50
+ os: linux
51
+ hosts: *
52
+ lookup: average -10m unaligned of user,system,softirq,irq,guest
53
+ units: %
54
+ every: 1m
55
+ warn: $this > (($status >= $WARNING) ? (75) : (85))
56
+ crit: $this > (($status == $CRITICAL) ? (85) : (95))
57
+ delay: down 15m multiplier 1.5 max 1h
58
+ info: average cpu utilization for the last 10 minutes (excluding iowait, nice and steal)
59
+ to: sysadmin
60
+```
61
+
62
+To silence this alarm, change `sysadmin` to `silent`.
63
+
64
+```yaml
65
+ to: silent
66
+```
67
+
68
+Use `killall -USR2 netdata` to reload your health configuration and ensure you get no more notifications about that
69
+alarm.
70
+
71
+You can add `to: silence` to any alarm you'd rather not bother you with notifications.
72
+
73
+## What's next?
74
+
75
+You should now know the fundamentals behind silencing any individual alarm in Netdata.
76
+
77
+To learn about _all_ of Netdata's health configuration possibilities, visit the [health reference
78
+guide](../REFERENCE.md), or check out other [tutorials on health monitoring](../README.md#tutorials).
79
+
80
+Or, take better control over how you get notified about alarms via the [notification
81
+system](../notifications/README.md).
82
+
83
+You can also use Netdata's [Health Management API](../../web/api/health/README.md#health-management-api) to control
84
+health checks and notifications while Netdata runs. With this API, you can disable health checks during a maintenance
85
+window or backup process, for example.
netlify.toml
+5
-1
@@ -13,4 +13,8 @@
13
14
[[redirects]]
15
from = "/docs/GettingStarted/"
16
- to = "/docs/getting-started"
\ No newline at end of file
16
+ to = "/docs/getting-started"
17
+
18
+[[redirects]]
19
+ from = "/docs/tutorials/dimension-templates/"
20
+ to = "/health/tutorials/dimension-templates/"
\ No newline at end of file
web/README.md
+1
-1
@@ -175,7 +175,7 @@ shows you two pieces of information: the collector that produces the chart, and
175
the chart's context.
176
177
Netdata also uses [contexts for alarm
178
-templates](../health/#alarm-line-on). You can create an
178
+templates](../health/REFERENCE.md#alarm-line-on). You can create an
179
alarm for the `net.packets` context to receive alerts for any chart with that
180
context, no matter which family it's attached to.
181