Add guide for monitoring a k8s cluster with Netdata
Joel Hans committed
Jul 6, 2020 at 06:51 UTC
59163db2e272d7a2856ea58670a027183dfc449f
2 files changed
+278
docs/guides/monitor/kubernetes-k8s-netdata.md
new
+275
@@ -0,0 +1,275 @@
1
+<!--
2
+title: "Monitor a Kubernetes (k8s) cluster with Netdata"
3
+description: "Use Netdata's helmchart, service discovery plugin, and Kubelet/kube-proxy collectors for real-time visibility into your Kubernetes cluster."
4
+image: /img/seo/guides/monitor/kubernetes-k8s-netdata.png
5
+custom_edit_url: https://github.com/netdata/netdata/edit/master/docs/guides/monitor/kubernetes-k8s-netdata.md
6
+-->
7
+
8
+# Monitor a Kubernetes cluster with Netdata
9
+
10
+While Kubernetes (k8s) might simplify the way you deploy, scale, and load-balance your applications, not all clusters
11
+come with "batteries included" when it comes to monitoring. Doubly so for a monitoring stack that helps you actively
12
+troubleshoot issues with your cluster.
13
+
14
+Some k8s providers, like GKE (Google Kubernetes Engine), do deploy clusters bundled with monitoring capabilities, such
15
+as Google Stackdriver Monitoring. However, these pre-configured solutions might not offer the depth of metrics,
16
+customization, or integration with your perferred alerting methods.
17
+
18
+Without this visibility, it's like you built an entire house and _then_ smashed your way through the finished walls to
19
+add windows.
20
+
21
+At Netdata, we're working to build Kubernetes monitoring tools that add visibility without complexity while also helping
22
+you actively troubleshoot anomalies or outages. Better yet, this toolkit includes a few complementary collectors that
23
+let you monitor the many layers of a Kubernetes cluster entirely for free.
24
+
25
+We already have a few complementary tools and collectors for monitoring the many layers of a Kubernetes cluster,
26
+_entirely for free_. These methods work together to help you troubleshoot performance or availablility issues across
27
+your k8s infrastructure.
28
+
29
+- A [Helm chart](https://github.com/netdata/helmchart), which bootstraps a Netdata Agent pod on every node in your
30
+ cluster, plus an additional parent pod for storing metrics and managing alarm notifications.
31
+- A [service discovery plugin](https://github.com/netdata/agent-service-discovery), which discovers and immediately
32
+ monitors 22 different services that might be running inside of your cluster's pods. Service discovery happens
33
+ without manual intervention as pods are created, destroyed, or moved between nodes. [Compatible
34
+ services](https://github.com/netdata/helmchart#service-discovery-and-supported-services) include Nginx, Apache,
35
+ MySQL, CoreDNS, and much more.
36
+- A [Kubelet collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/k8s_kubelet), which runs
37
+ on each node in a k8s cluster to monitor the number of pods/containers, the volume of operations on each container,
38
+ and more.
39
+- A [kube-proxy collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/k8s_kubeproxy), which
40
+ also runs on each node and monitors latency and the volume of HTTP requests to the proxy.
41
+- A [cgroups collector](/collectors/cgroups.plugin/README.md), which collects CPU, memory, and bandwidth metrics for
42
+ each container running on your k8s cluster.
43
+
44
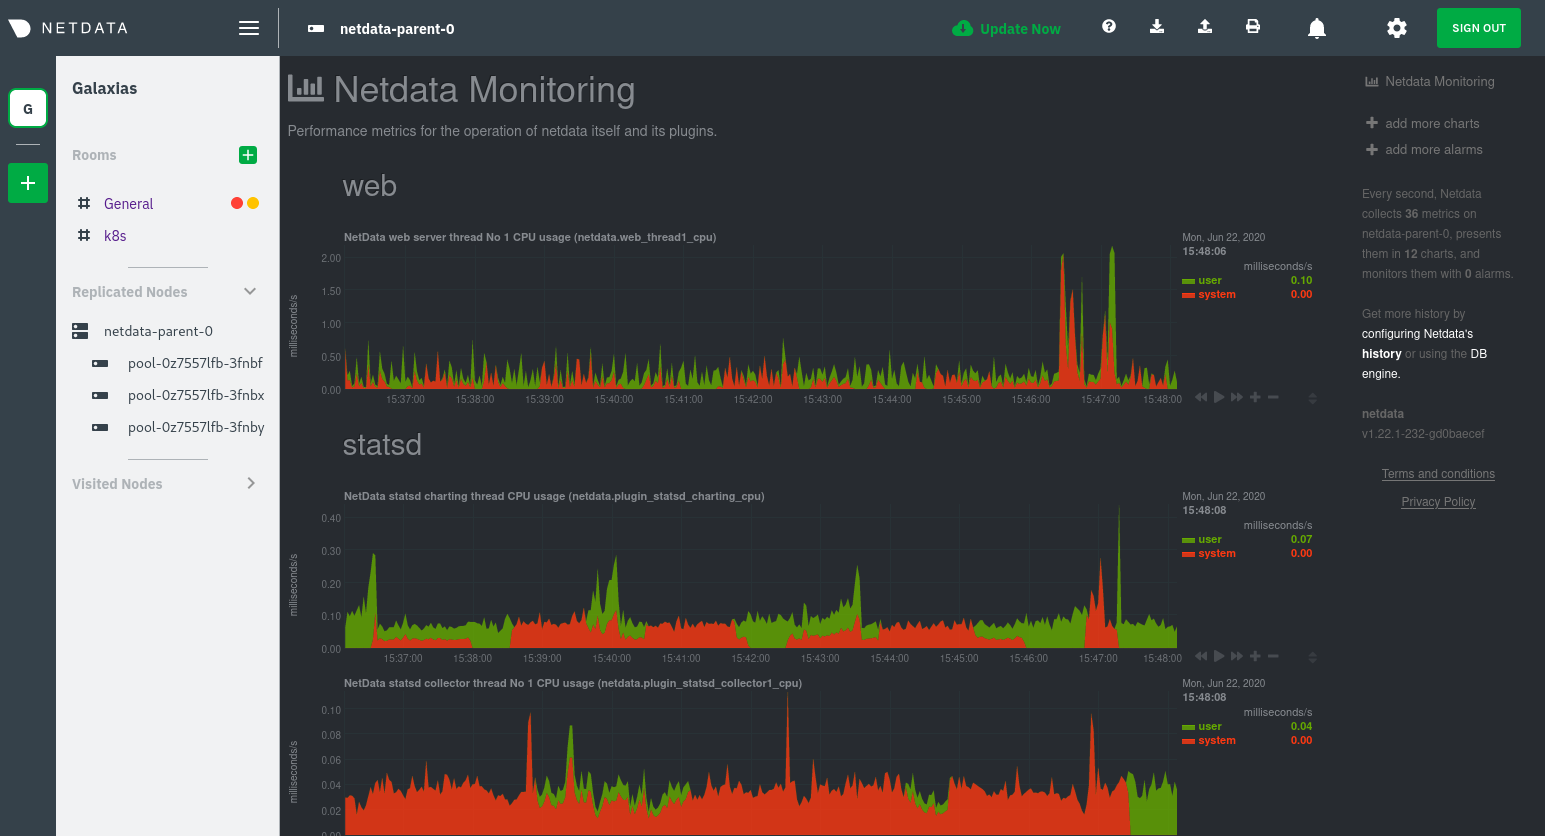
+By following this guide, you'll learn how to discover, explore, and take away insights from each of these layers in your
45
+Kubernetes cluster. Let's get started.
46
+
47
+## Prerequisites
48
+
49
+To follow this guide, you need:
50
+
51
+- A working cluster running Kubernetes v1.9 or newer.
52
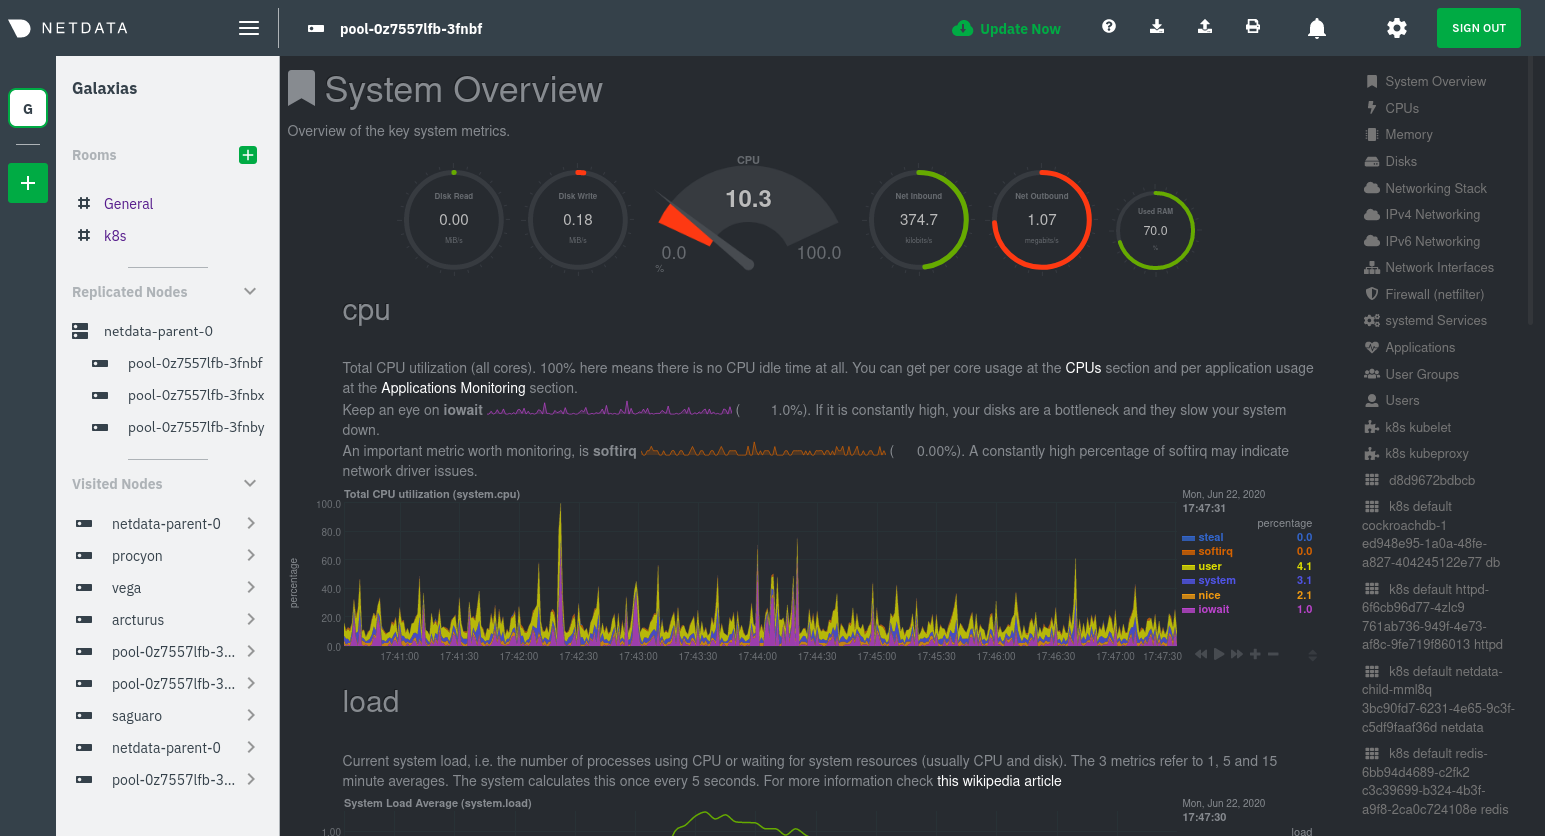
+- The [kubectl](https://kubernetes.io/docs/reference/kubectl/overview/) command line tool, within [one minor version
53
+ difference](https://kubernetes.io/docs/tasks/tools/install-kubectl/#before-you-begin) of your cluster, on an
54
+ administrative system.
55
+- The [Helm package manager](https://helm.sh/) v3.0.0 or newer on the same administrative system.
56
+
57
+**You need to install the Netdata Helm chart on your cluster** before you proceed. See our [Kubernetes installation
58
+process](/packaging/installer/methods/kubernetes.md) for details.
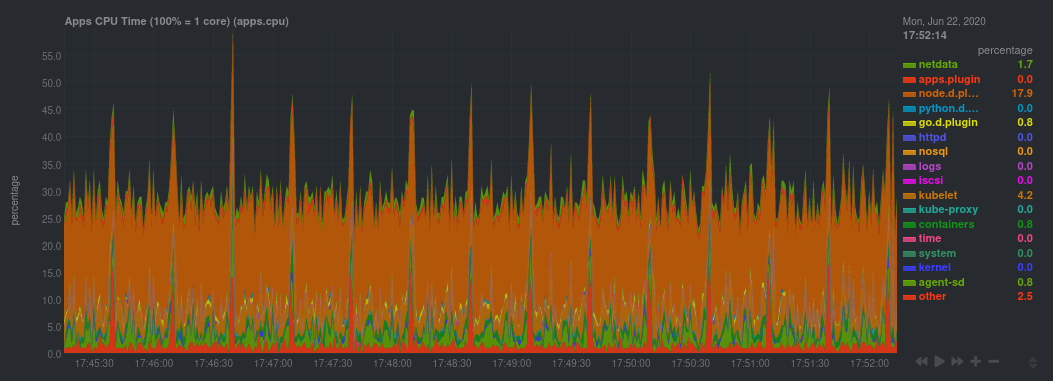
59
+
60
+This guide uses a 3-node cluster, running on Digital Ocean, as an example. This cluster runs CockroachDB, Redis, and
61
+Apache, which we'll use as examples of how to monitor a Kubernetes cluster with Netdata.
62
+
63
+```bash
64
+kubectl get nodes
65
+NAME STATUS ROLES AGE VERSION
66
+pool-0z7557lfb-3fnbf Ready <none> 51m v1.17.5
67
+pool-0z7557lfb-3fnbx Ready <none> 51m v1.17.5
68
+pool-0z7557lfb-3fnby Ready <none> 51m v1.17.5
69
+
70
+kubectl get pods
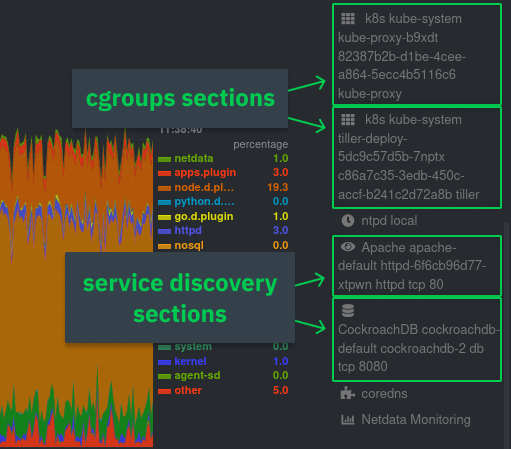
71
+NAME READY STATUS RESTARTS AGE
72
+cockroachdb-0 1/1 Running 0 44h
73
+cockroachdb-1 1/1 Running 0 44h
74
+cockroachdb-2 1/1 Running 1 44h
75
+cockroachdb-init-q7mp6 0/1 Completed 0 44h
76
+httpd-6f6cb96d77-4zlc9 1/1 Running 0 2m47s
77
+httpd-6f6cb96d77-d9gs6 1/1 Running 0 2m47s
78
+httpd-6f6cb96d77-xtpwn 1/1 Running 0 11m
79
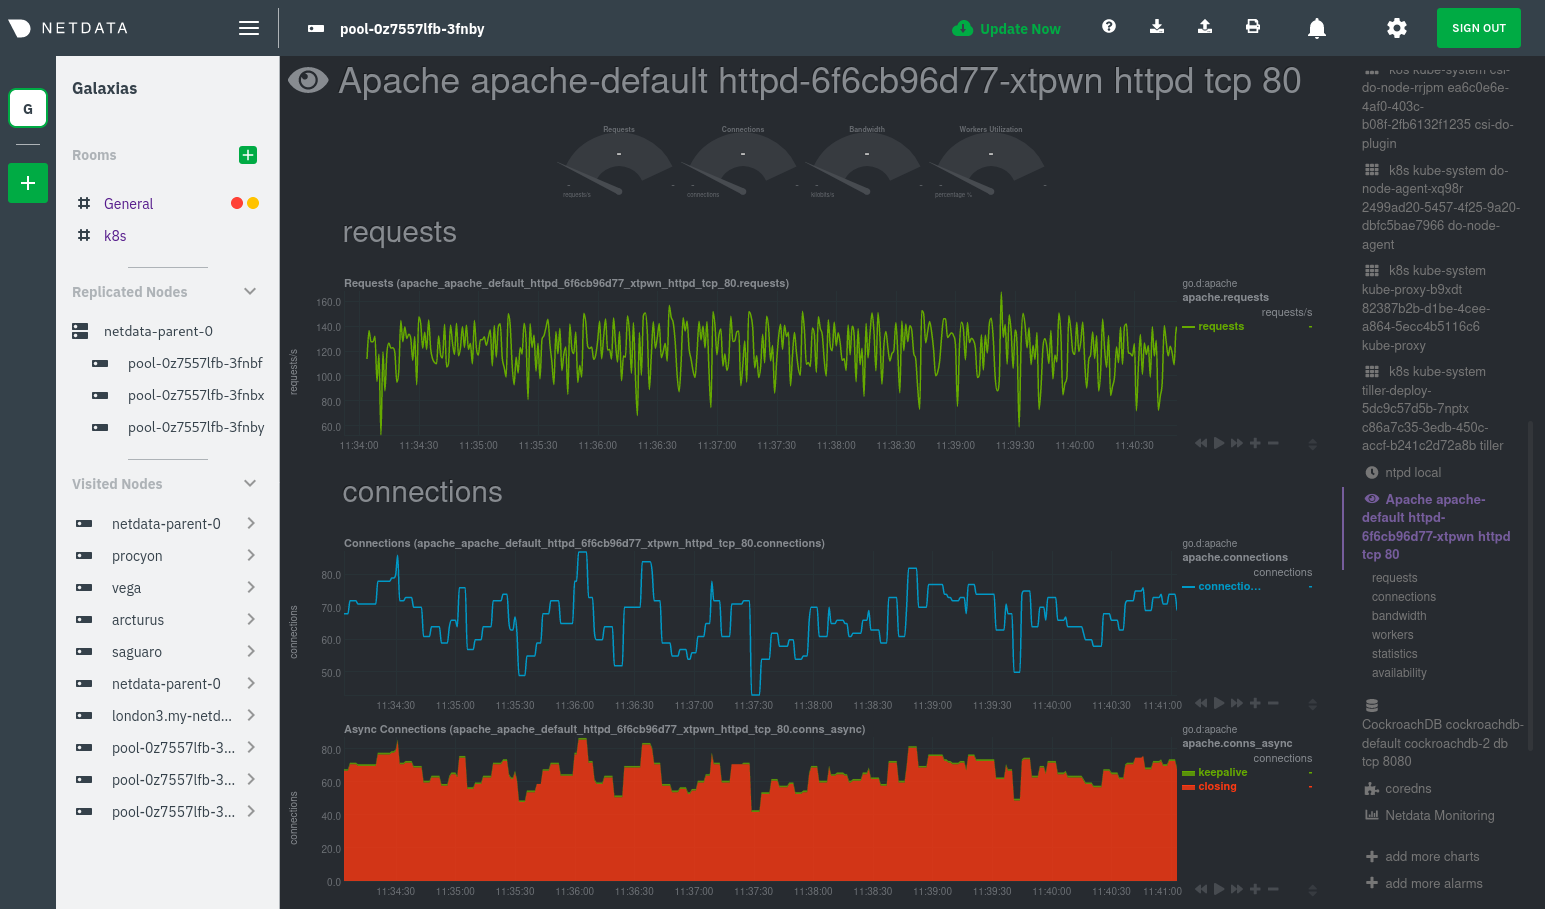
+netdata-child-5p2m9 2/2 Running 0 42h
80
+netdata-child-92qvf 2/2 Running 0 42h
81
+netdata-child-djc6w 2/2 Running 0 42h
82
+netdata-parent-0 1/1 Running 0 42h
83
+redis-6bb94d4689-6nn6v 1/1 Running 0 73s
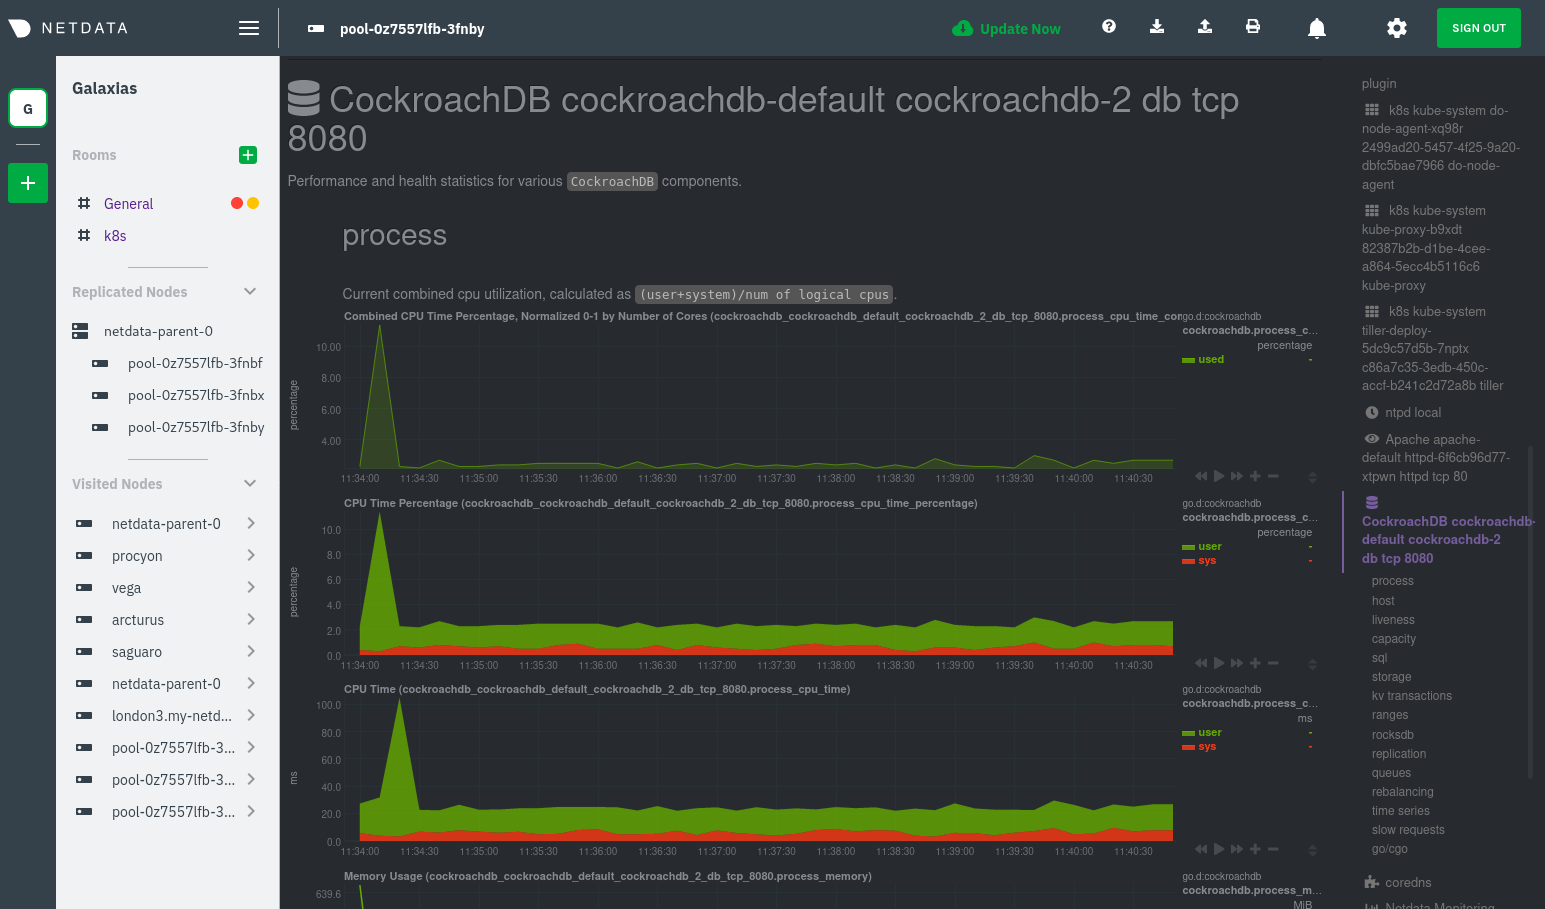
84
+redis-6bb94d4689-c2fk2 1/1 Running 0 73s
85
+redis-6bb94d4689-tjcz5 1/1 Running 0 88s
86
+```
87
+
88
+## Explore Netdata's Kubernetes charts
89
+
90
+The Helm chart installs and enables everything you need for visibility into your k8s cluster, including the service
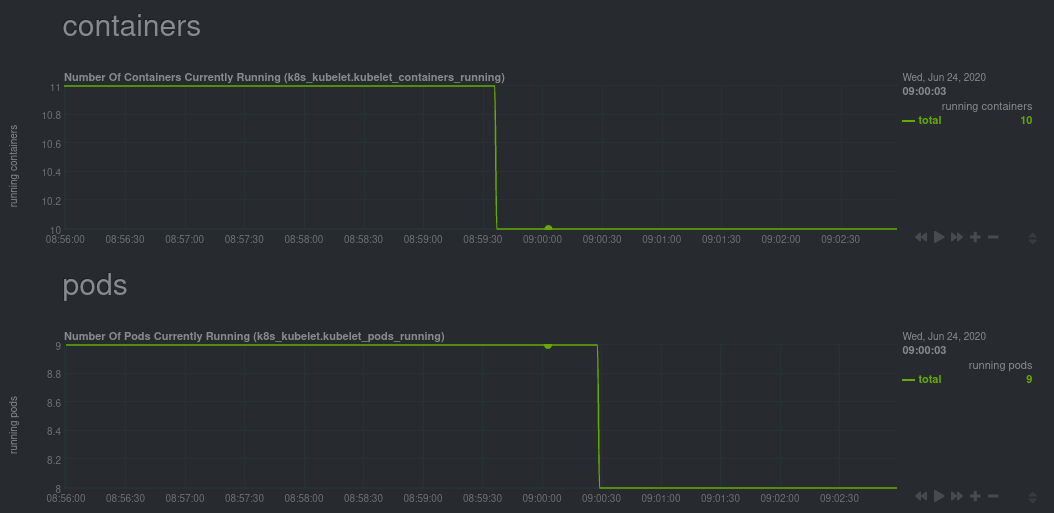
91
+discovery plugin, Kubelet collector, kube-proxy collector, and cgroups collector.
92
+
93
+To get started, open your browser and navigate to your cluster's Netdata dashboard. See our [Kubernetes installation
94
+instructions](/packaging/installer/methods/kubernetes.md) for how to access the dashboard based on your cluster's
95
+configuration.
96
+
97
+You'll see metrics from the parent pod as soon as you navigate to the dashboard:
98
+
99
+
101
+
102
+Remember that the parent pod is responsible for storing metrics from all the child pods and sending alarms.
103
+
104
+Take note of the **Replicated Nodes** menu, which shows not only the parent pod, but also the three child pods. This
105
+example cluster has three child pods, but the number of child pods depends entirely on the number of nodes in your
106
+cluster.
107
+
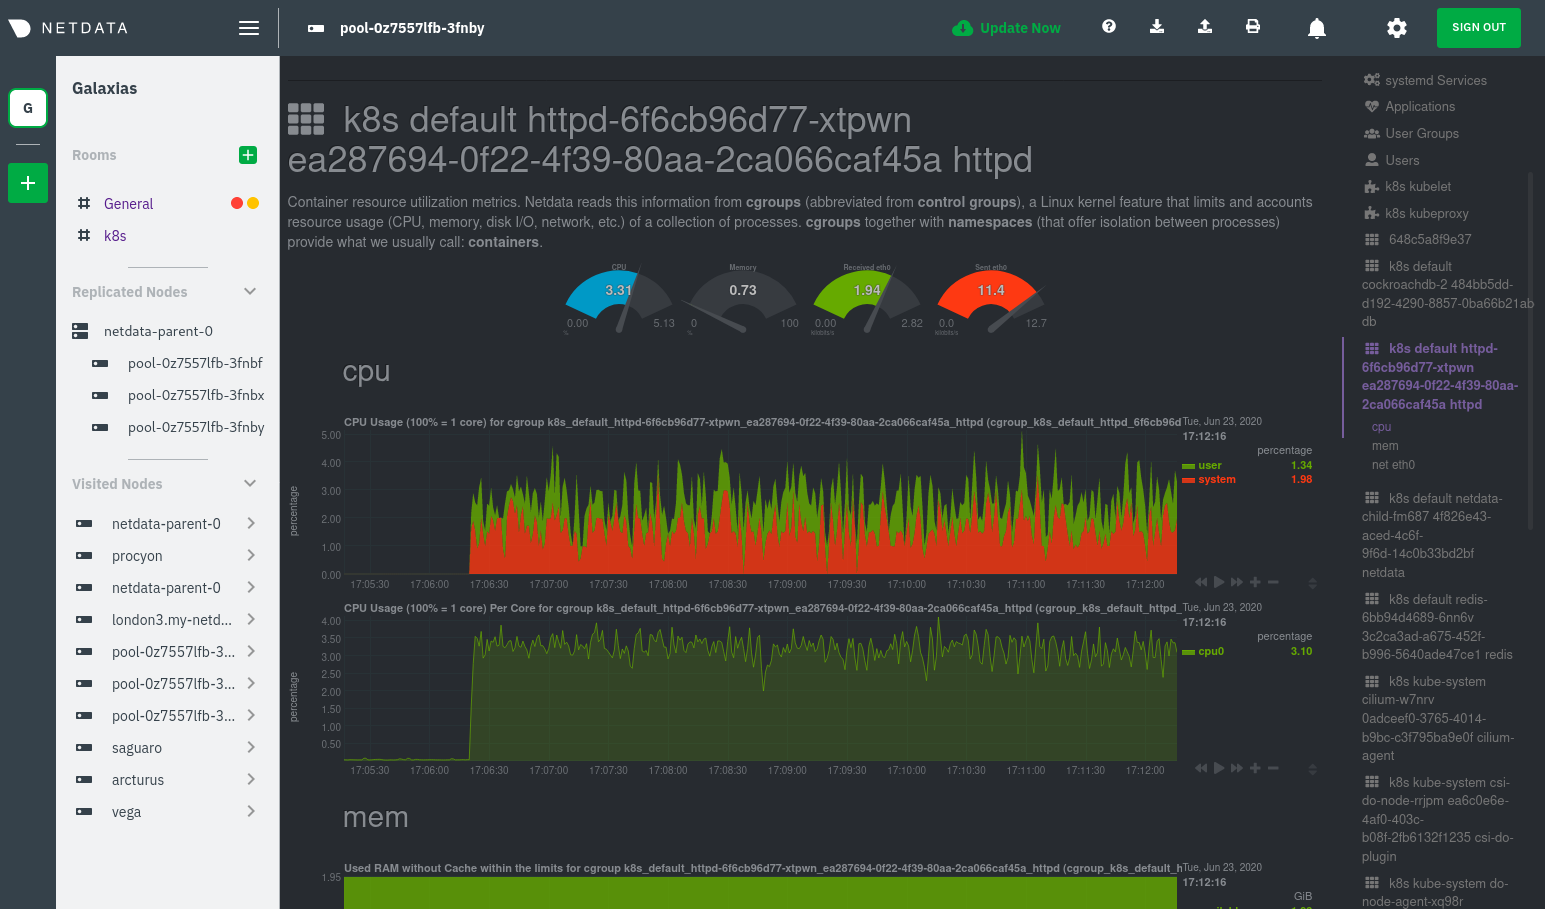
108
+You'll use the links in the **Replicated Nodes** menu to navigate between the various pods in your cluster. Let's do
109
+that now to explore the pod-level Kubernetes monitoring Netdata delivers.
110
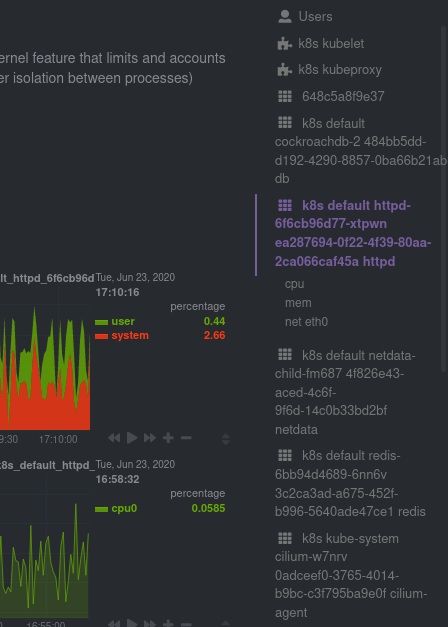
+
111
+### Pods
112
+
113
+Click on any of the nodes under **netdata-parent-0**. Netdata redirects you to a separate instance of the Netdata
114
+dashboard, run by the Netdata child pod, which visualizes thousands of metrics from that node.
115
+
116
+
118
+
119
+From this dashboard, you can see all the familiar charts showing the health and performance of an individual node, just
120
+like you would if you installed Netdata on a single physical system. Explore CPU, memory, bandwidth, networking, and
121
+more.
122
+
123
+You can use the menus on the right-hand side of the dashboard to navigate between different sections of charts and
124
+metrics.
125
+
126
+For example, click on the **Applications** section to view per-application metrics, collected by
127
+[apps.plugin](/collectors/apps.plugin/README.md). The first chart you see is **Apps CPU Time (100% = 1 core)
128
+(apps.cpu)**, which shows the CPU utilization of various applications running on the node. You shouldn't be surprised to
129
+find Netdata processes (`netdata`, `sd-agent`, and more) alongside Kubernetes processes (`kubelet`, `kube-proxy`, and
130
+`containers`).
131
+
132
+
134
+
135
+Beneath the **Applications** section, you'll begin to see sections for **k8s kubelet**, **k8s kubeproxy**, and long
136
+strings that start with **k8s**, which are sections for metrics collected by
137
+[`cgroups.plugin`](/collectors/cgroups.plugin/README.md). Let's skip over those for now and head further down to see
138
+Netdata's service discovery in action.
139
+
140
+### Service discovery (services running inside of pods)
141
+
142
+Thanks to Netdata's service discovery feature, you monitor containerized applications running in k8s pods with zero
143
+configuration or manual intervention. Service discovery is like a watchdog for created or deleted pods, recognizing the
144
+service they run based on the image name and port and immediately attempting to apply a logical default configuration.
145
+
146
+Service configuration supports [22
147
+services](https://github.com/netdata/helmchart#service-discovery-and-supported-services), which are automatically added
148
+or removed from Netdata as soon as the pods are created or destroyed.
149
+
150
+You can find these service discovery sections near the bottom of the menu. The names for these sections follow a
151
+pattern: the name of the detected service, followed by a string of the module name, pod TUID, service type, port
152
+protocol, and port number. See the graphic below to help you identify service discovery sections.
153
+
154
+
156
+
157
+For example, the first service discovery section shows metrics for a pod running an Apache web server running on port 80
158
+in a pod named `httpd-6f6cb96d77-xtpwn`.
159
+
160
+> If you don't see any service discovery sections, it's either because your services are not compatible with service
161
+> discovery or you changed their default configuration, such as the listening port. See the [list of supported
162
+> services](https://github.com/netdata/helmchart#service-discovery-and-supported-services) for details about whether
163
+> your installed services are compatible with service discovery, or read the [configuration
164
+> instructions](/packaging/installer/methods/kubernetes.md#configure-service-discovery) to change how it discovers the
165
+> supported services.
166
+
167
+Click on any of these service discovery sections to see metrics from that particular service. For example, click on the
168
+**Apache apache-default httpd-6f6cb96d77-xtpwn httpd tcp 80** section brings you to a series of charts populated by the
169
+[Apache collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/apache) itself.
170
+
171
+With service discovery, you can now see valuable metrics like requests, bandwidth, workers, and more for this pod.
172
+
173
+
175
+
176
+The same goes for metrics coming from the CockroachDB pod running on this same node.
177
+
178
+
180
+
181
+Service discovery helps you monitor the health of specific applications running on your Kubernetes cluster, which in
182
+turn gives you a complete resource when troubleshooting your infrastructure's health and performance.
183
+
184
+### Kubelet
185
+
186
+Let's head back up the menu to the **k8s kubelet** section. Kubelet is an agent that runs on every node in a cluster. It
187
+receives a set of PodSpecs from the Kubernetes Control Plane and ensures the pods described there are both running and
188
+healthy. Think of it as a manager for the various pods on that node.
189
+
190
+Monitoring each node's Kubelet can be invaluable when diagnosing issues with your Kubernetes cluster. For example, you
191
+can see when the volume of running containers/pods has dropped.
192
+
193
+
195
+
196
+This drop might signal a fault or crash in a particular Kubernetes service or deployment (see `kubectl get services` or
197
+`kubectl get deployments` for more details). If the number of pods increases, it may be because of something more
198
+benign, like another member of your team scaling up a service with `kubectl scale`.
199
+
200
+You can also view charts for the Kubelet API server, the volume of runtime/Docker operations by type,
201
+configuration-related errors, and the actual vs. desired numbers of volumes, plus a lot more.
202
+
203
+Kubelet metrics are collected and visualized thanks to the [kubelet
204
+collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/k8s_kubelet), which is enabled with
205
+zero configuration on most Kubernetes clusters with standard configurations.
206
+
207
+### kube-proxy
208
+
209
+Scroll down into the **k8s kubeproxy** section to see metrics about the network proxy that runs on each node in your
210
+Kubernetes cluster. kube-proxy allows for pods to communicate with each other and accept sessions from outside your
211
+cluster.
212
+
213
+With Netdata, you can monitor how often your k8s proxies are syncing proxy rules between nodes. Dramatic changes in
214
+these figures could indicate an anomaly in your cluster that's worthy of further investigation.
215
+
216
+kube-proxy metrics are collected and visualized thanks to the [kube-proxy
217
+collector](https://learn.netdata.cloud/docs/agent/collectors/go.d.plugin/modules/k8s_kubeproxy), which is enabled with
218
+zero configuration on most Kubernetes clusters with standard configurations.
219
+
220
+### Containers
221
+
222
+We can finally talk about the final piece of Kubernetes monitoring: containers. Each Kubernetes pod is a set of one or
223
+more cooperating containers, sharing the same namespace, all of which are resourced and tracked by the cgroups feature
224
+of the Linux kernel. Netdata automatically detects and monitors each running container by interfacing with the cgroups
225
+feature itself.
226
+
227
+You can find these sections beneath **Users**, **k8s kubelet**, and **k8s kubeproxy**. Below, a number of containers
228
+devoted to running services like CockroachDB, Apache, Redis, and more.
229
+
230
+
232
+
233
+Let's look at the section devoted to the container that runs the Apache pod named `httpd-6f6cb96d77-xtpwn`, as described
234
+in the previous part on [service discovery](#service-discovery-services-running-inside-of-pods).
235
+
236
+
238
+
239
+At first glance, these sections might seem redundant. You might ask, "Why do I need both a service discovery section
240
+_and_ a container section? It's just one pod, after all!"
241
+
242
+The difference is that while the service discovery section shows _Apache_ metrics, the equivalent cgroups section shows
243
+that container's CPU, memory, and bandwidth usage. You can use the two sections in conjunction to monitor the health and
244
+performance of your pods and the services they run.
245
+
246
+For example, let's say you get an alarm notification from `netdata-parent-0` saying the
247
+`ea287694-0f22-4f39-80aa-2ca066caf45a` container (also known as the `httpd-6f6cb96d77-xtpwn` pod) is using 99% of its
248
+available RAM. You can then hop over to the **Apache apache-default httpd-6f6cb96d77-xtpwn httpd tcp 80** section to
249
+further investigate why Apache is using an unexpected amount of RAM.
250
+
251
+All container metrics, whether they're managed by Kubernetes or the Docker service directly, are collected by the
252
+[cgroups collector](/collectors/cgroups.plugin/README.md). Because this collector integrates with the cgroups Linux
253
+kernel feature itself, monitoring containers requires zero configuration on most Kubernetes clusters.
254
+
255
+## What's next?
256
+
257
+After following this guide, you should have a more comprehensive understanding of how to monitor your Kubernetes cluster
258
+with Netdata. With this setup, you can monitor the health and performance of all your nodes, pods, services, and k8s
259
+agents. Pre-configured alarms will tell you when something goes awry, and this setup gives you every per-second metric
260
+you need to make informed decisions about your cluster.
261
+
262
+The best part of monitoring a Kubernetes cluster with Netdata is that you don't have to worry about constantly running
263
+complex `kubectl` commands to see hundreds of highly granular metrics from your nodes. And forget about using `kubectl
264
+exec -it pod bash` to start up a shell on a pod to find and diagnose an issue with any given pod on your cluster.
265
+
266
+And with service discovery, all your compatible pods will automatically appear and disappear as they scale up, move, or
267
+scale down across your cluster.
268
+
269
+To monitor your Kubernetes cluster with Netdata, start by [installing the Helm
270
+chart](/packaging/installer/methods/kubernetes.md) if you haven't already. The Netdata Agent is open source and entirely
271
+free for every cluster and every organization, whether you have 10 or 10,000 pods. A few minutes and one `helm install`
272
+later and you'll have started on the path of building an effective platform for troubleshooting the next performance or
273
+availability issue on your Kubernetes cluster.
274
+
275
+[](<>)
packaging/installer/methods/kubernetes.md
+3
@@ -149,6 +149,9 @@ helm upgrade netdata ./netdata-helmchart
149
150
## What's next?
151
152
+Read the [monitoring a Kubernetes cluster guide](/docs/guides/monitor/kubernetes-k8s-netdata.md) for details on the
153
+various metrics and charts created by the Helm chart and some best practices on real-time troubleshooting using Netdata.
154
+
155
Check out our [Agent's getting started guide](/docs/getting-started.md) for a quick overview of Netdata's capabilities,
156
especially if you want to change any of the configuration settings for either the parent or child nodes.
157